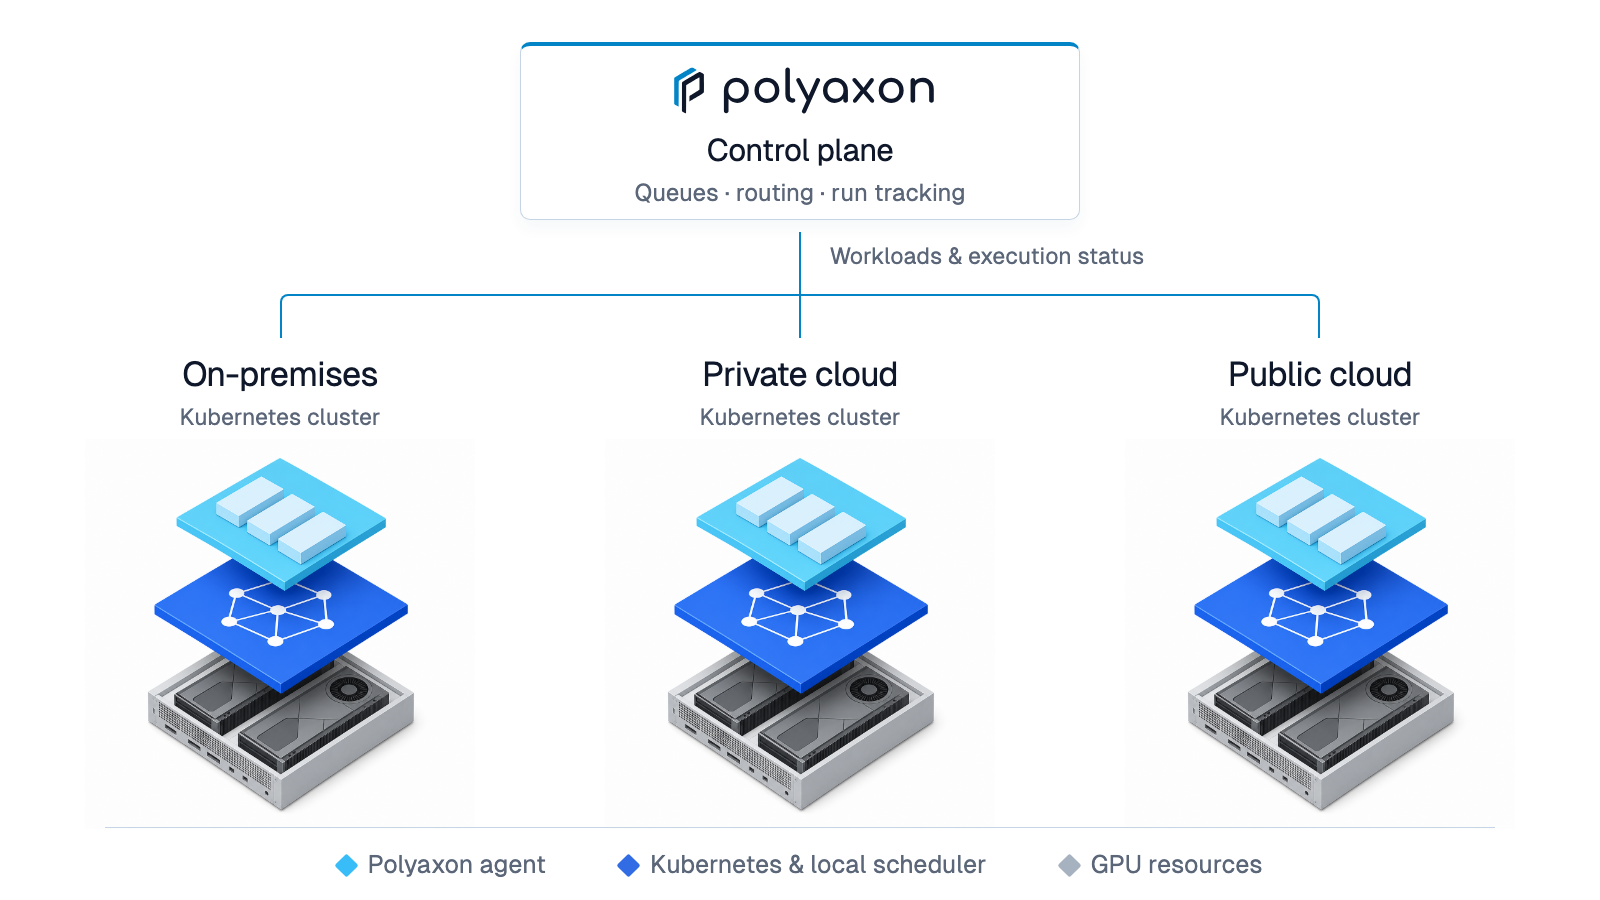
Multi-cluster GPU orchestration
Design multi-cluster GPU orchestration around workload eligibility, data locality, queue routing, recovery, and clear dispatch ownership.
OrchestrationKubernetes
The Polyaxon blog
Practical guides to building, running, and improving ML and AI in production.
GPU orchestration, distributed training, and multi-tenant AI workloads.
Design multi-cluster GPU orchestration around workload eligibility, data locality, queue routing, recovery, and clear dispatch ownership.
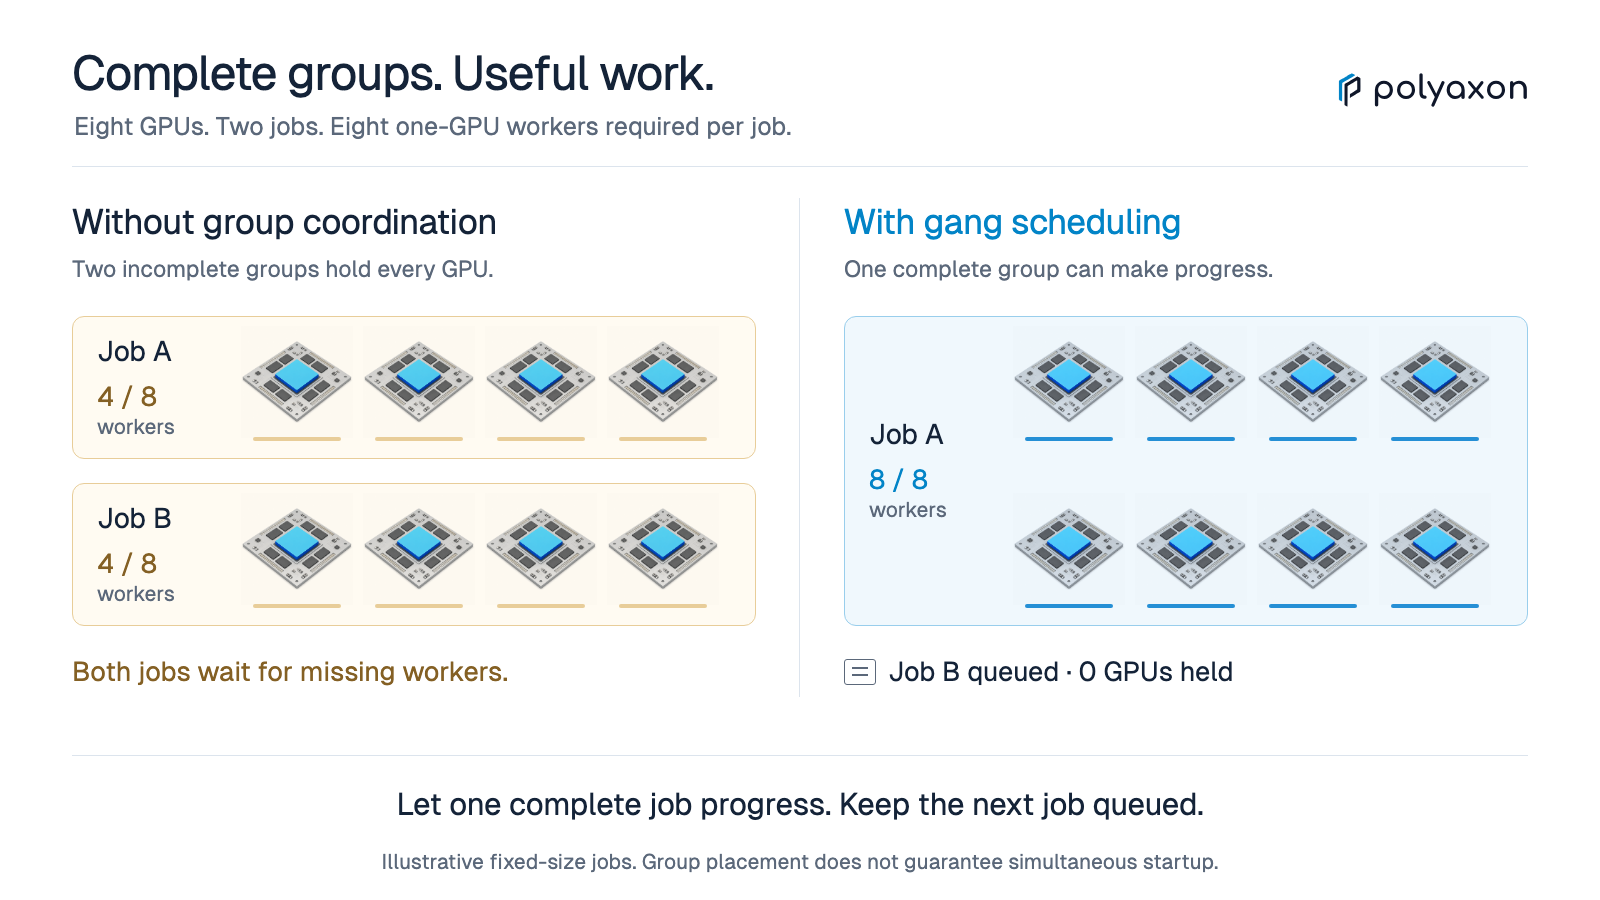
Understand how gang scheduling prevents partial distributed jobs from holding GPUs, how minimum membership works, and what Polyaxon supports.
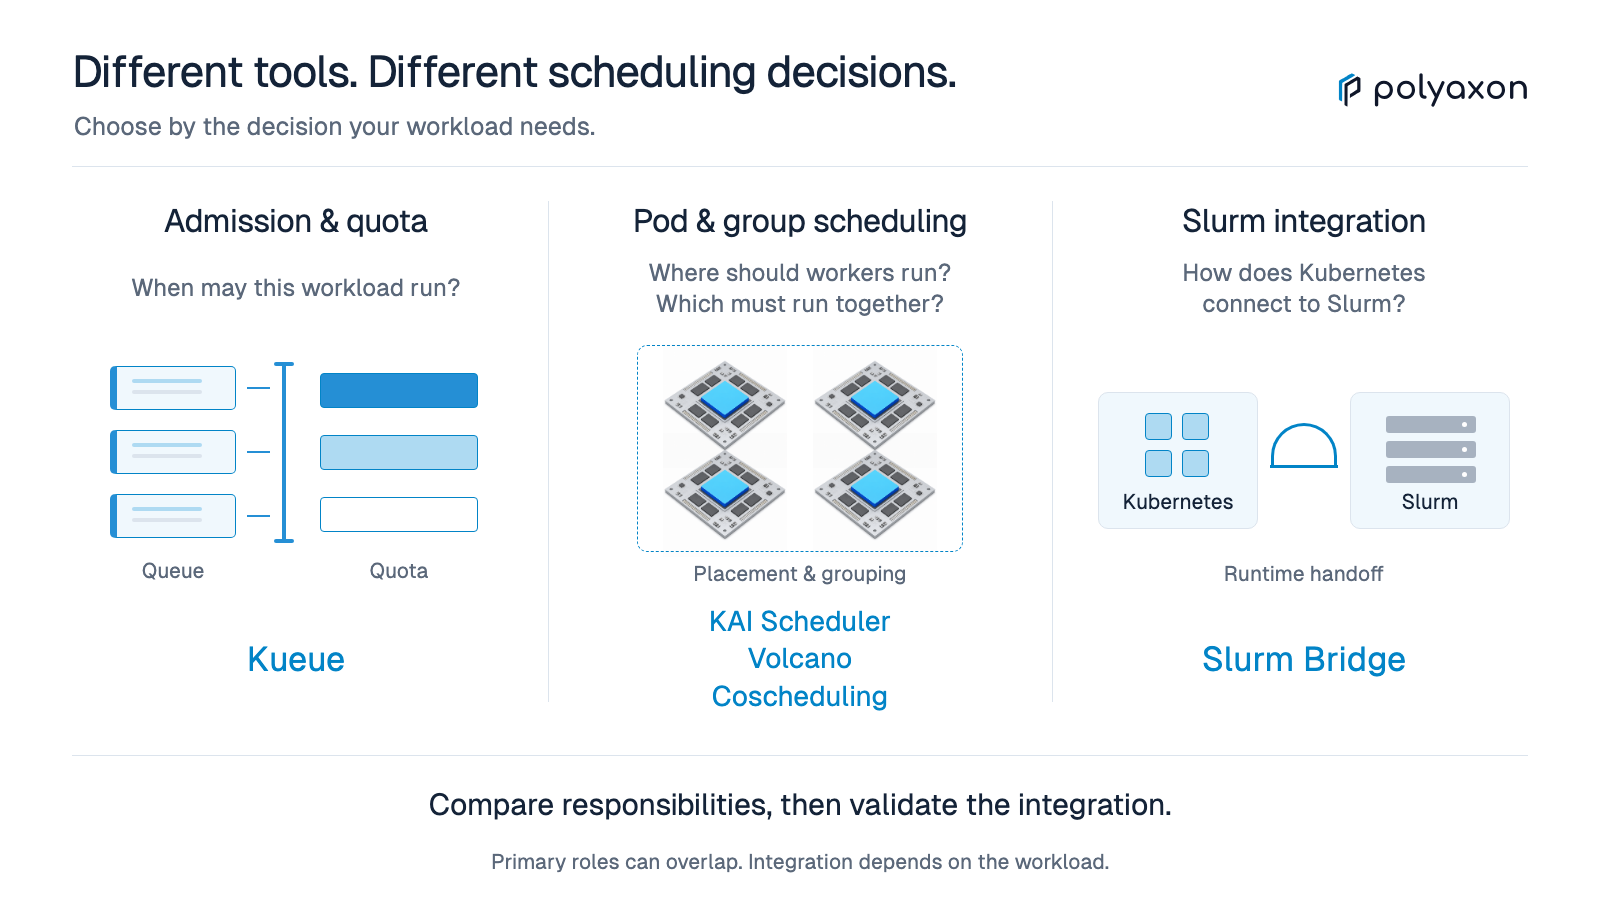
Compare Kueue, KAI Scheduler, Volcano, Coscheduling, and Slurm Bridge by responsibility, workload fit, and Polyaxon integration path.
Understand native topology-aware workload scheduling, combine rack locality with gang placement, and assess the tradeoff between waiting and communication.
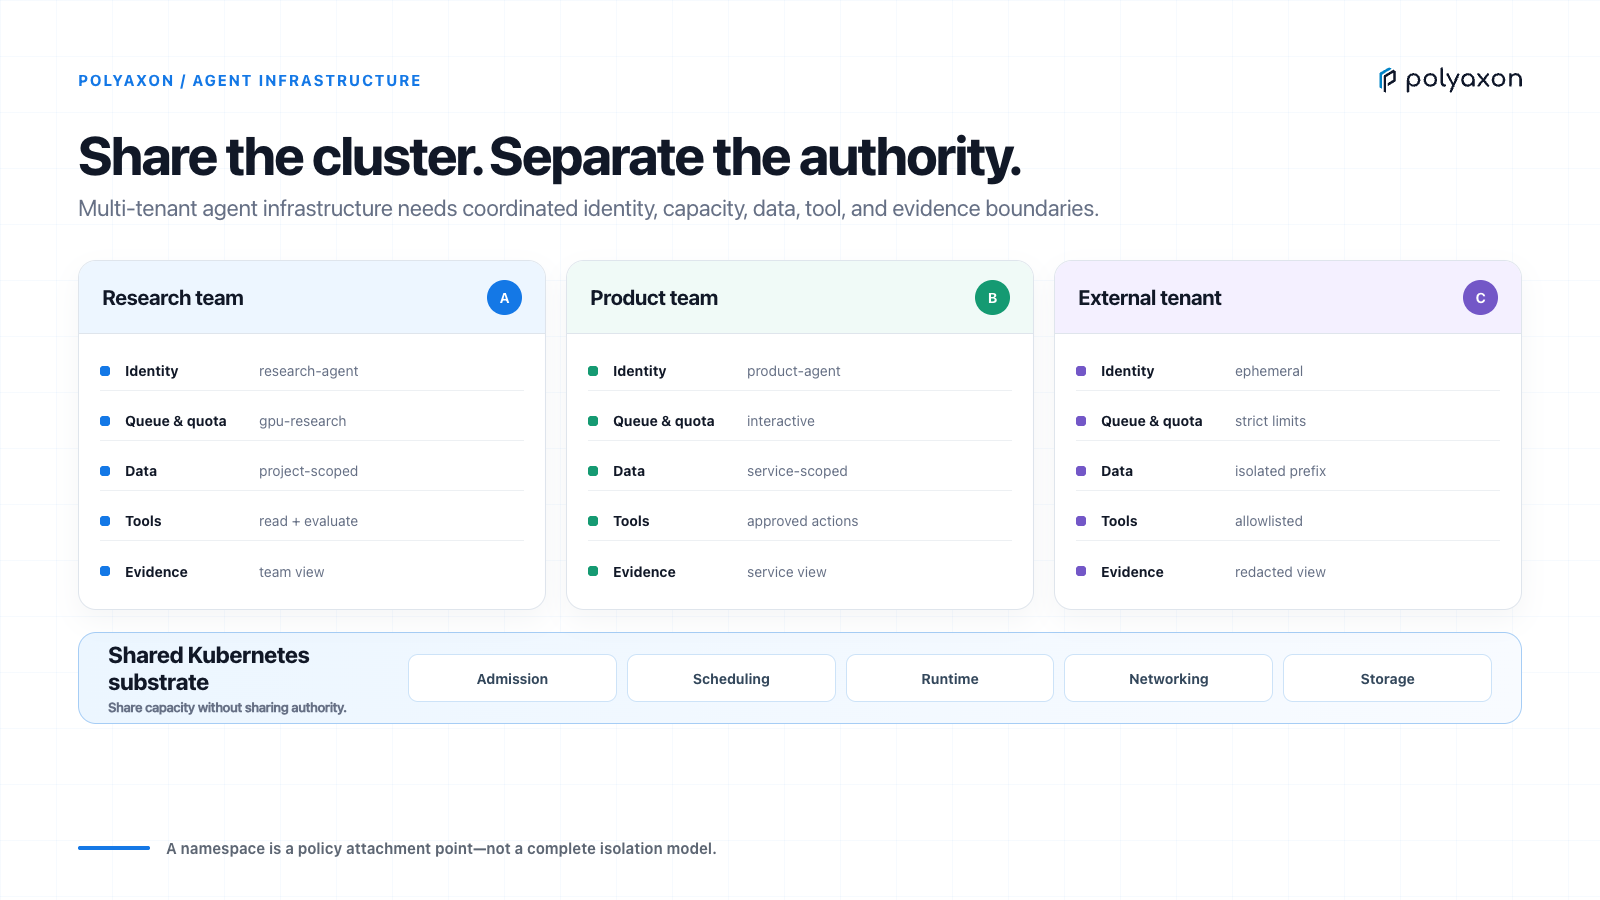
Separate identity, network access, data, queues, budgets, and evidence when multiple teams or customers run AI agents on shared Kubernetes infrastructure.
Track experiments, tune models, manage compute costs, and recover training.
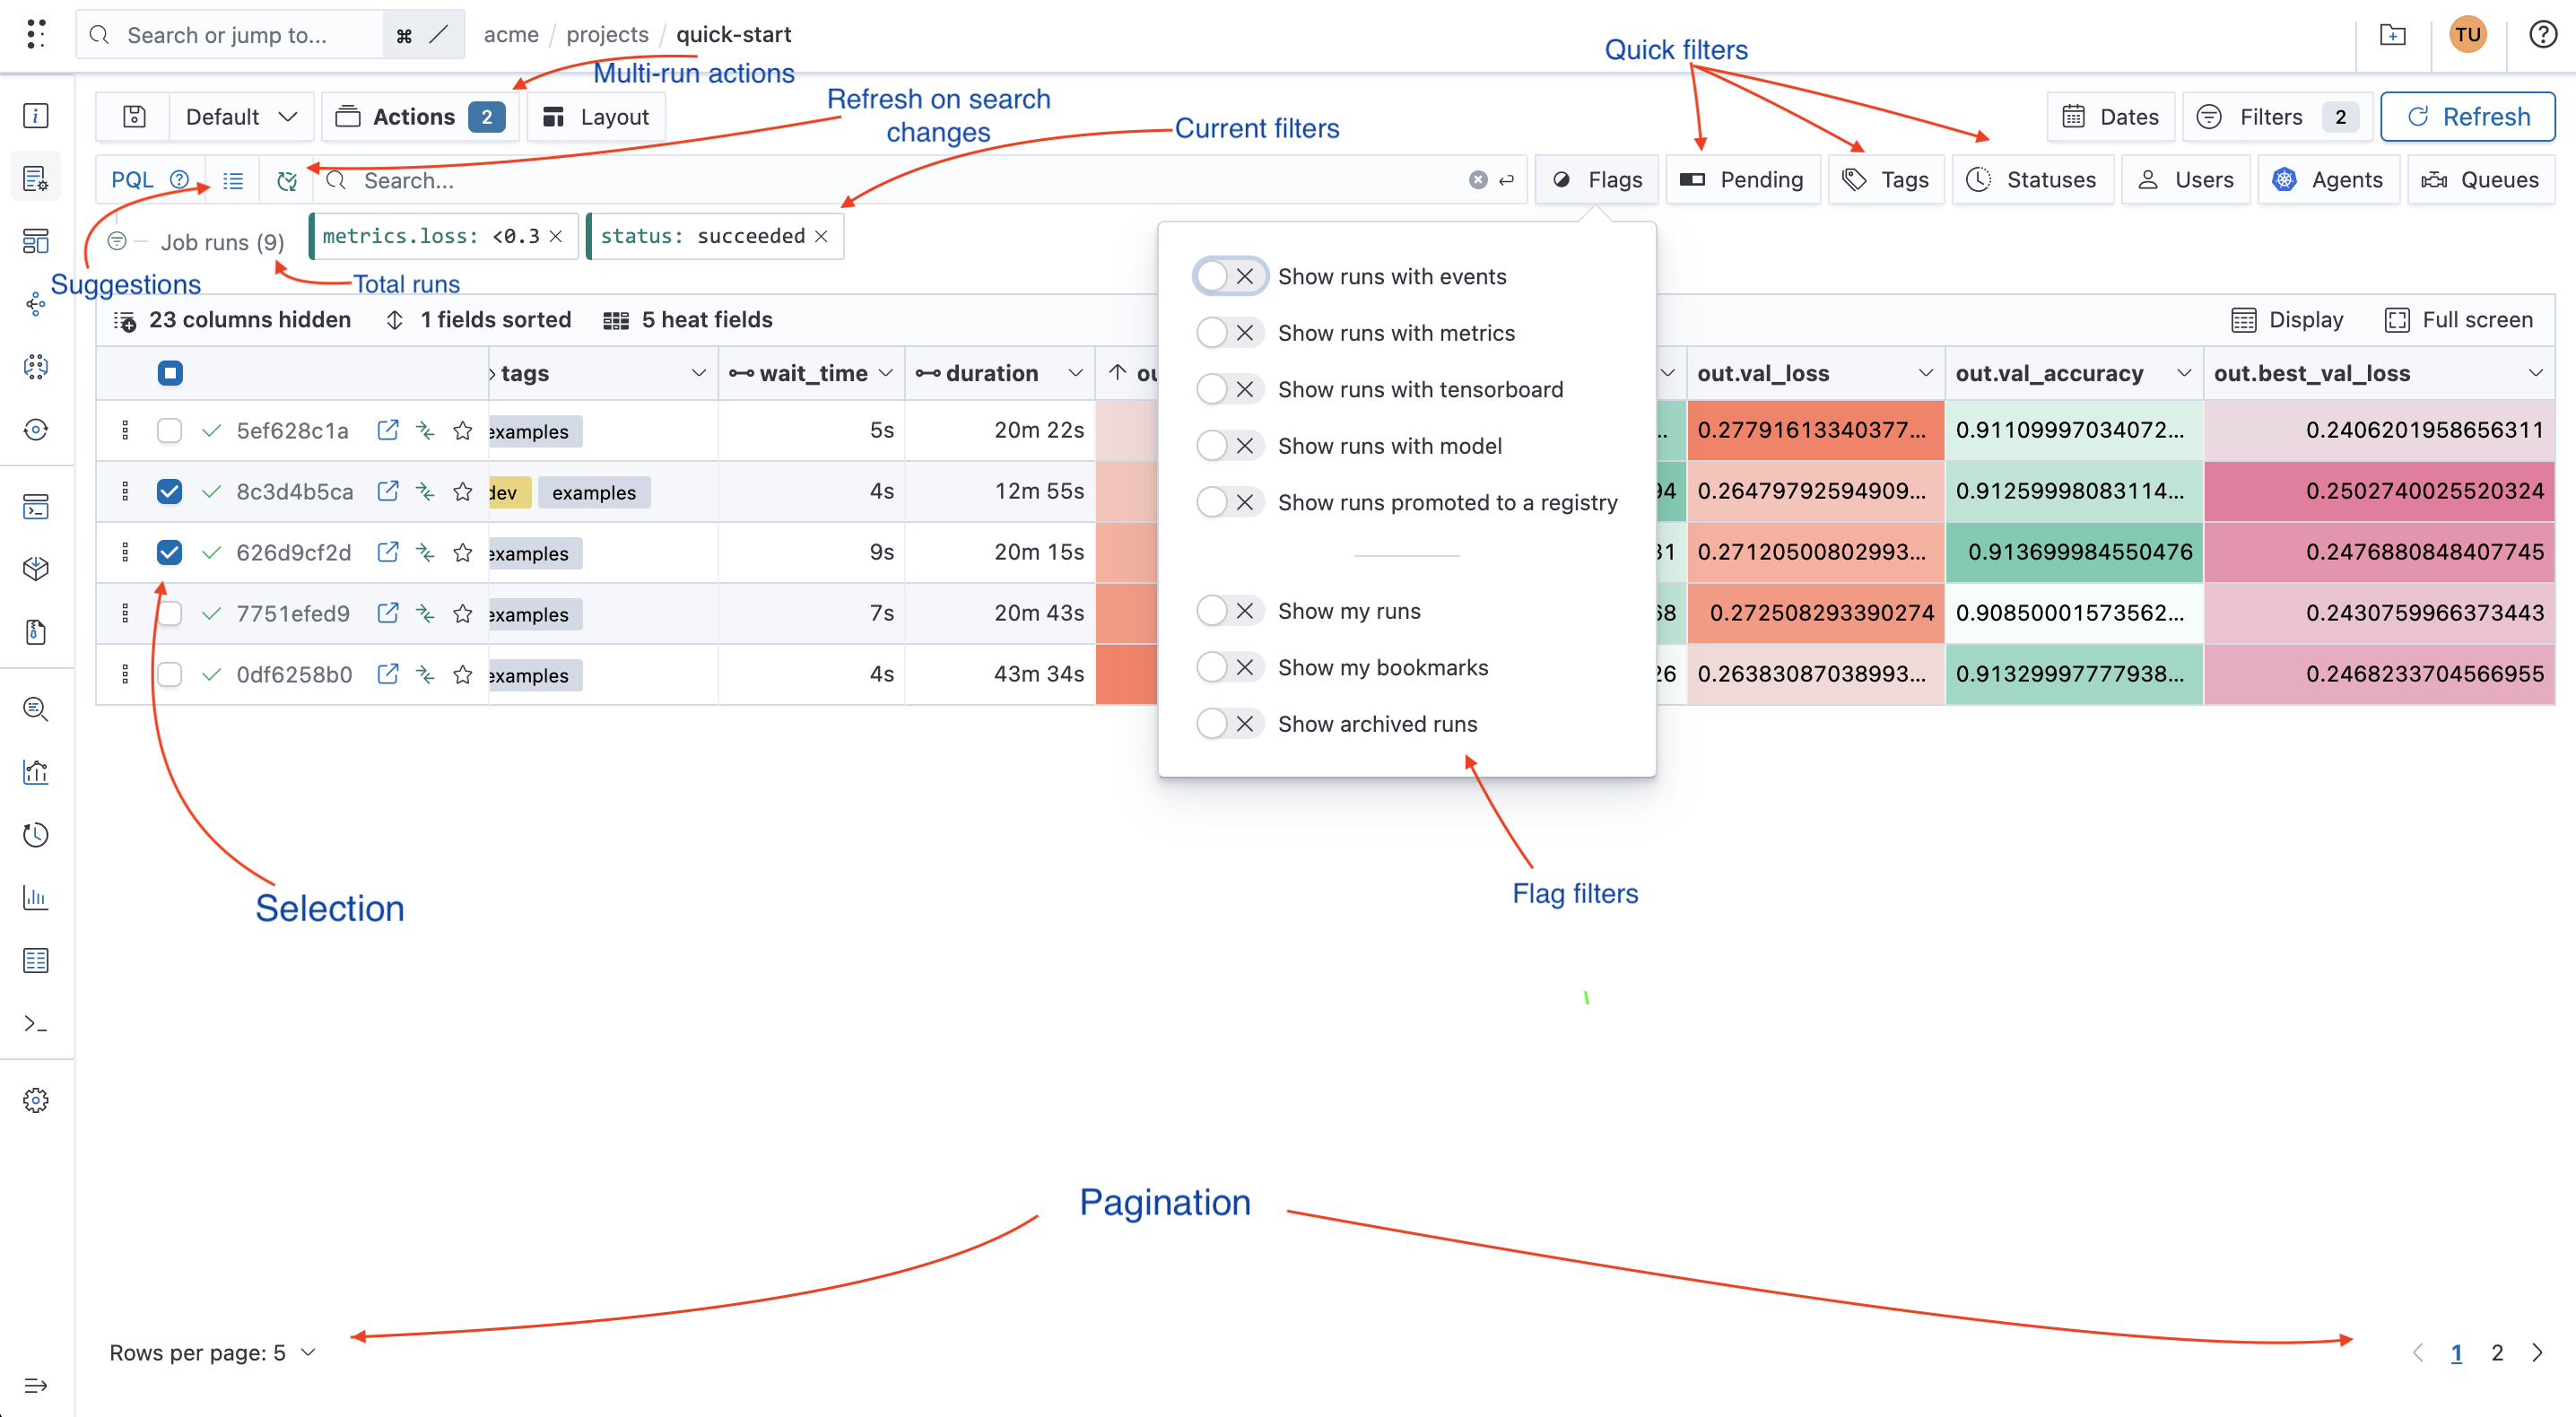
Understand ML metadata with examples of runs, datasets, and model artifacts. Learn how a metadata store connects them and how to query them in Polyaxon.
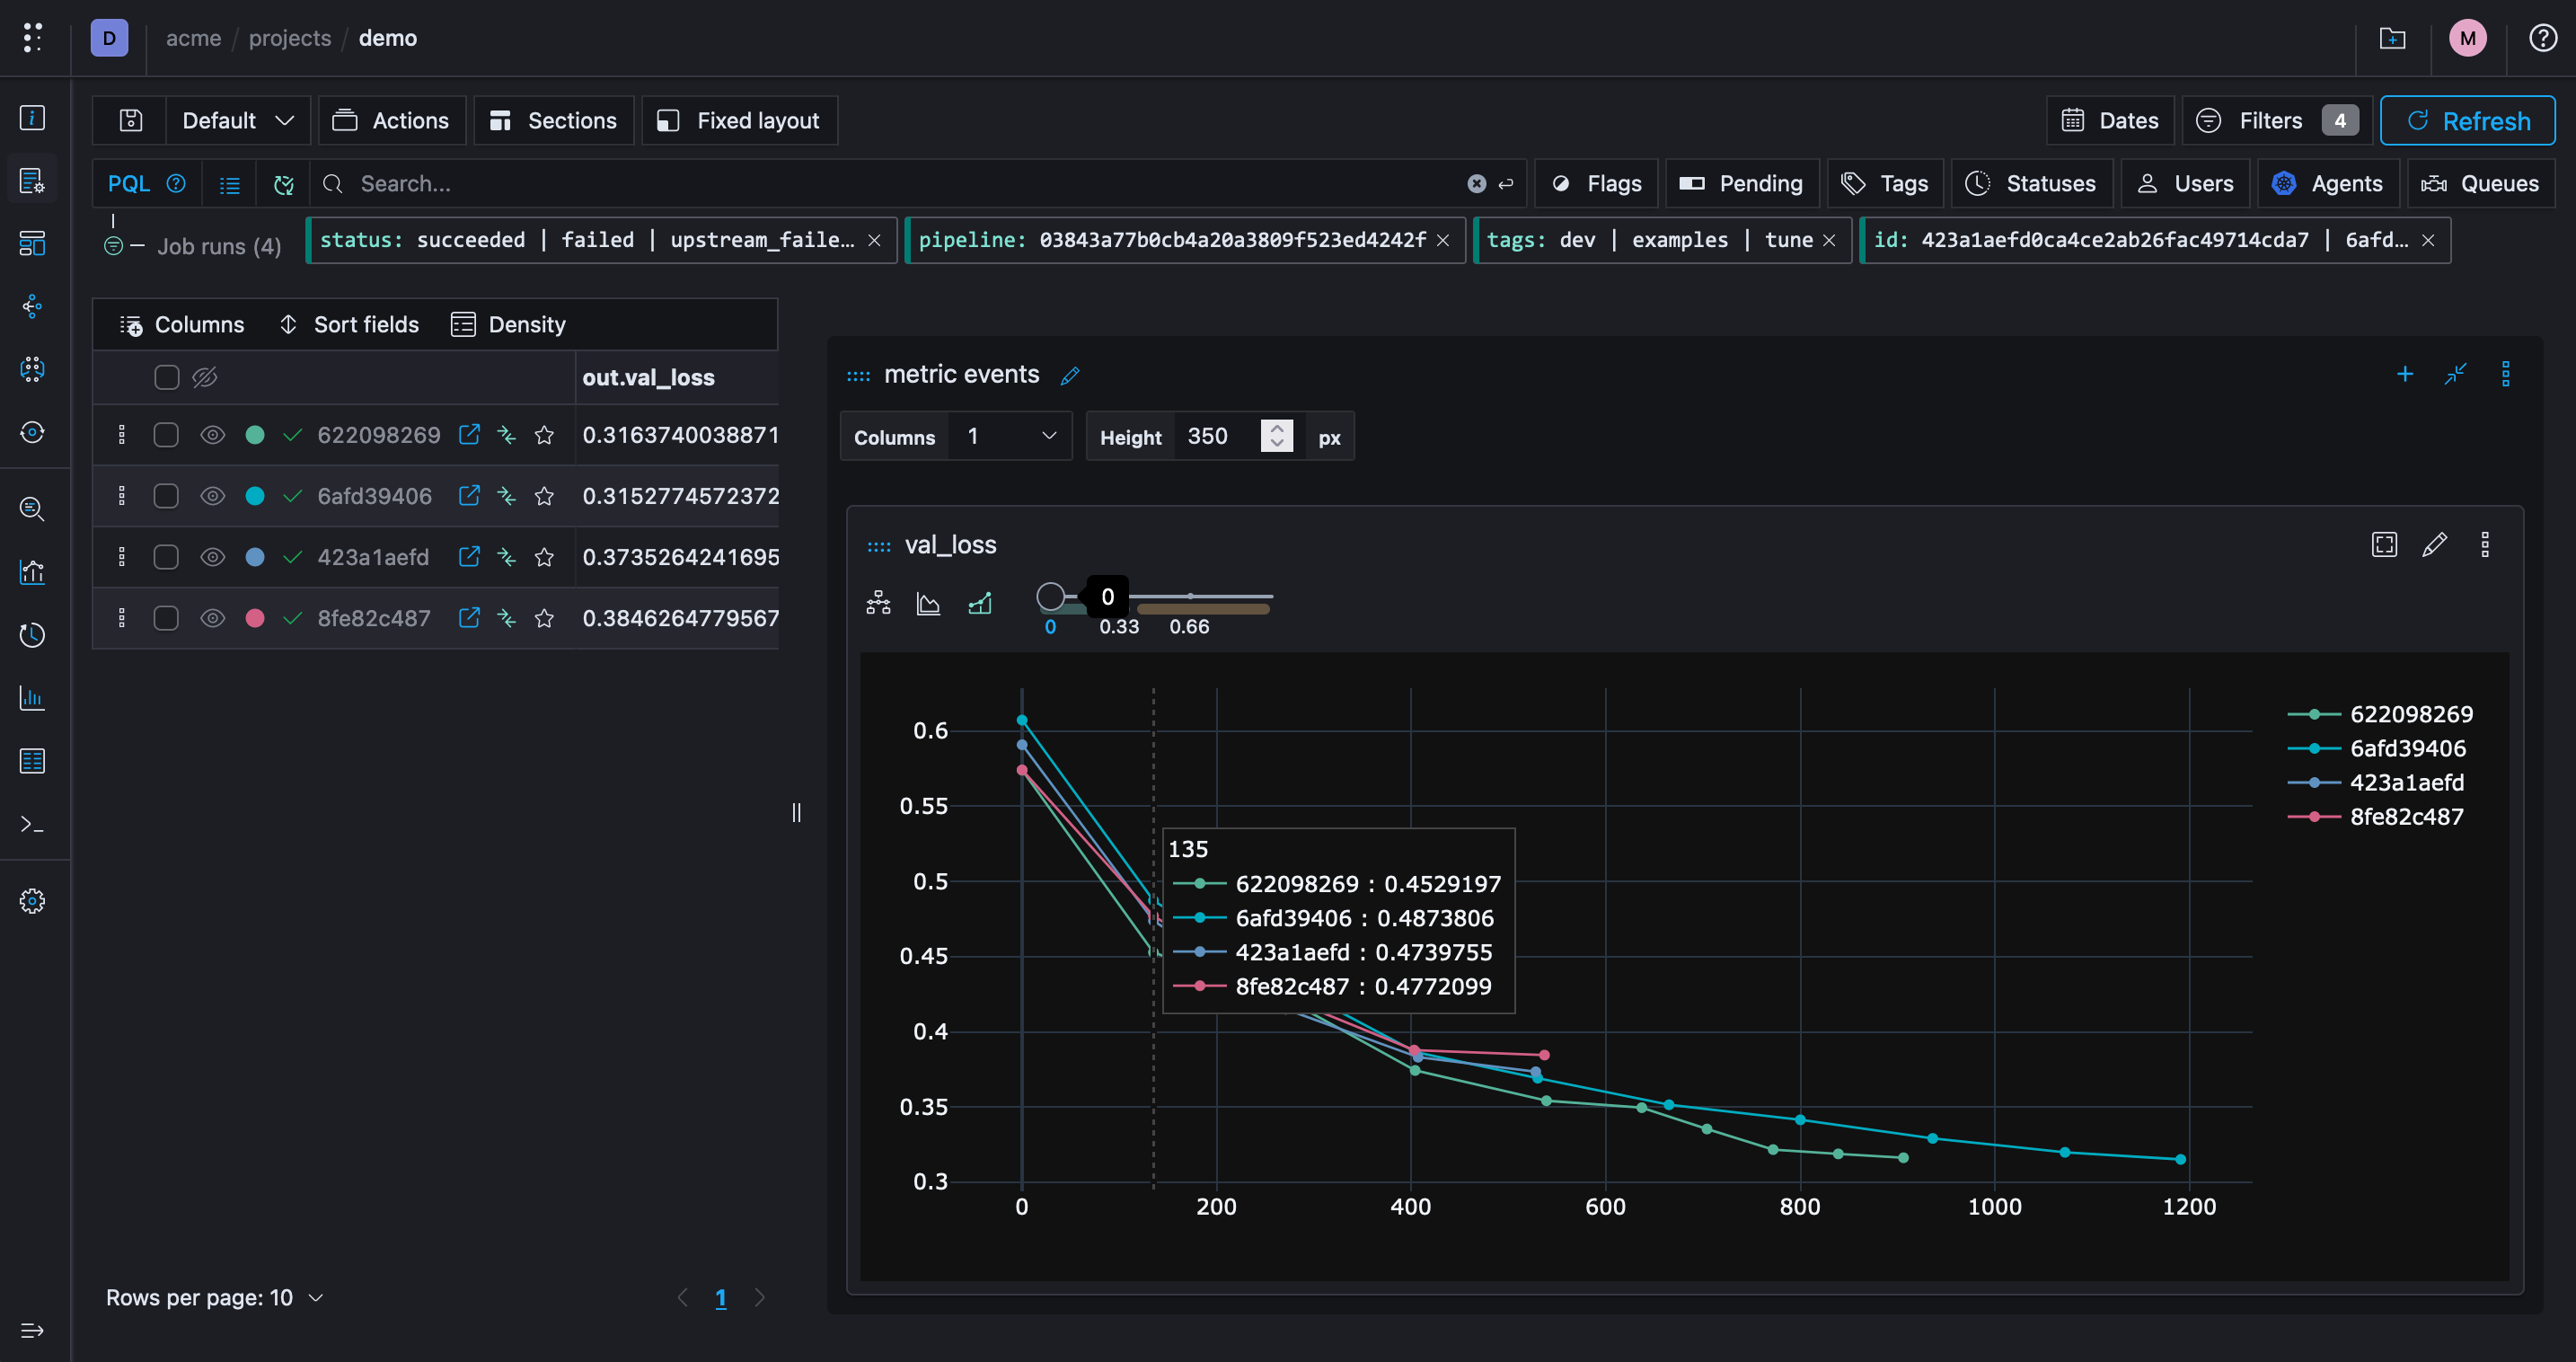
Learn what to record for each ML experiment, how to compare runs fairly, and how to log parameters, metrics, datasets, and model artifacts with Polyaxon.
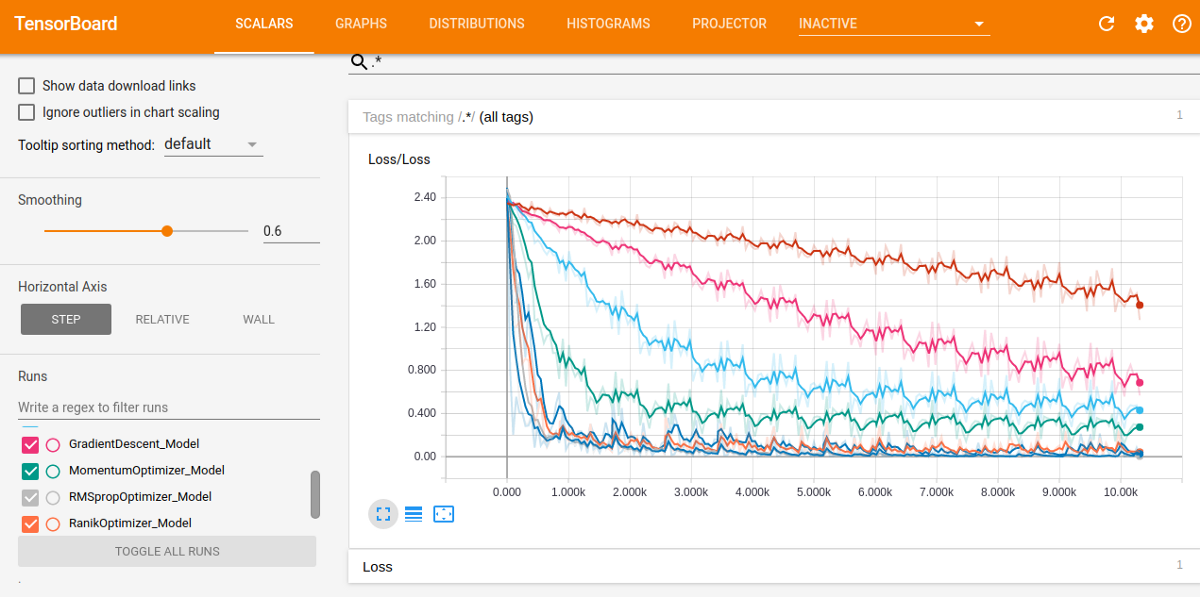
hyperparameters tuning is very important concept in order to choose the optimal hyperparameters for a given algorithm!
Control multi-cloud ML spending with normalized allocation, workload unit economics, placement policies, elastic capacity, and reproducible efficiency measurements.
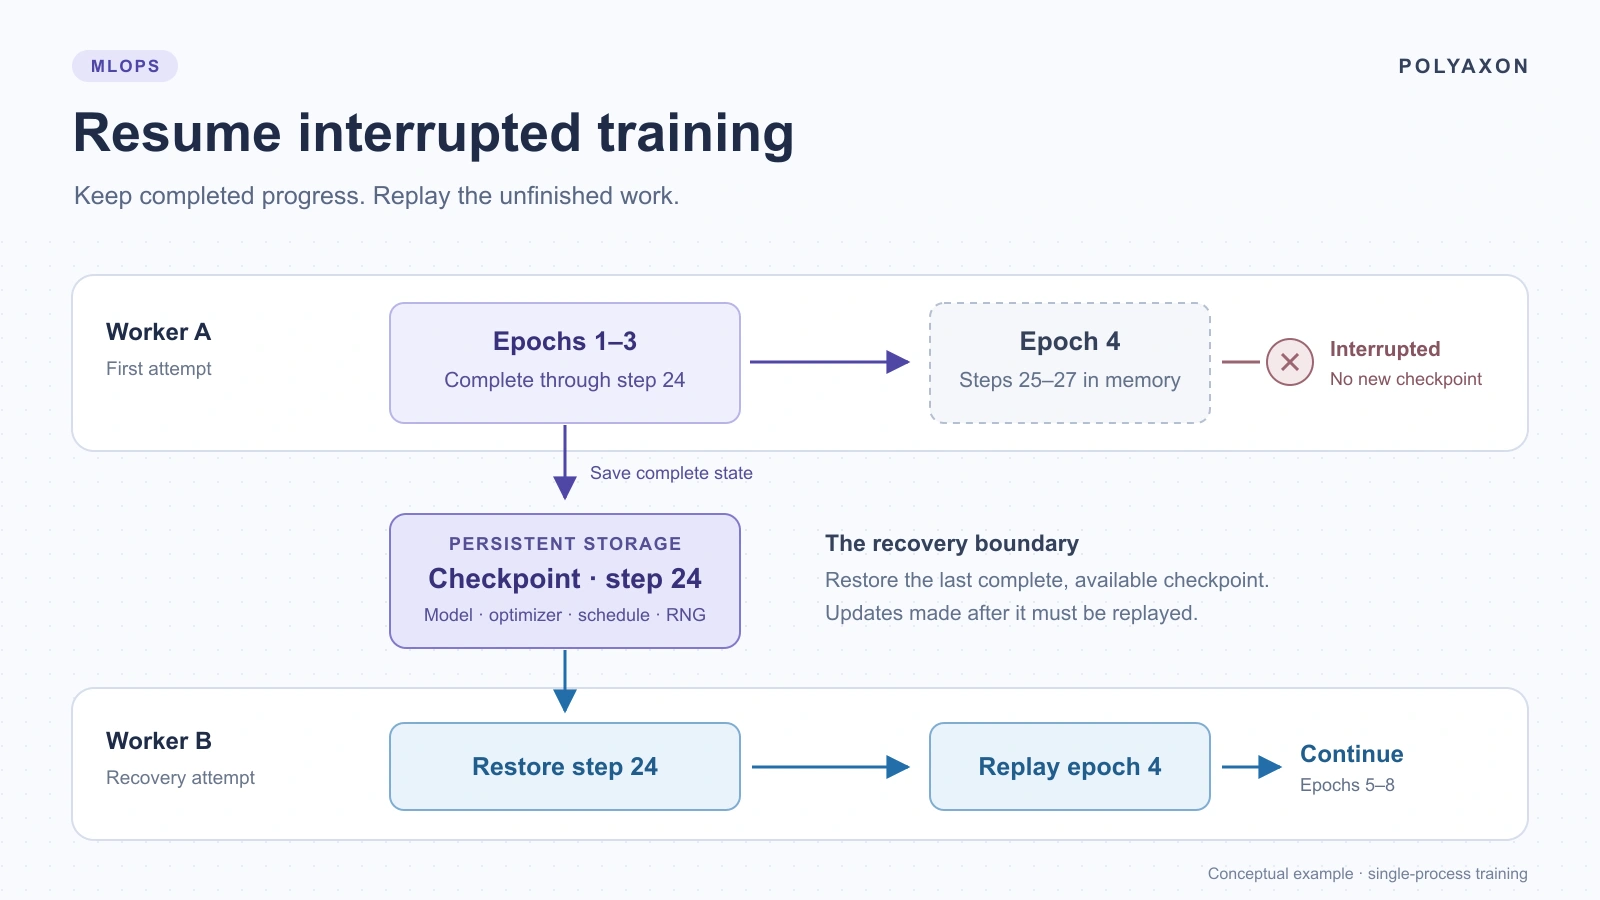
Build recoverable PyTorch training jobs with complete checkpoints, durable storage, and explicit restoration. Practice recovery locally and with Polyaxon.
Agent runtimes, Kubernetes isolation, and parallel coding workflows.
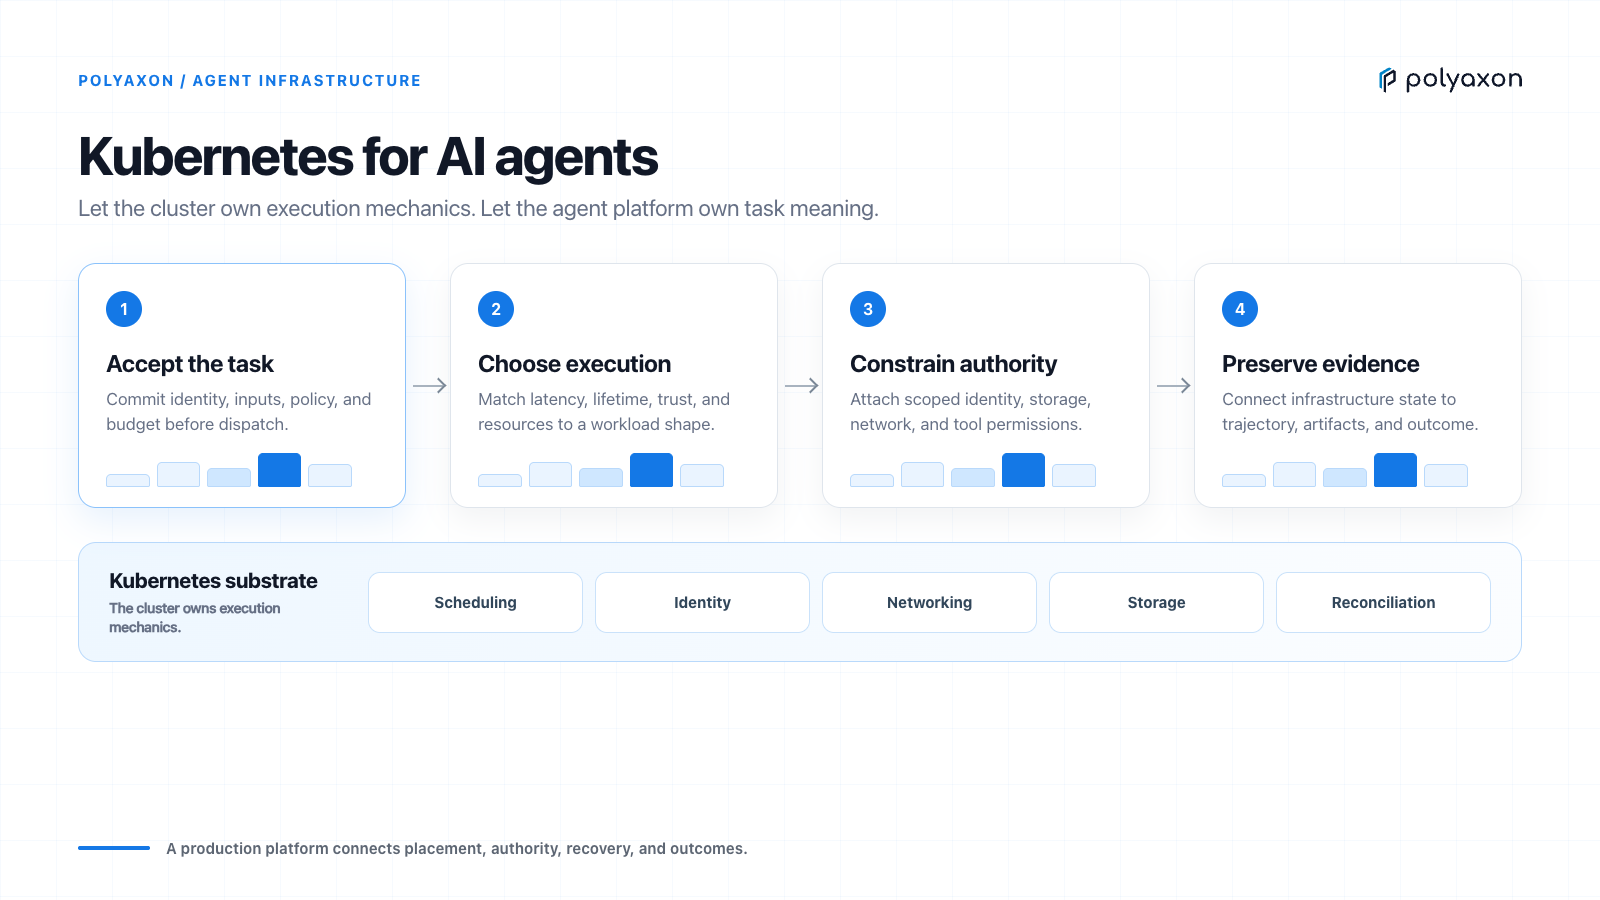
Design a Kubernetes platform for AI agents with clear workload boundaries, durable state, scoped access, resource controls, and end-to-end evidence.
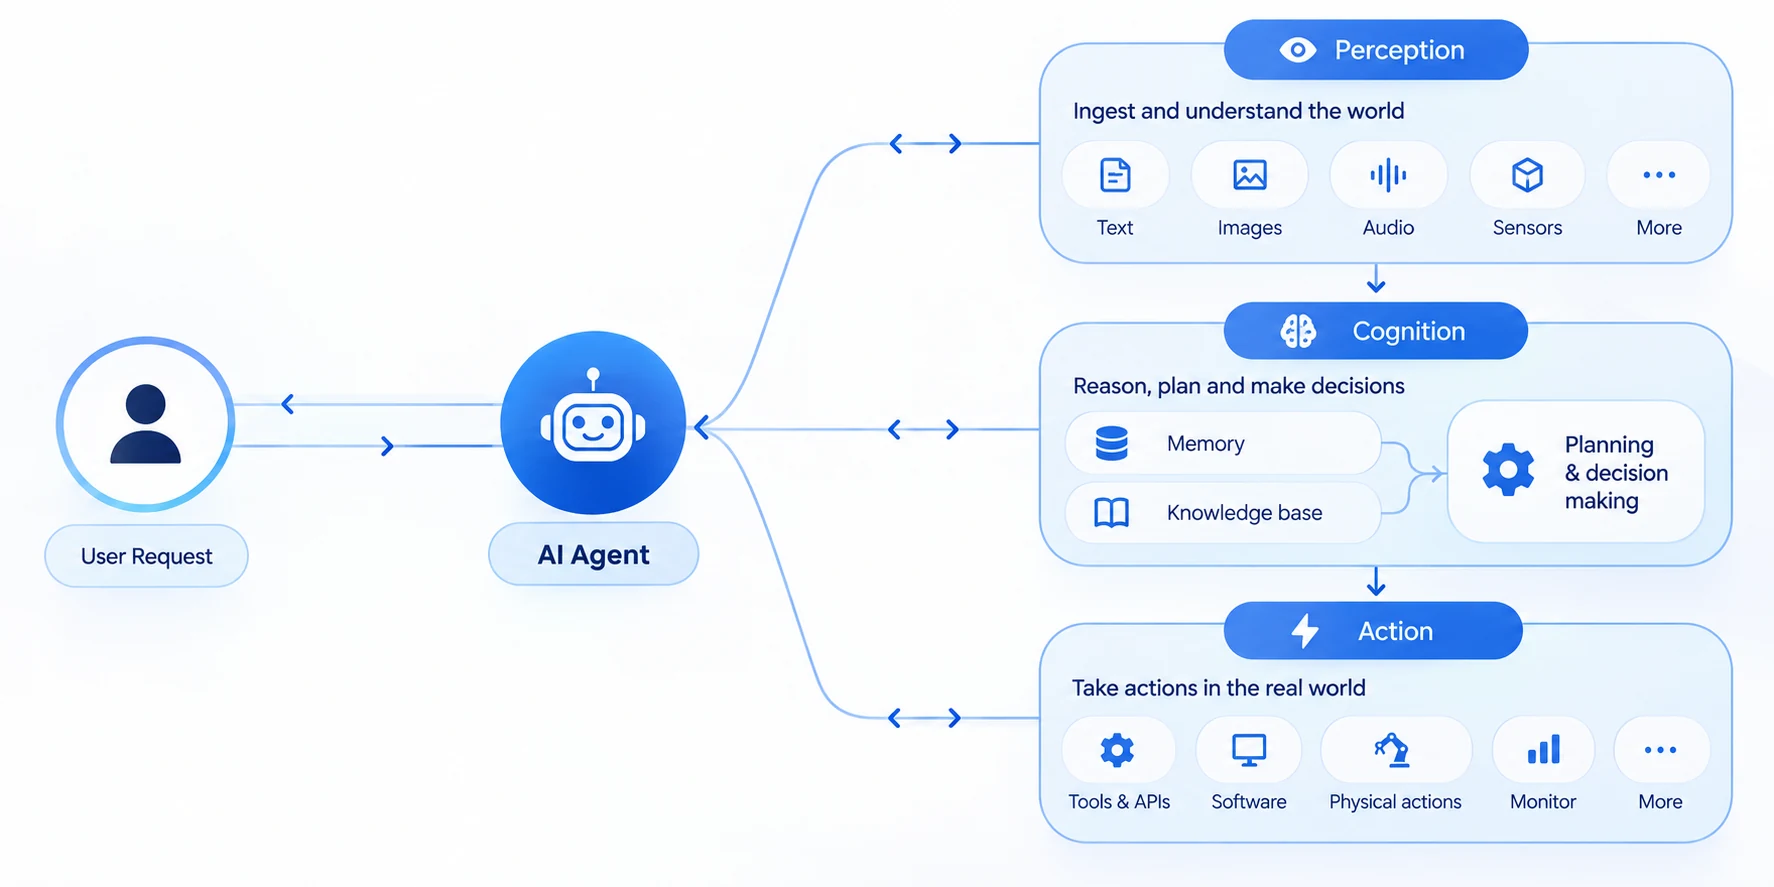
Map agent architectures to Polyaxon jobs, services, and DAGs, with concrete workload configuration and a repeatable architecture-comparison workflow.
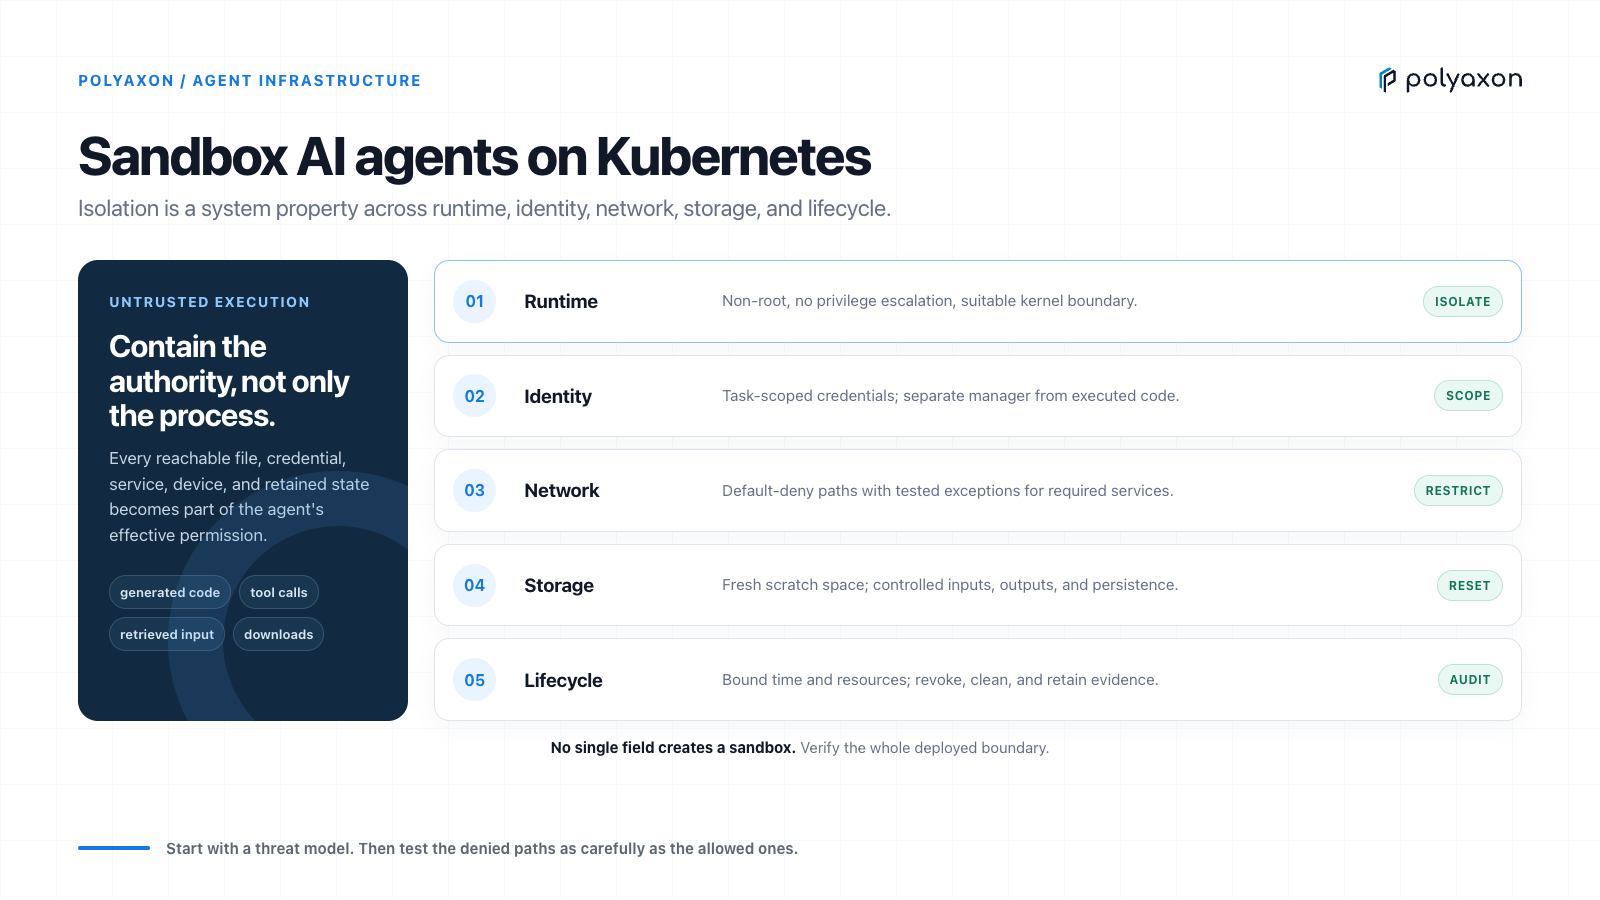
Design isolated Kubernetes execution for AI agents with a threat model, stronger runtimes, scoped identity, controlled egress, bounded storage, and auditable cleanup.

Run parallel coding agents in separate Polyaxon workspaces, collect candidate patches, evaluate independently, and merge only reviewed changes.
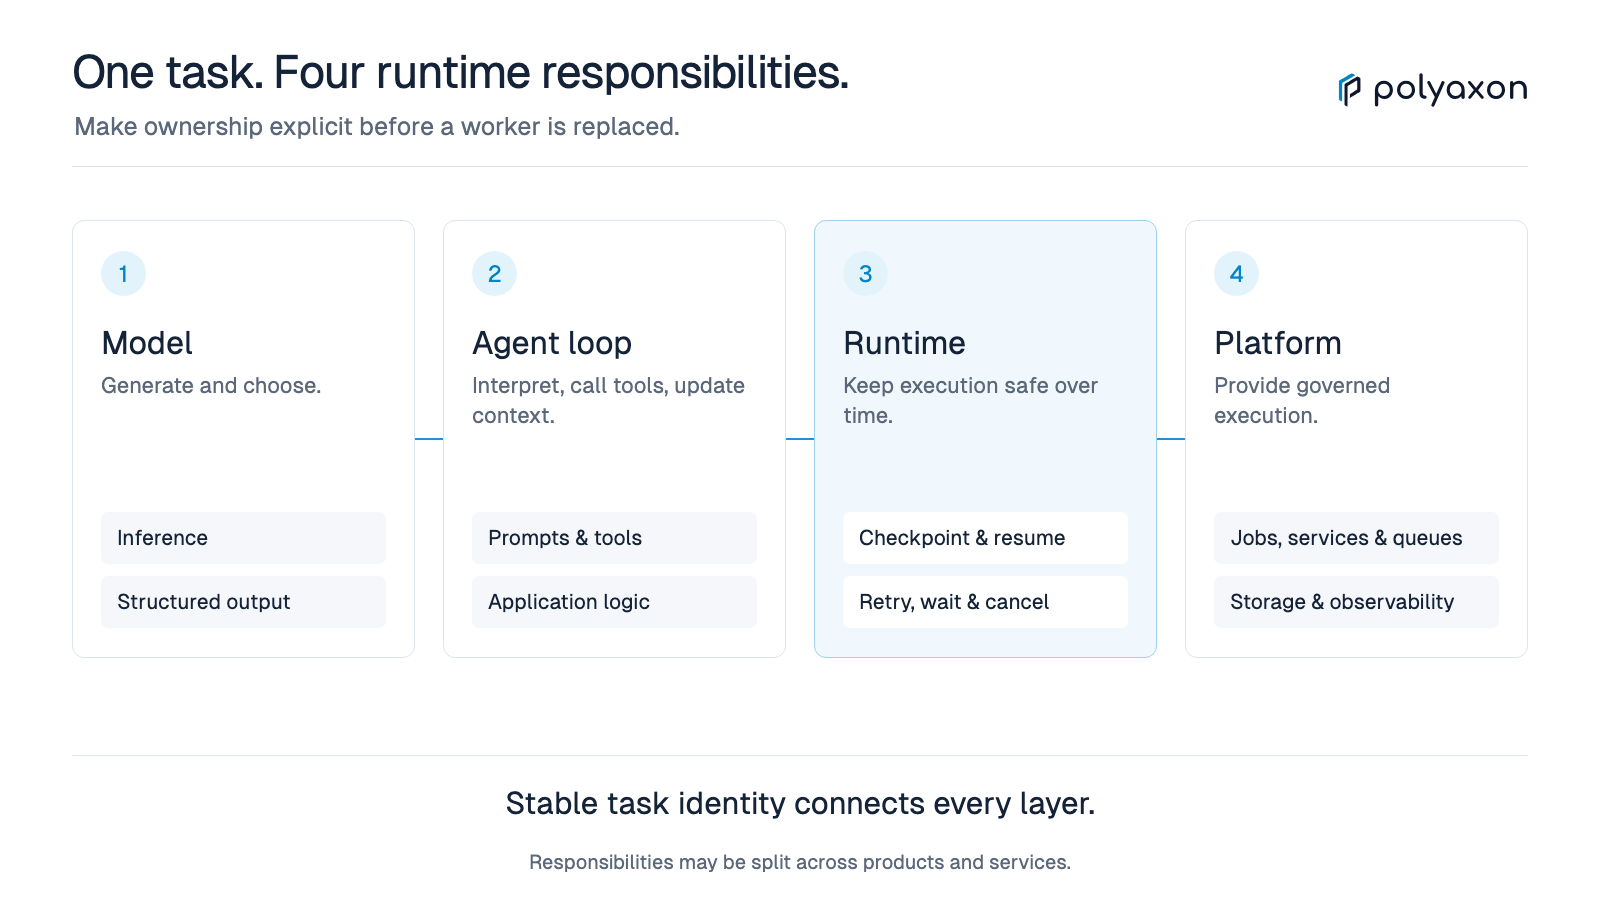
Design agent execution around durable state, safe tool retries, approval waits, and recovery, with clear responsibilities for Polyaxon and your agent framework.
Evaluate, observe, and improve LLM applications in production.
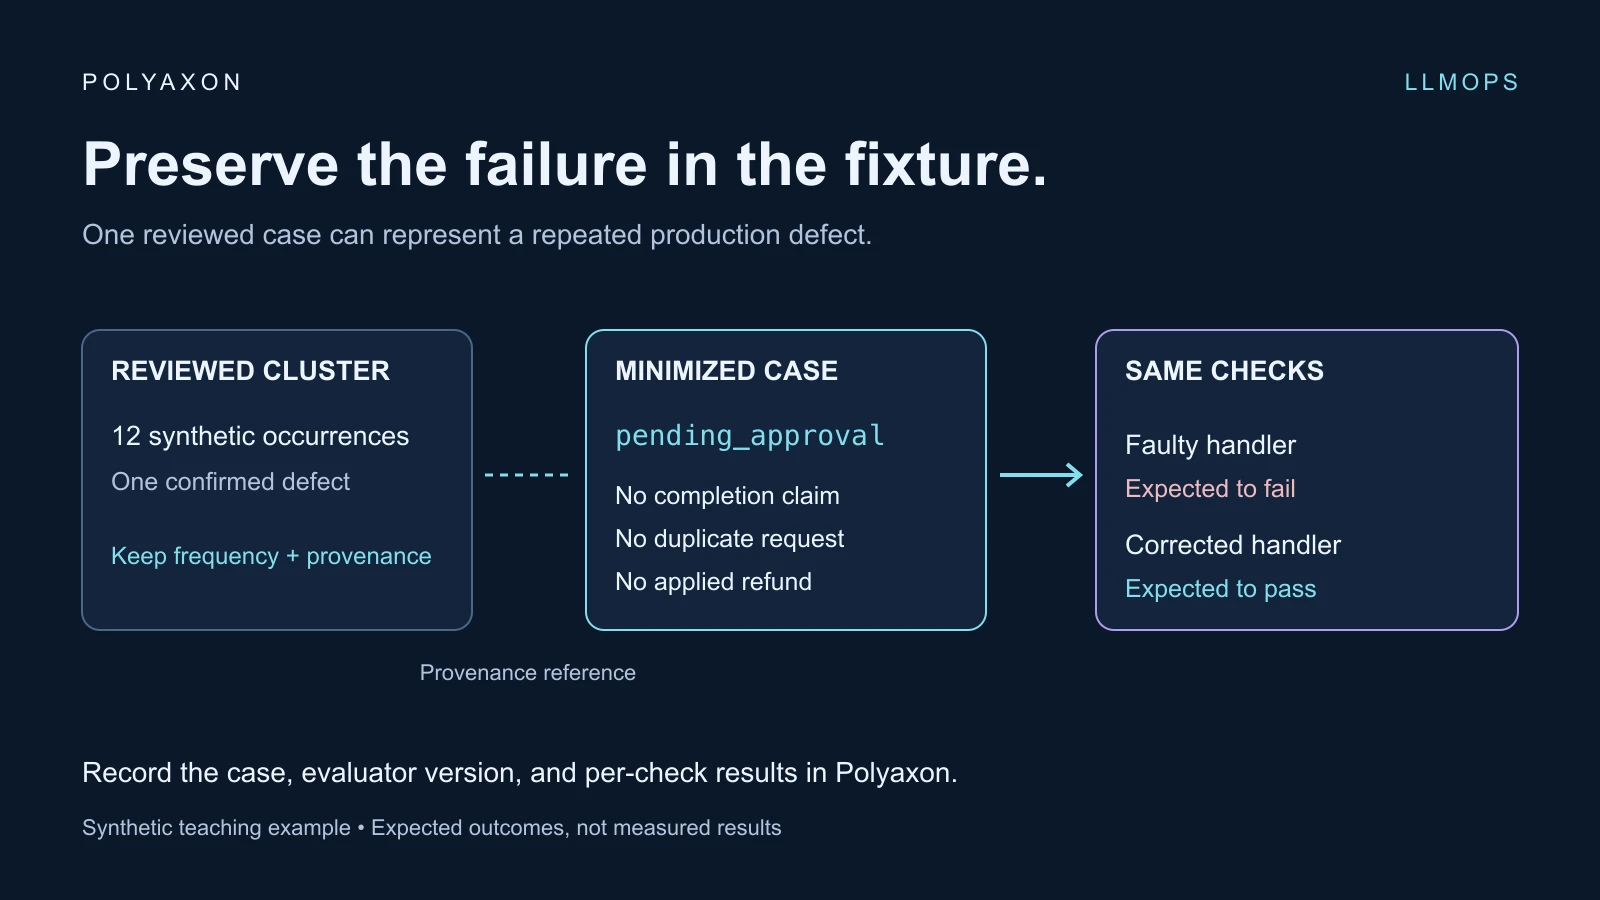
Turn a failure cluster into a reviewed regression case, preserve the causal tool response, and record baseline and candidate checks with Polyaxon.
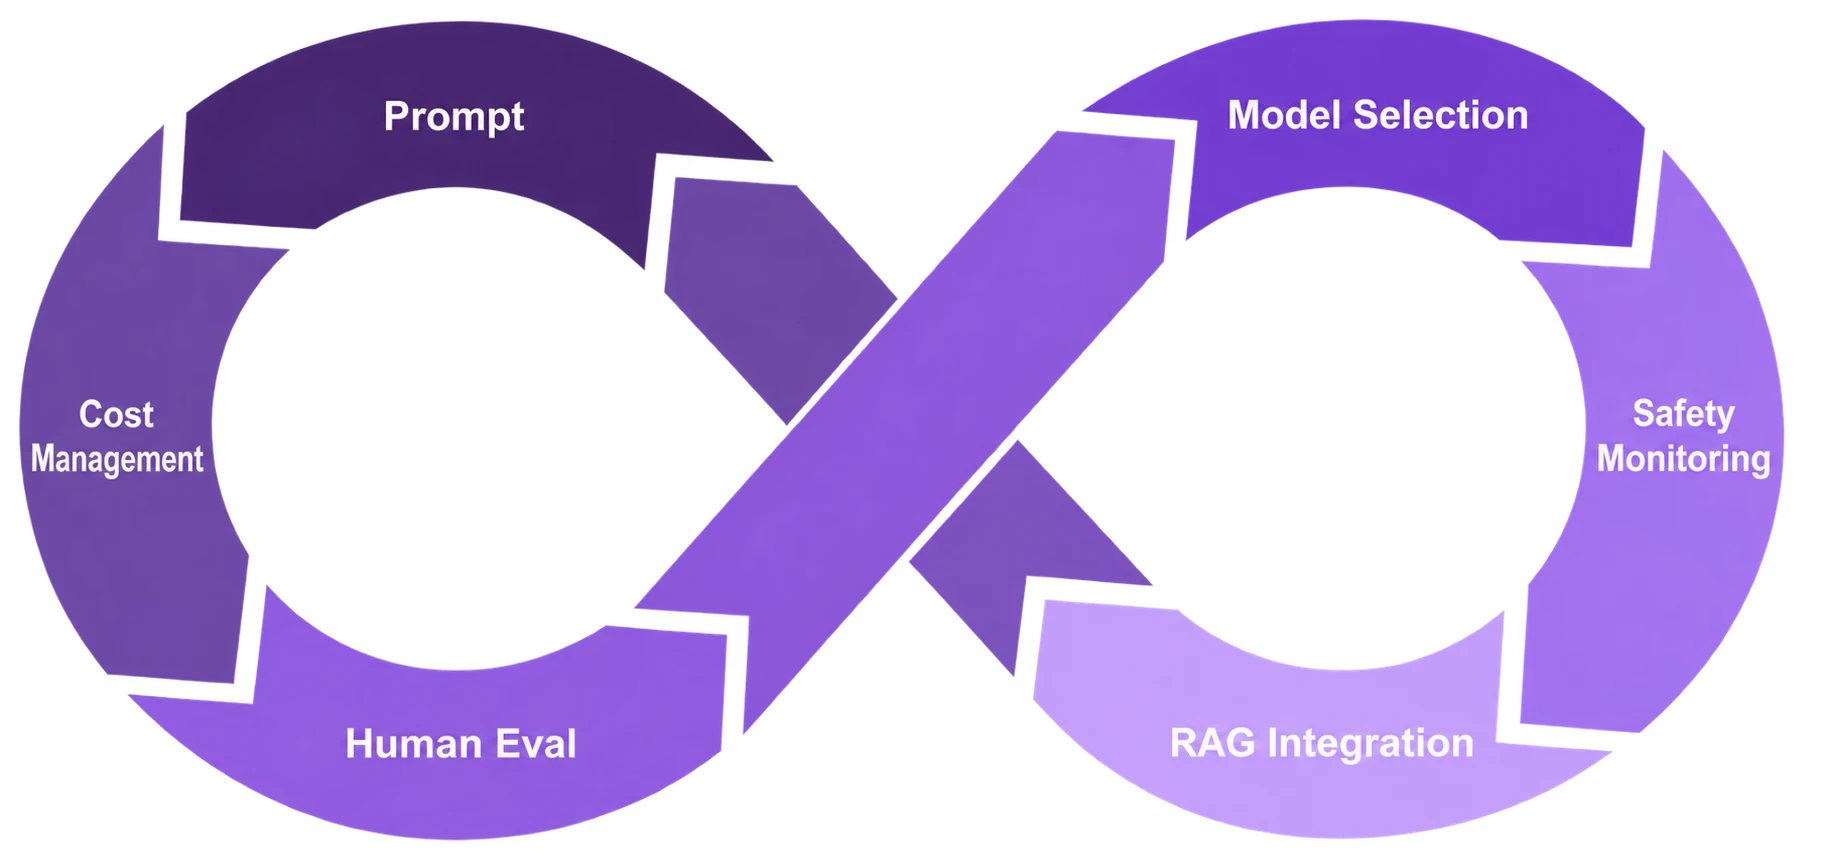
LLMOps applies repeatable development, evaluation, deployment, and observability practices to production LLM applications and AI agents.
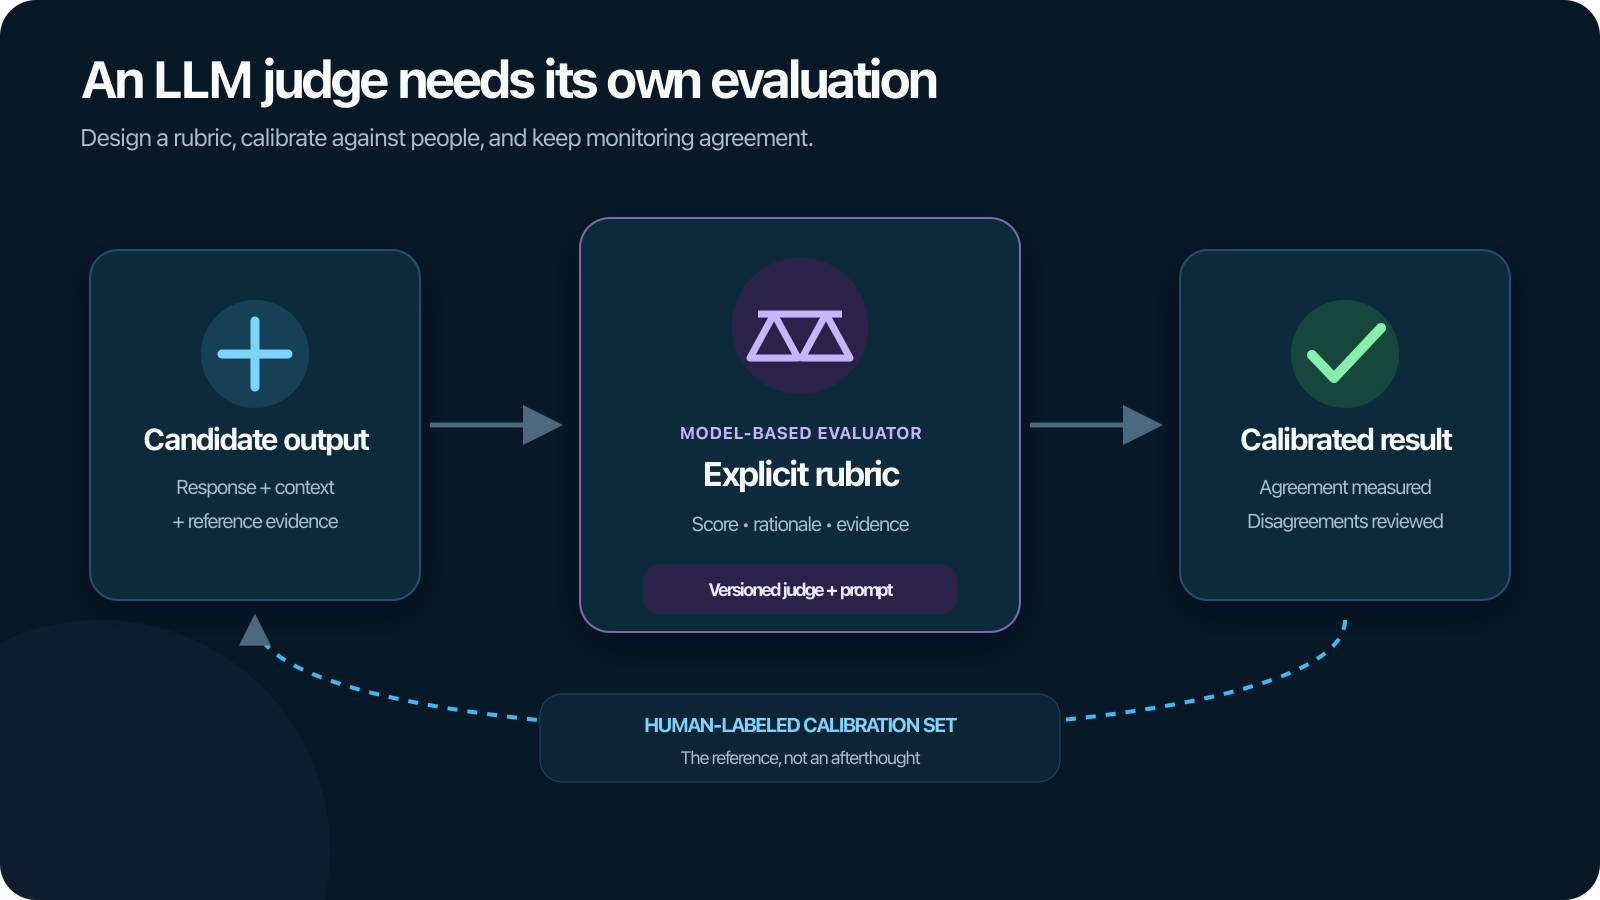
Use LLMs as scalable evaluators without treating them as ground truth: design clear rubrics, calibrate against humans, and monitor bias and drift.
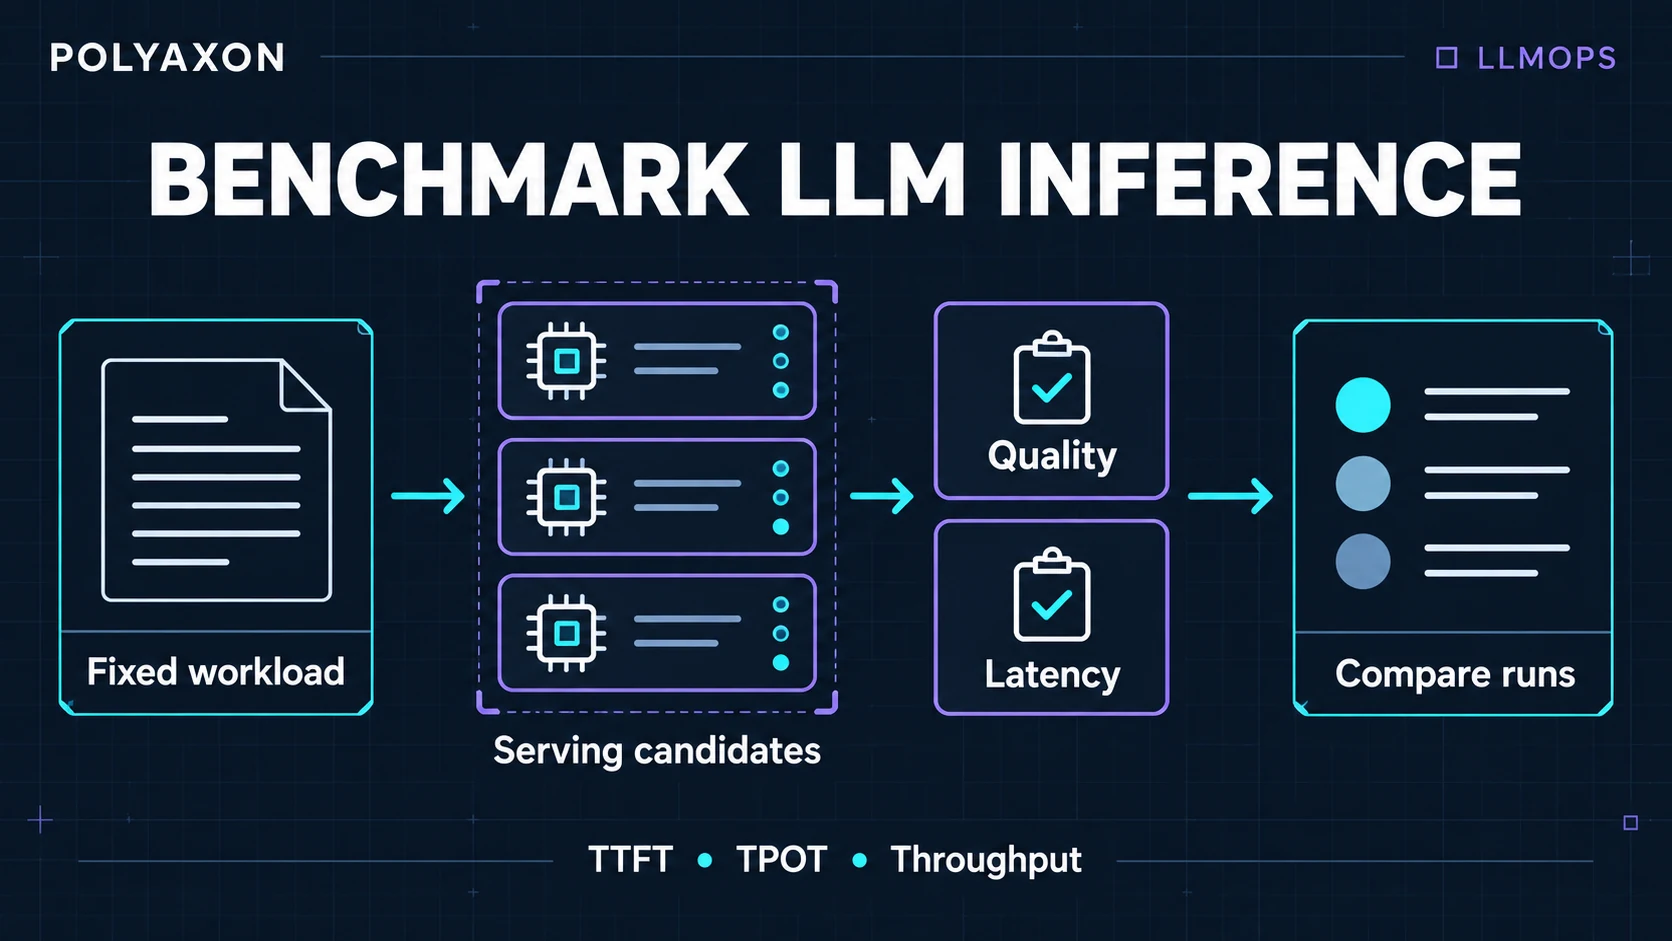
Compare inference optimizations against a fixed workload, latency limits, and quality checks, with benchmark configurations and results tracked in Polyaxon.
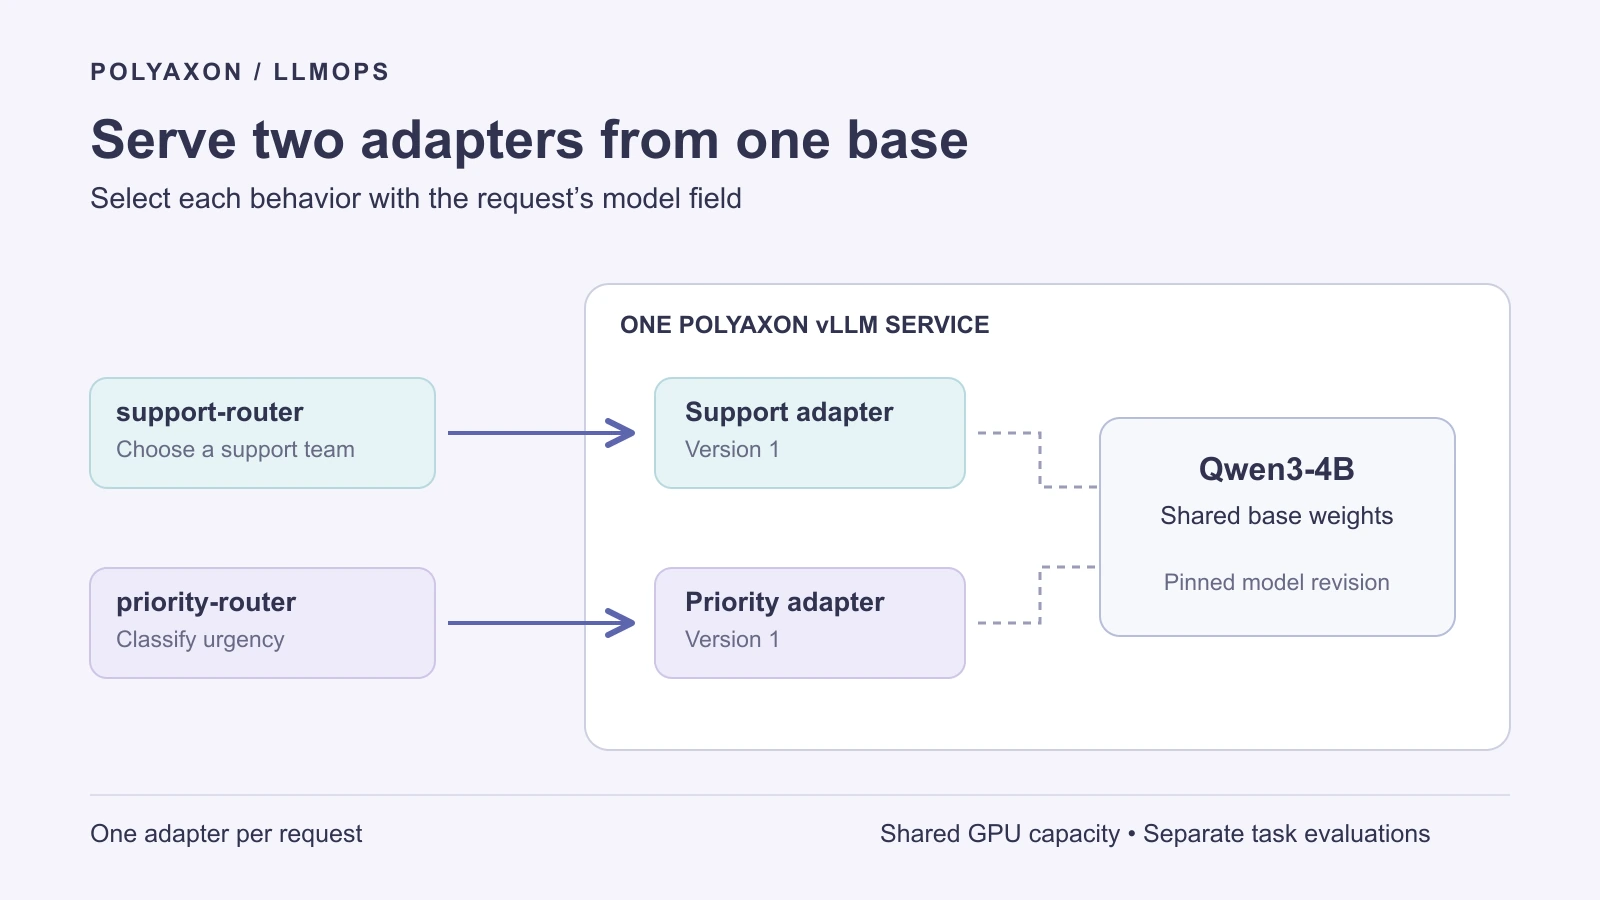
Deploy two task-specific LoRA adapters over one Qwen base model, select them by name, and measure quality and shared GPU capacity with Polyaxon.
Build reliable data pipelines and preserve the evidence behind your models.
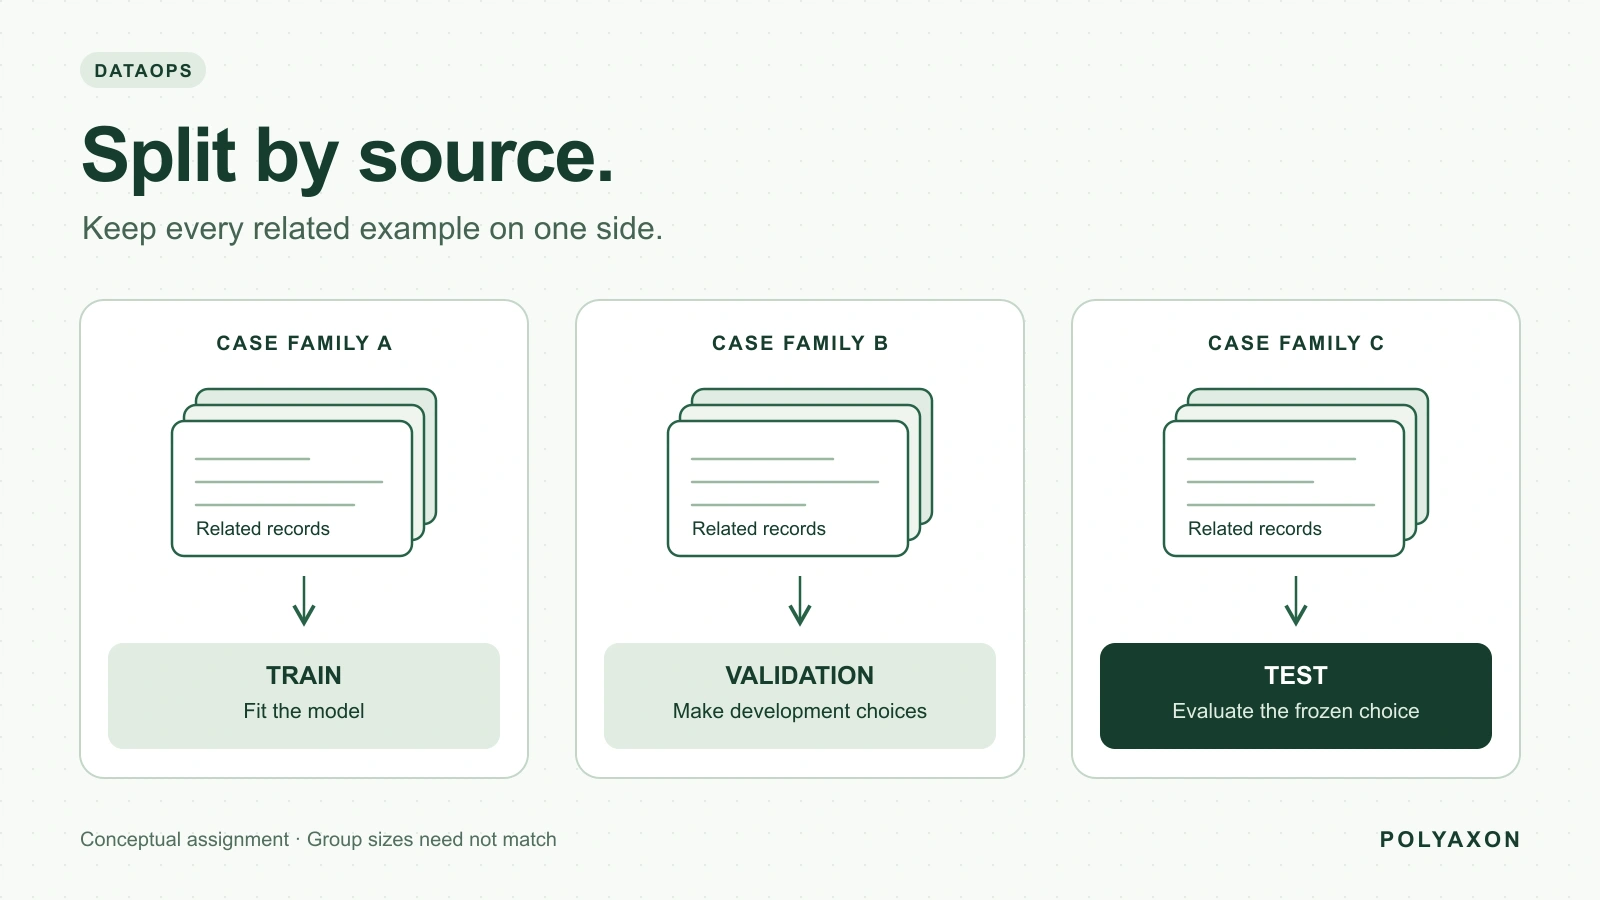
Choose evaluation boundaries, keep related examples together, audit duplicate overlap, and retain reproducible split manifests for ML and LLM experiments.
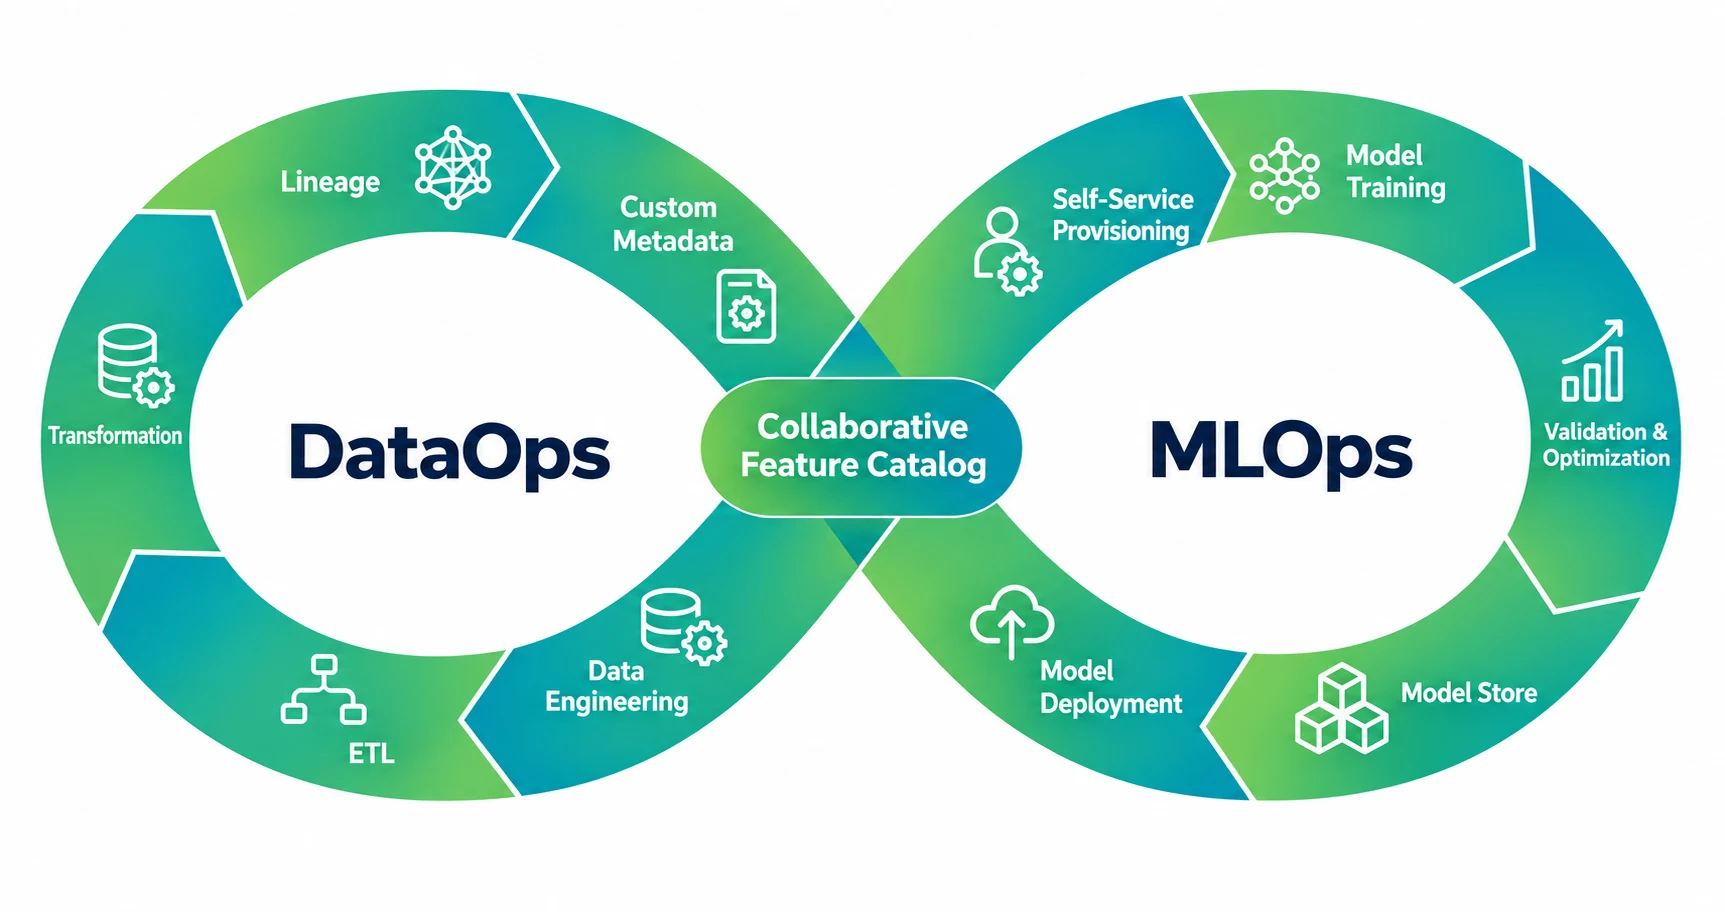
DataOps delivers reliable data; MLOps delivers reliable ML systems. Compare their responsibilities, checks, and handoffs using a practical example.
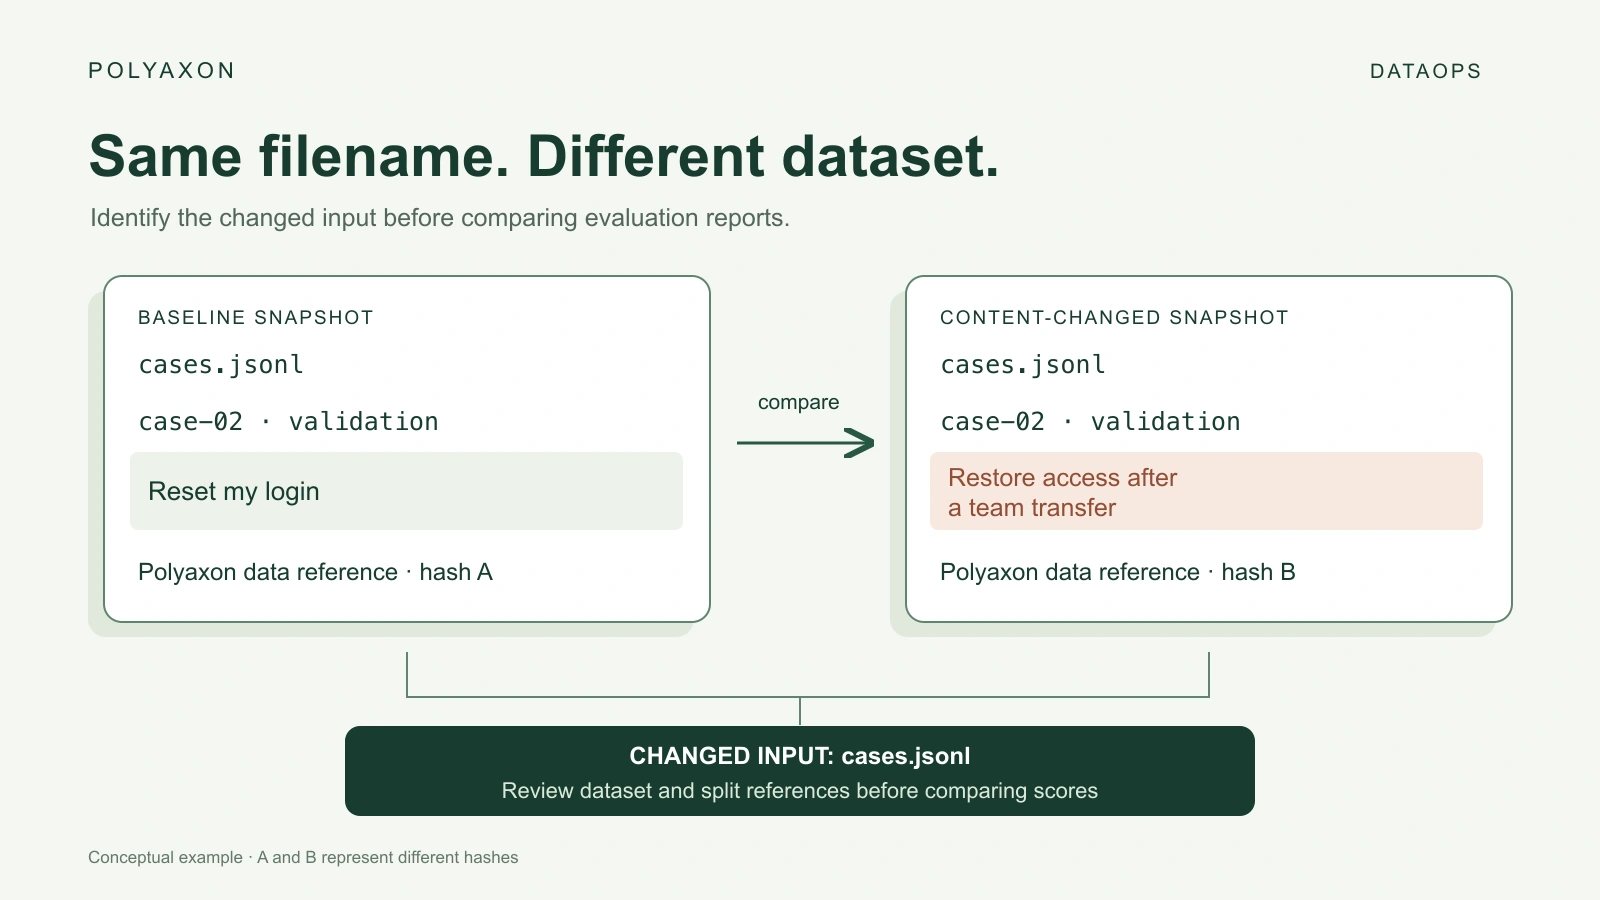
Use Polyaxon data references, artifact logging, and registered versions to retain the dataset and split behind each evaluation.
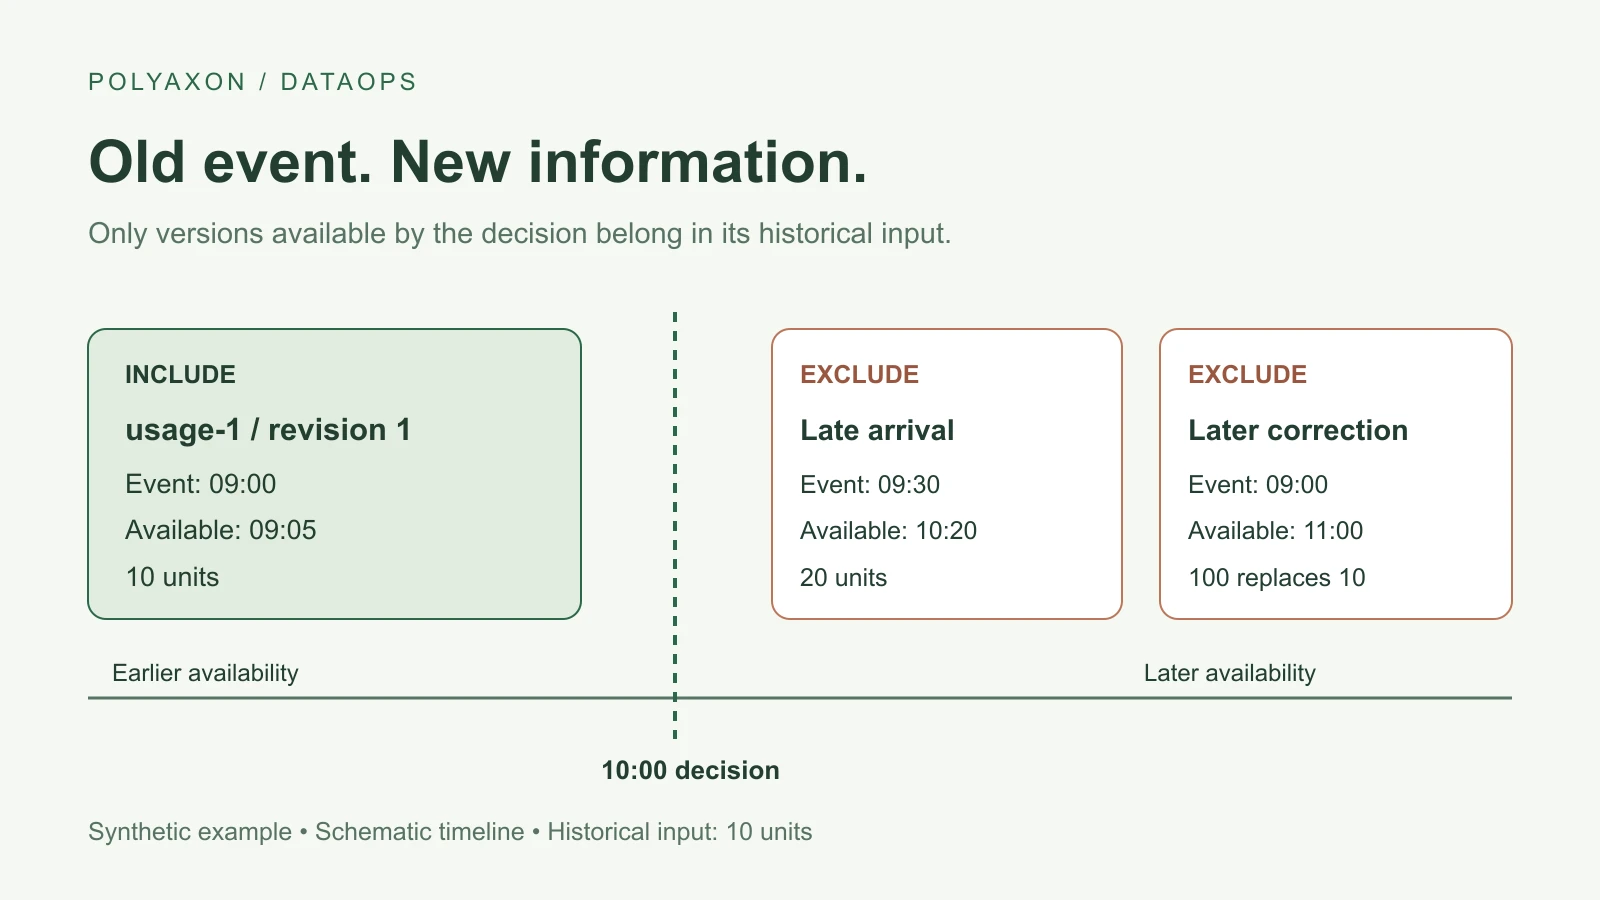
Reconstruct evaluation features using event time and actual availability time, excluding late arrivals and later corrections while preserving the source versions in Polyaxon.
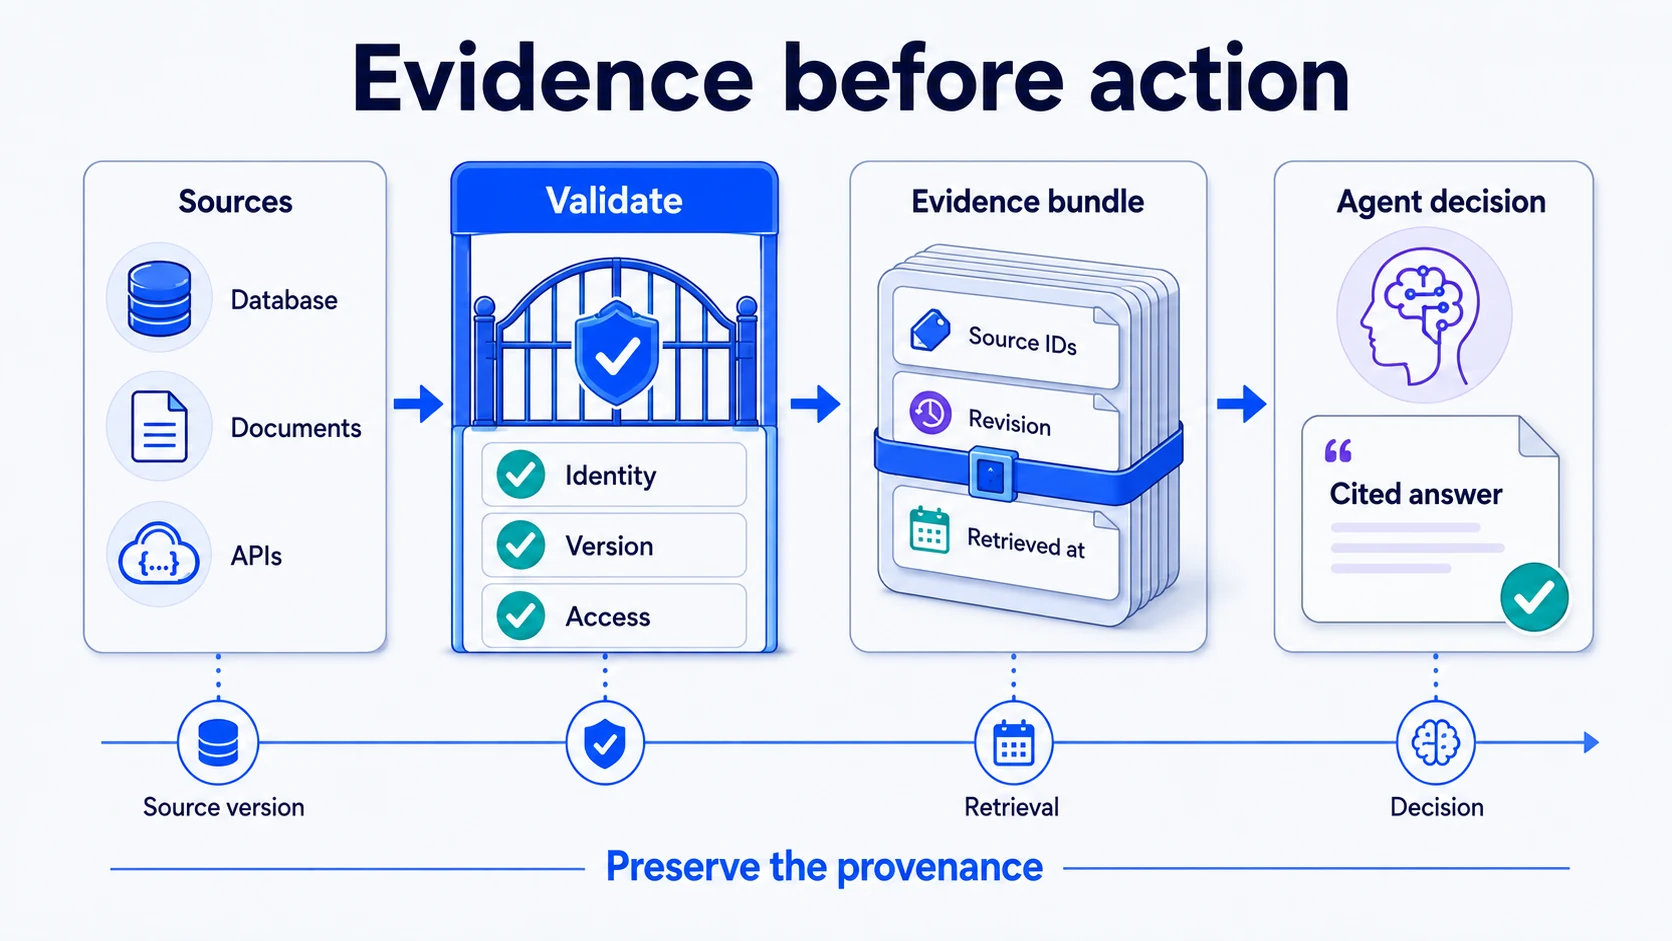
Design agent data paths that preserve source identity, versions, permissions, freshness, retrieval evidence, and verification results.
The latest guides, tutorials, and product updates.
Limit aggregate GPU requests with ResourceQuota, supply CPU and memory defaults, and align Polyaxon resource profiles and queues with namespace budgets.
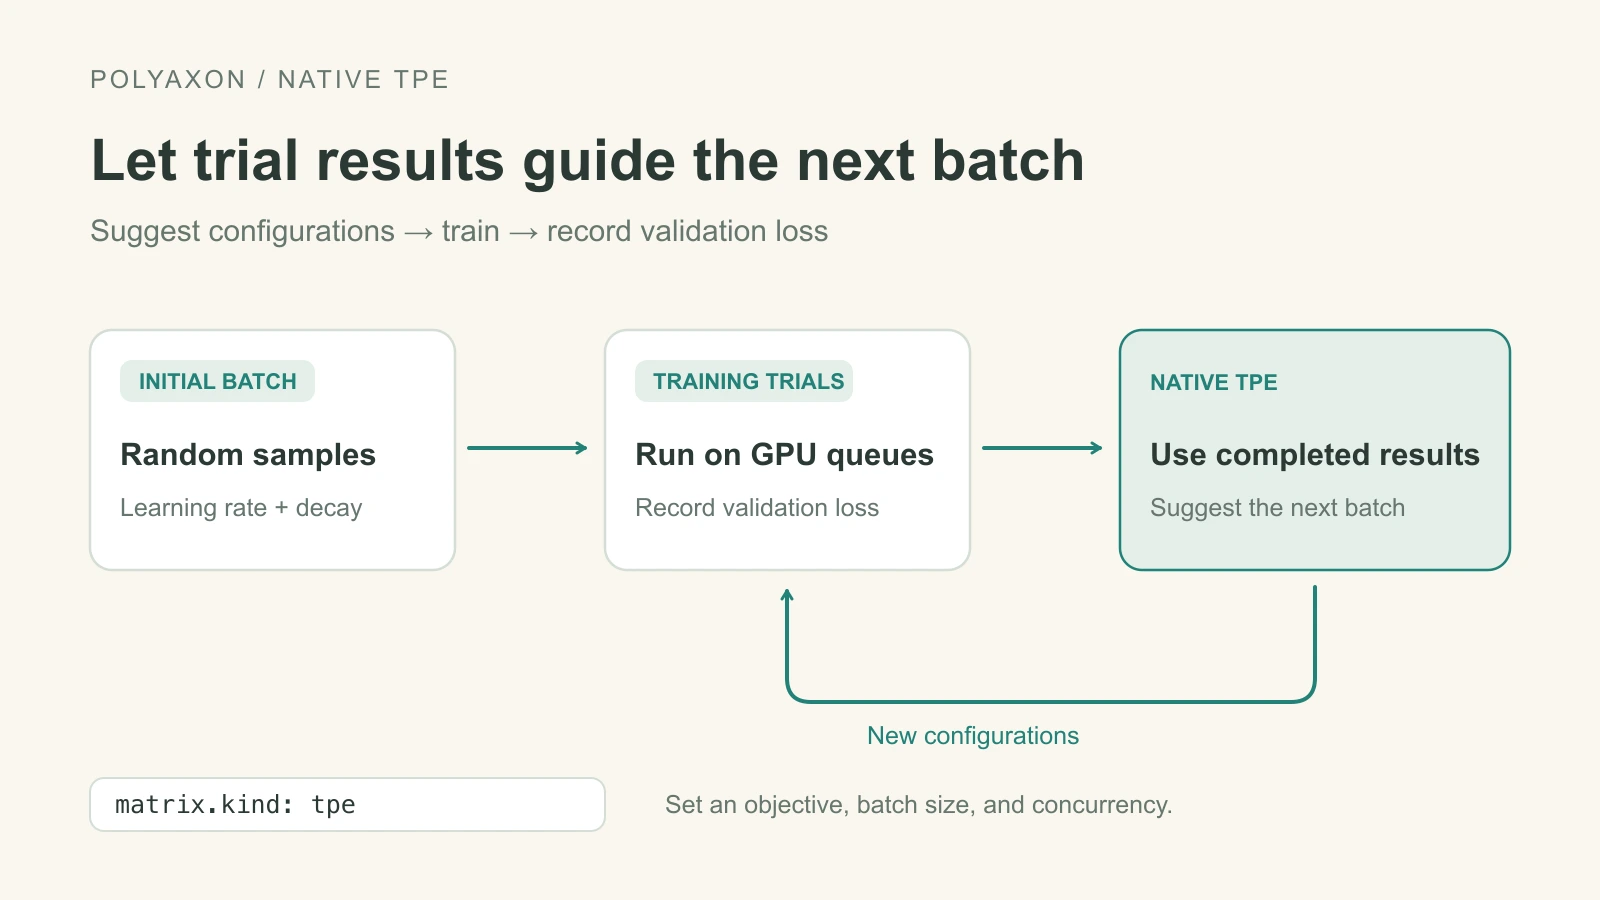
Use completed trial results to guide hyperparameter choices with native TPE, run GPU training trials, and compare validation loss in Polyaxon.
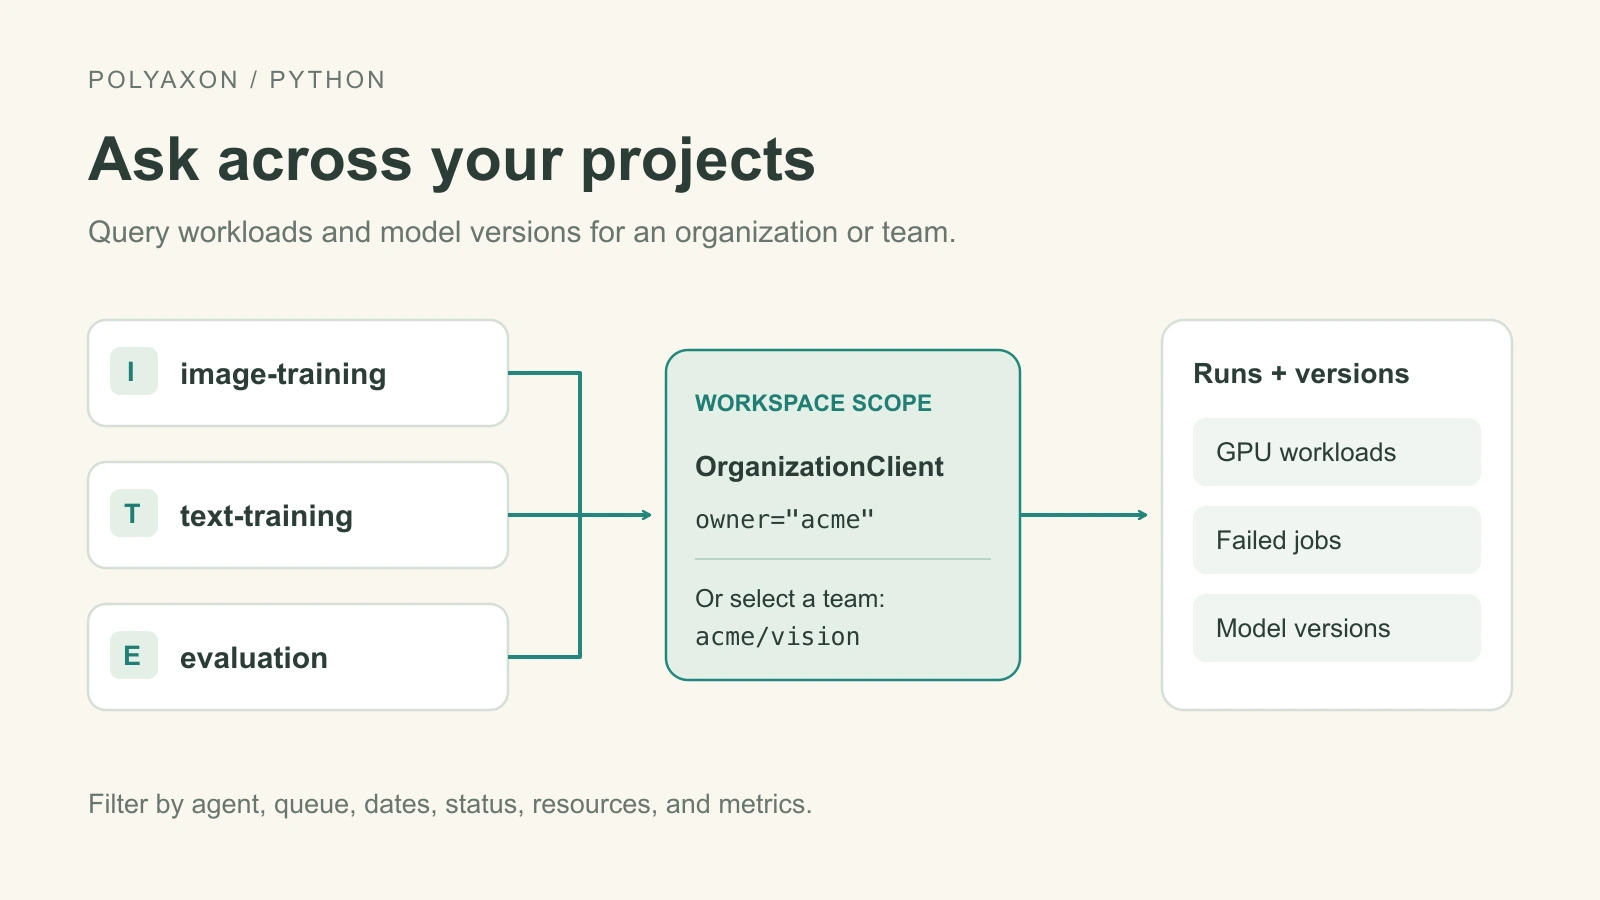
Use Polyaxon's organization and team APIs to inspect GPU workloads by agent, count model versions, and calculate job failure rates across projects.
Set a PodDisruptionBudget around usable inference capacity, inspect blocked evictions, and account for replacement GPUs and model warmup.
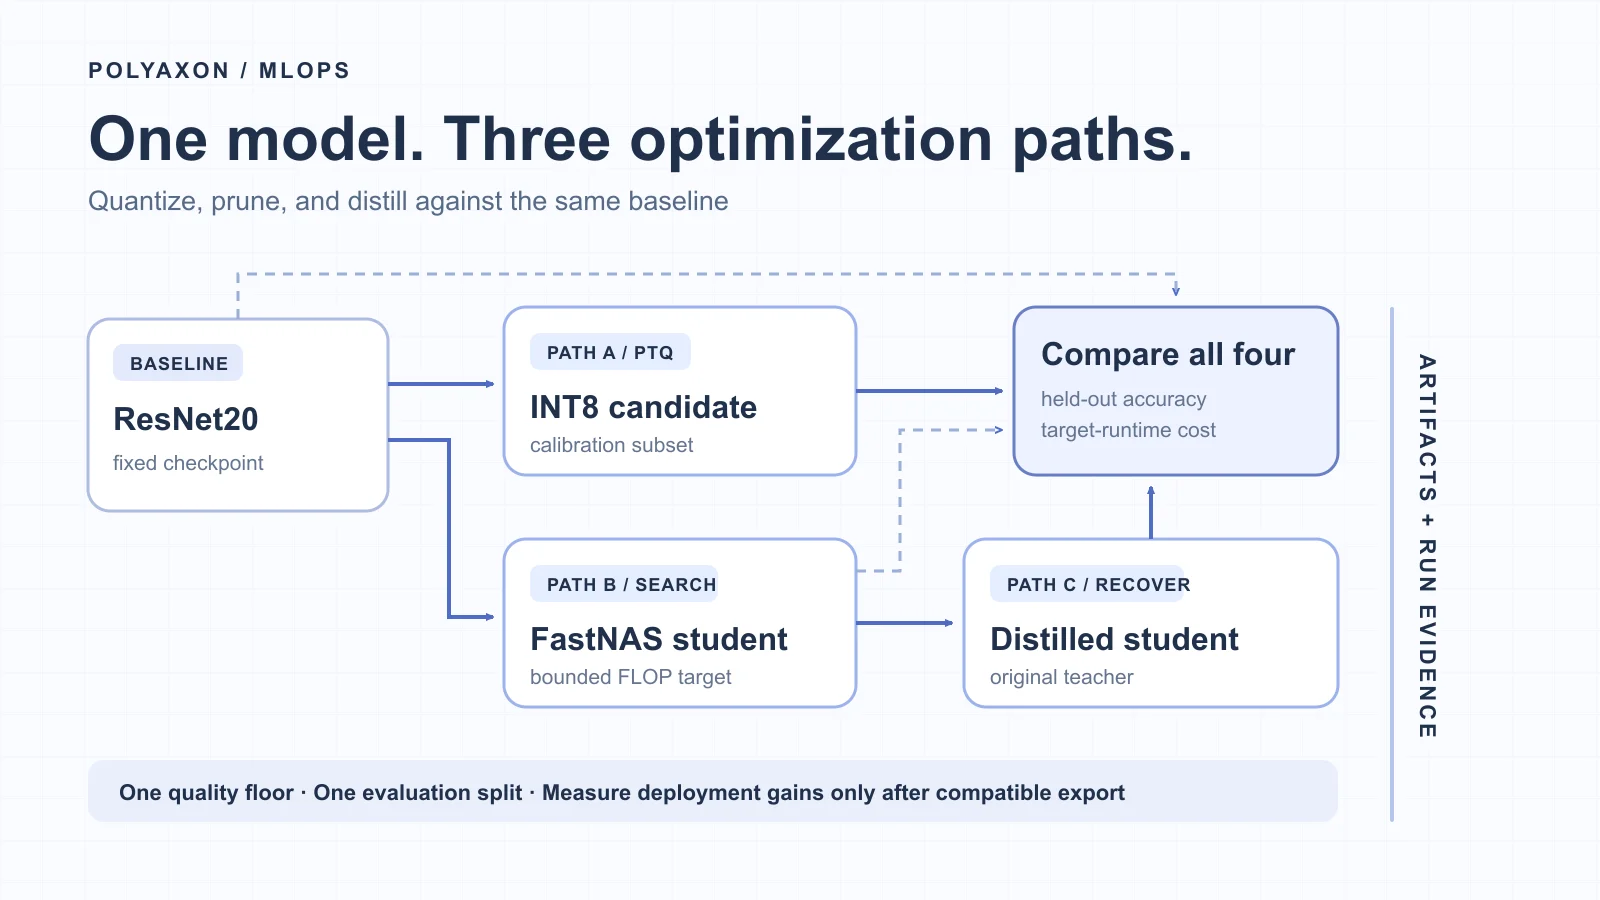
Compare INT8 quantization, FastNAS pruning, and distillation against one tracked baseline, then measure the candidate that meets your accuracy floor.
Deploy two task-specific LoRA adapters over one Qwen base model, select them by name, and measure quality and shared GPU capacity with Polyaxon.
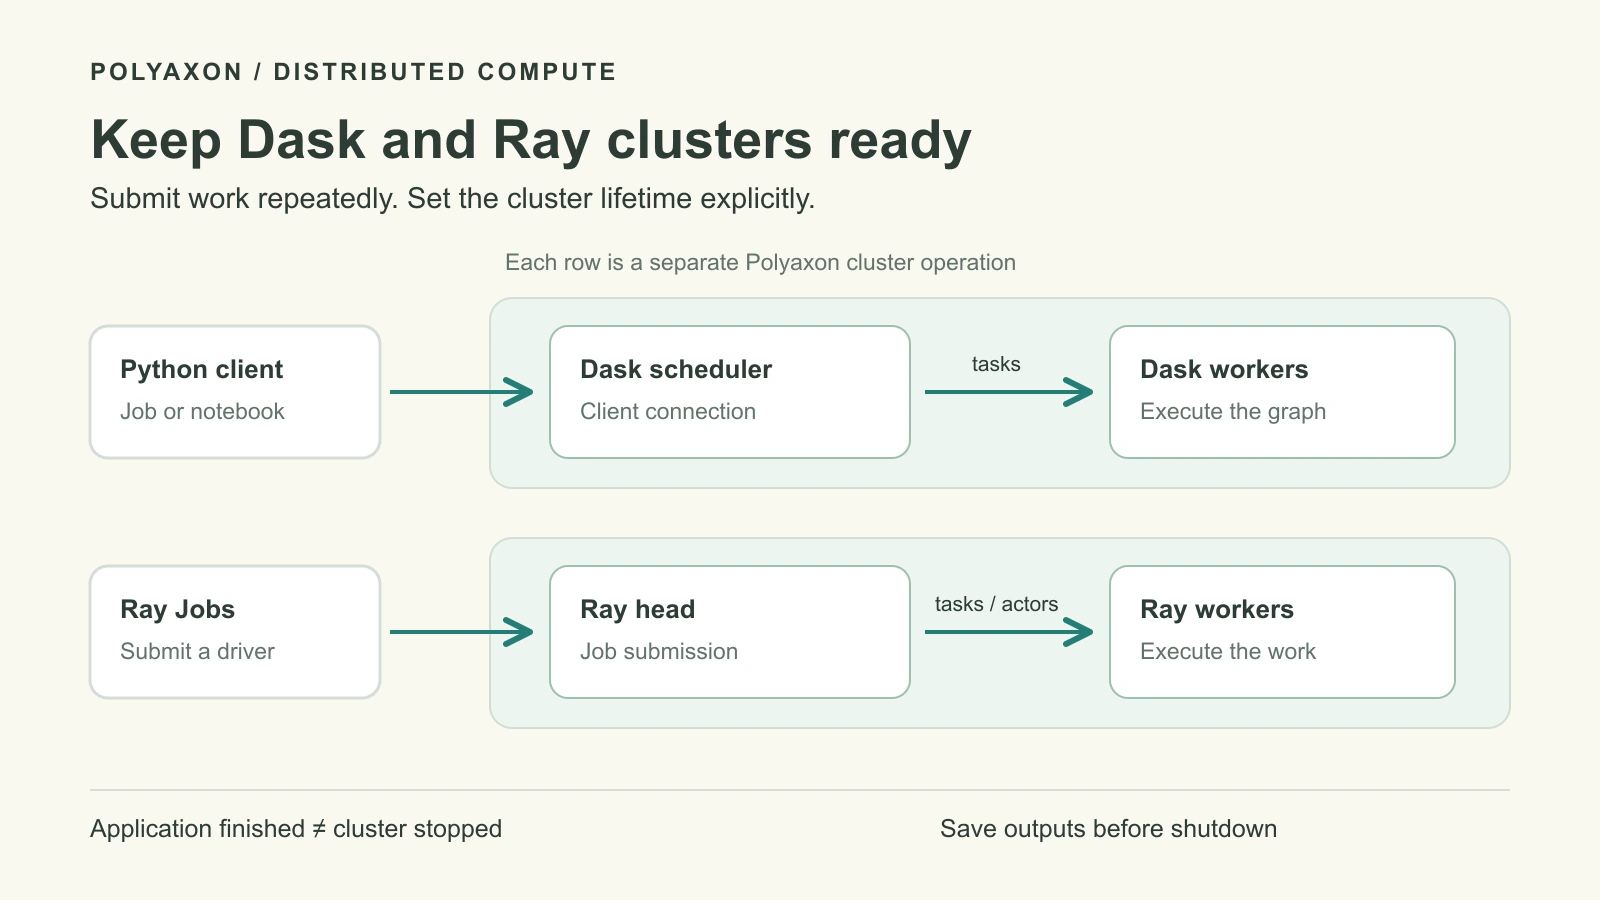
Launch Dask or Ray clusters with Polyaxonfiles, submit repeated work, and control worker capacity, durable outputs, and cluster lifetimes.
Use Kubernetes Job success policies for chosen indexes or success counts, preserve durable results, and distinguish them from Polyaxon metric early stopping.
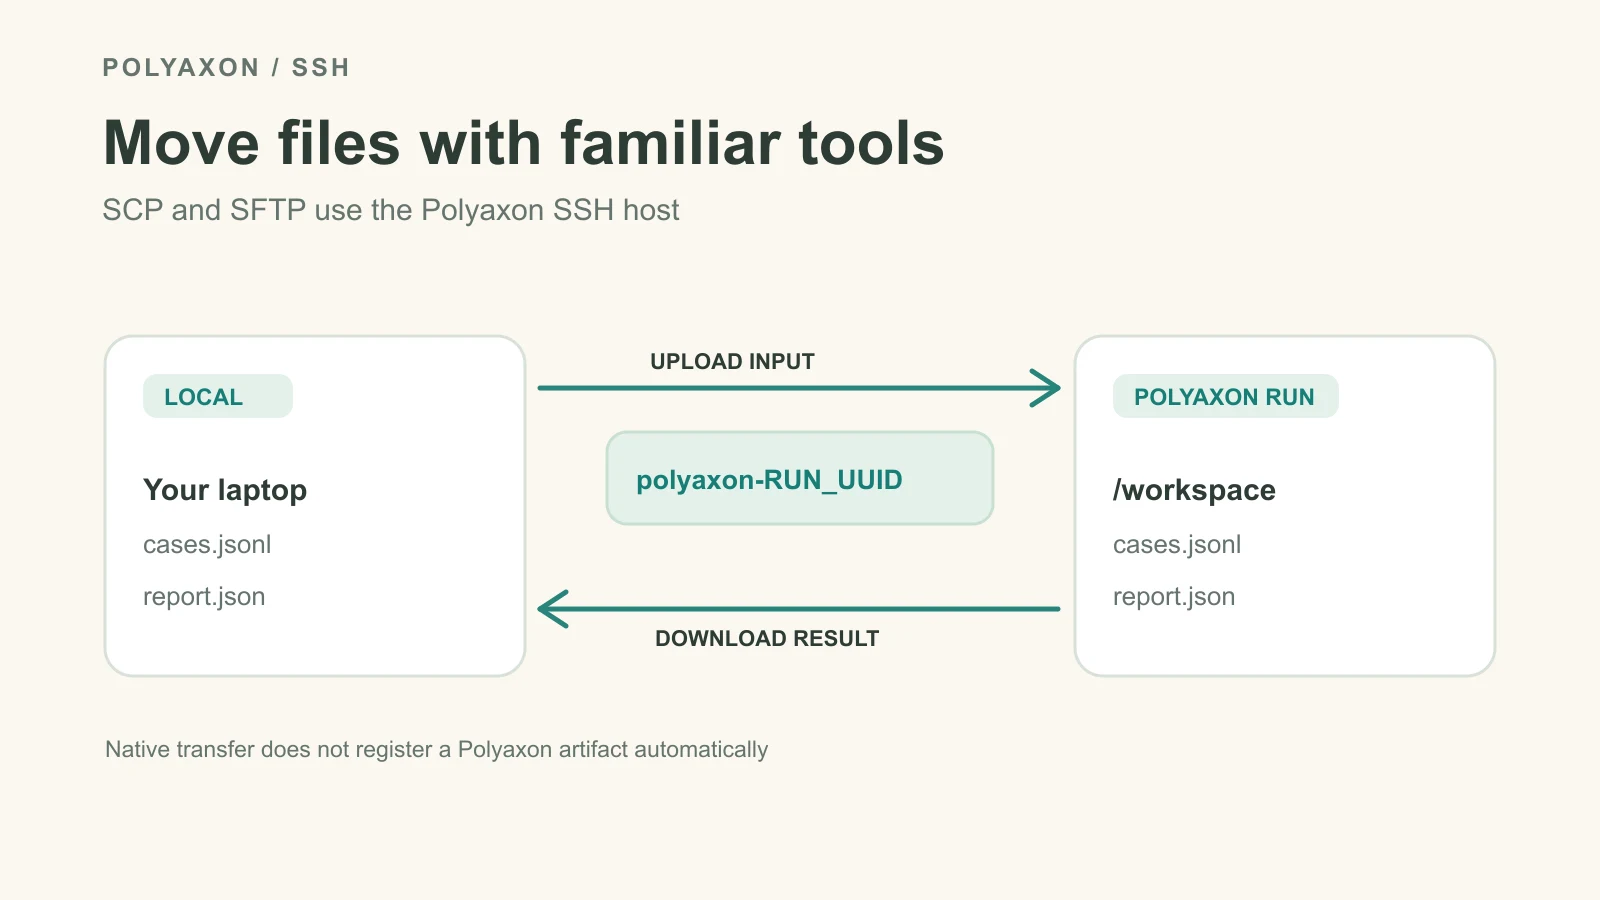
Use Polyaxon's generated SSH host with native SCP and SFTP to move files into and out of a running service workspace.
Use topology spread constraints for inference availability, understand minDomains and GPU capacity, and preserve placement intent in Polyaxon.
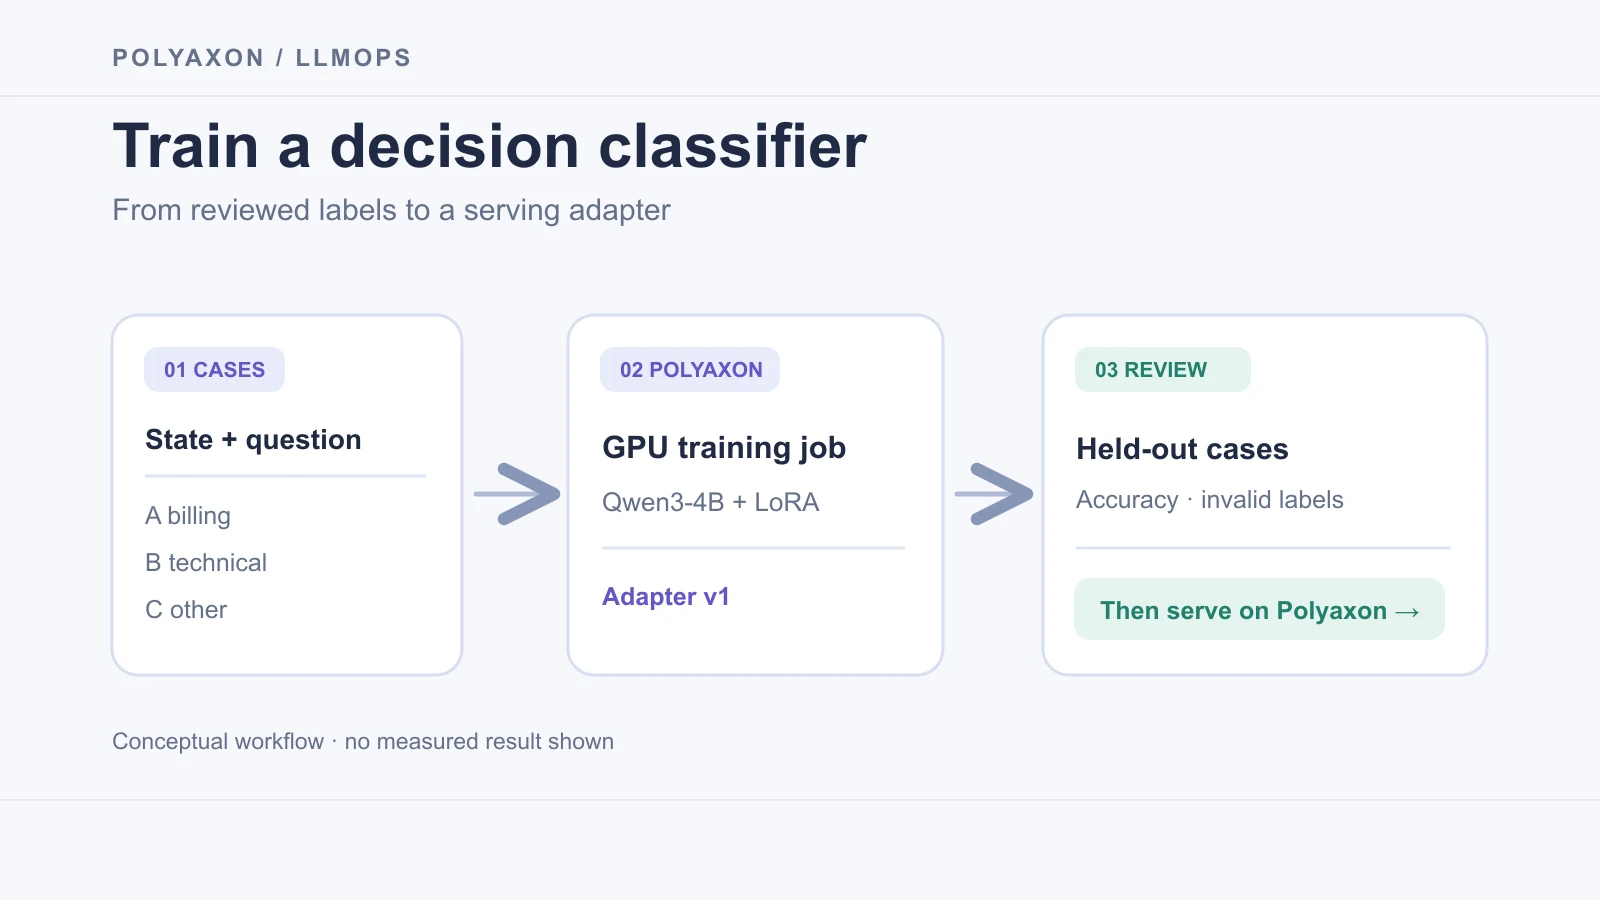
Fine-tune an open Qwen model for bounded support-routing decisions with Polyaxon jobs, track the adapter, and serve the reviewed version through vLLM.
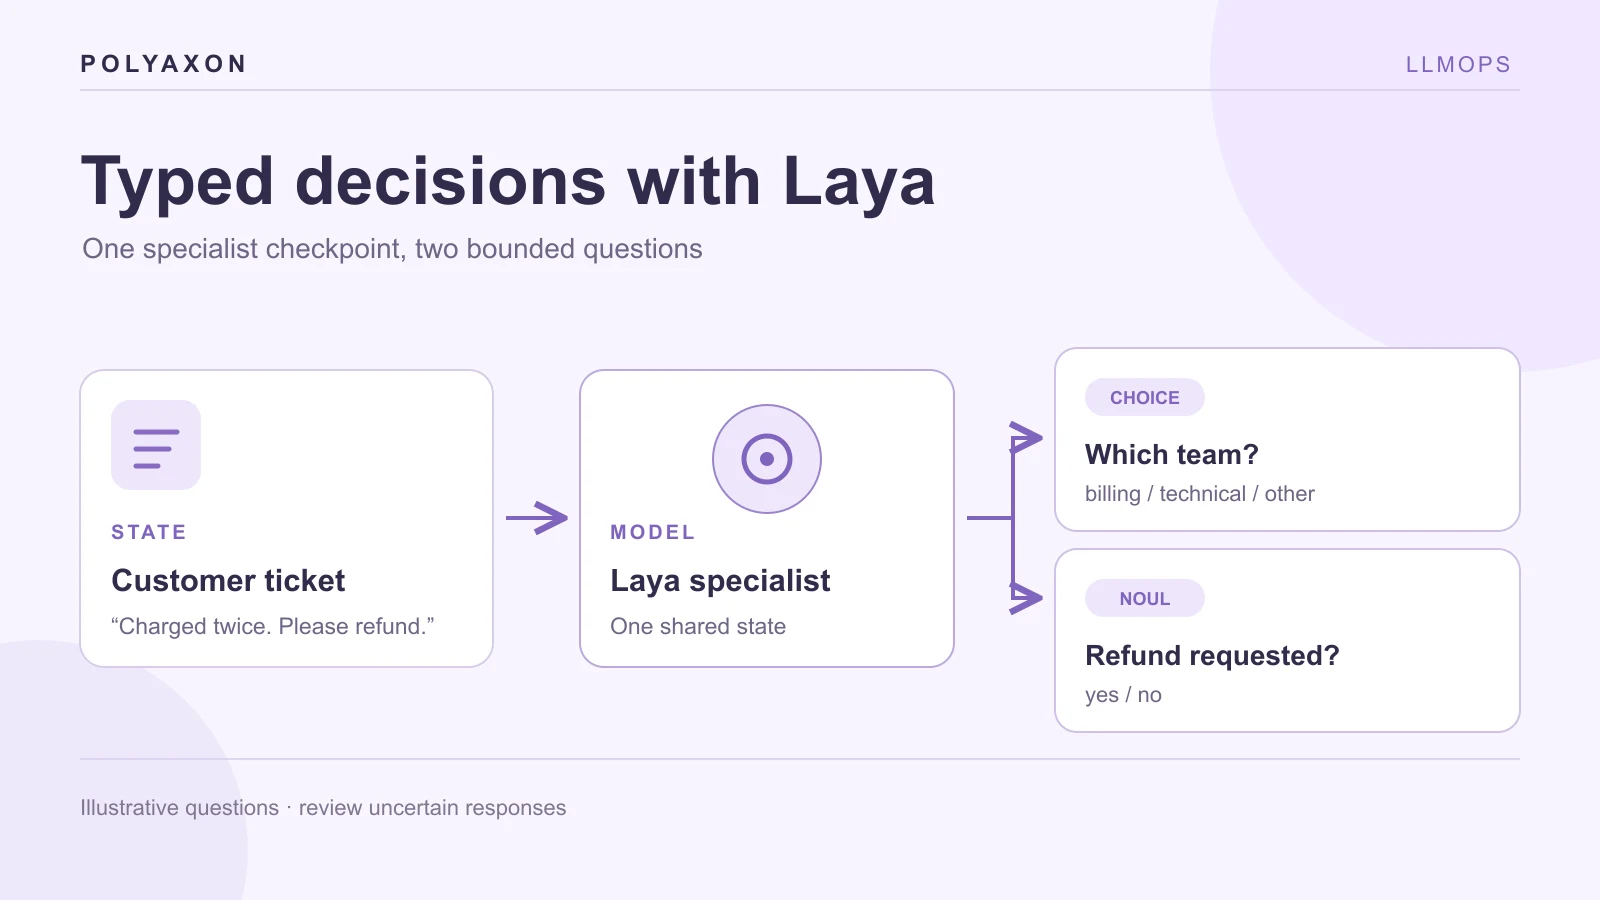
Serve the open Laya typed-decisions checkpoint through Polyaxon, with a CPU classifier endpoint, explicit model scope, and a review path for uncertain classifications.
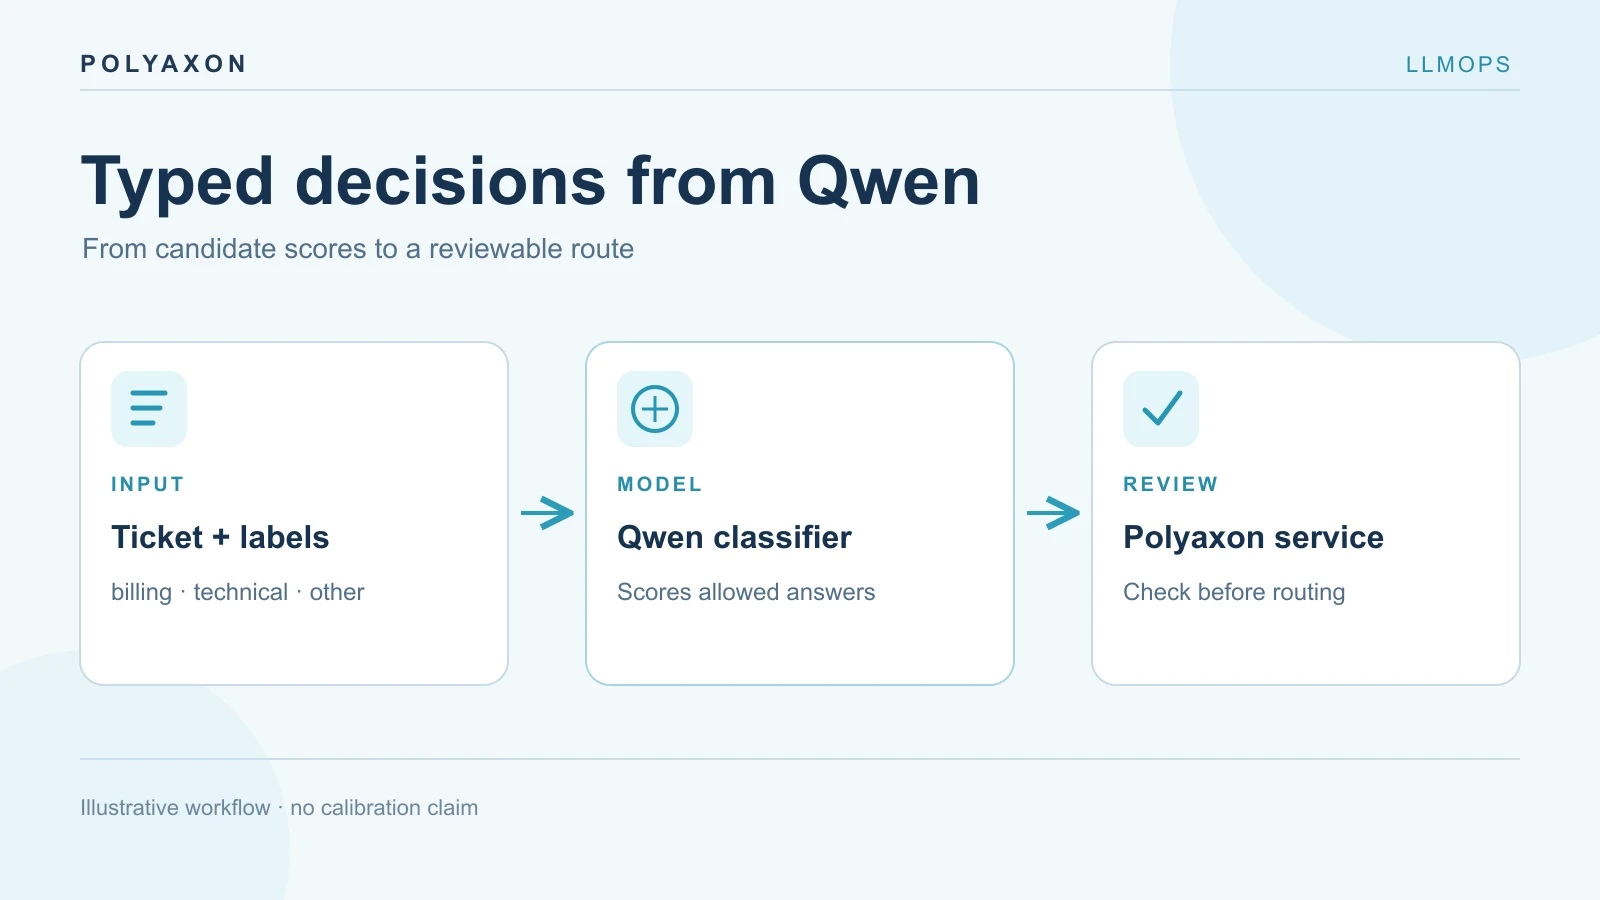
Deploy an open Qwen model behind a typed classification API on Polyaxon, then check the decision schema and calibration before routing real work.
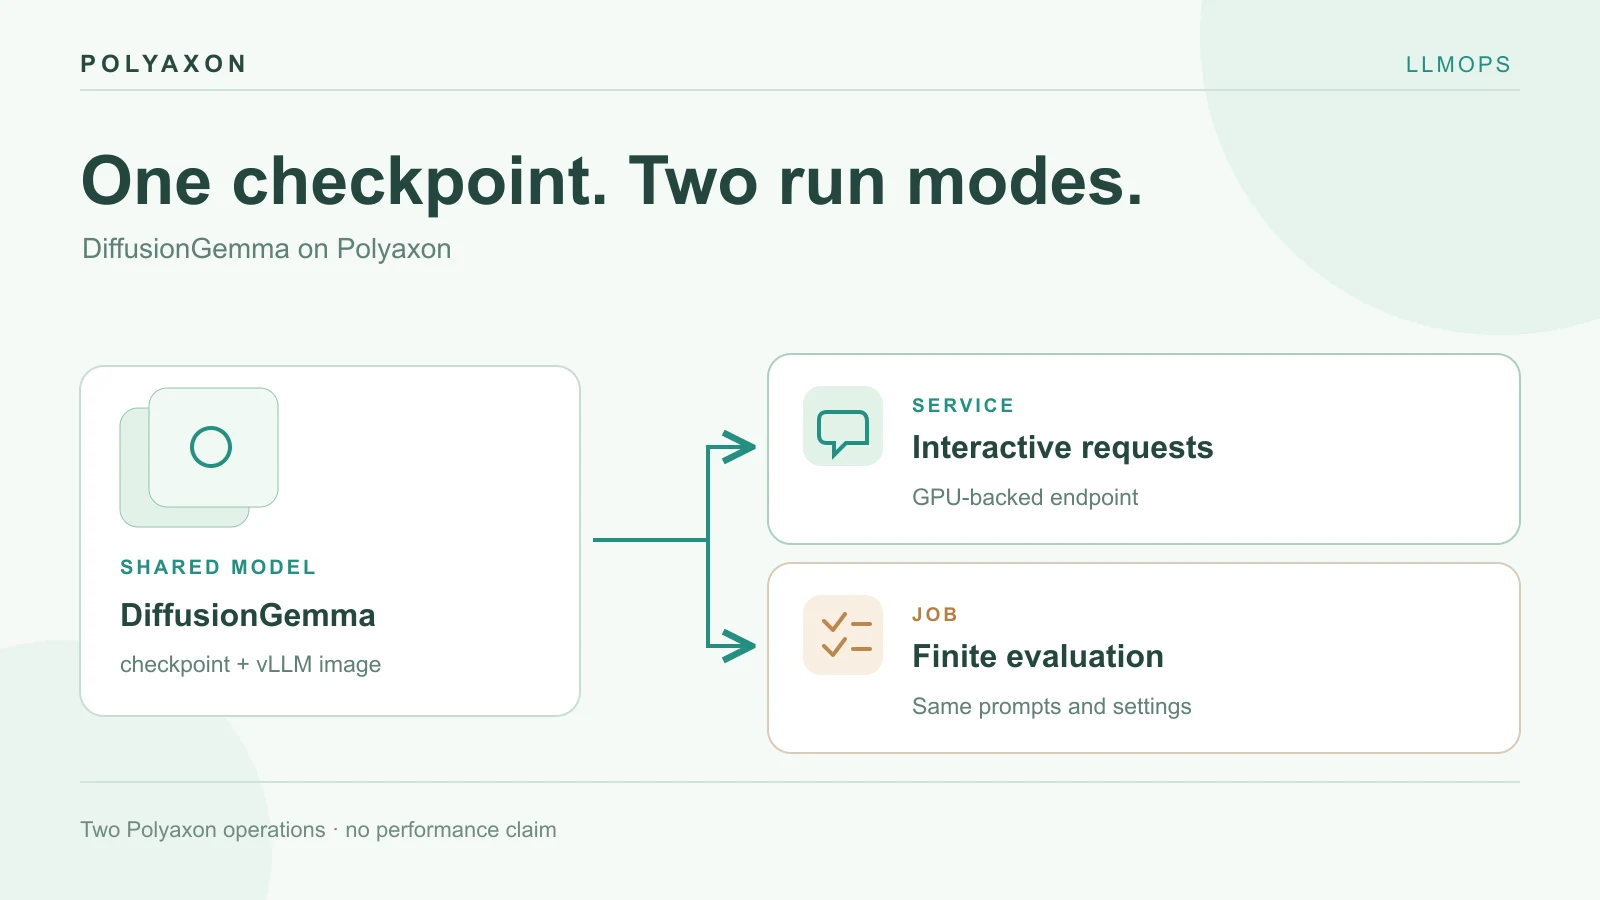
Adapt Google's Gemma-on-Kubernetes deployment choices to Polyaxon with a DiffusionGemma vLLM service, a batch evaluation job, and an explicit compatibility checklist.
Combine CPU Manager eligibility, full-core allocation, and Topology Manager policy, then compare CPU/GPU workloads with Polyaxon.
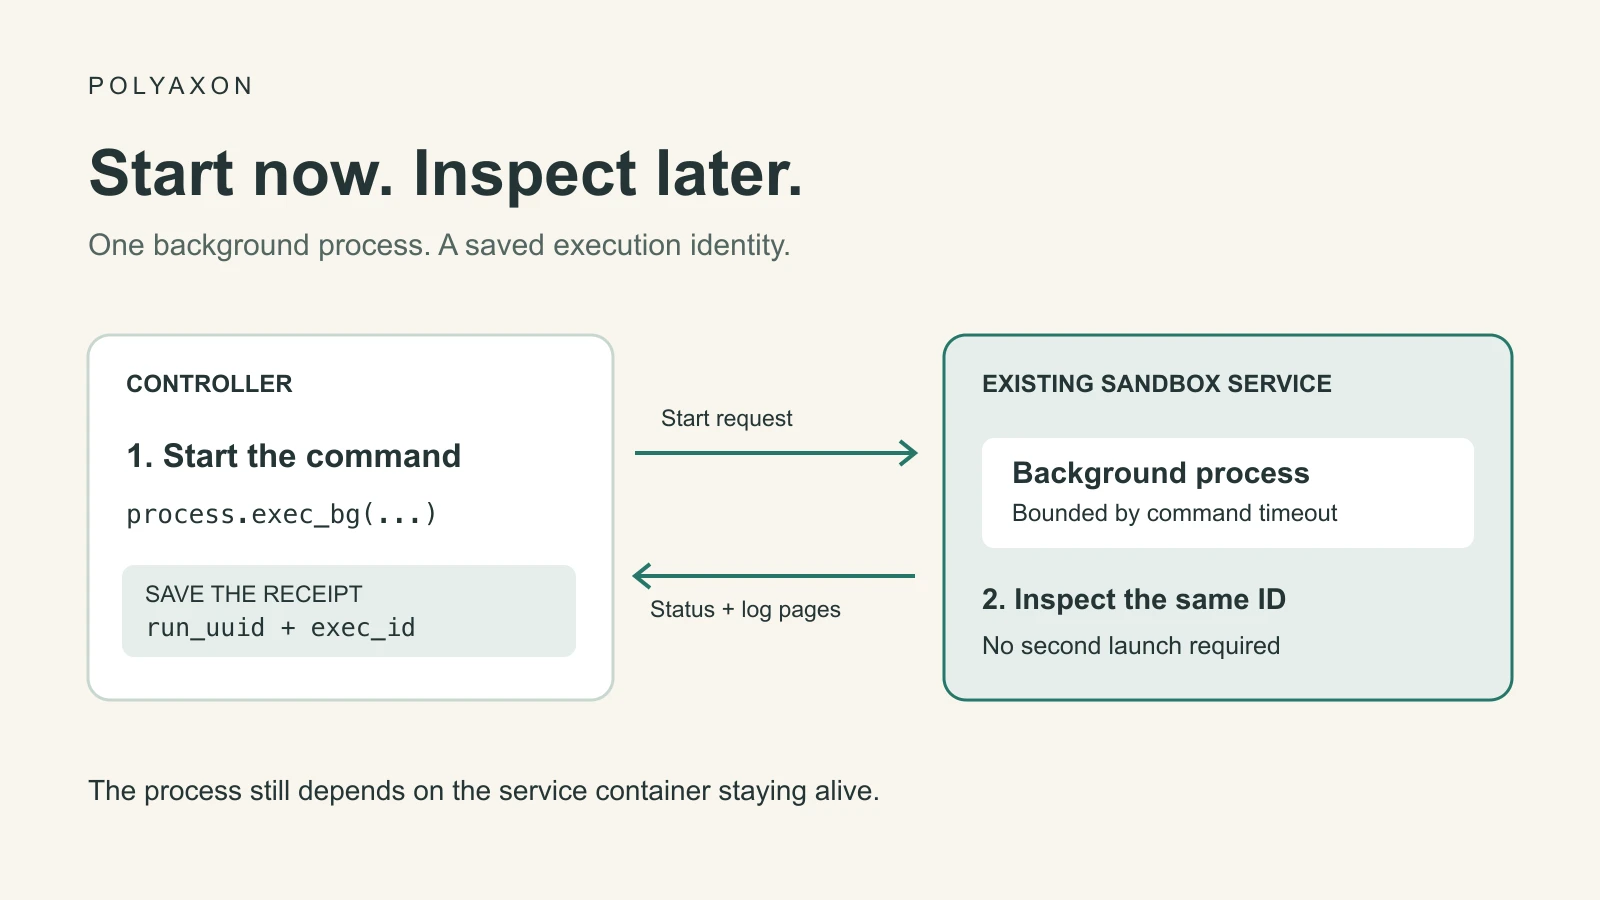
Start a background process, save its execution ID, reconnect to status and logs, and distinguish command limits from the lifetime of a Polyaxon sandbox.
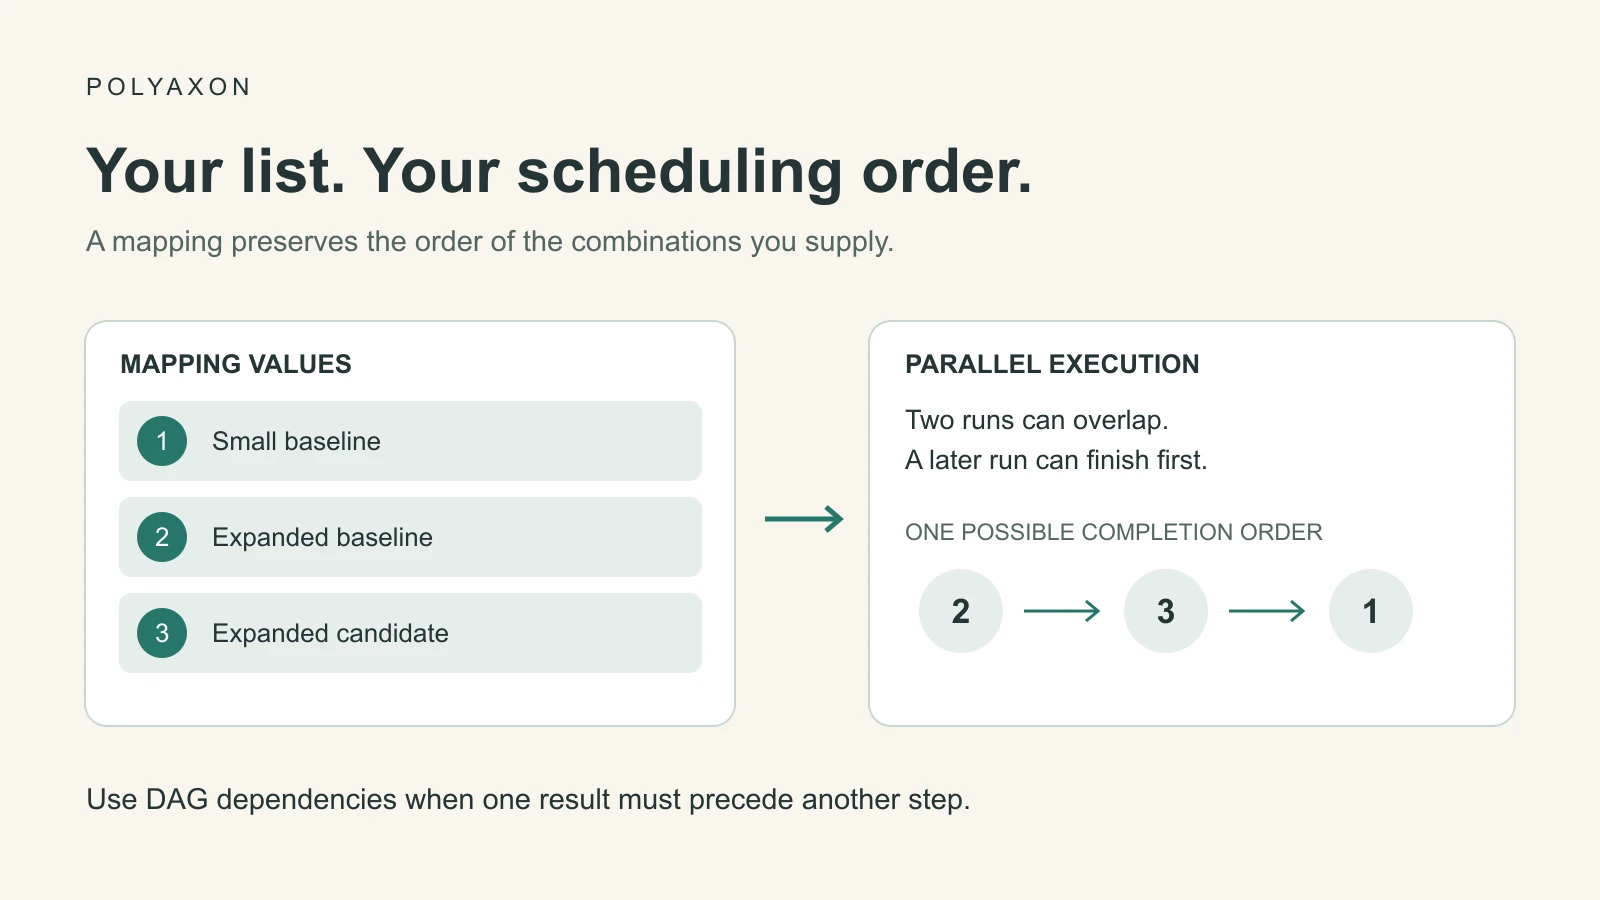
Use an ordered Polyaxon mapping for a curated list of experiments, control concurrency, and distinguish scheduling order from dependencies and completion order.
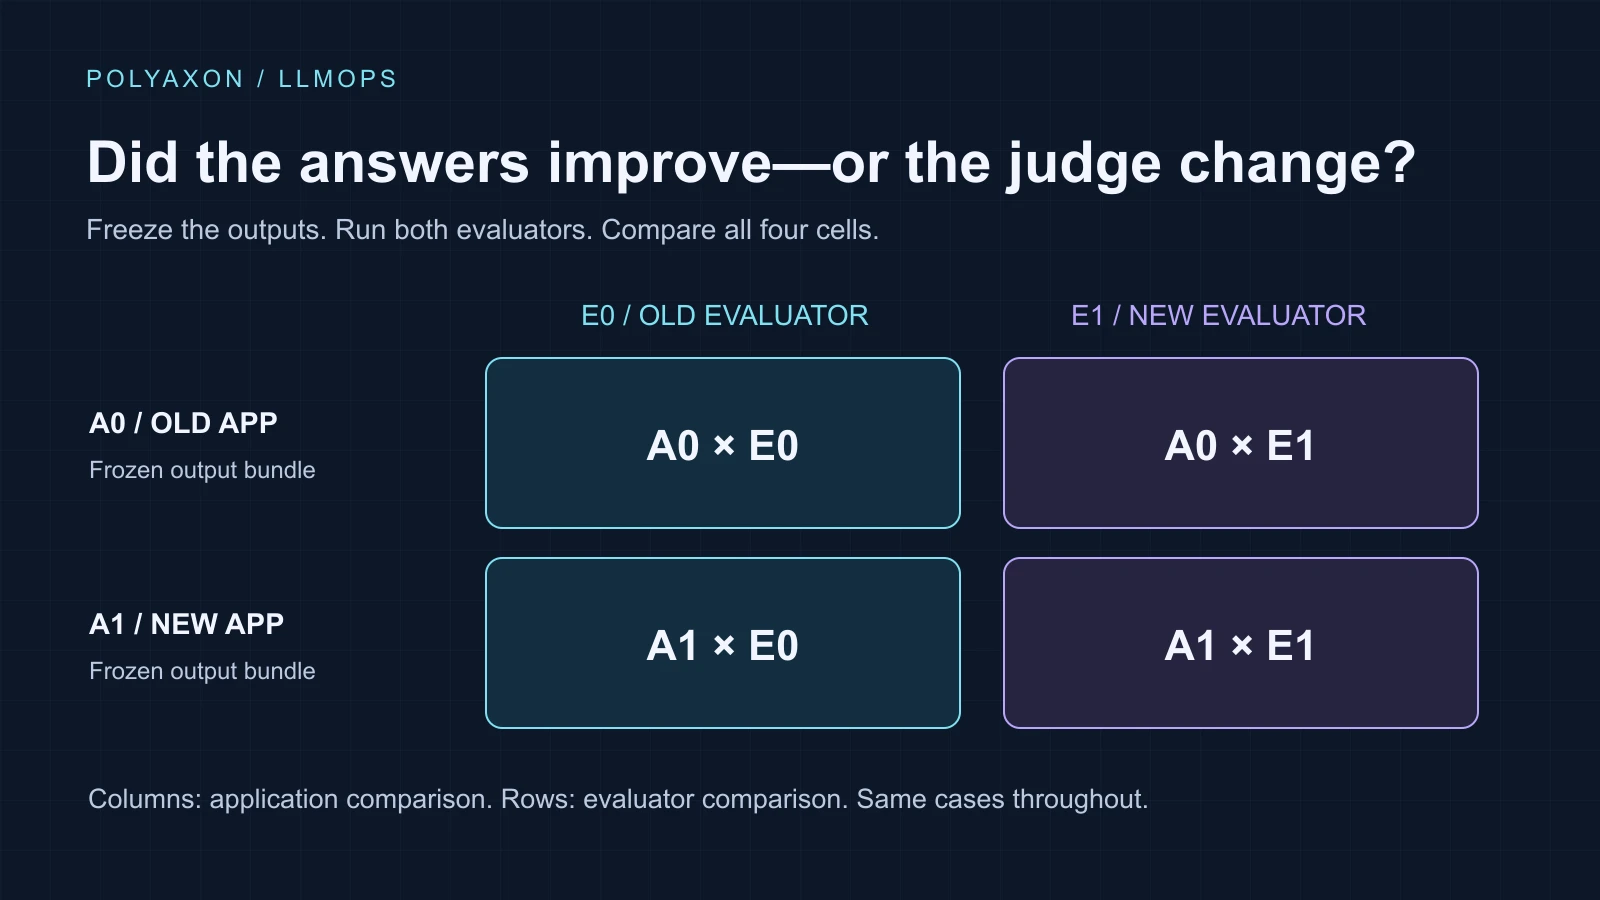
Compare old and new application outputs under both evaluator versions, inspect changed decisions, and retain the four comparisons in Polyaxon.
Understand exact prefix reuse in vLLM, structure repeated context, account for replica routing, and compare cold and warm workloads with Polyaxon.
Use Kubernetes in-place resource resizing for running workloads, inspect whether changes took effect, and understand the limits for Polyaxon services.
Explore native gang scheduling in Kubernetes 1.37, its potential for Polyaxon training and sandboxes, and how it compares with KAI, Kueue, and Volcano.
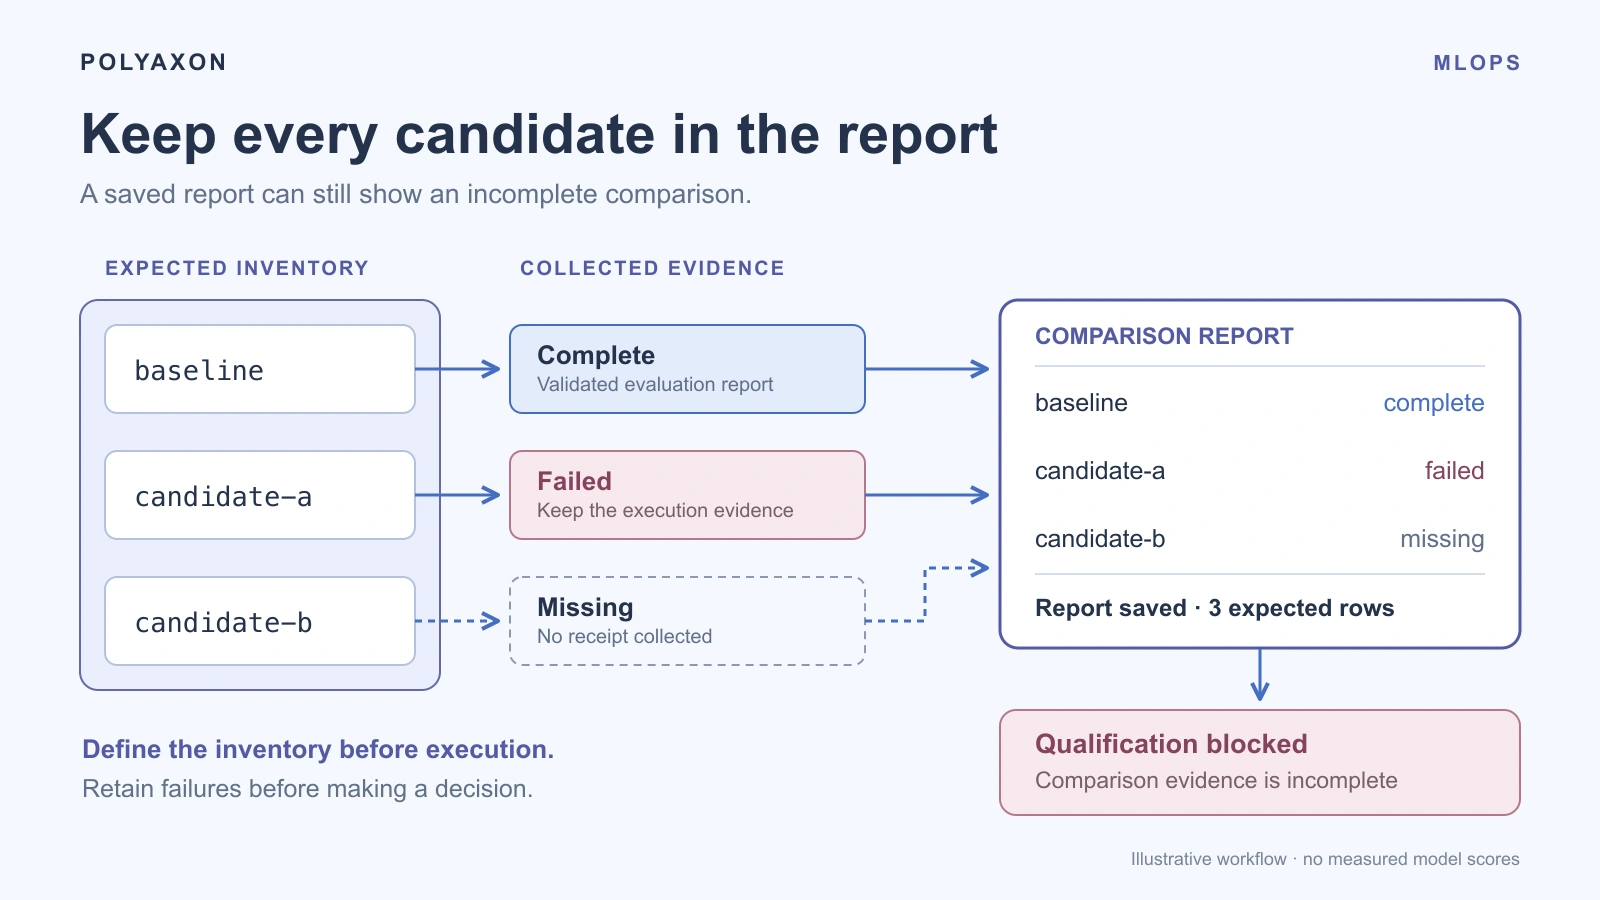
Reconcile evaluation results against an expected candidate manifest, preserve failed and missing outcomes, and separate pipeline reporting from release approval.
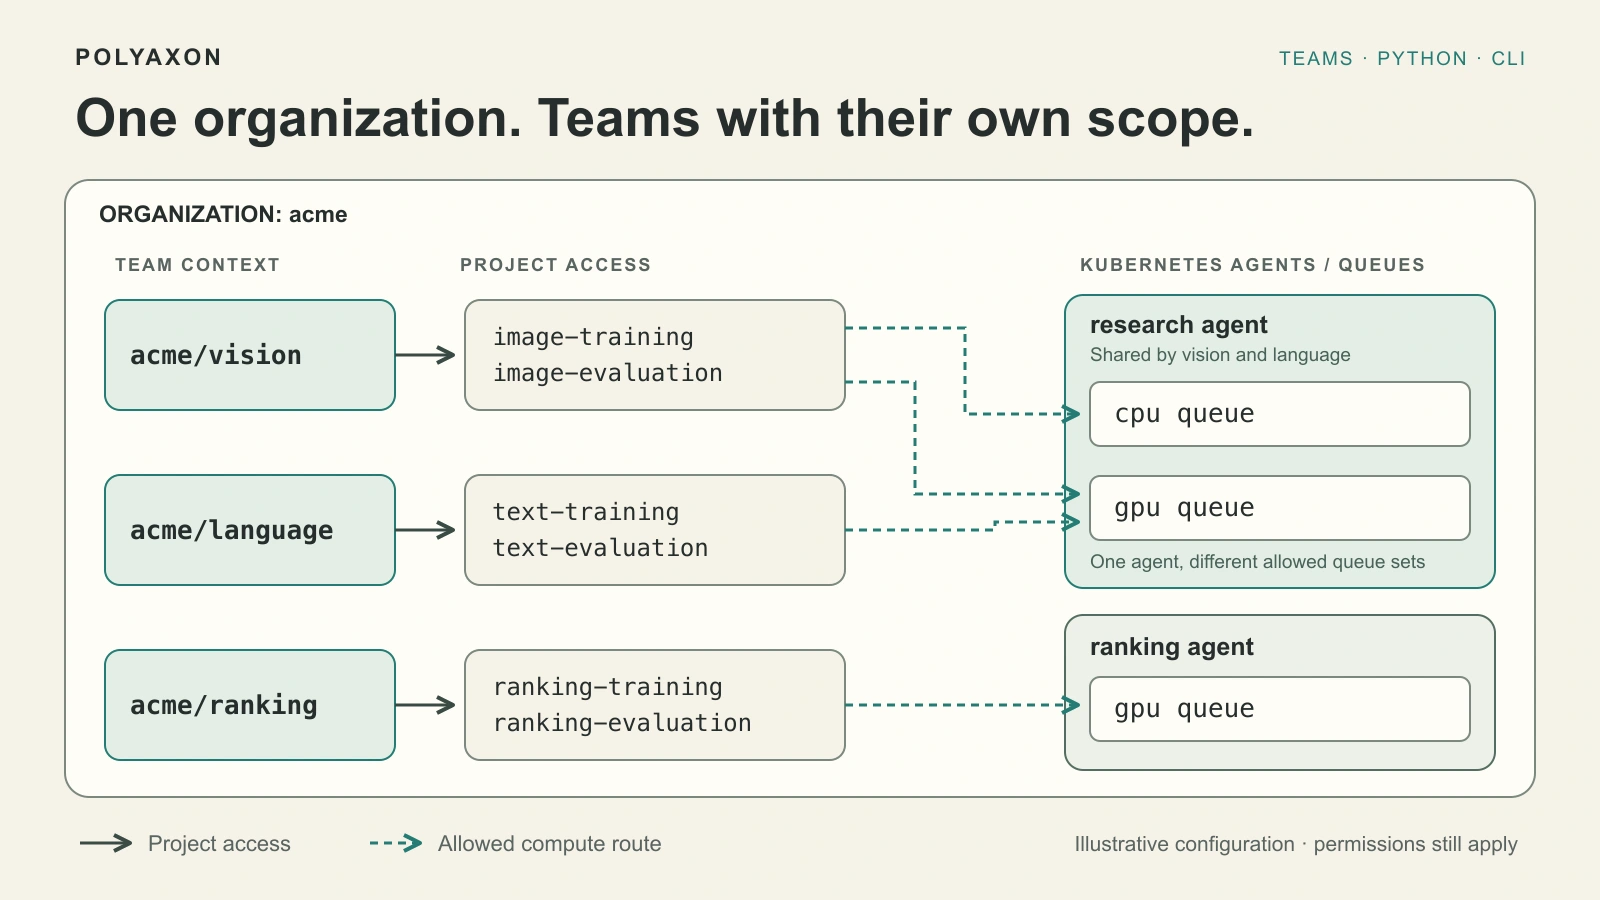
Scope Polyaxon Python clients and CLI commands to a team, review runs across its projects, and keep explicit project targets and saved defaults clear.
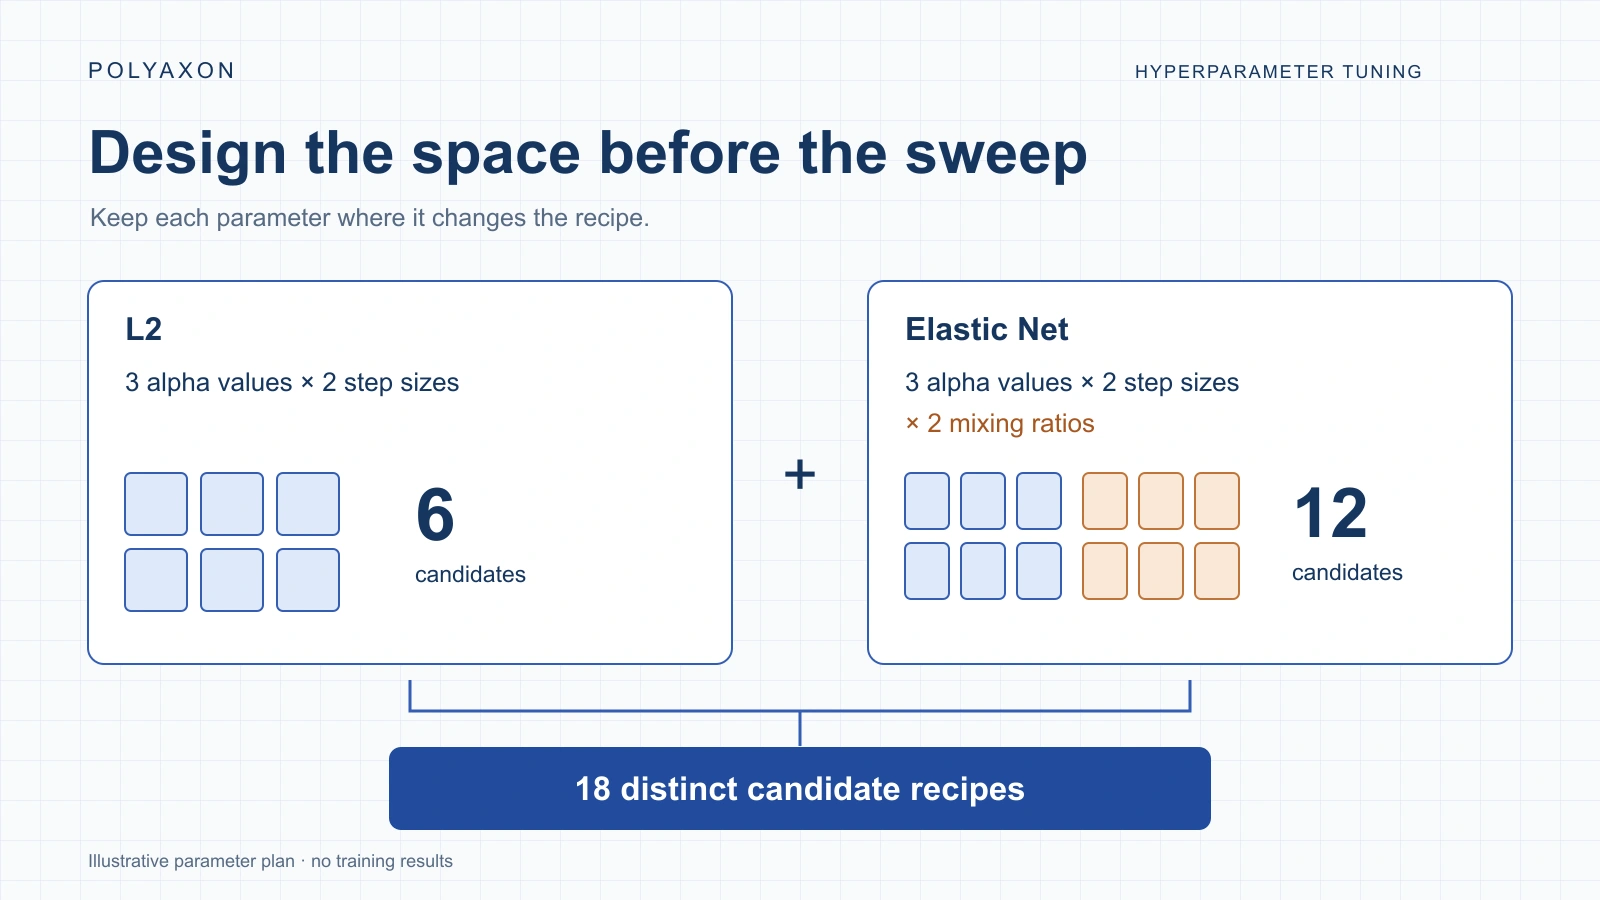
Use Polyaxon matrices to choose parameter scales, separate meaningful combinations, and control the size of a hyperparameter sweep.