Multi-cluster GPU orchestration
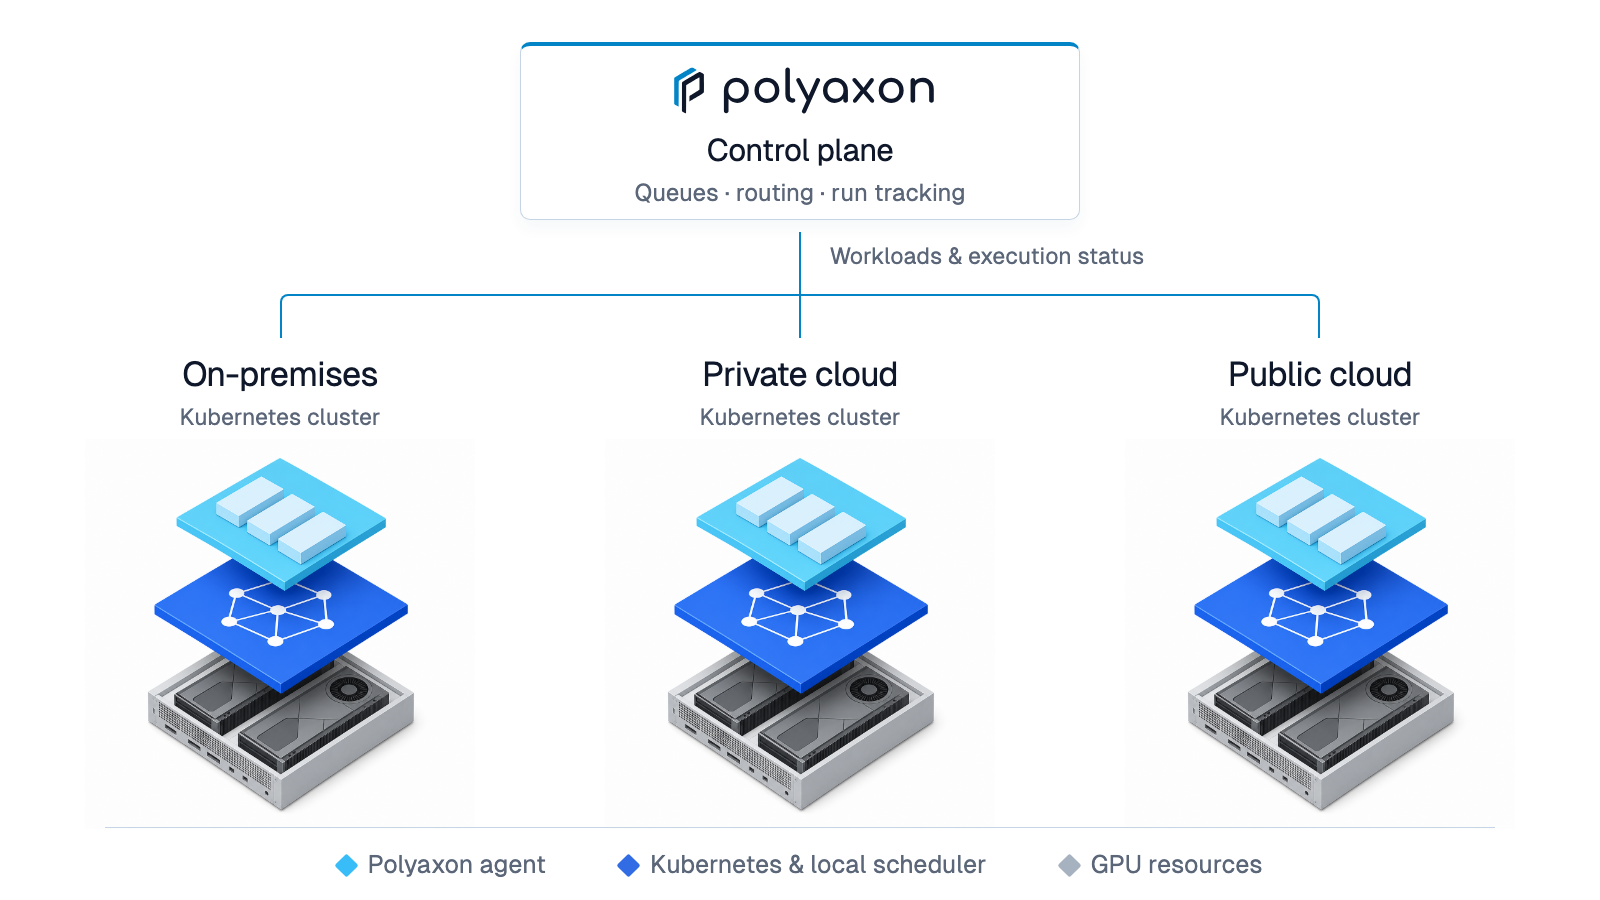
Design multi-cluster GPU orchestration around workload eligibility, data locality, queue routing, recovery, and clear dispatch ownership.
OrchestrationKubernetes
The Polyaxon blog
Practical guides to building, running, and improving ML and AI in production.
GPU orchestration, distributed training, and multi-tenant AI workloads.
Design multi-cluster GPU orchestration around workload eligibility, data locality, queue routing, recovery, and clear dispatch ownership.
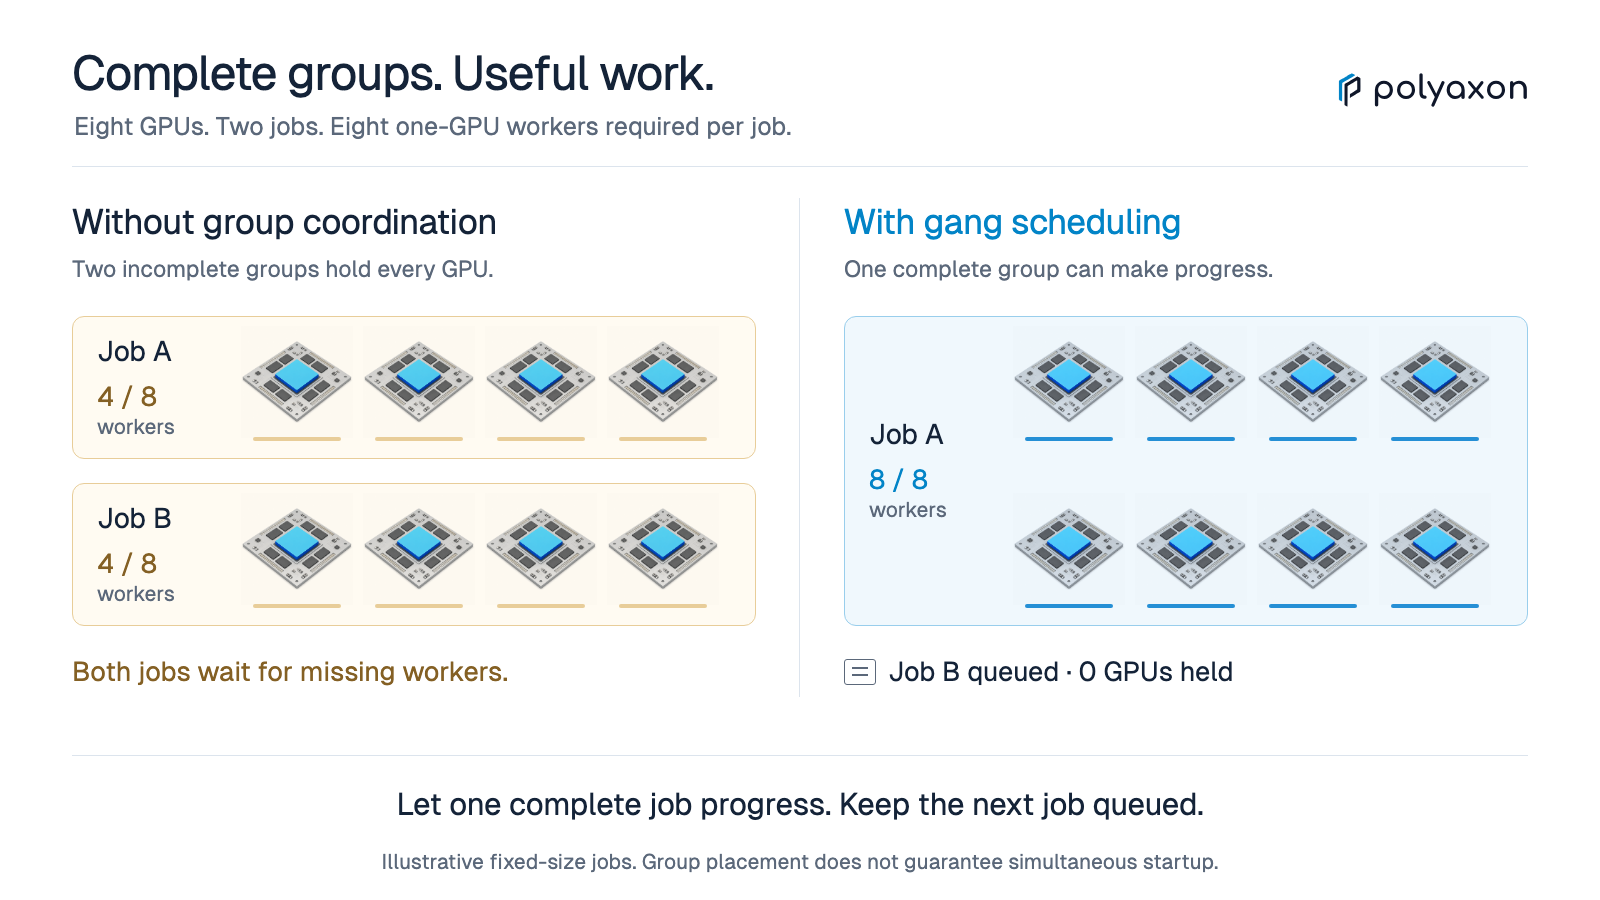
Understand how gang scheduling prevents partial distributed jobs from holding GPUs, how minimum membership works, and what Polyaxon supports.
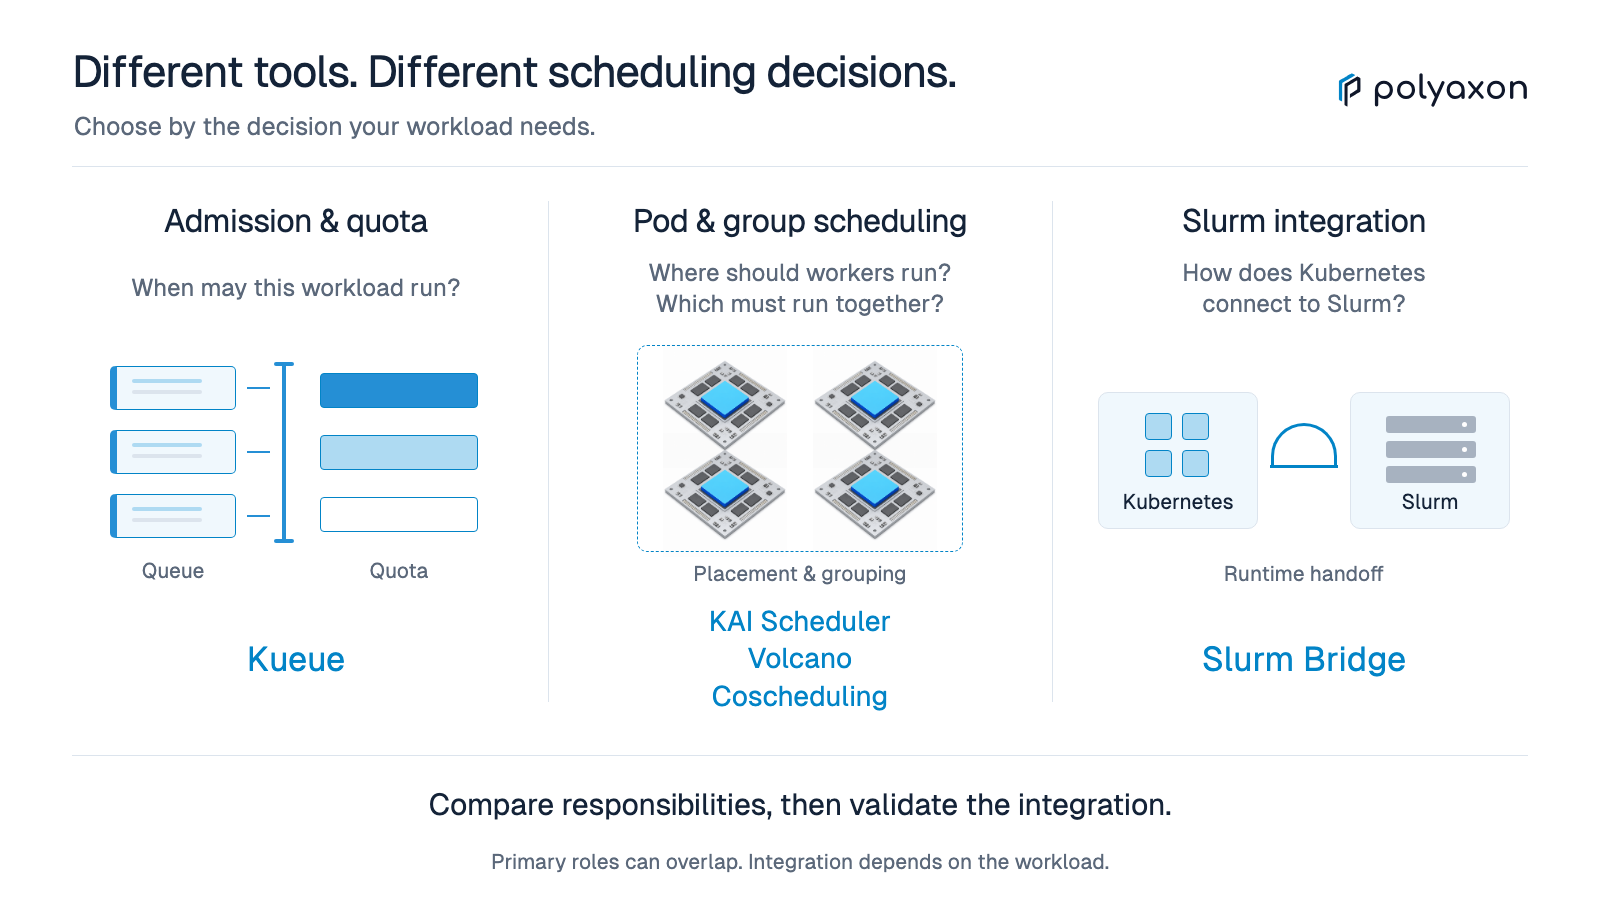
Compare Kueue, KAI Scheduler, Volcano, Coscheduling, and Slurm Bridge by responsibility, workload fit, and Polyaxon integration path.
Understand native topology-aware workload scheduling, combine rack locality with gang placement, and assess the tradeoff between waiting and communication.
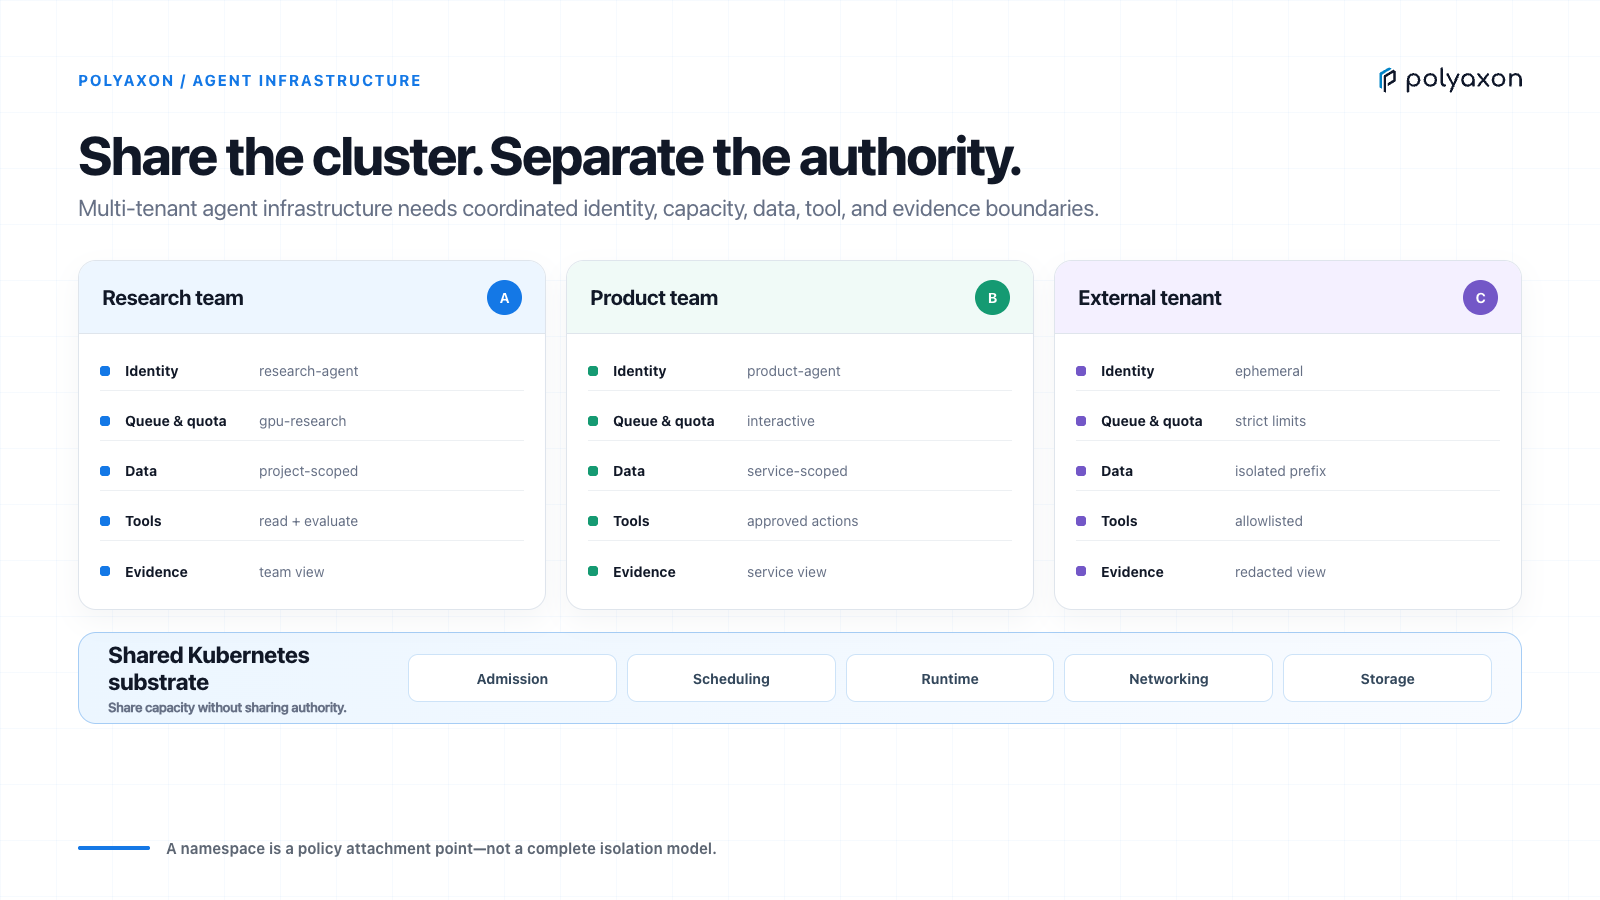
Separate identity, network access, data, queues, budgets, and evidence when multiple teams or customers run AI agents on shared Kubernetes infrastructure.
Track experiments, tune models, manage compute costs, and recover training.
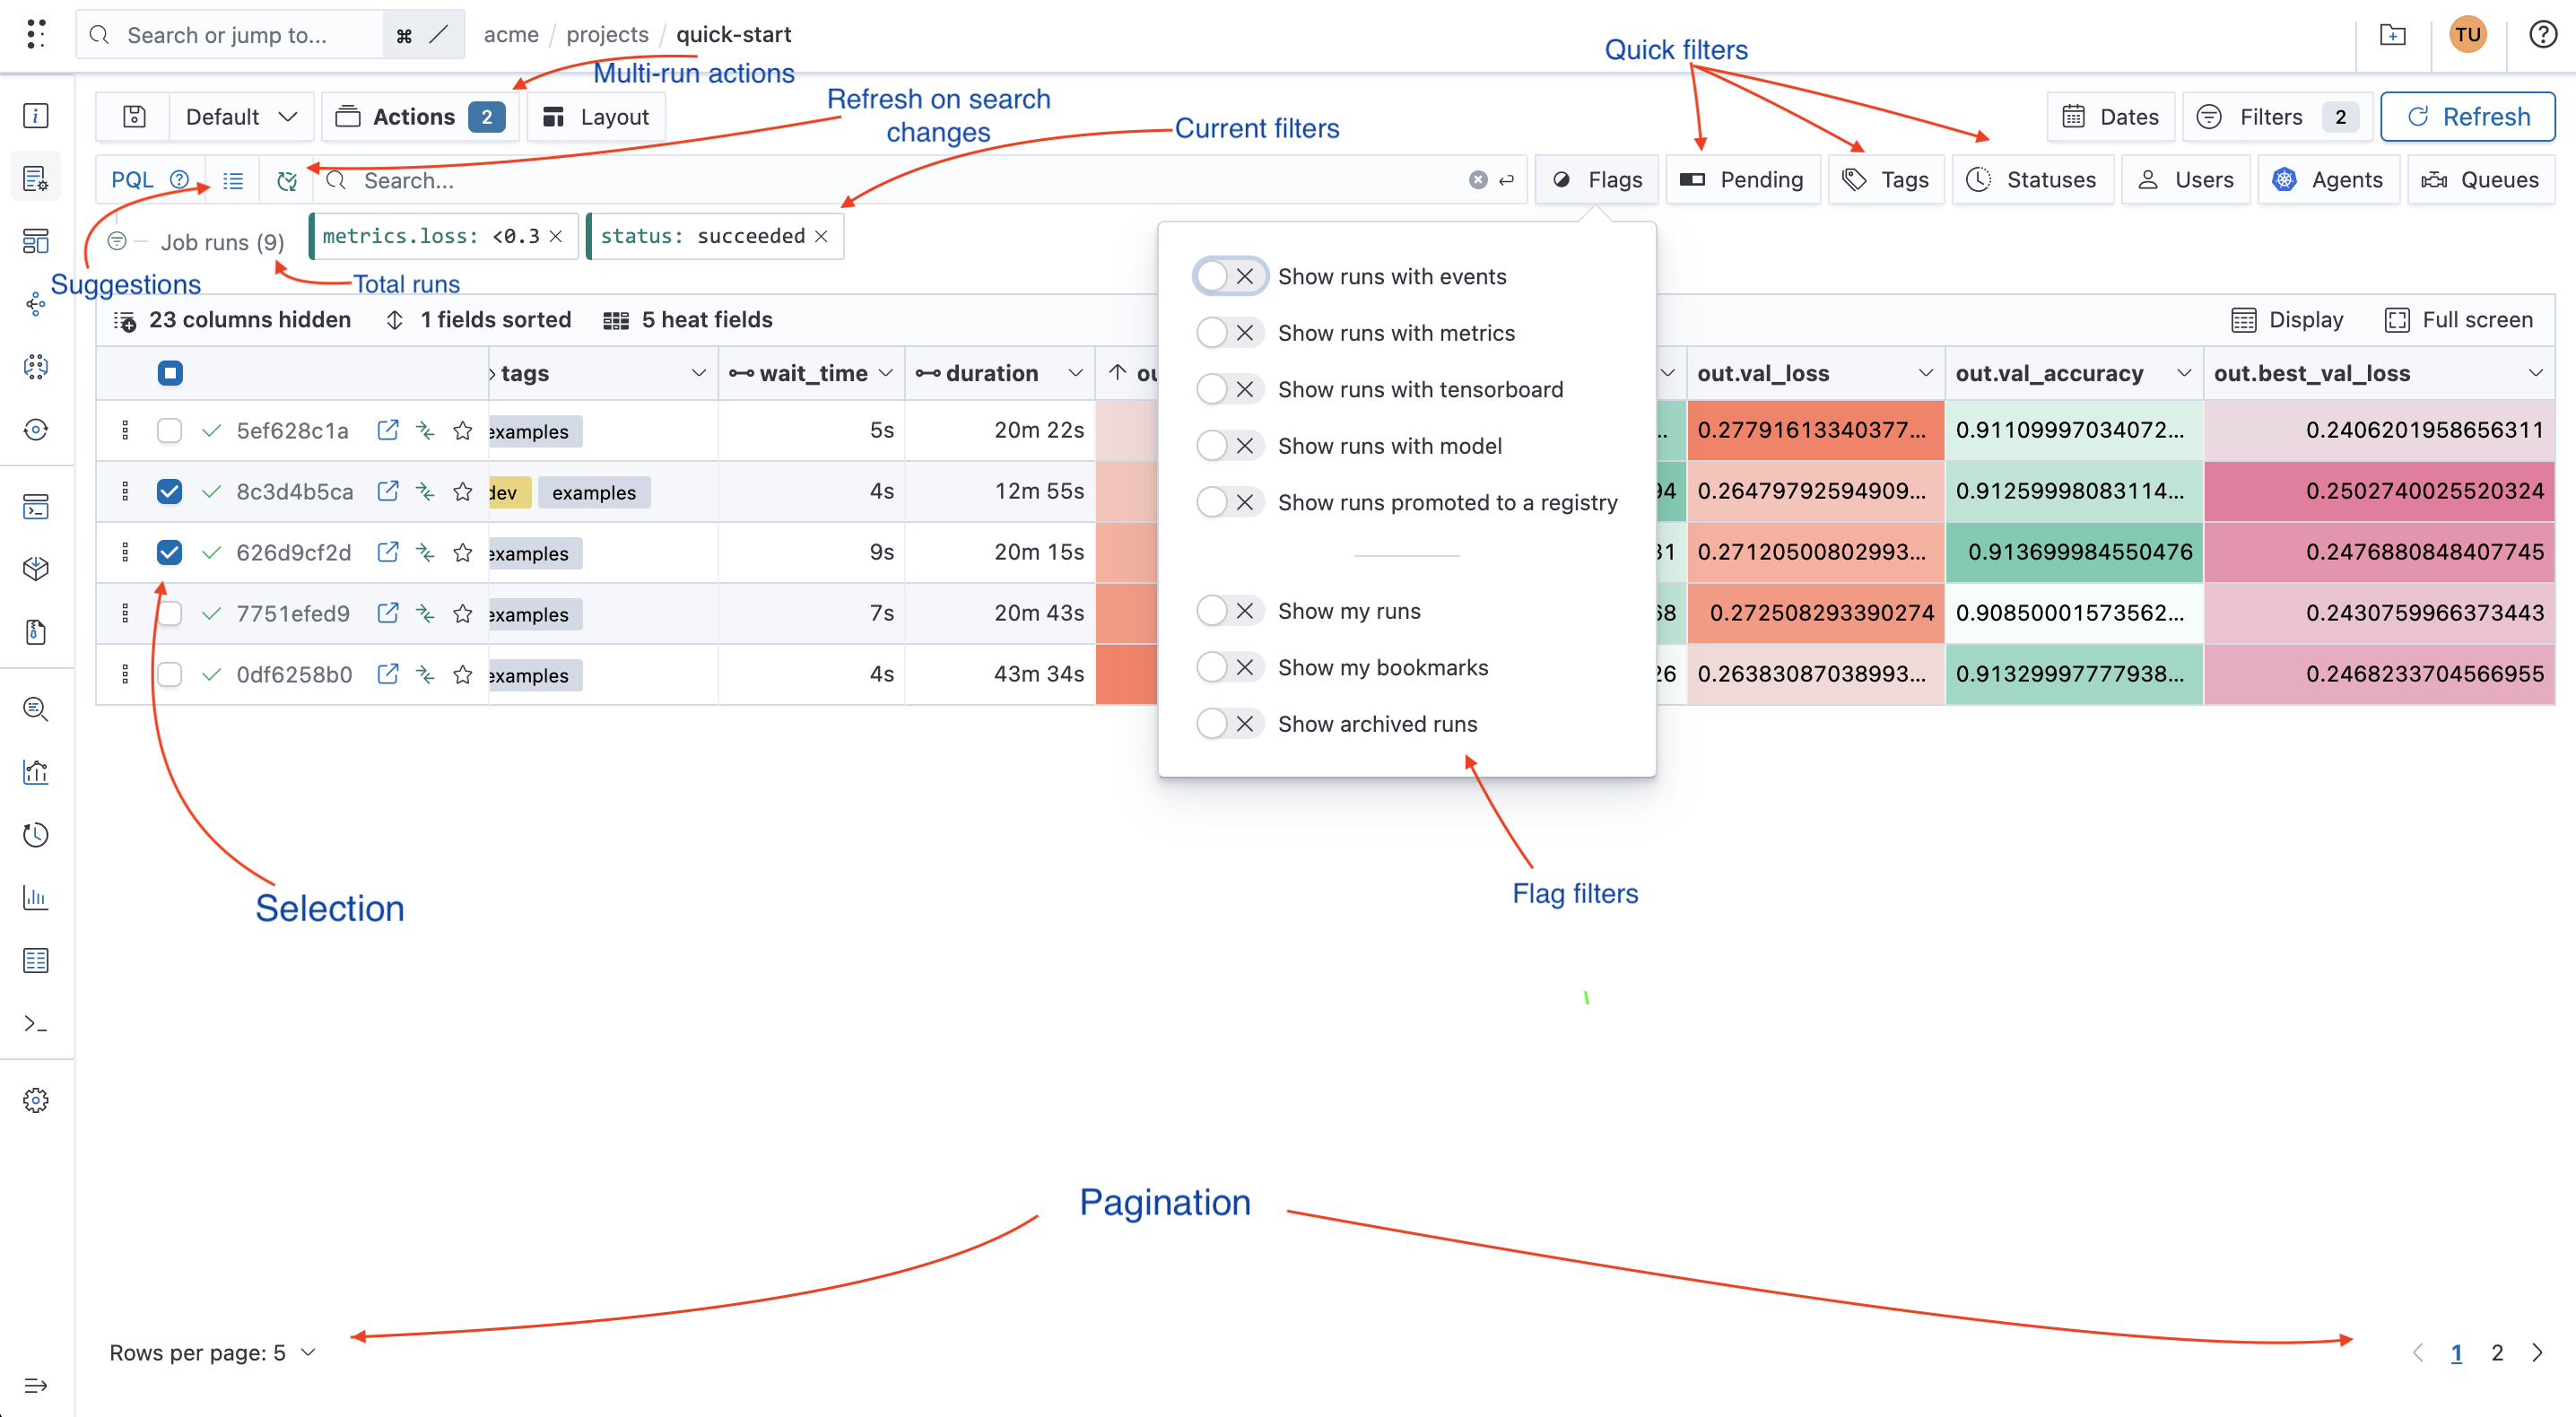
Understand ML metadata with examples of runs, datasets, and model artifacts. Learn how a metadata store connects them and how to query them in Polyaxon.
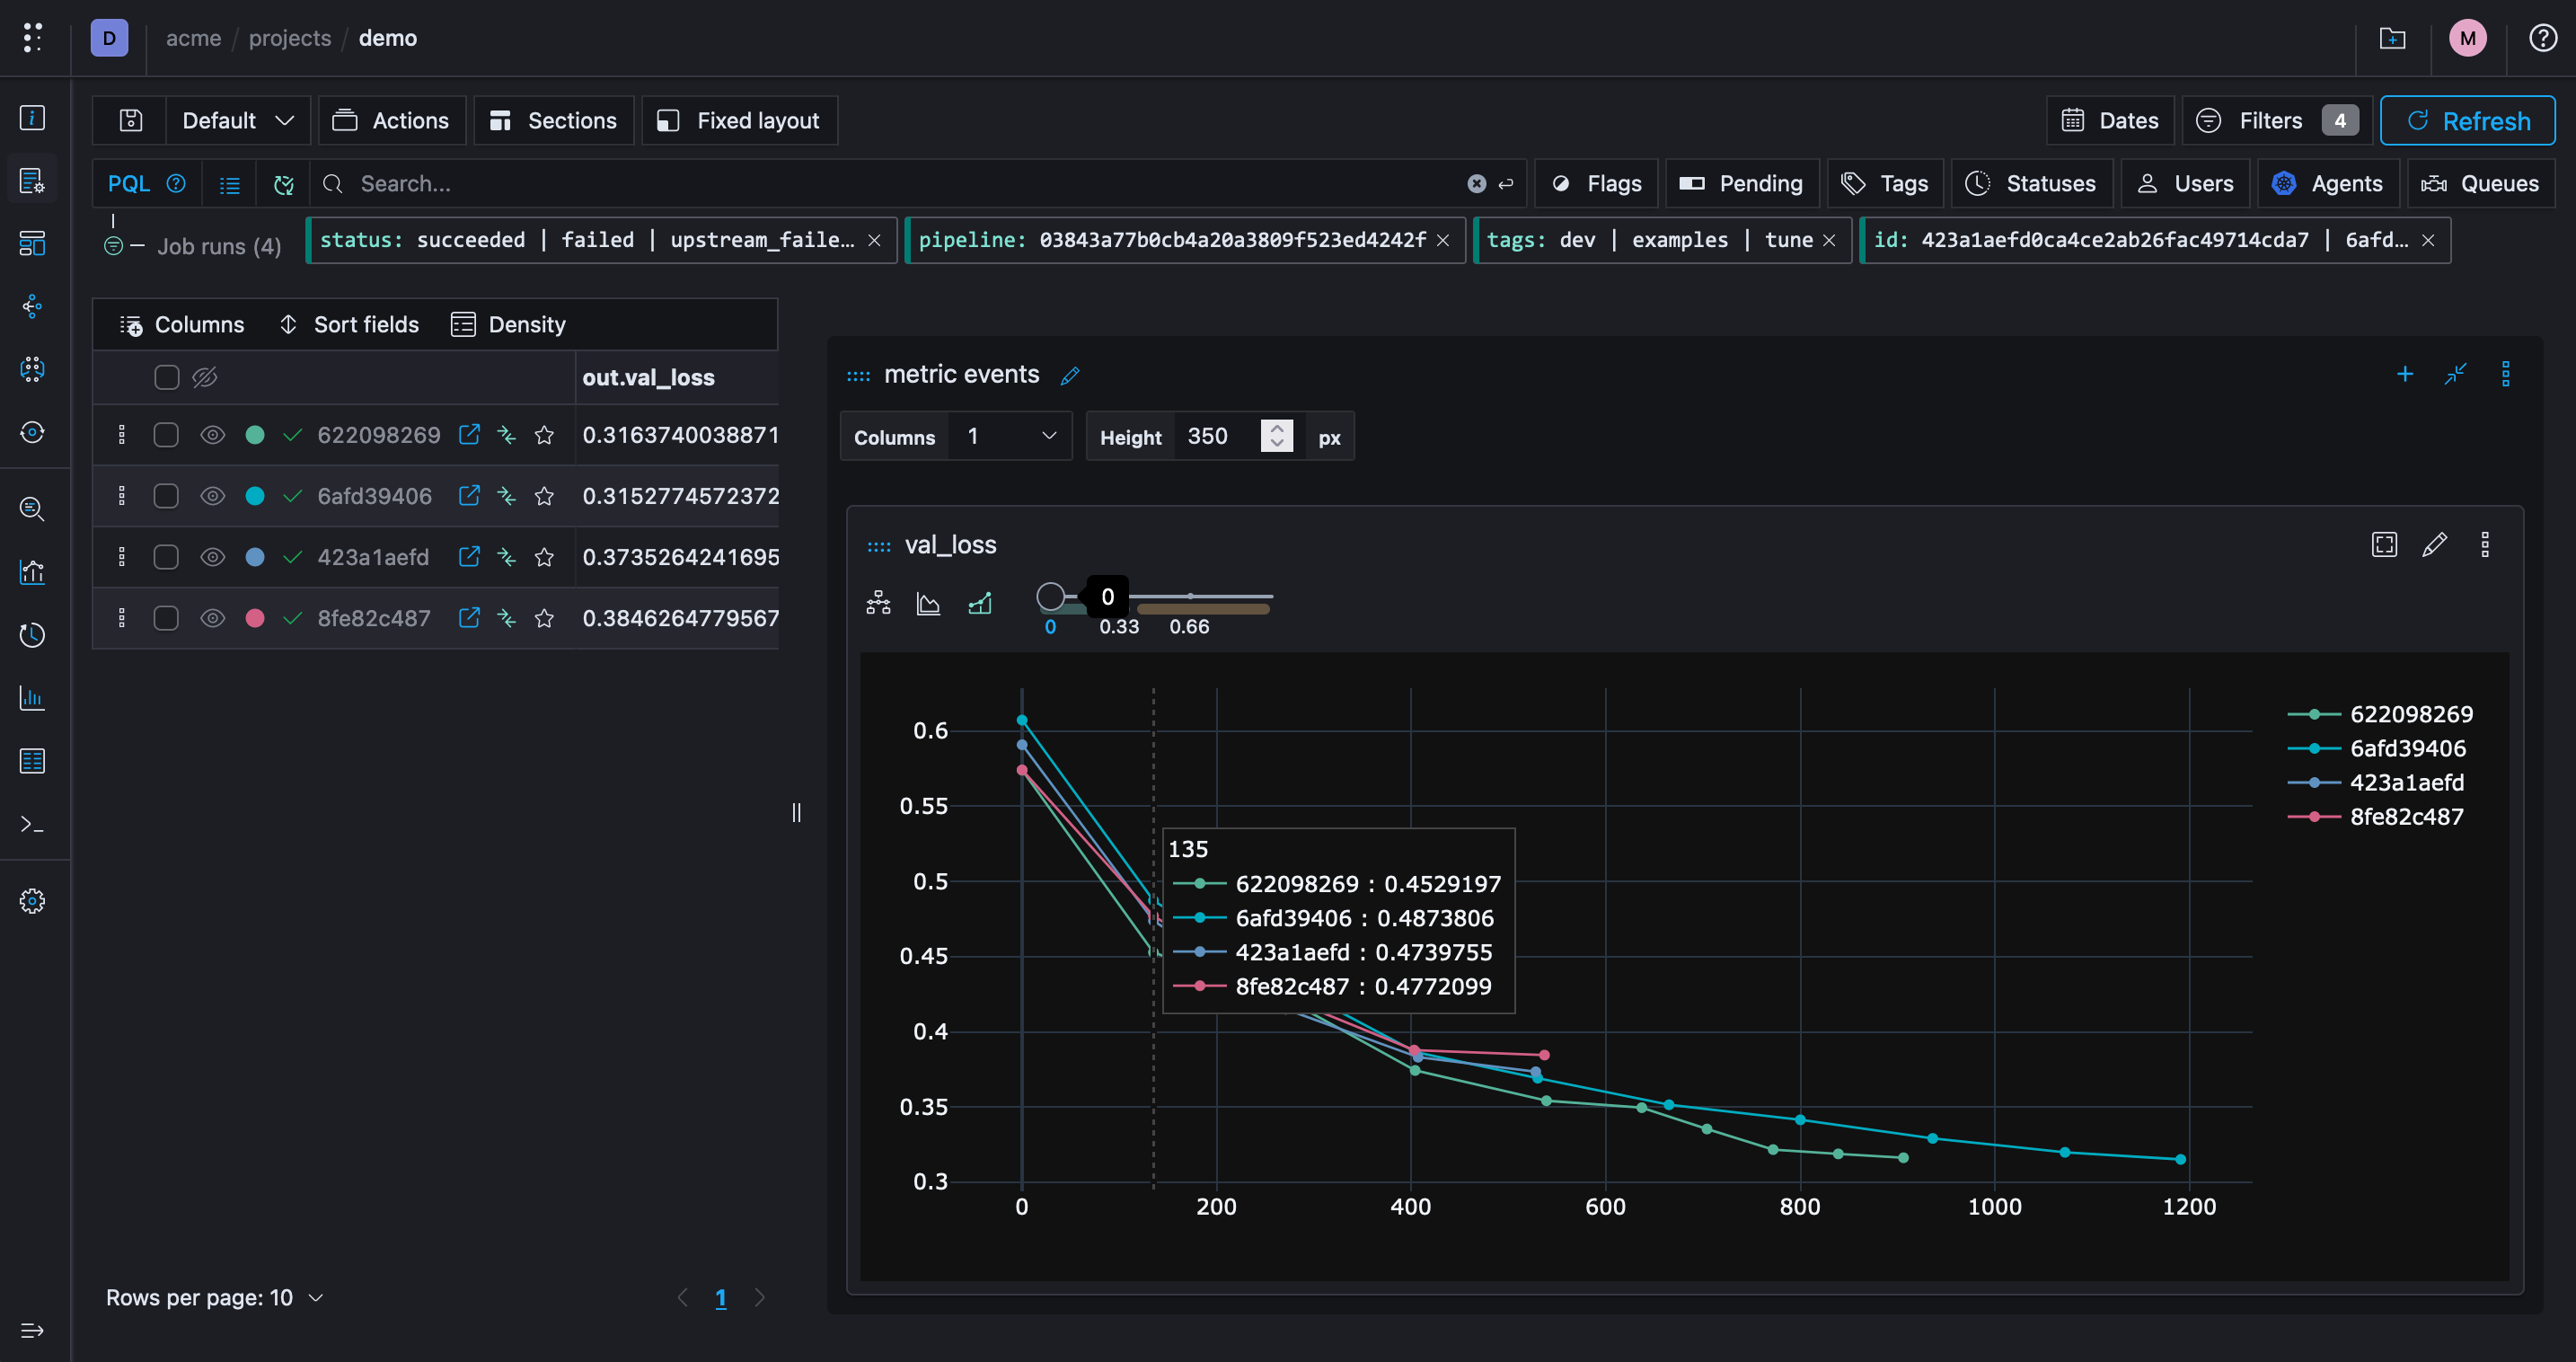
Learn what to record for each ML experiment, how to compare runs fairly, and how to log parameters, metrics, datasets, and model artifacts with Polyaxon.
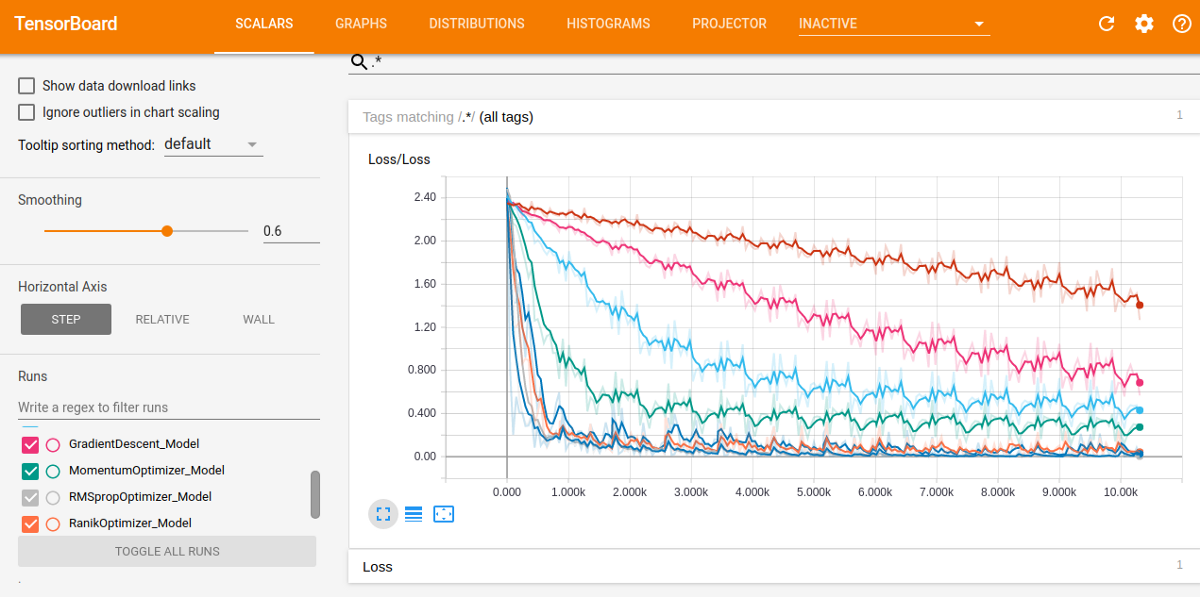
hyperparameters tuning is very important concept in order to choose the optimal hyperparameters for a given algorithm!
Control multi-cloud ML spending with normalized allocation, workload unit economics, placement policies, elastic capacity, and reproducible efficiency measurements.
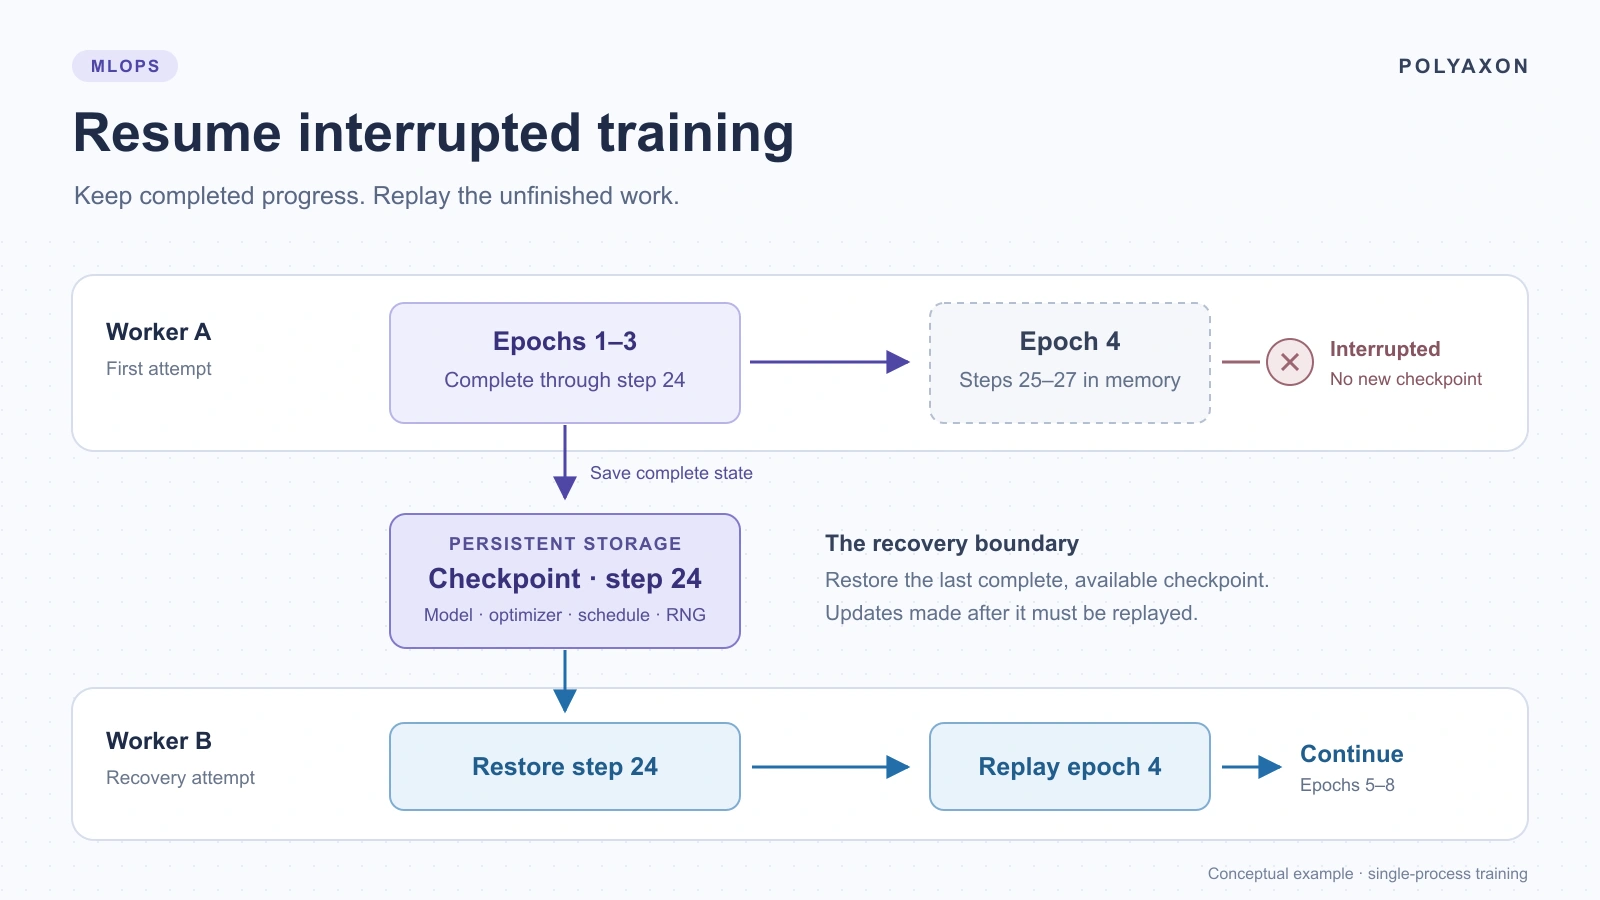
Build recoverable PyTorch training jobs with complete checkpoints, durable storage, and explicit restoration. Practice recovery locally and with Polyaxon.
Agent runtimes, Kubernetes isolation, and parallel coding workflows.
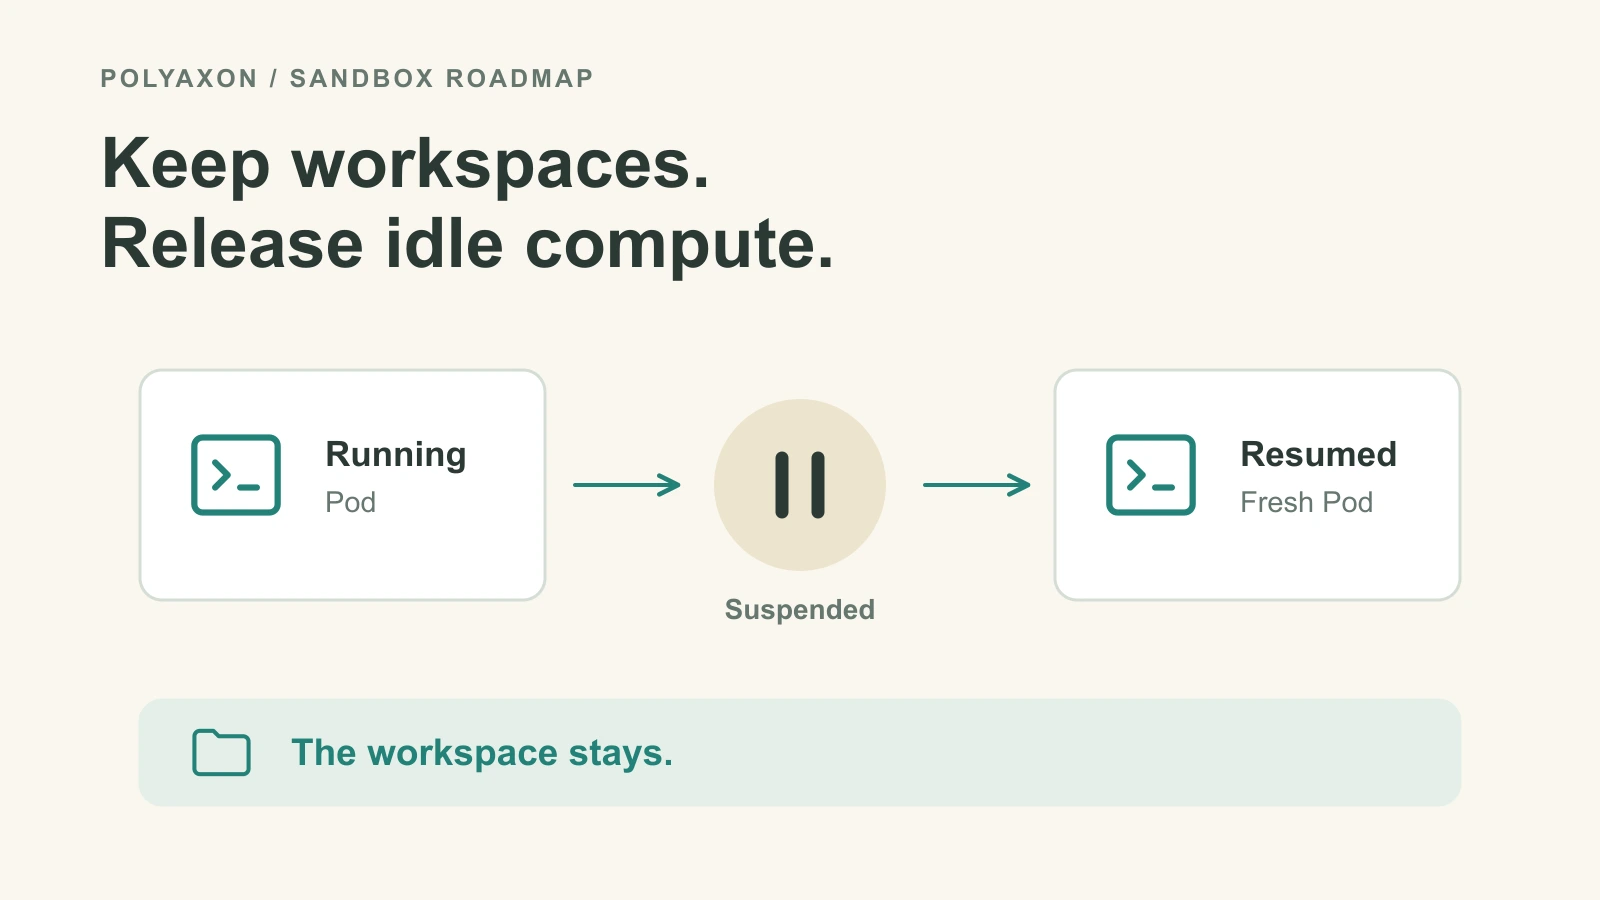
Our plans for persistent sandbox workspaces, suspend/resume, activity-aware idle suspension, and ready pools on Kubernetes—and where AX and Substrate differ.
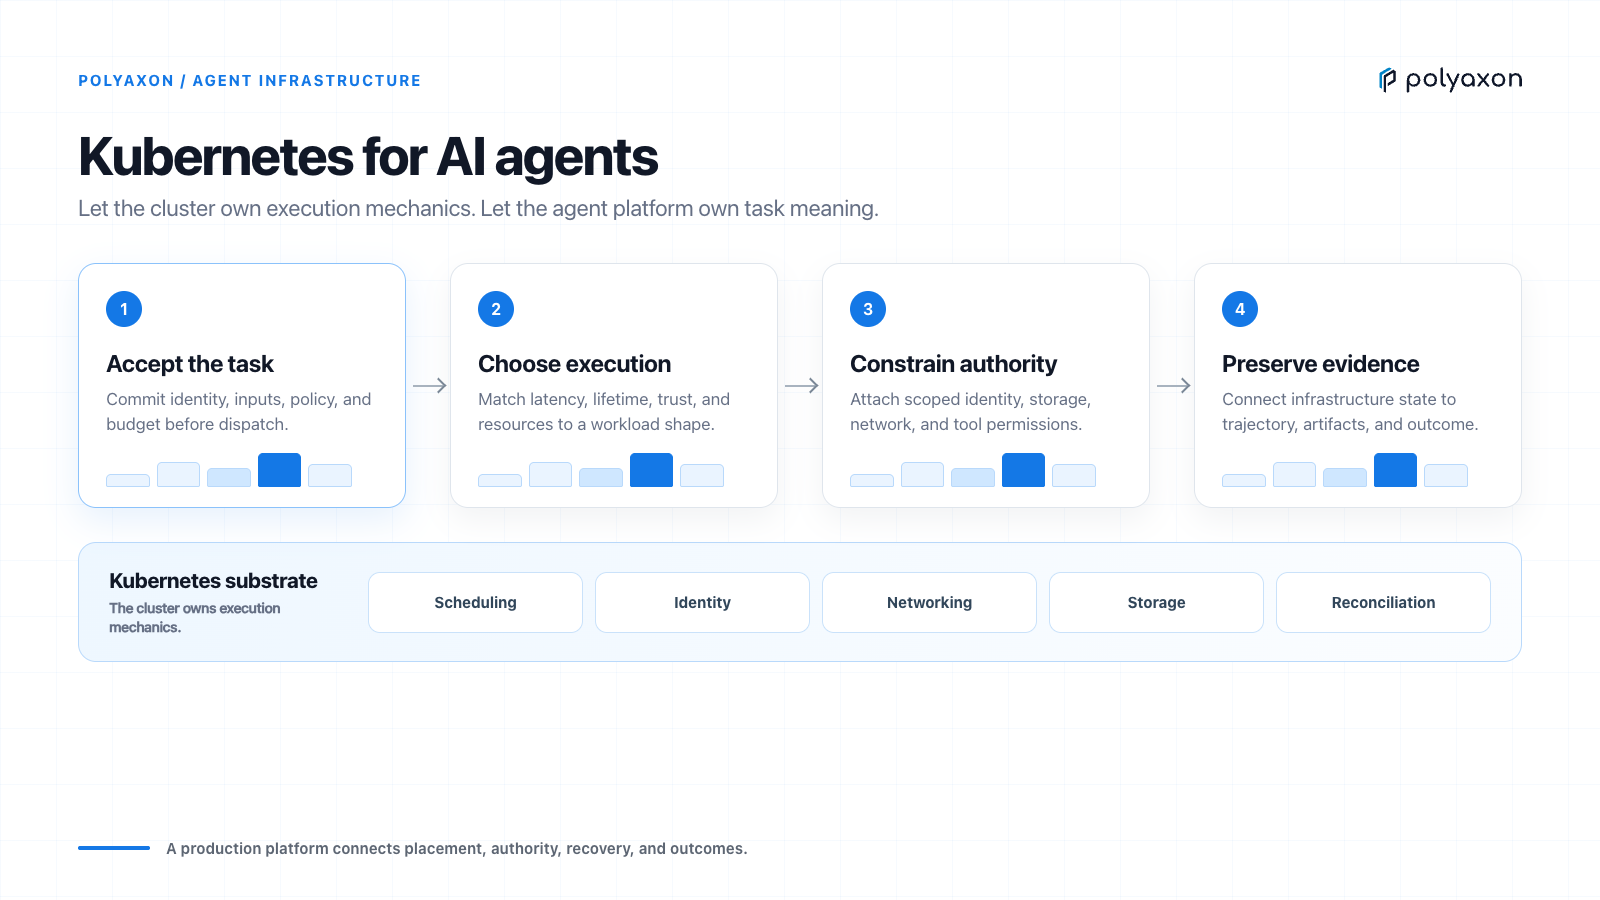
Design a Kubernetes platform for AI agents with clear workload boundaries, durable state, scoped access, resource controls, and end-to-end evidence.
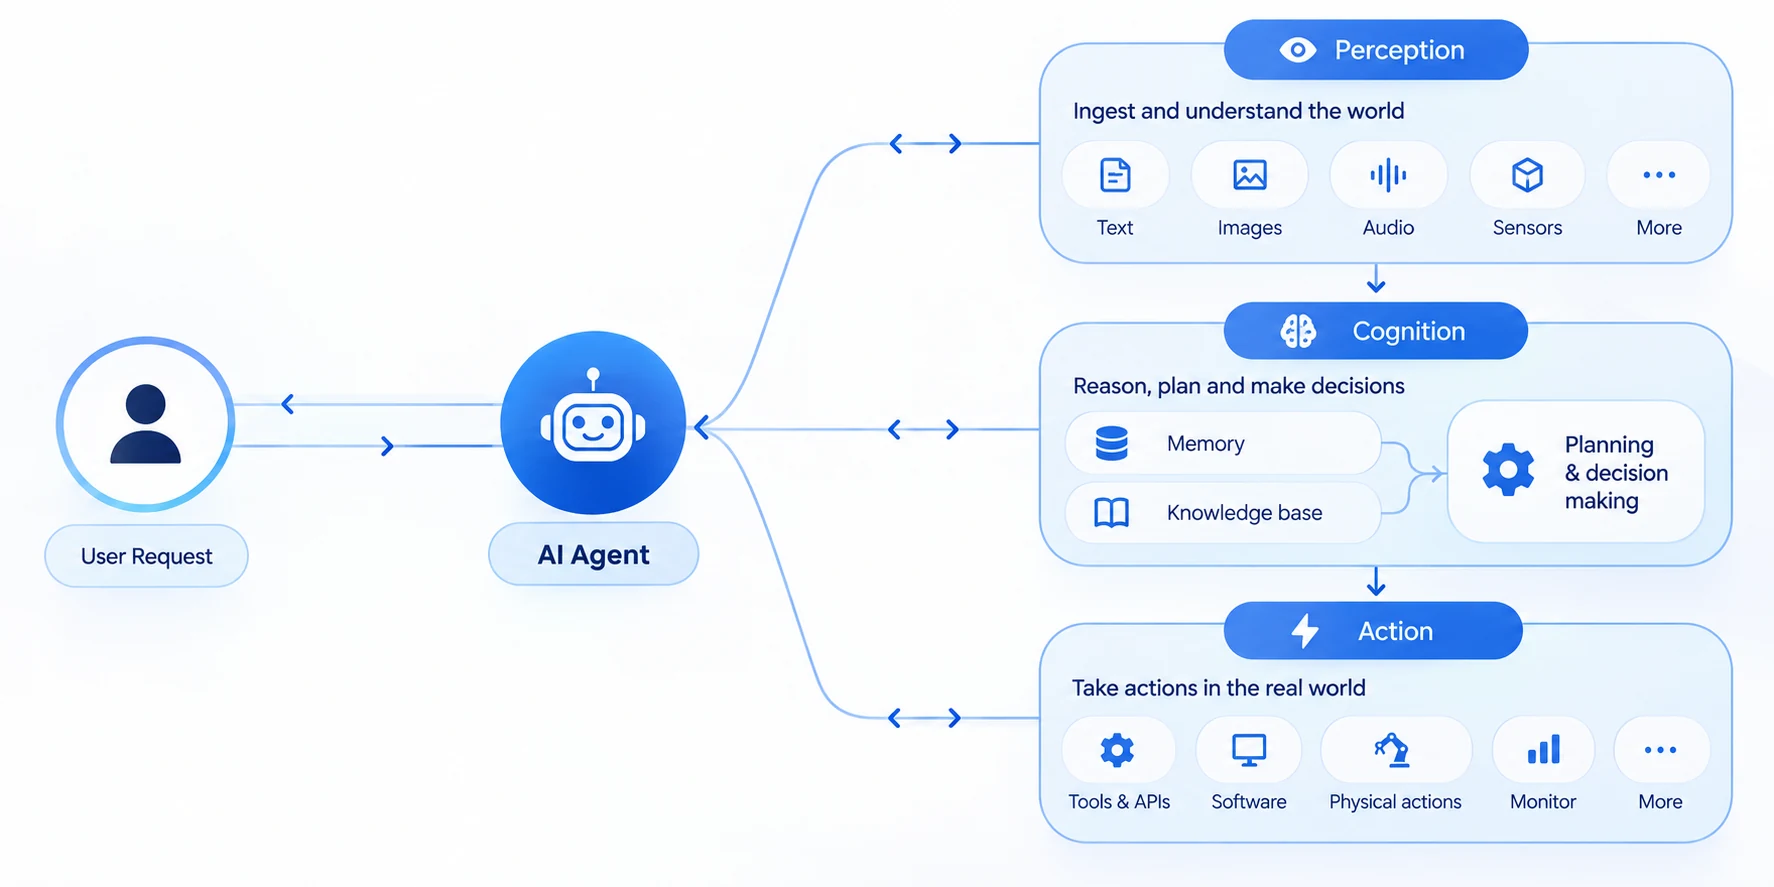
Map agent architectures to Polyaxon jobs, services, and DAGs, with concrete workload configuration and a repeatable architecture-comparison workflow.
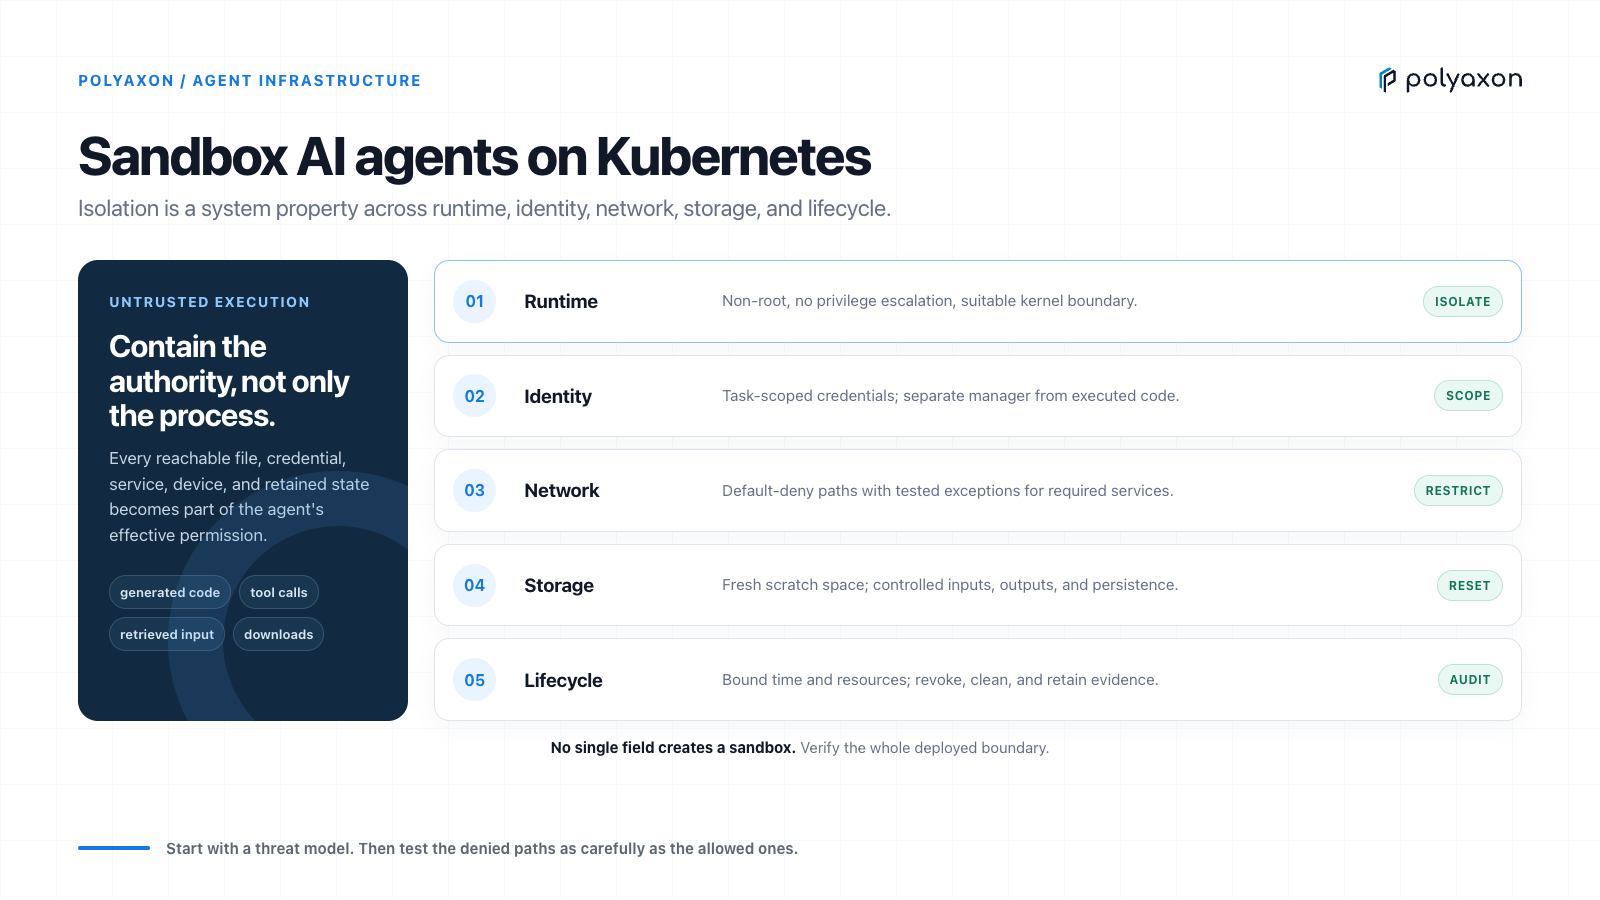
Design isolated Kubernetes execution for AI agents with a threat model, stronger runtimes, scoped identity, controlled egress, bounded storage, and auditable cleanup.

Run parallel coding agents in separate Polyaxon workspaces, collect candidate patches, evaluate independently, and merge only reviewed changes.
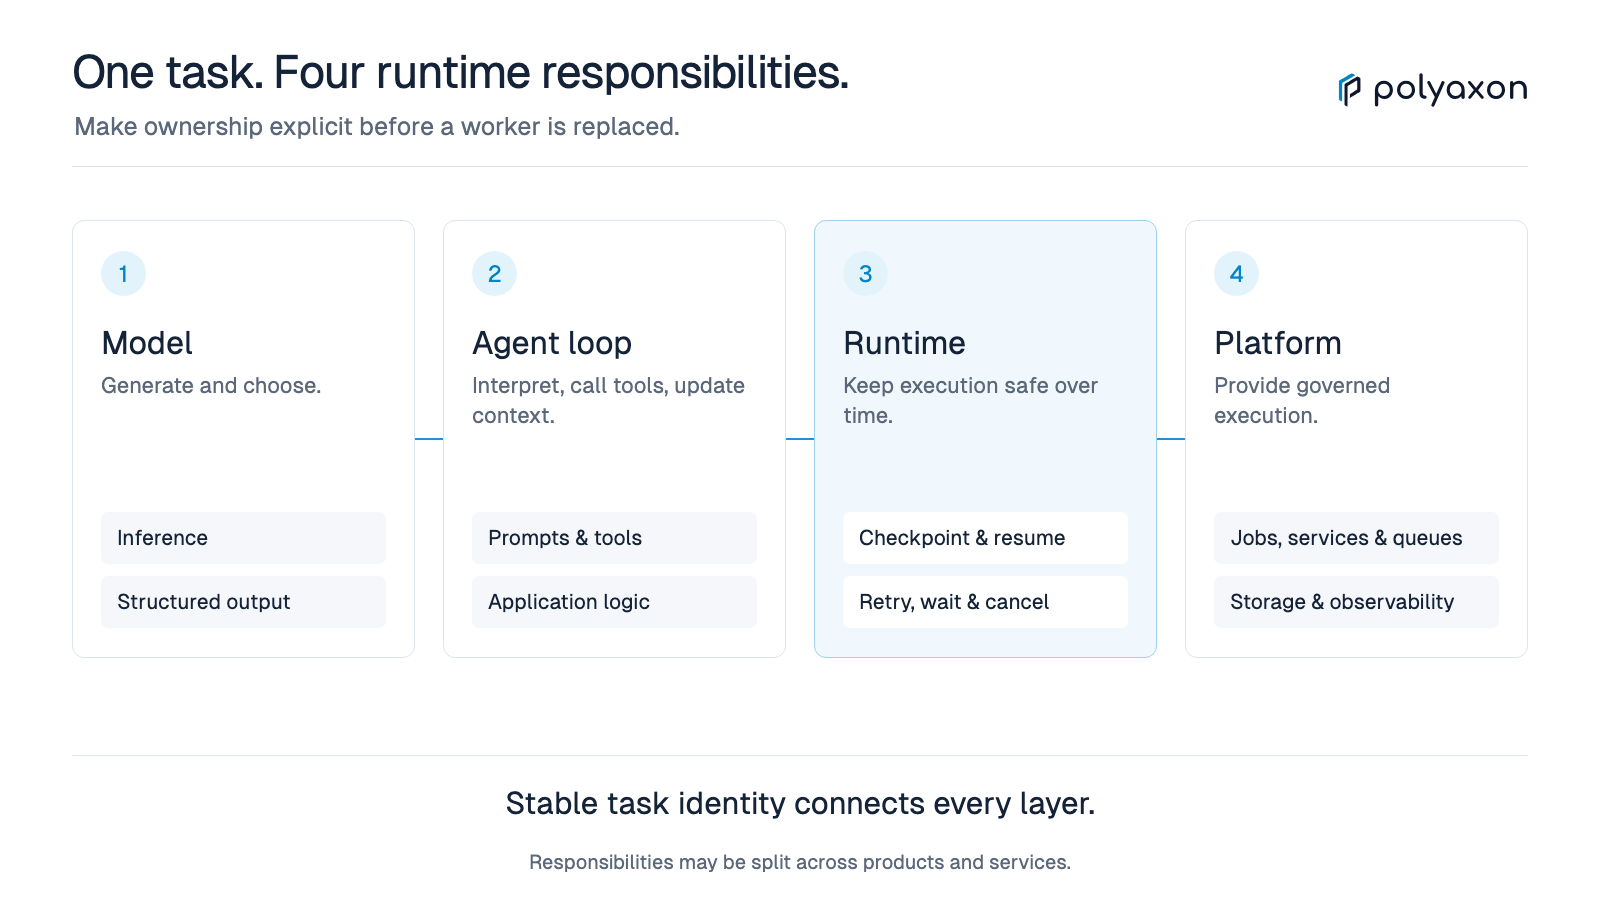
Design agent execution around durable state, safe tool retries, approval waits, and recovery, with clear responsibilities for Polyaxon and your agent framework.
Evaluate, observe, and improve LLM applications in production.
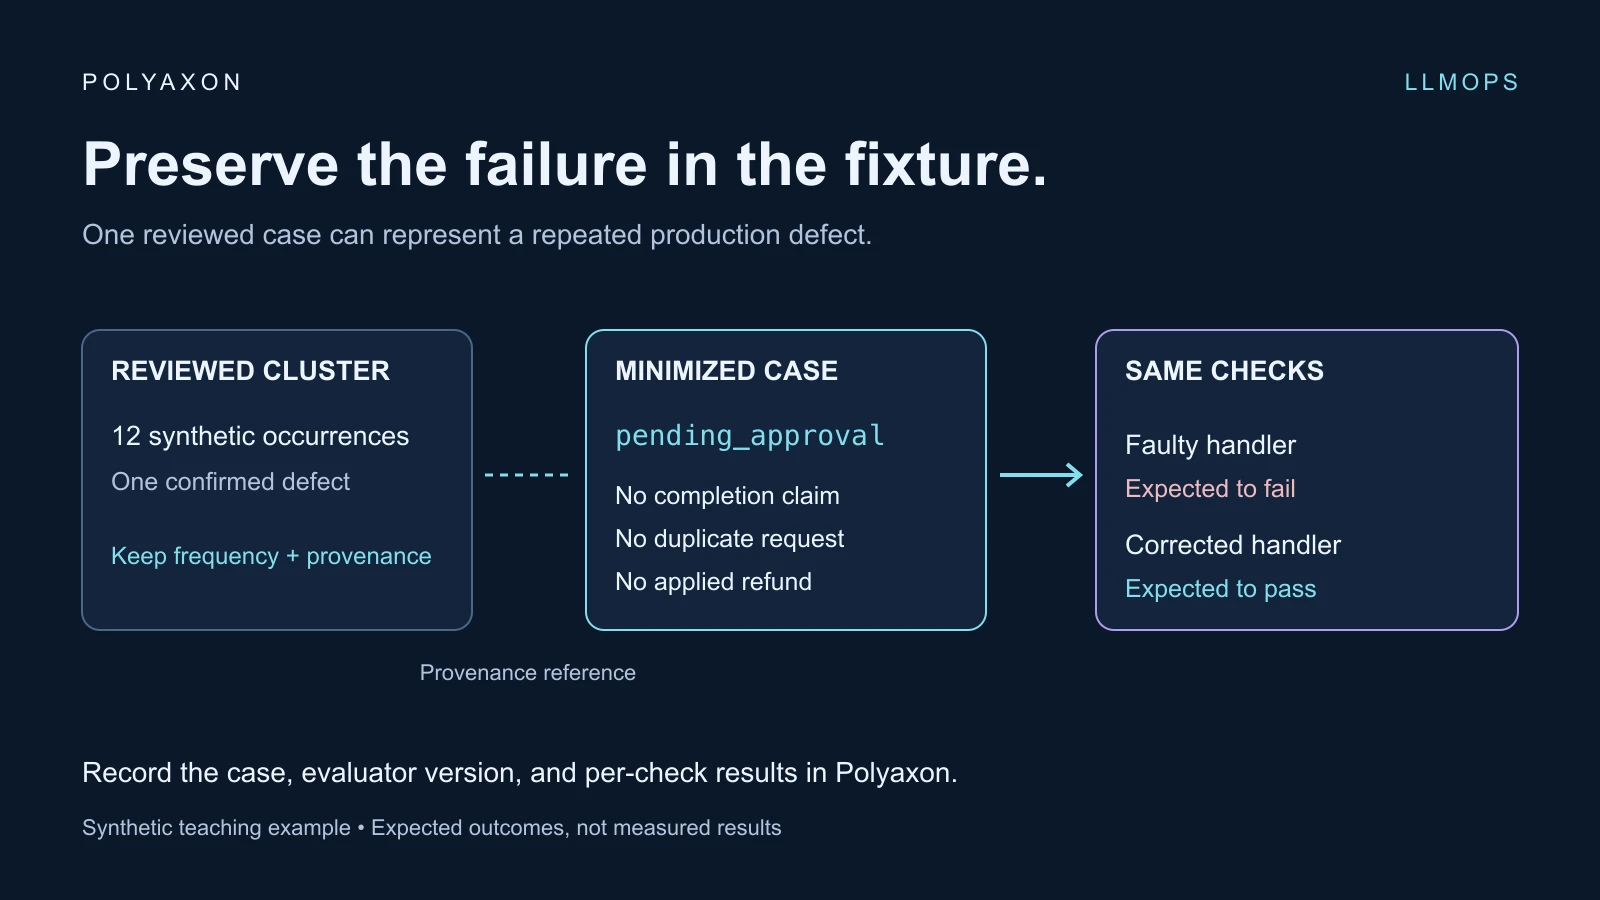
Turn a failure cluster into a reviewed regression case, preserve the causal tool response, and record baseline and candidate checks with Polyaxon.
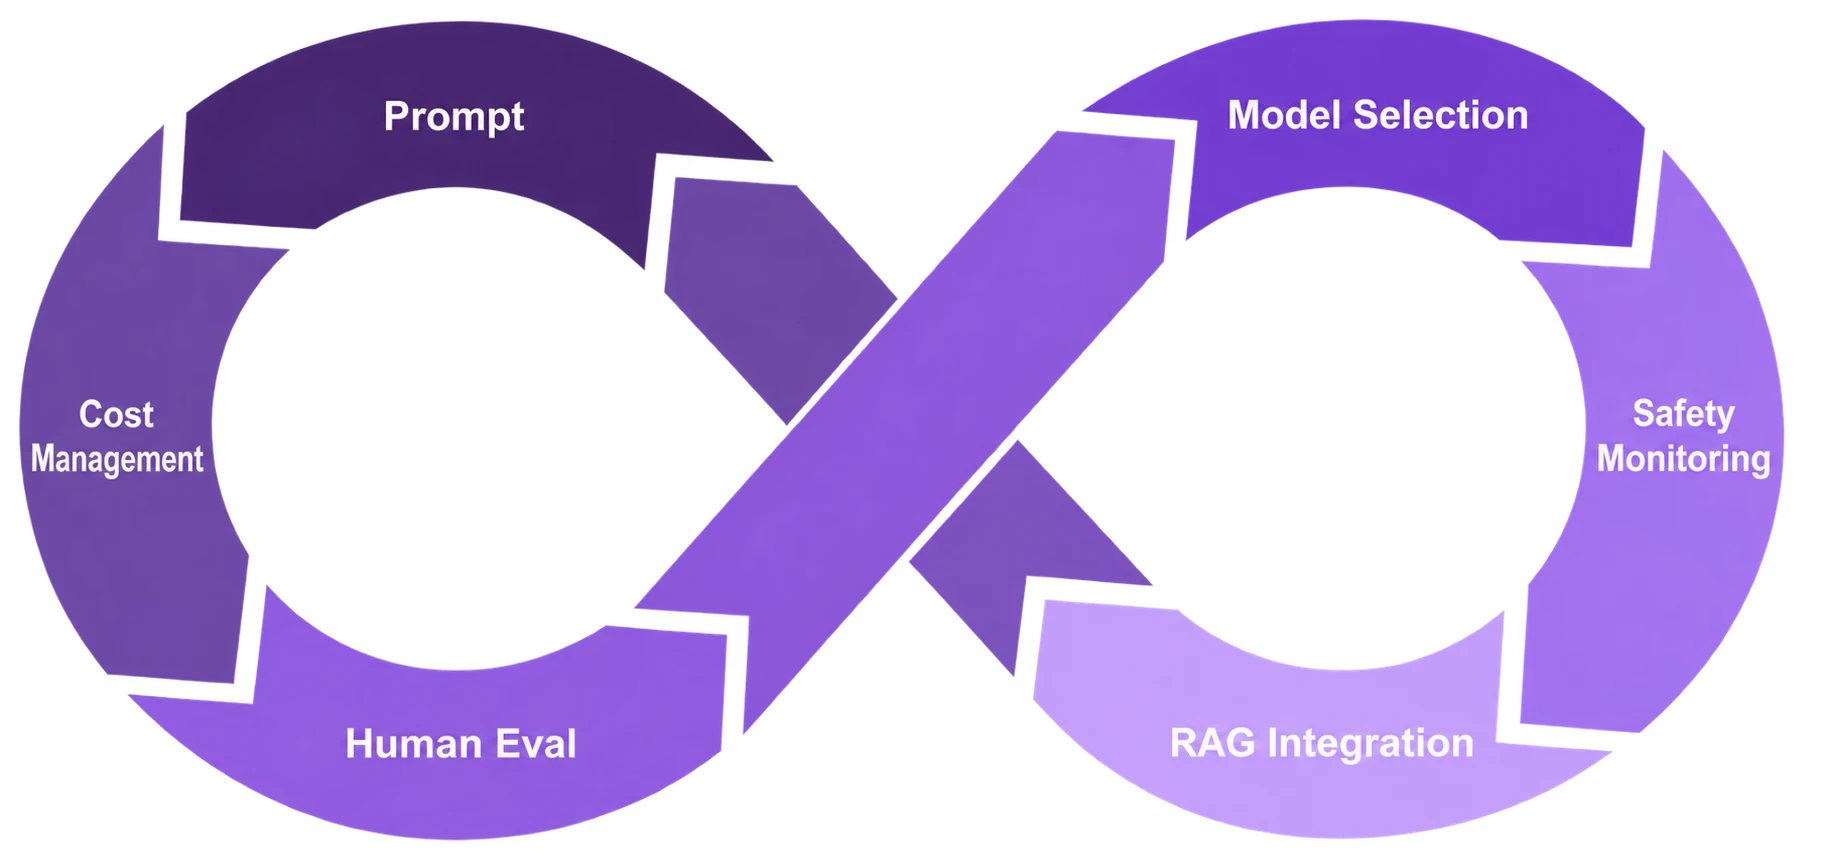
LLMOps applies repeatable development, evaluation, deployment, and observability practices to production LLM applications and AI agents.
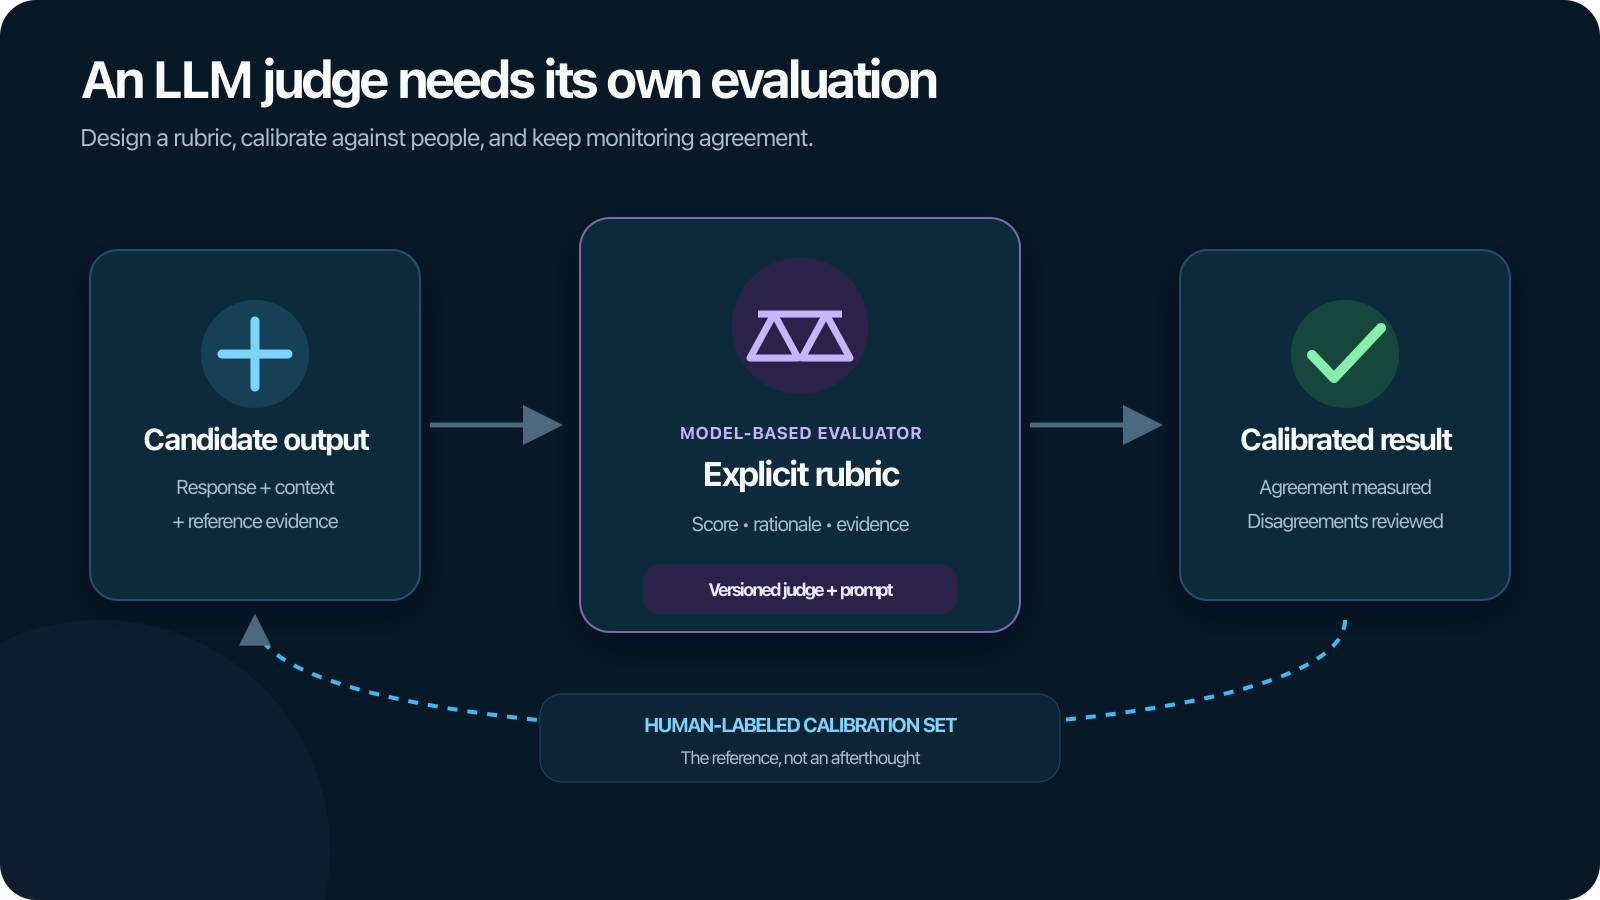
Use LLMs as scalable evaluators without treating them as ground truth: design clear rubrics, calibrate against humans, and monitor bias and drift.
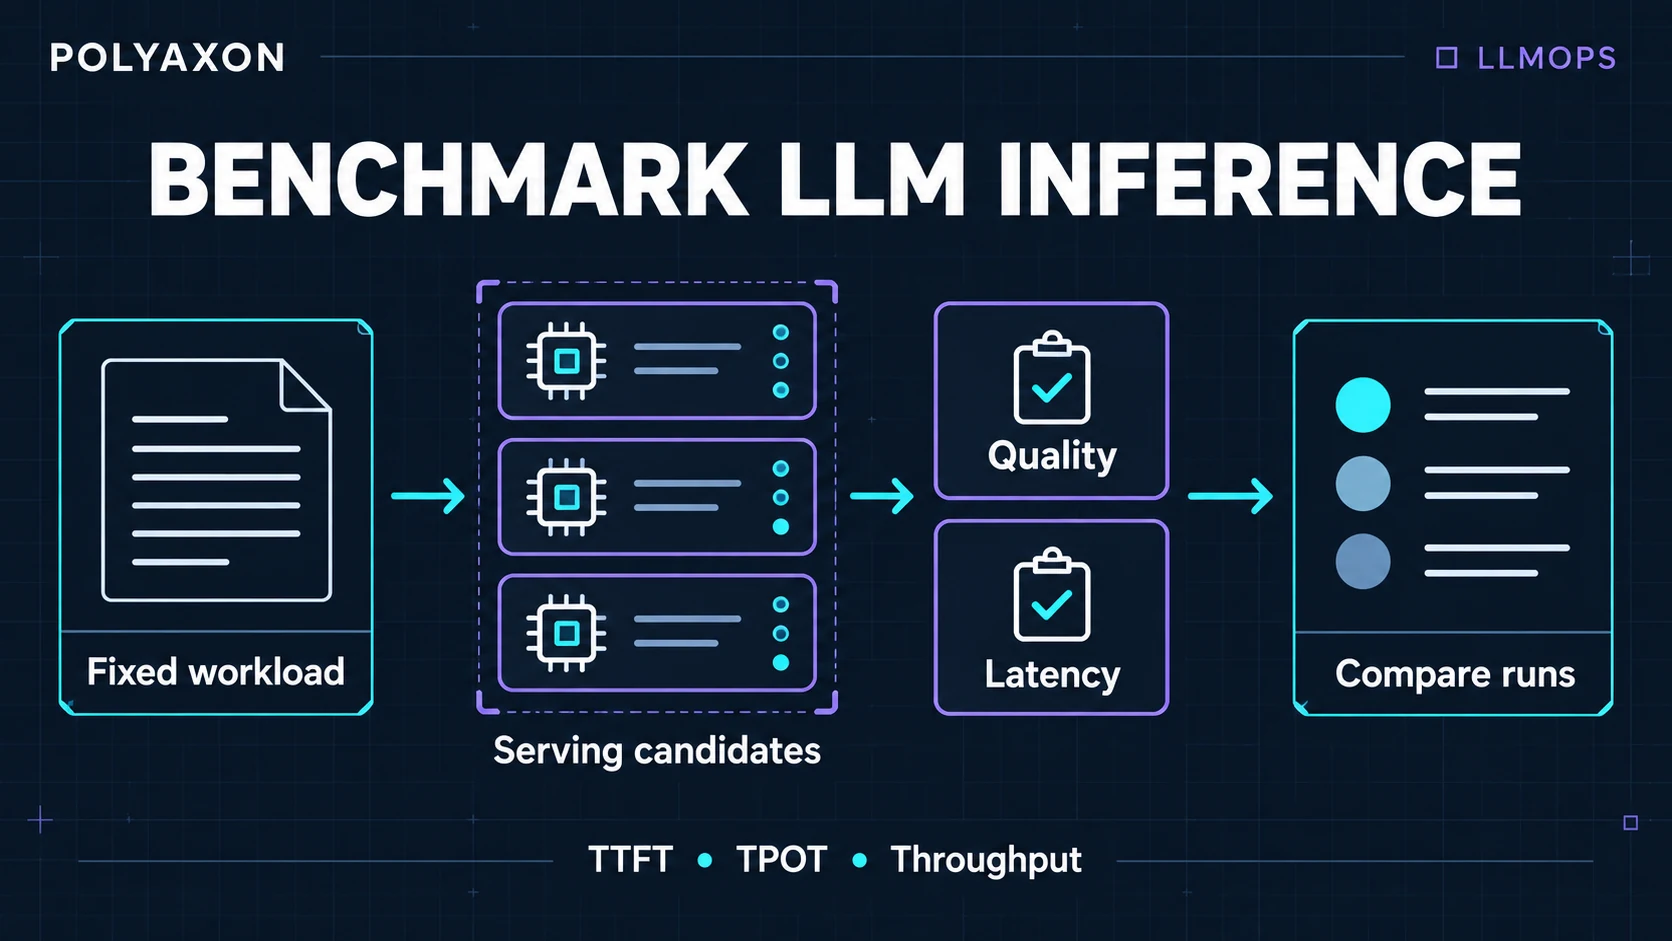
Compare inference optimizations against a fixed workload, latency limits, and quality checks, with benchmark configurations and results tracked in Polyaxon.
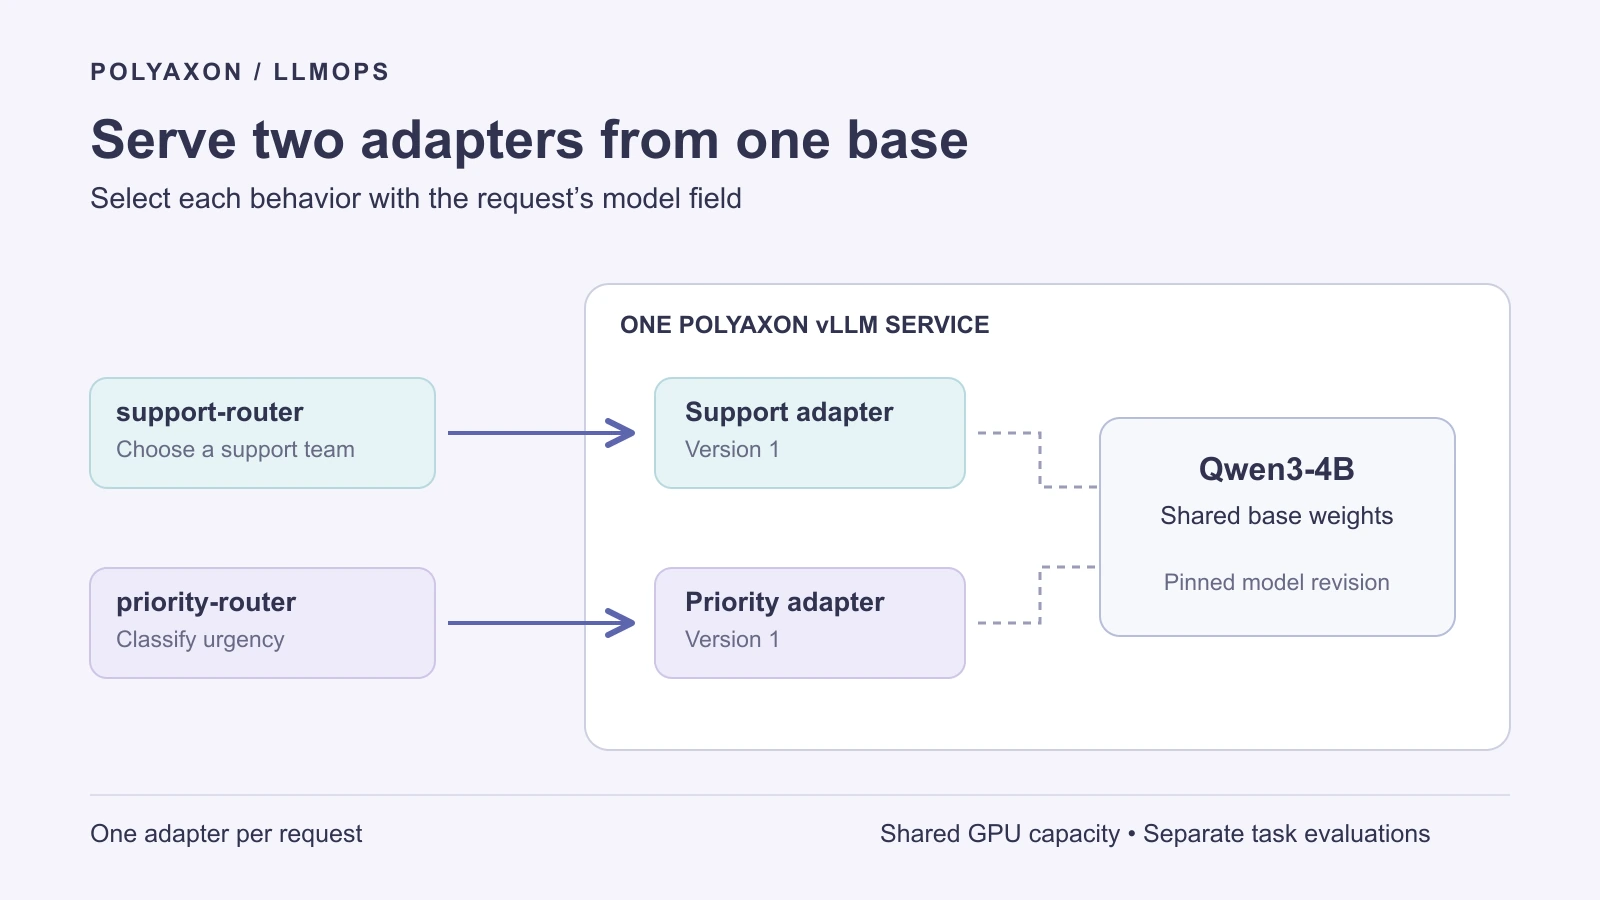
Deploy two task-specific LoRA adapters over one Qwen base model, select them by name, and measure quality and shared GPU capacity with Polyaxon.
Build reliable data pipelines and preserve the evidence behind your models.
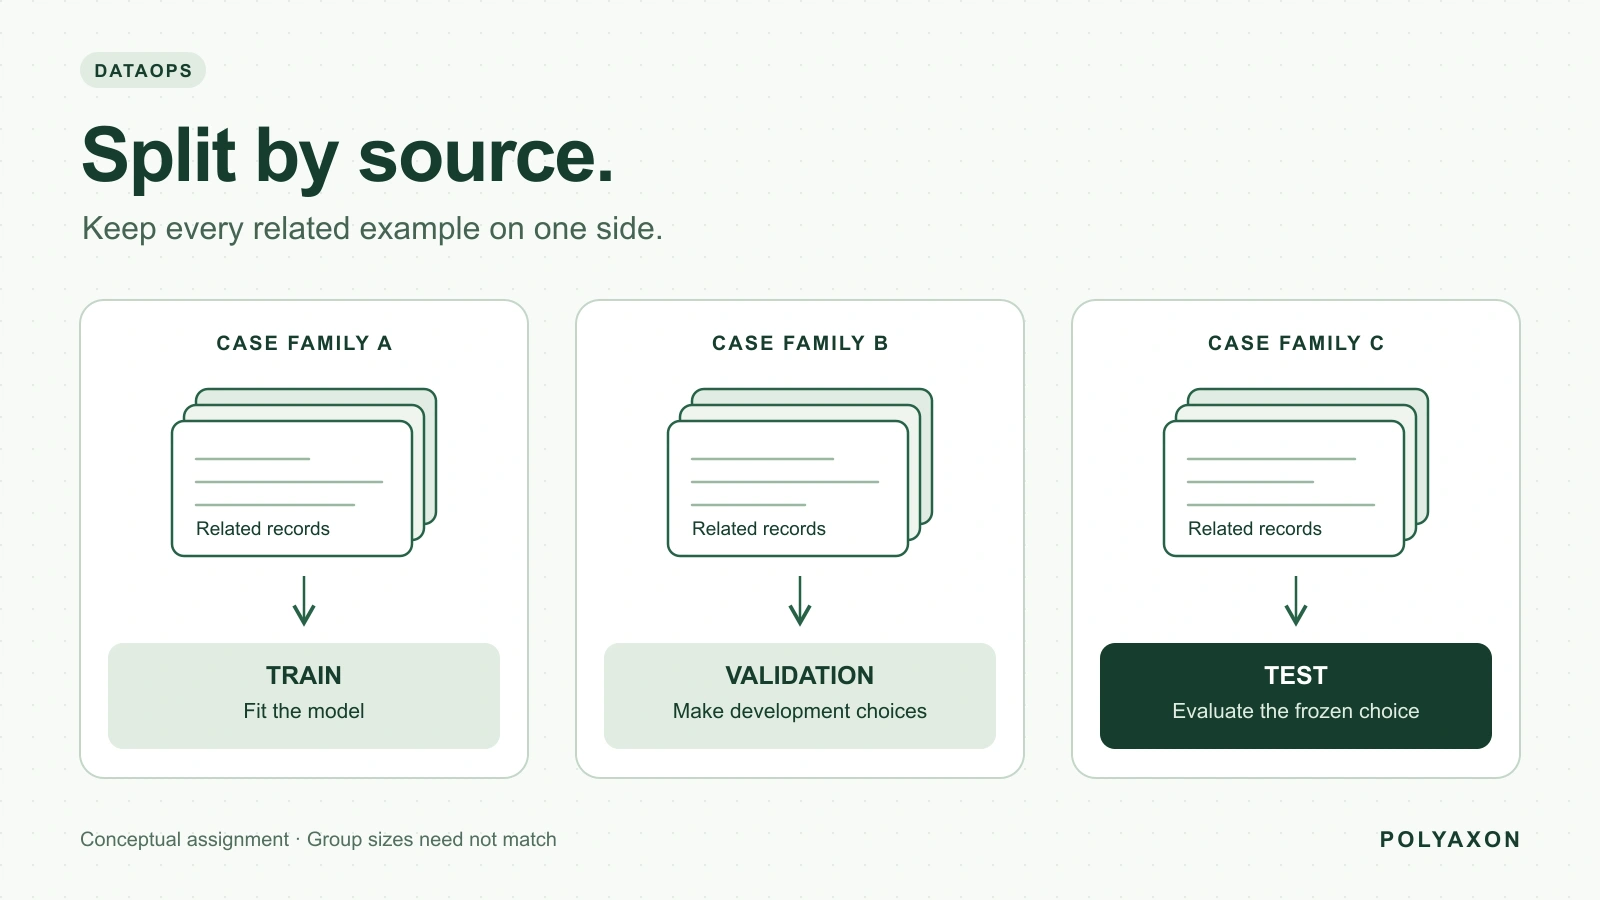
Choose evaluation boundaries, keep related examples together, audit duplicate overlap, and retain reproducible split manifests for ML and LLM experiments.
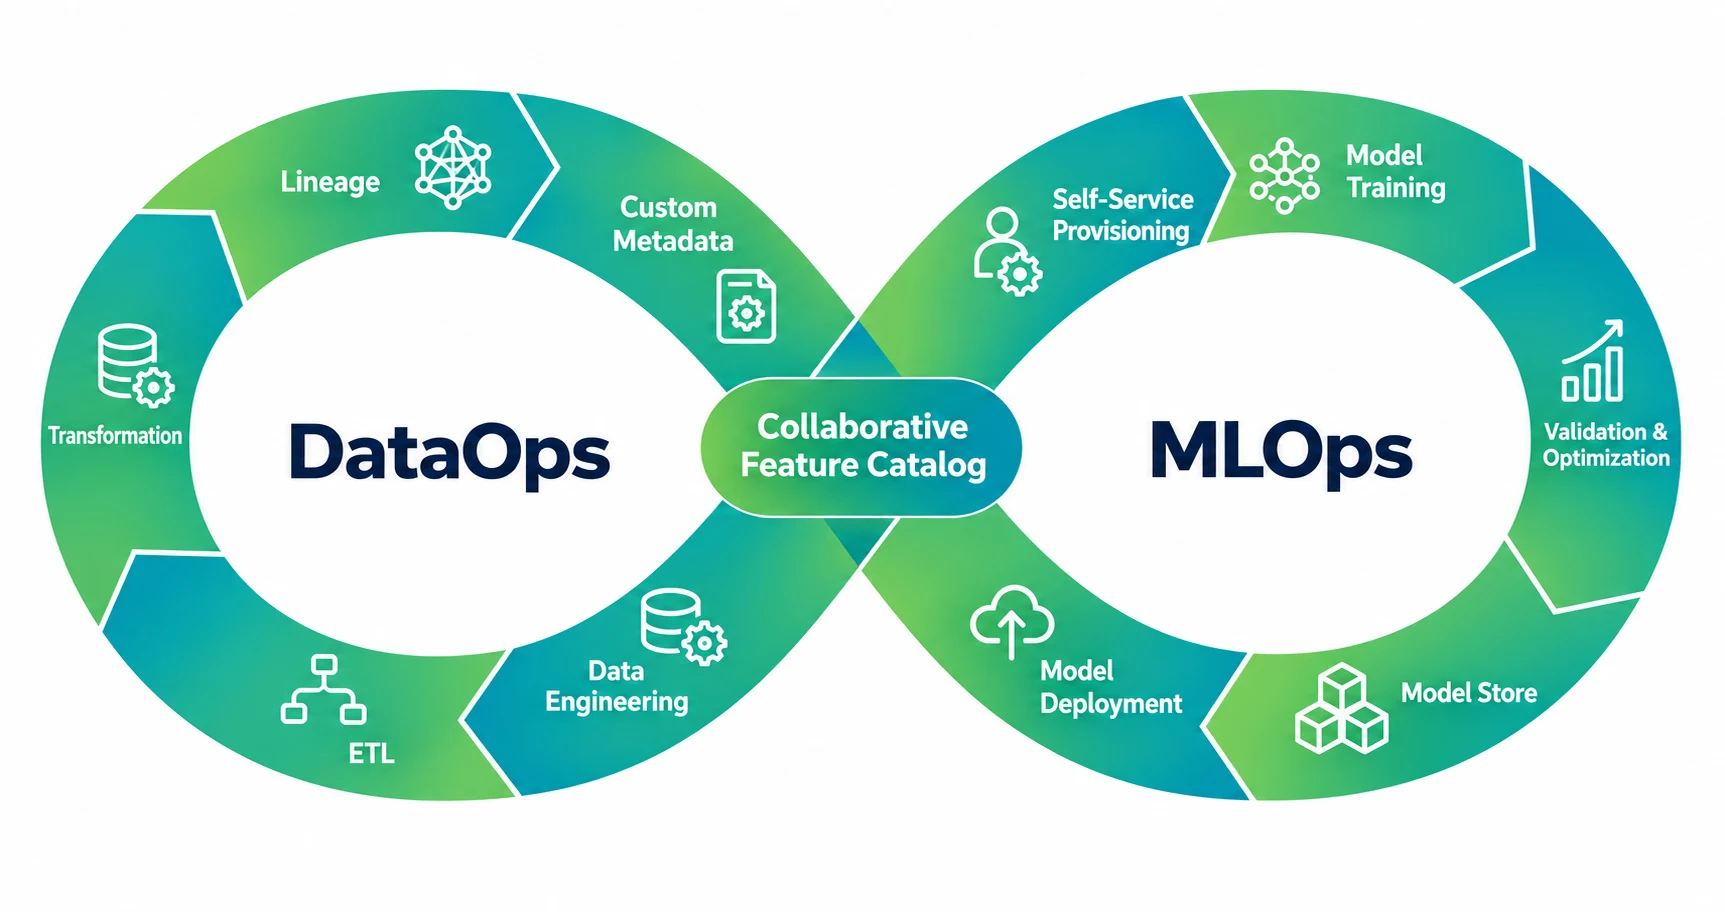
DataOps delivers reliable data; MLOps delivers reliable ML systems. Compare their responsibilities, checks, and handoffs using a practical example.
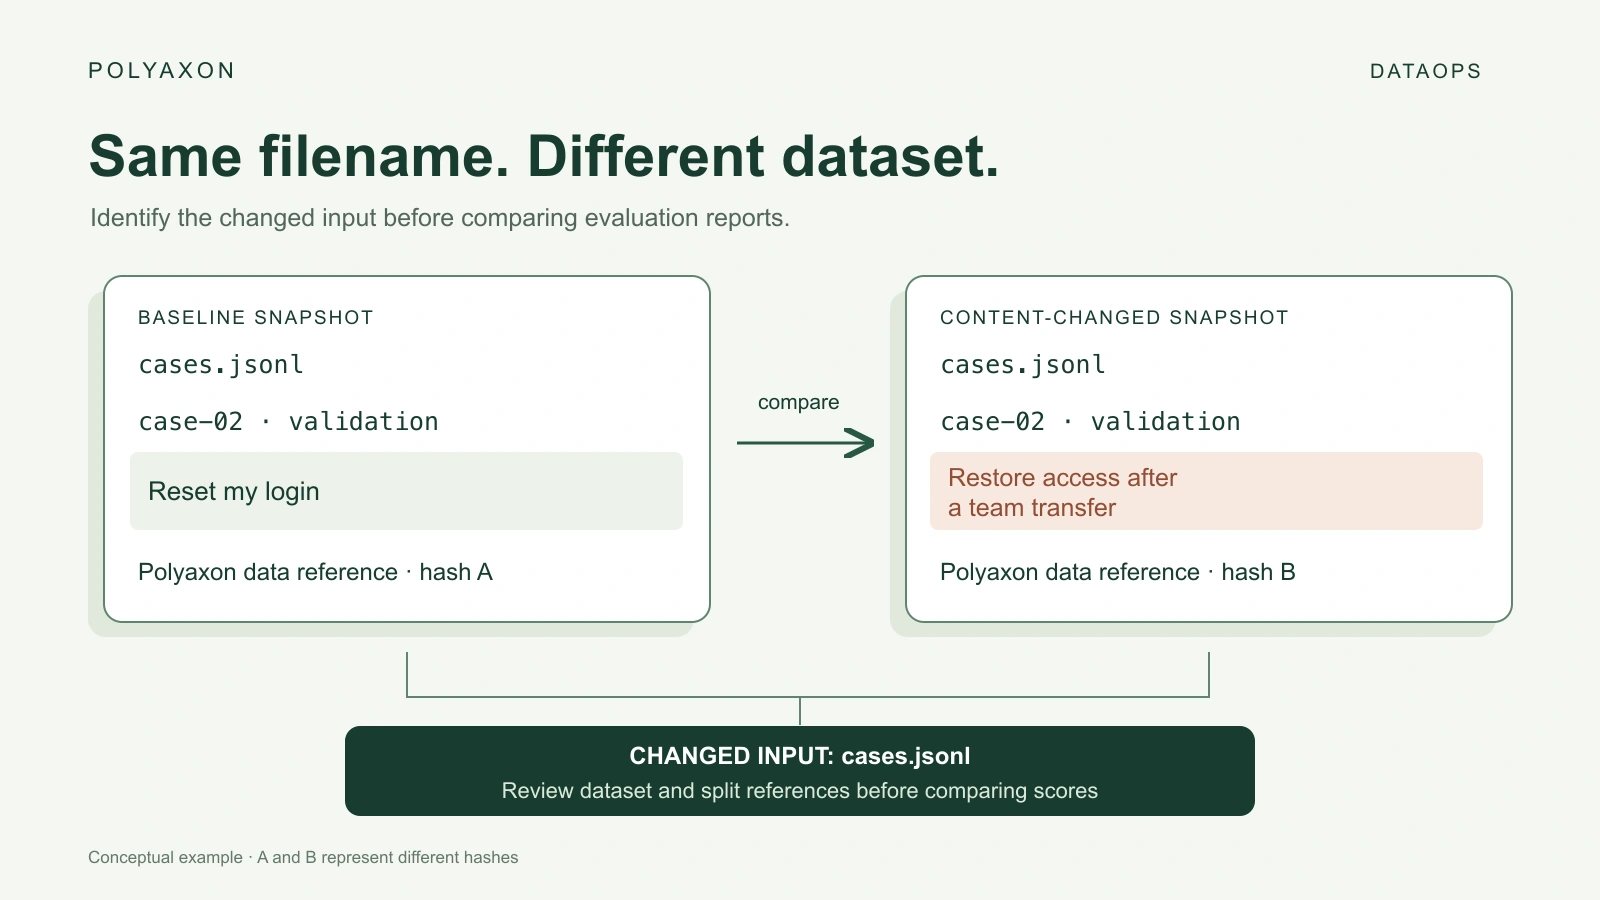
Use Polyaxon data references, artifact logging, and registered versions to retain the dataset and split behind each evaluation.
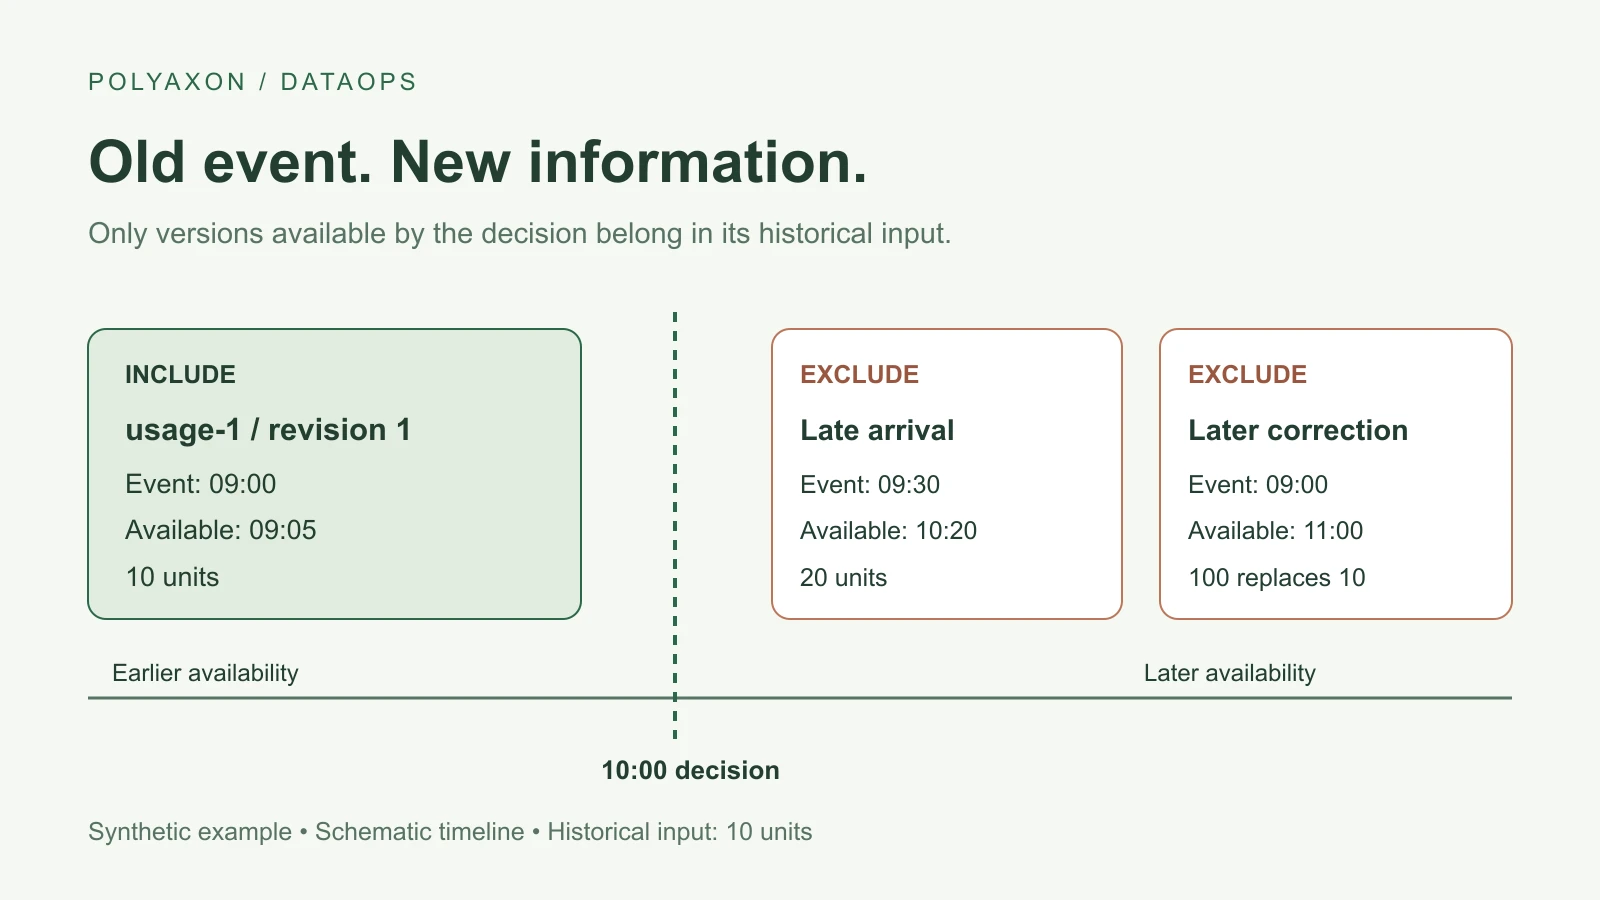
Reconstruct evaluation features using event time and actual availability time, excluding late arrivals and later corrections while preserving the source versions in Polyaxon.
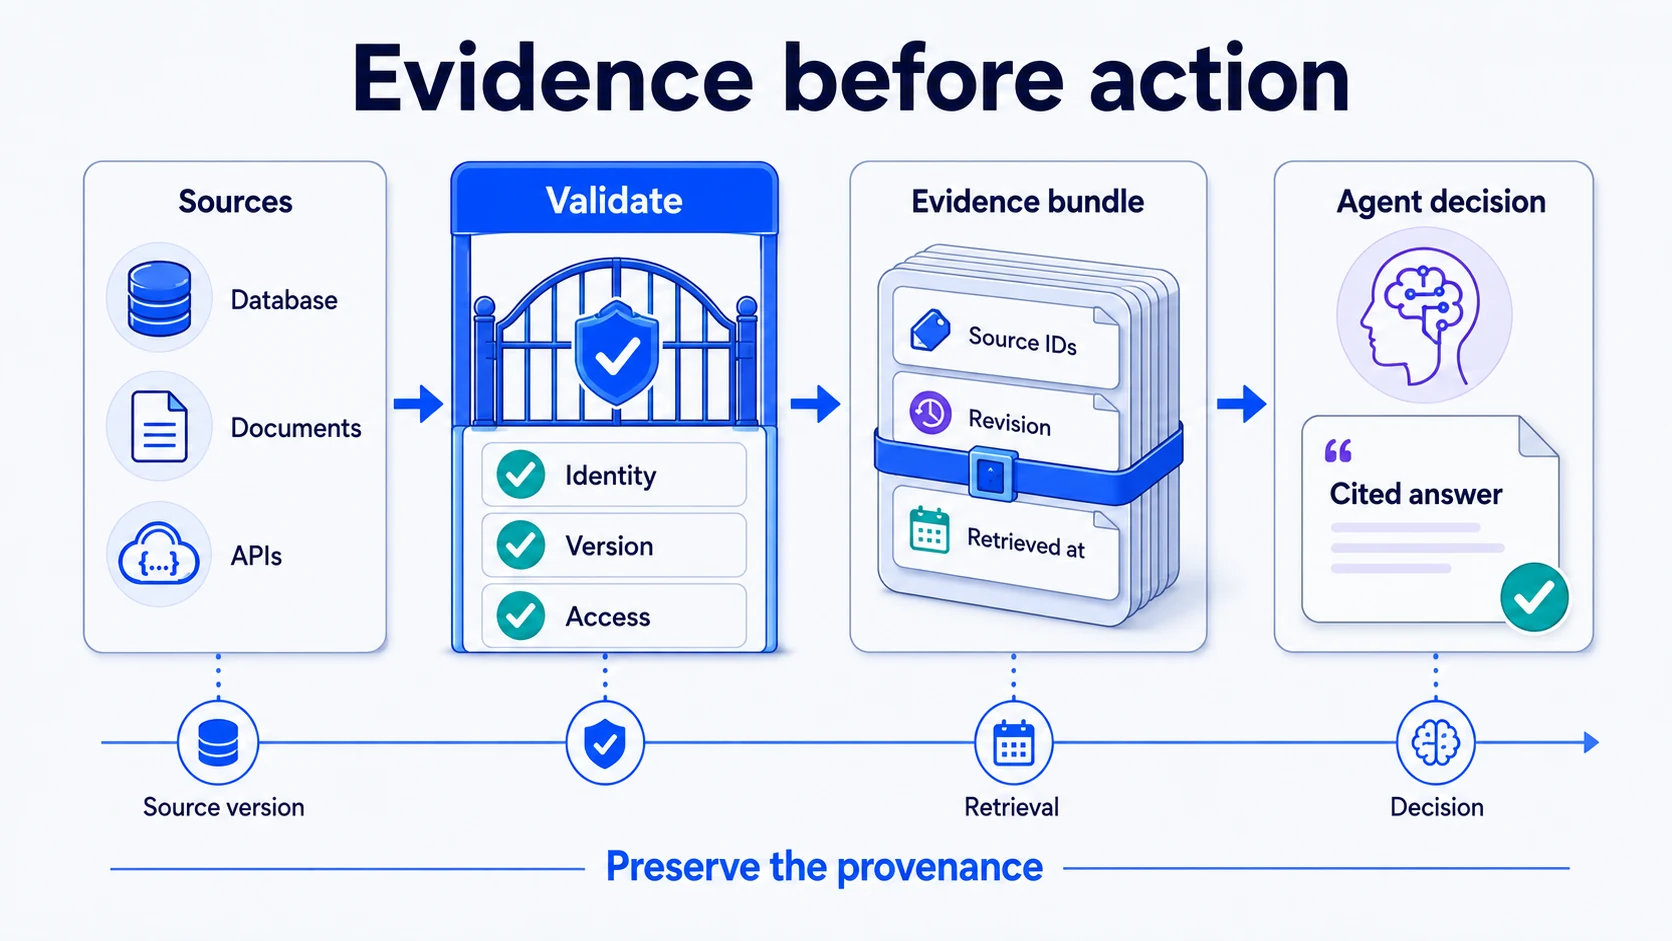
Design agent data paths that preserve source identity, versions, permissions, freshness, retrieval evidence, and verification results.
The latest guides, tutorials, and product updates.

Save a Polyaxon comparison's query, columns, sorting and charts, reopen it for later runs, and share reusable searches and dashboards with your team.
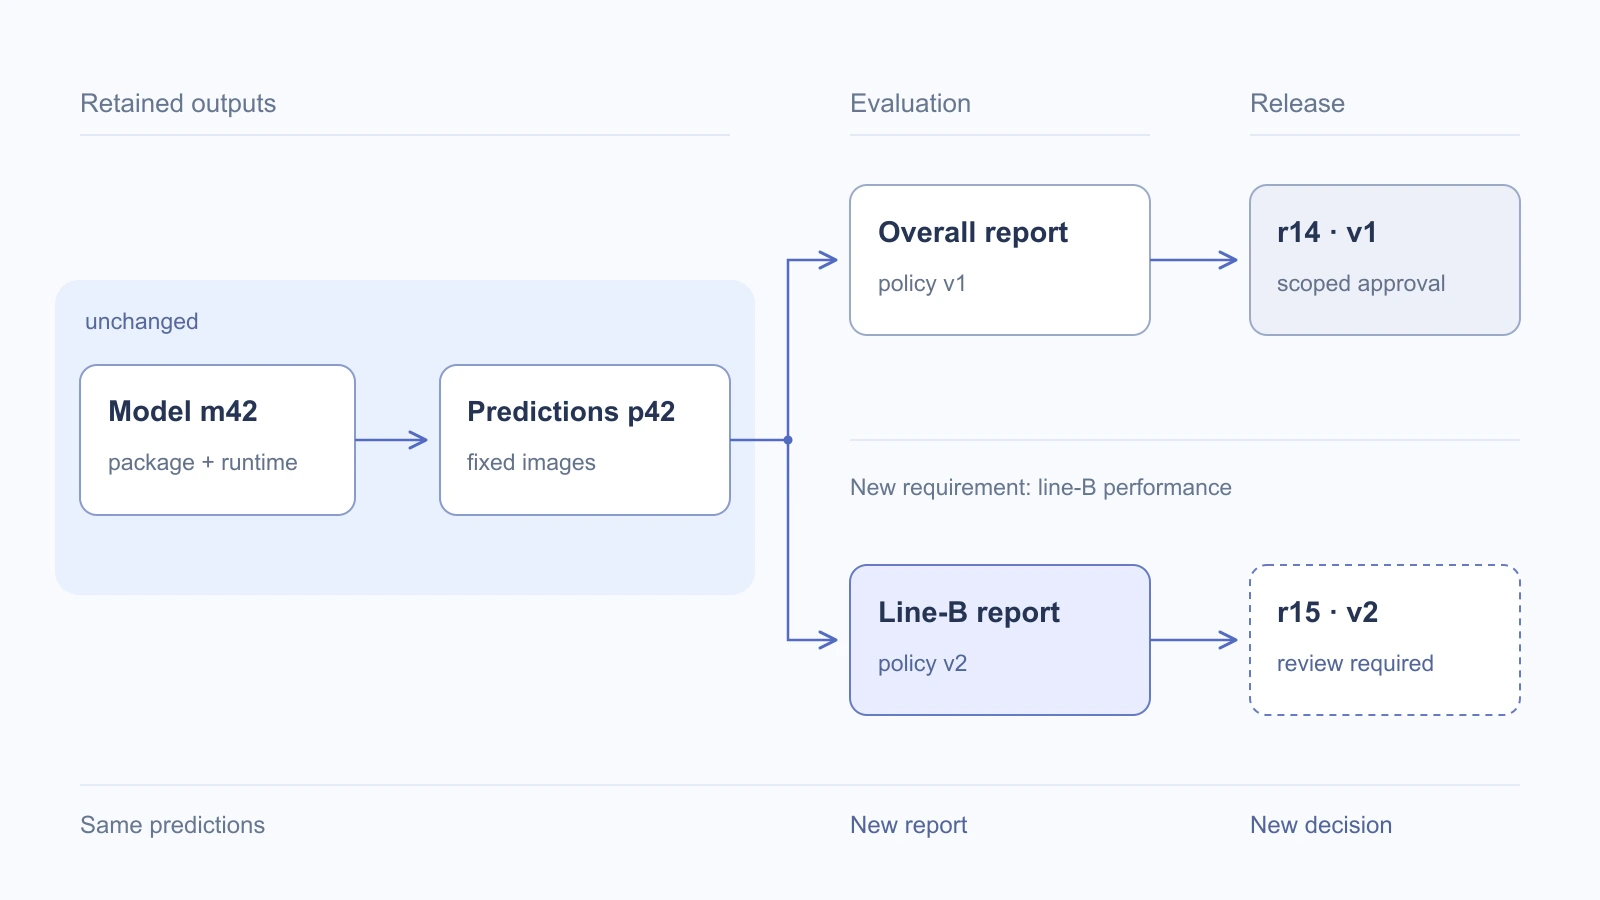
Build an attributable model release record, reuse unchanged pipeline outputs, and recompute reports and decisions when their dependencies change.
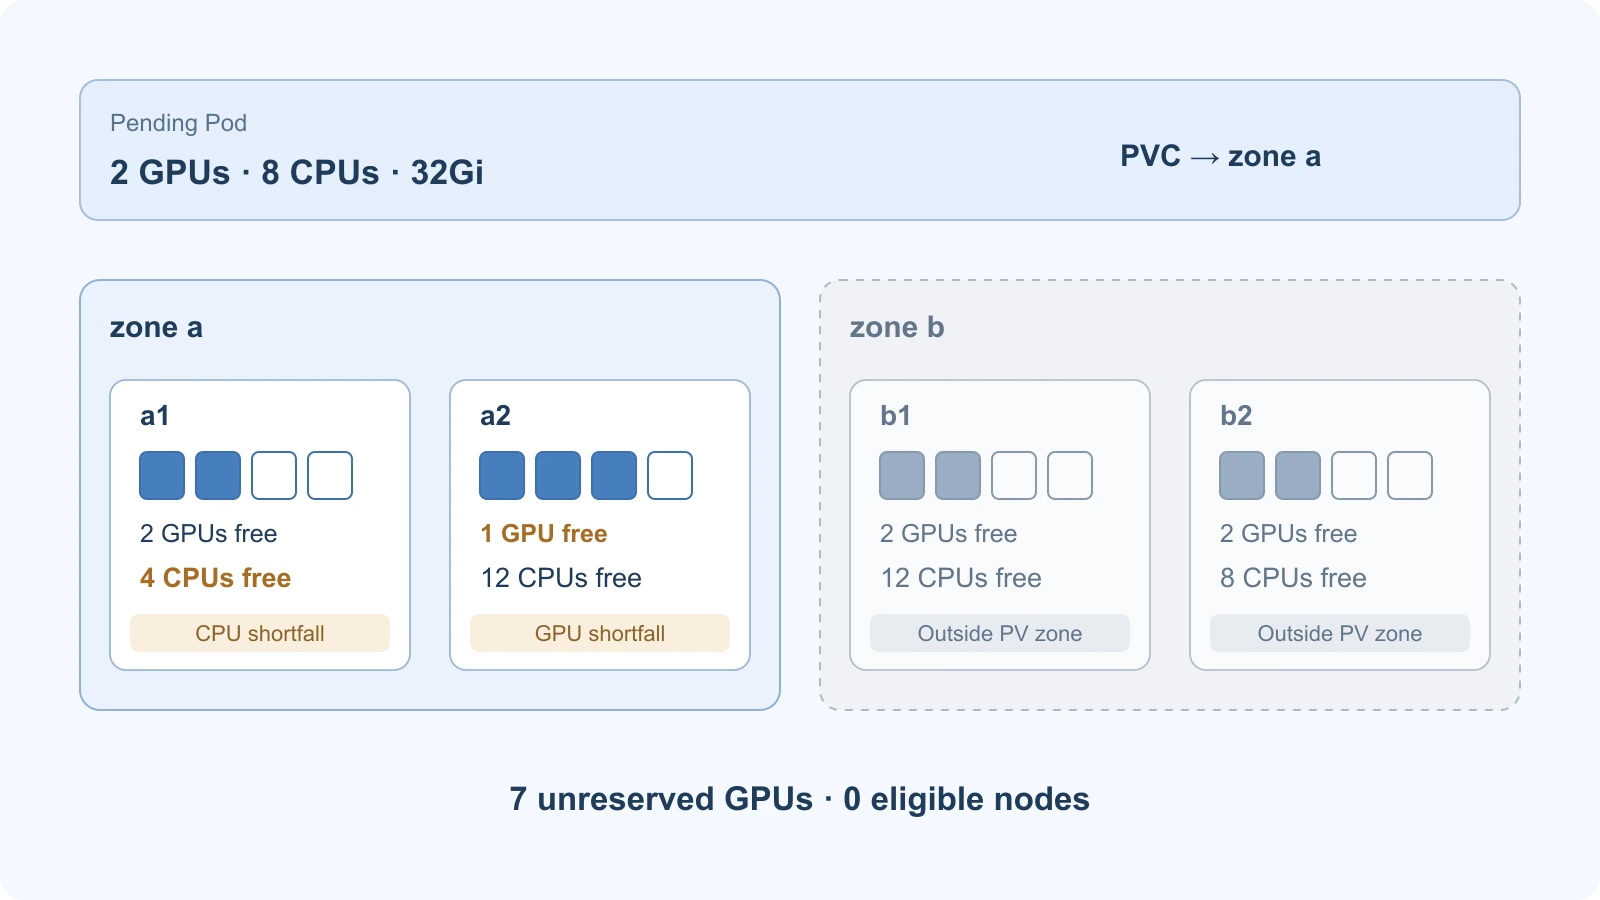
Work through a GPU placement case where available devices, CPU reservations, and volume topology leave no eligible node.
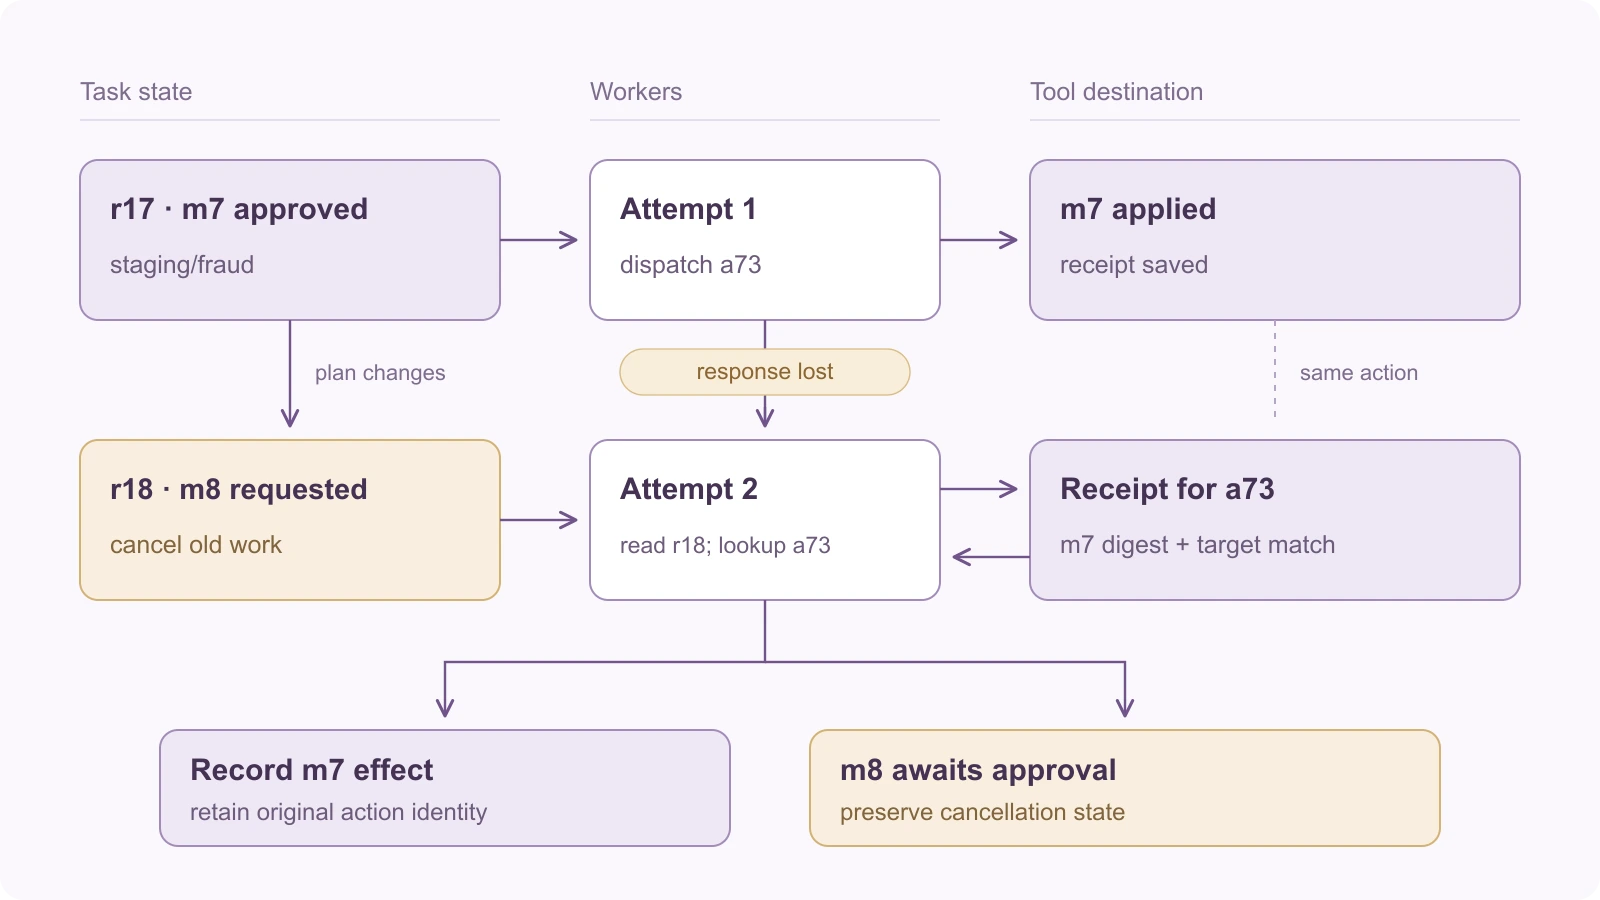
Reconcile uncertain tool effects, preserve approval and cancellation across task changes, and compare recovery policies using final-state evidence.
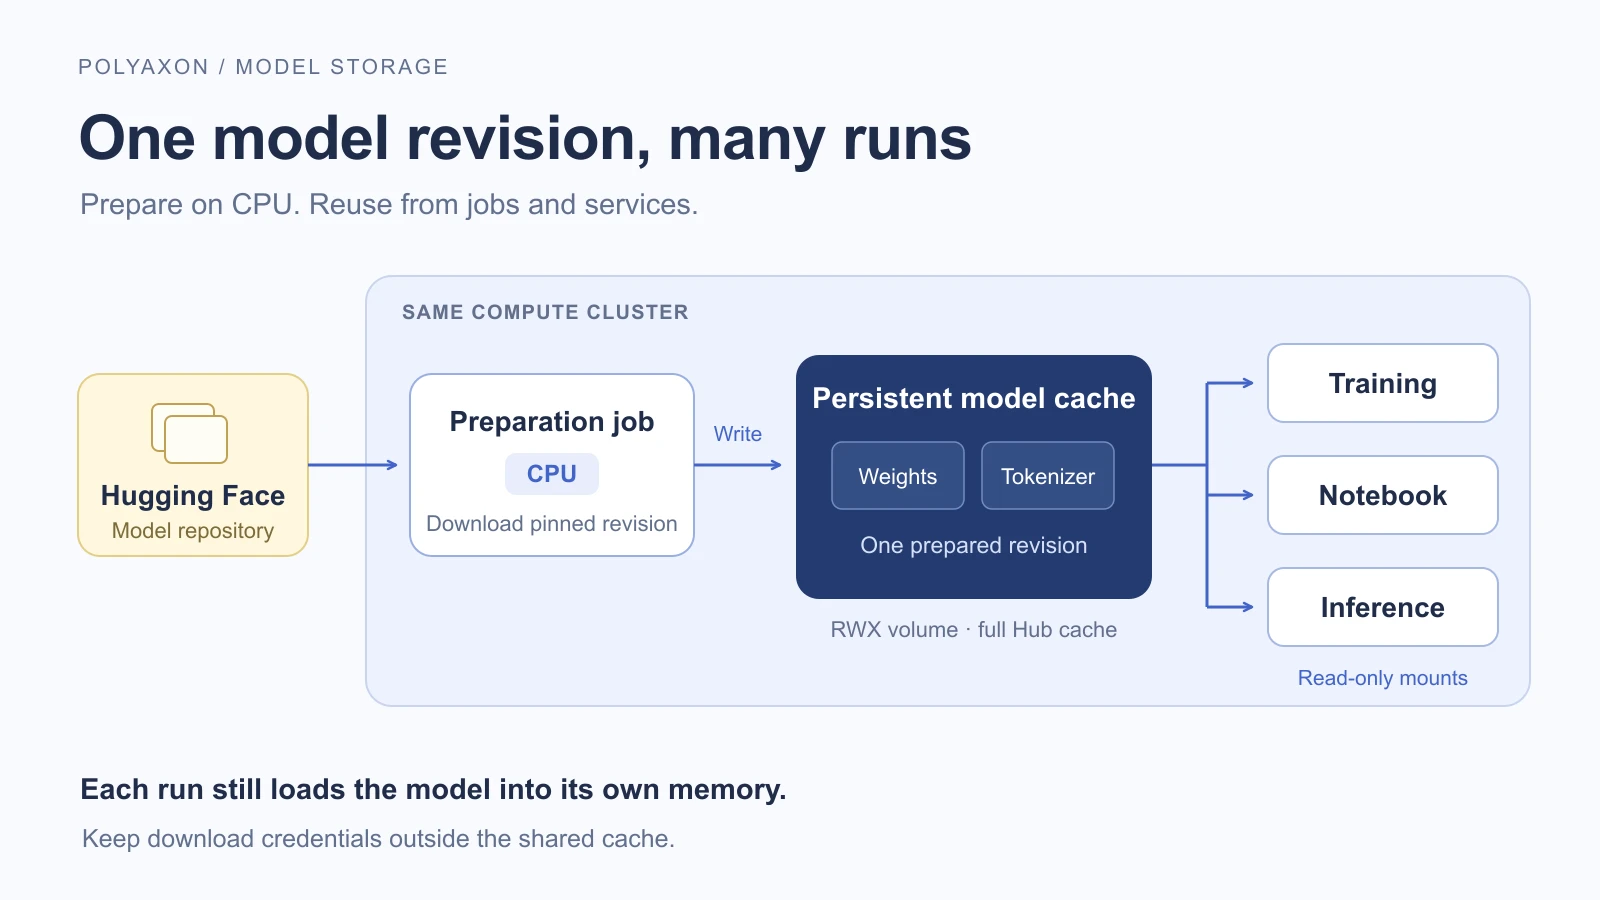
Prepare a pinned model revision in a CPU job, then reuse its files from read-only storage in Polyaxon training, notebook and inference workloads.
Set PyTorch CPU threads, DataLoader workers, and native-library thread counts together within a Kubernetes container's CPU budget.
Inspect /dev/shm, size DataLoader prefetching, and configure shared memory for PyTorch jobs on Kubernetes and Polyaxon.
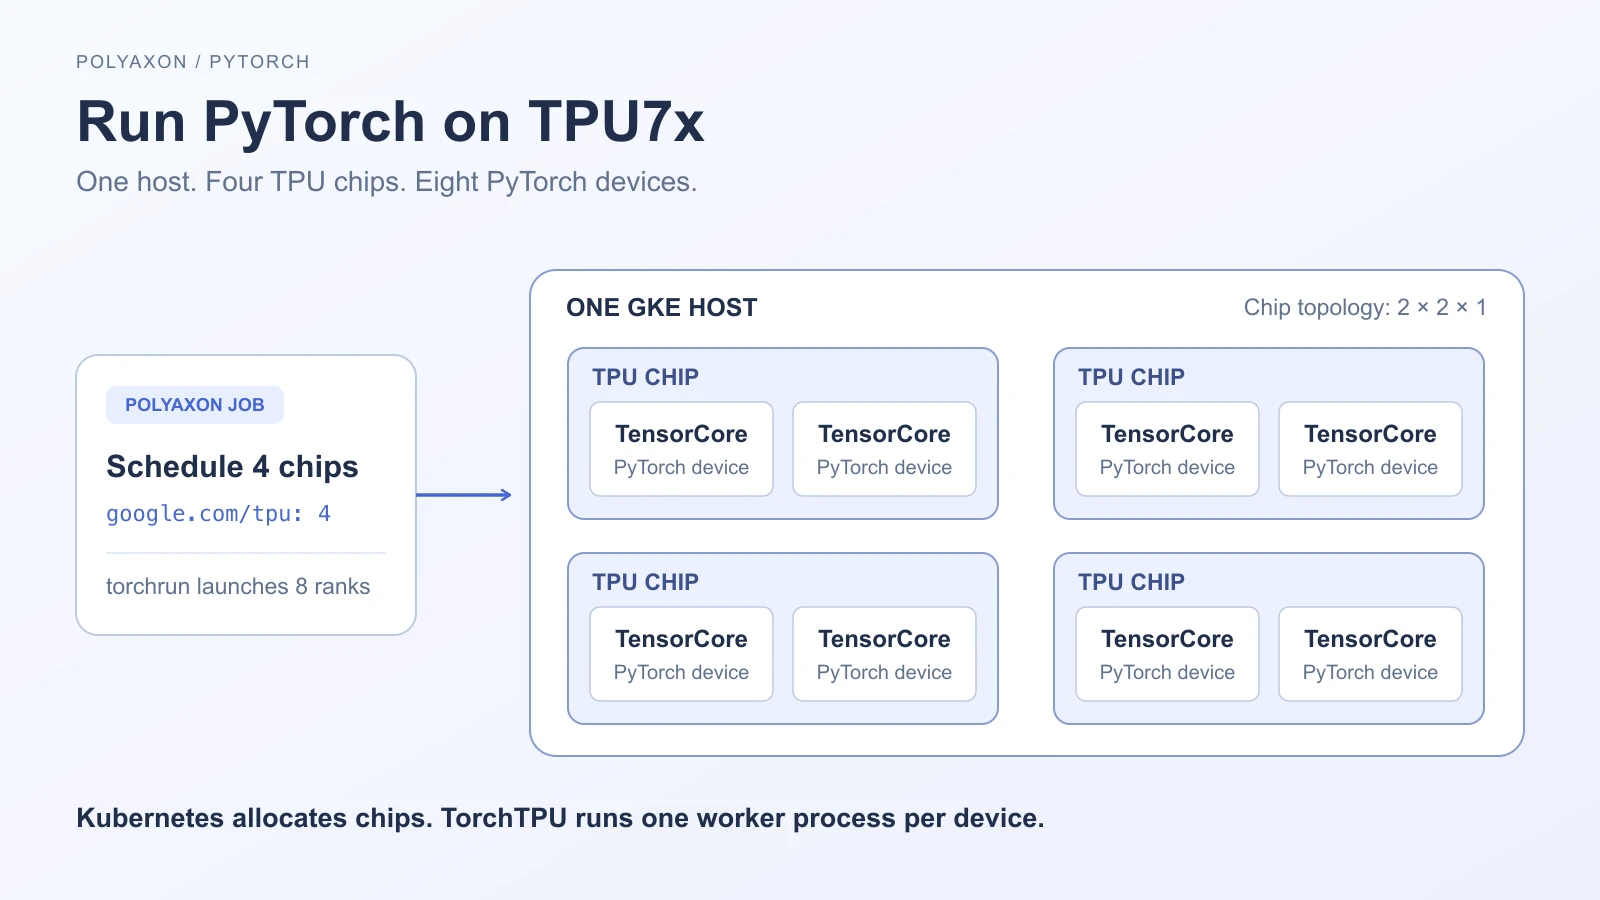
Deploy TorchTPU through a simplified Polyaxonfile, train with eight PyTorch workers on four TPU7x chips, and track metrics and model weights.
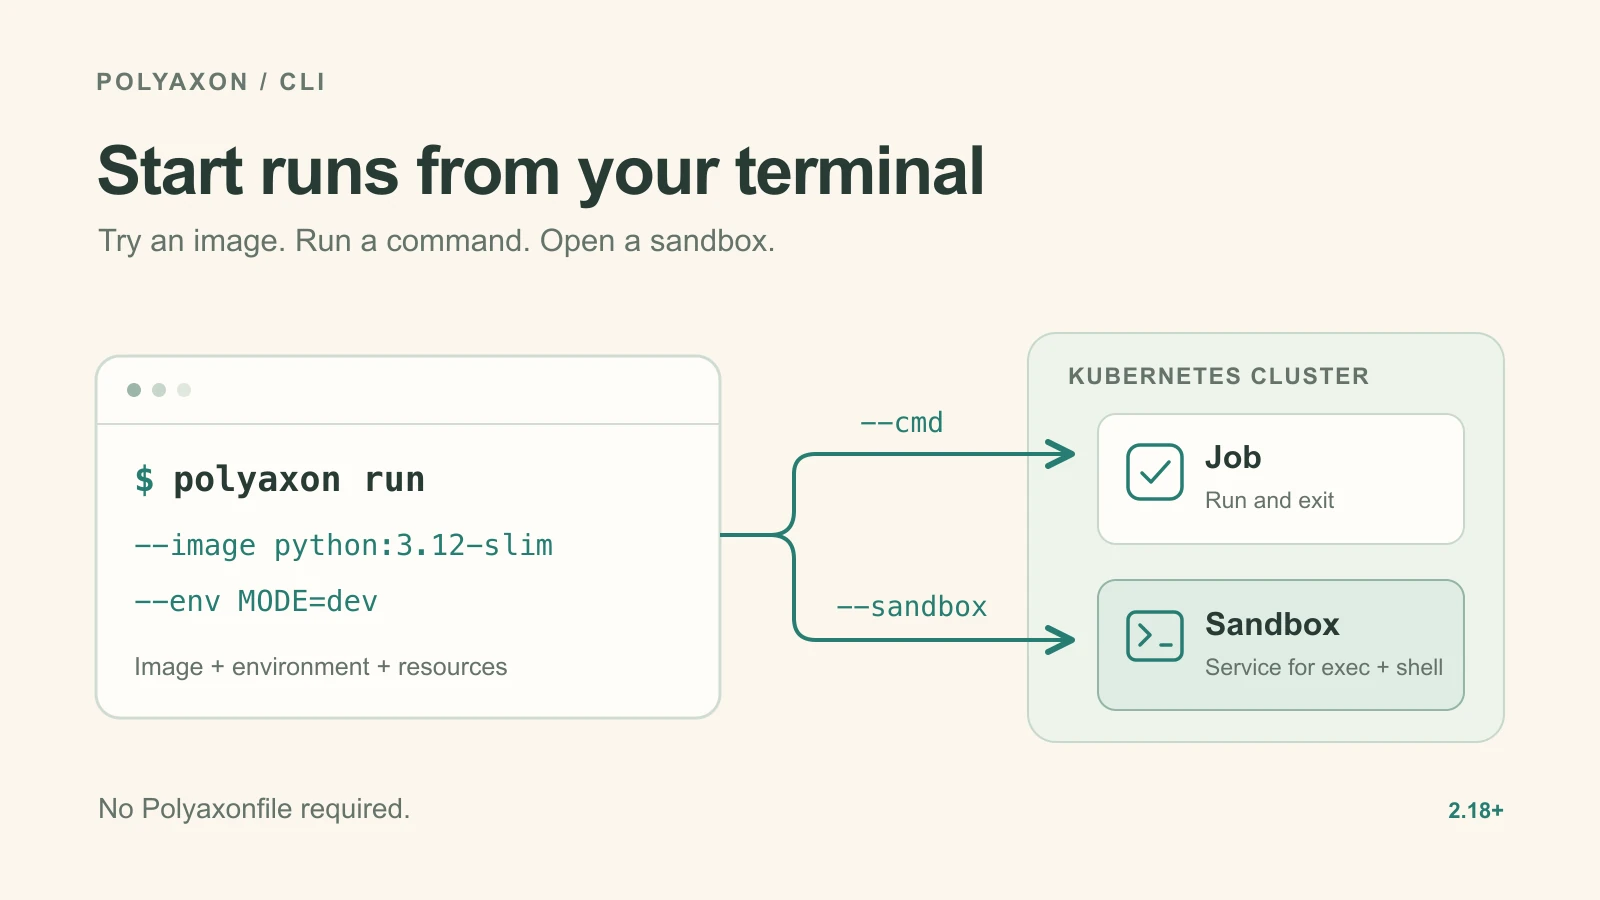
Try container images, package versions and environment changes from the Polyaxon CLI, or start a sandbox without writing a Polyaxonfile.
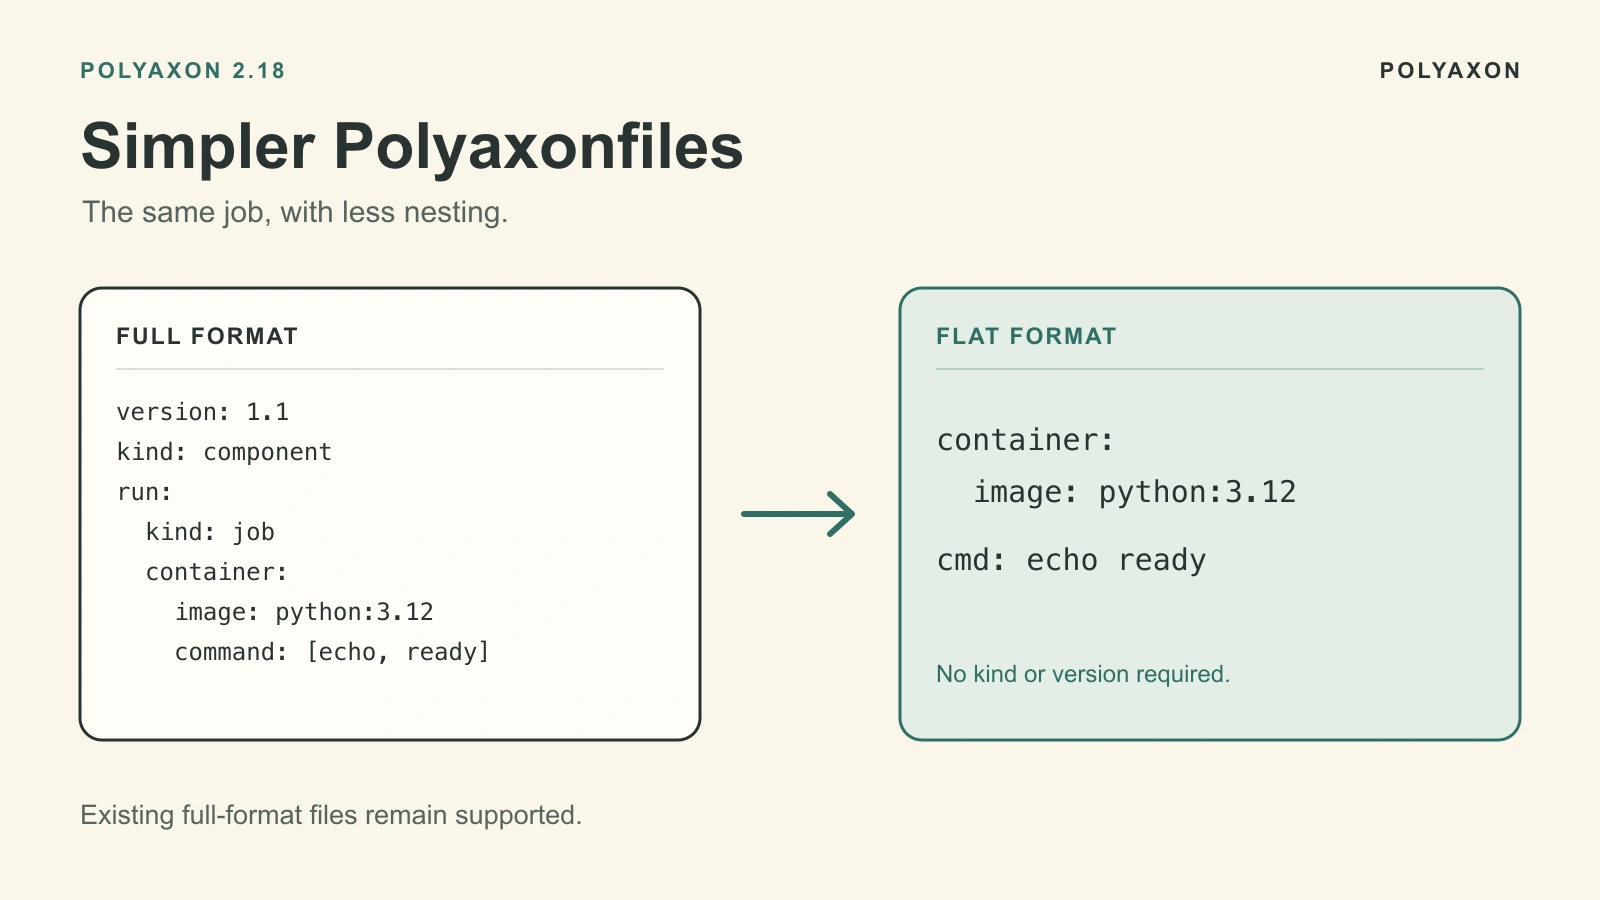
Define jobs and services with top-level container, cmd, env, resources, and service in Polyaxon 2.18, while keeping existing Polyaxonfiles supported.
Use Kubernetes Job TTLs to bound finished workload retention, preserve logs and artifacts separately, and configure the same policy through Polyaxon.
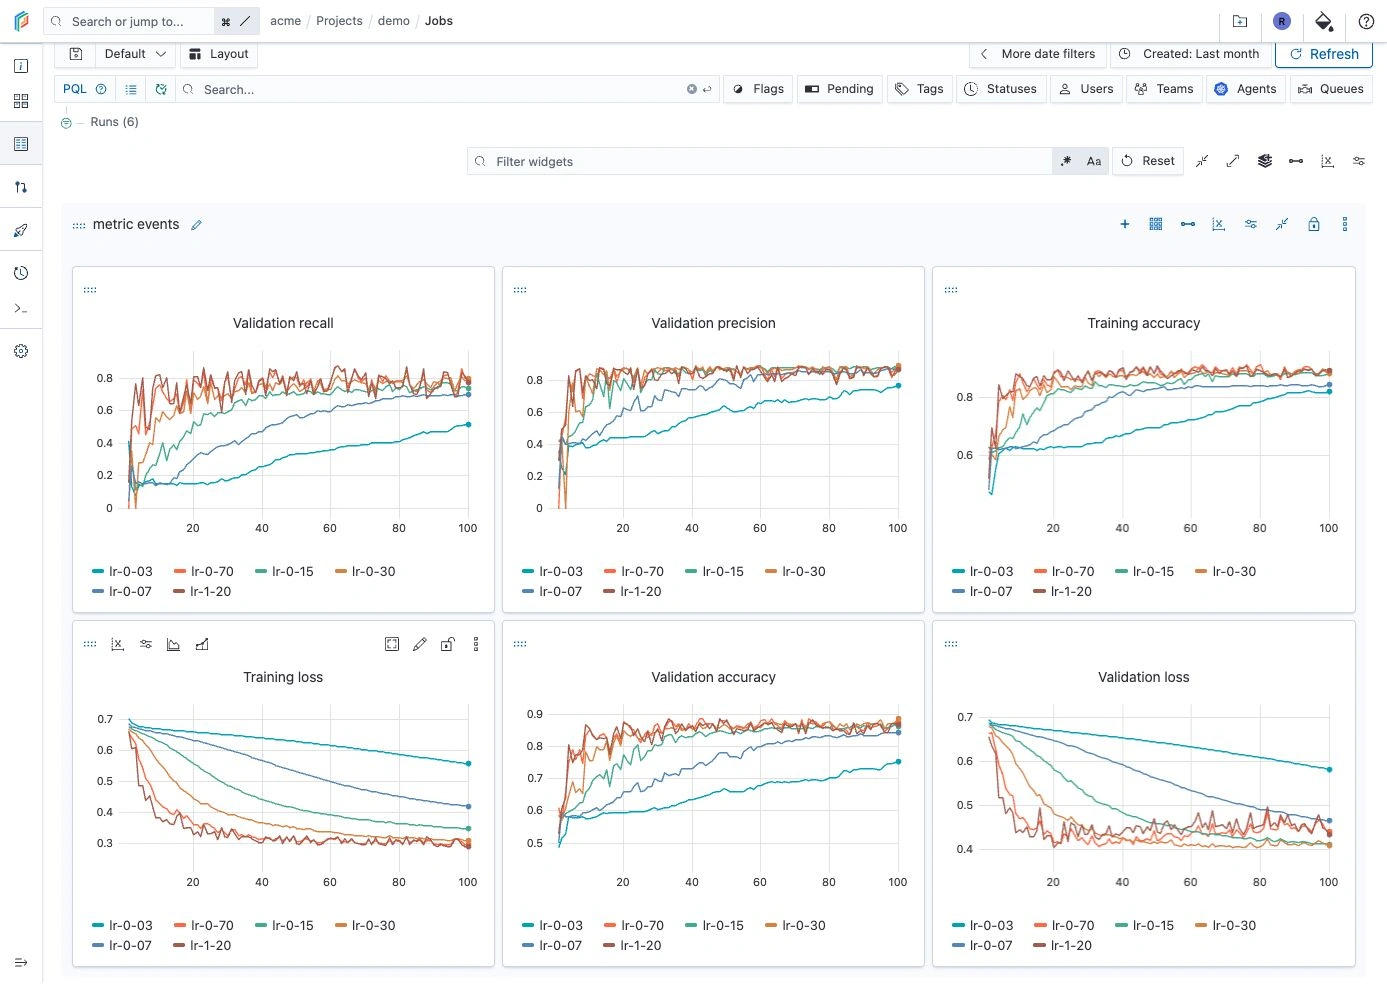
Compare six experiments at the same epoch, zoom across metric charts together, and configure tooltips with multiple live metric columns and run parameters.
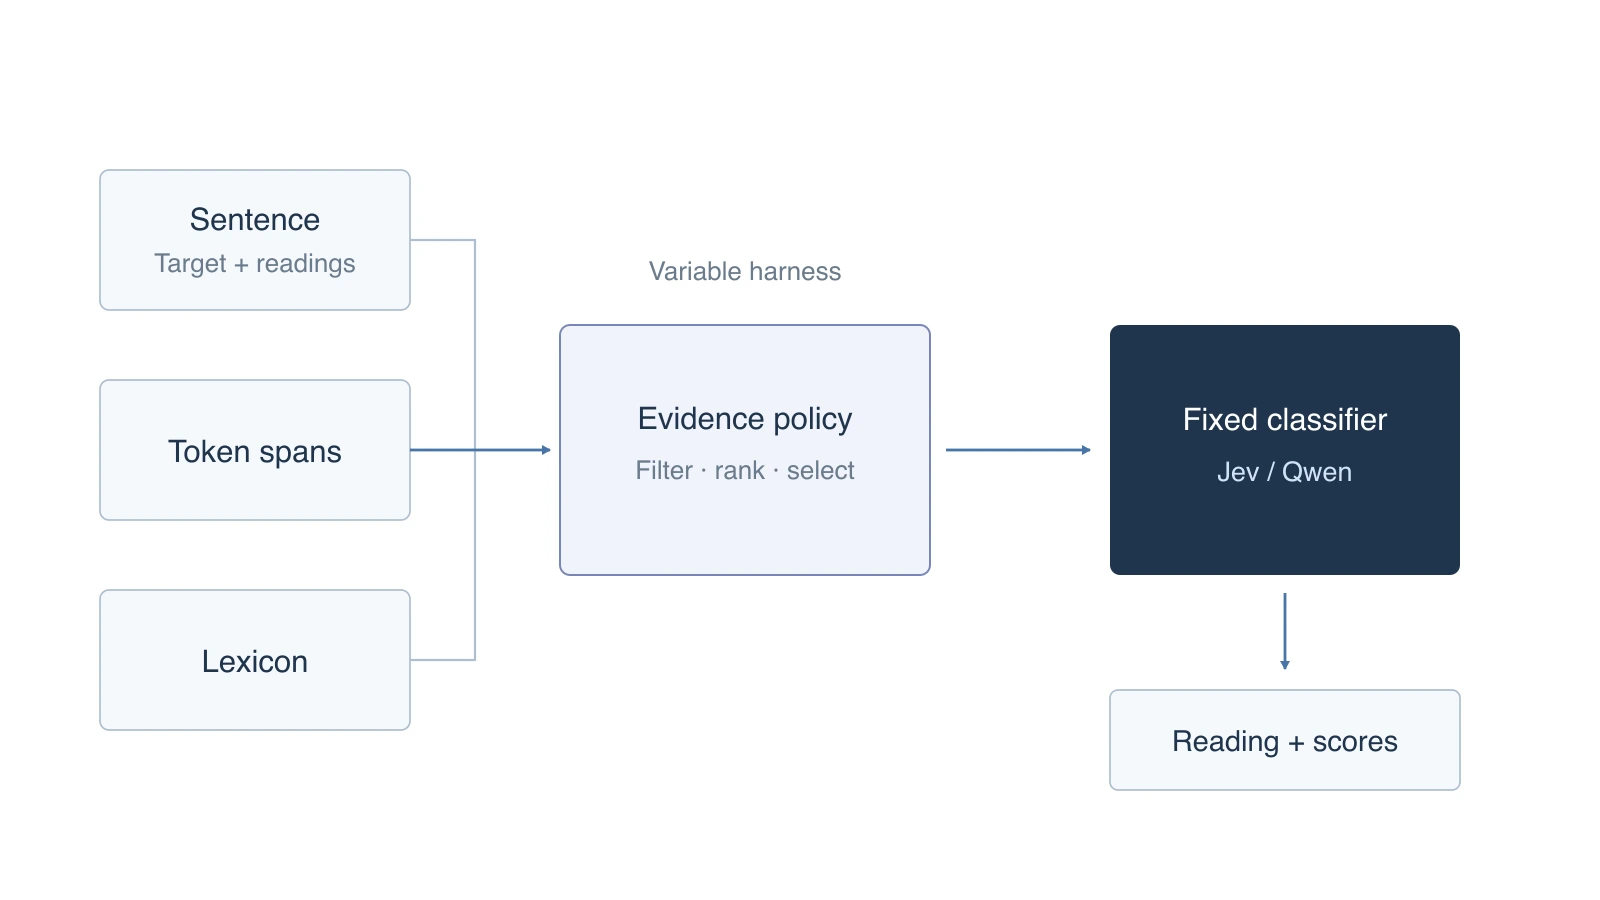
Build a measured research loop around Jev or a self-hosted classifier using Polyaxon jobs, sandboxes, experiment matrices, and per-case evidence.
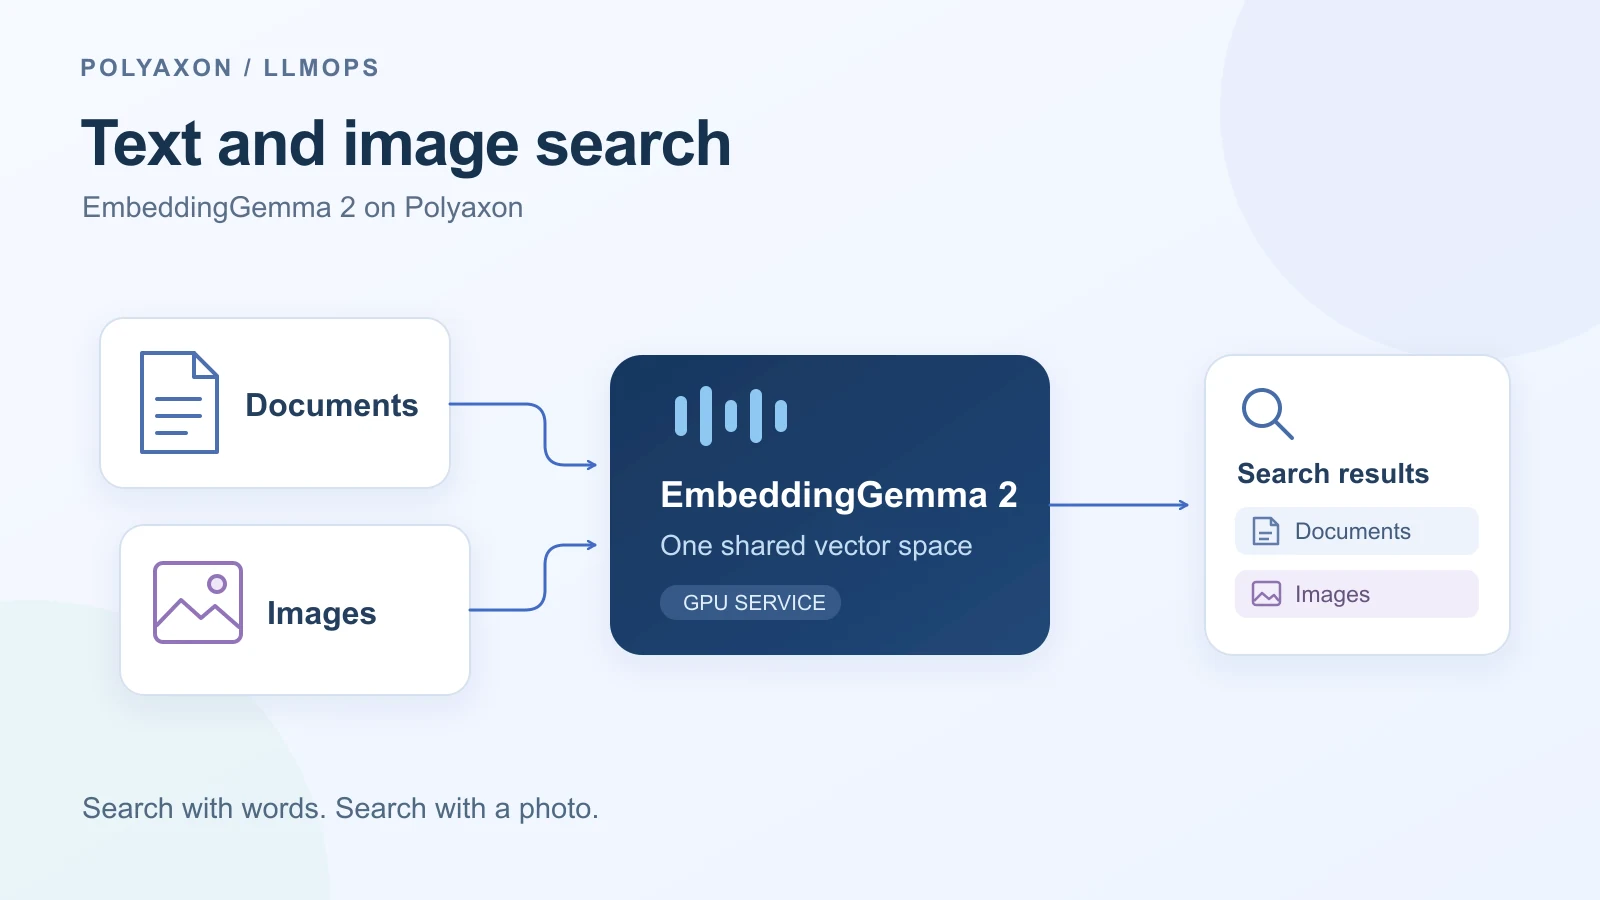
Deploy EmbeddingGemma 2 as a Polyaxon GPU service, then use text or an image to search a mixed collection of documents and photos.
Use eStargz and containerd for lazy image pulls, then measure a Polyaxon GPU job through its first completed CUDA operation.
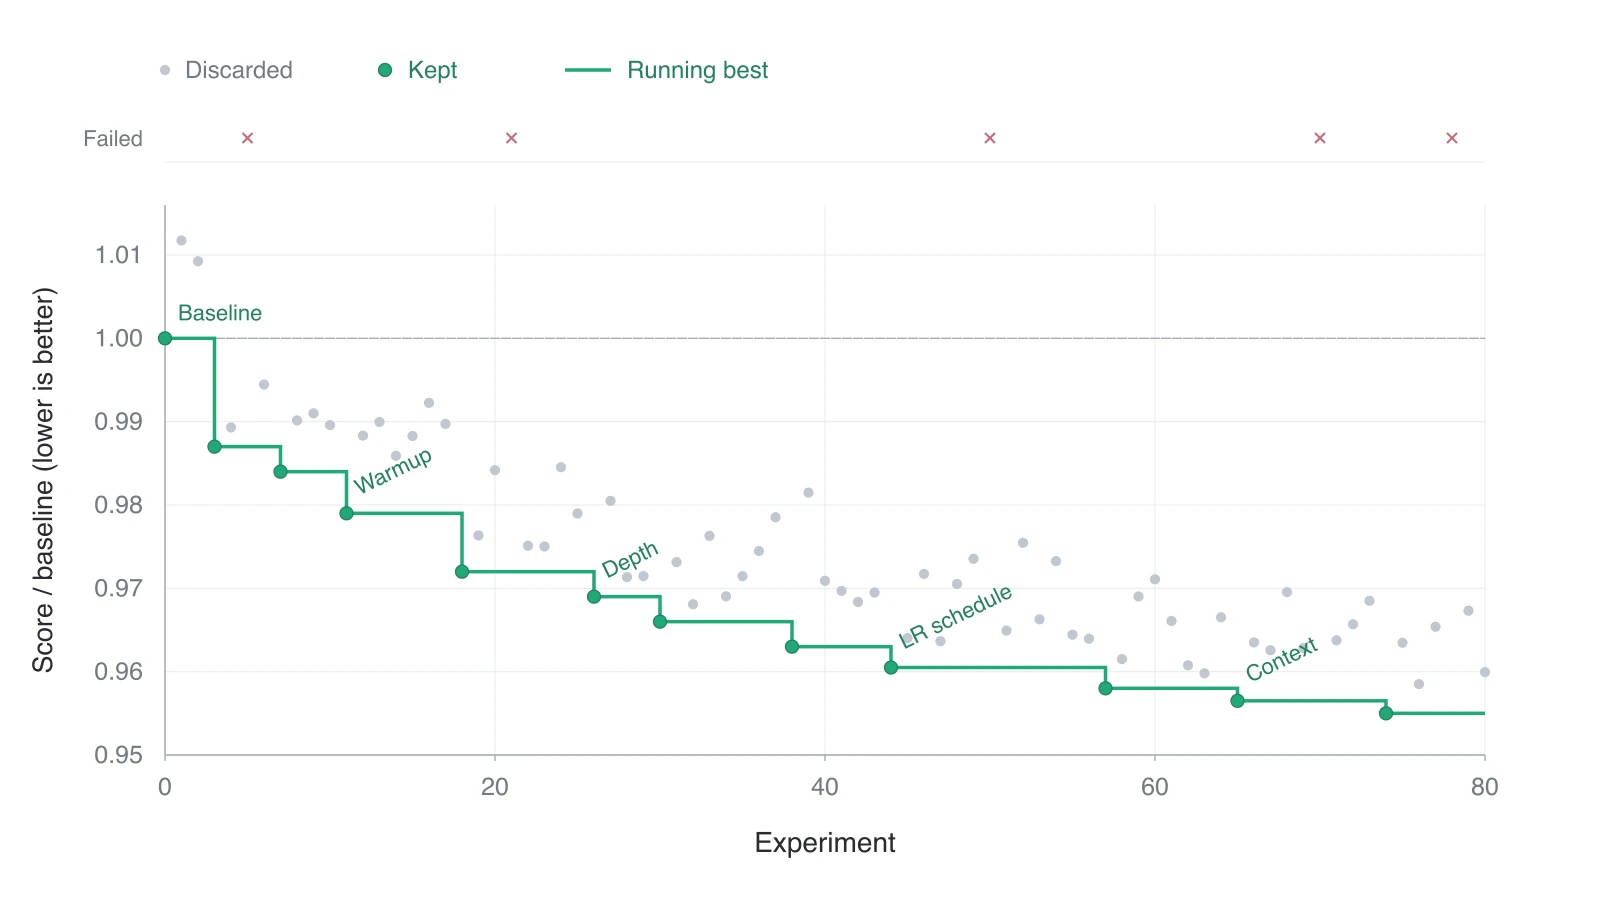
A design note on autonomous experimentation: fixed protocols, selection bias, independent evaluation, and durable research campaigns in Polyaxon.
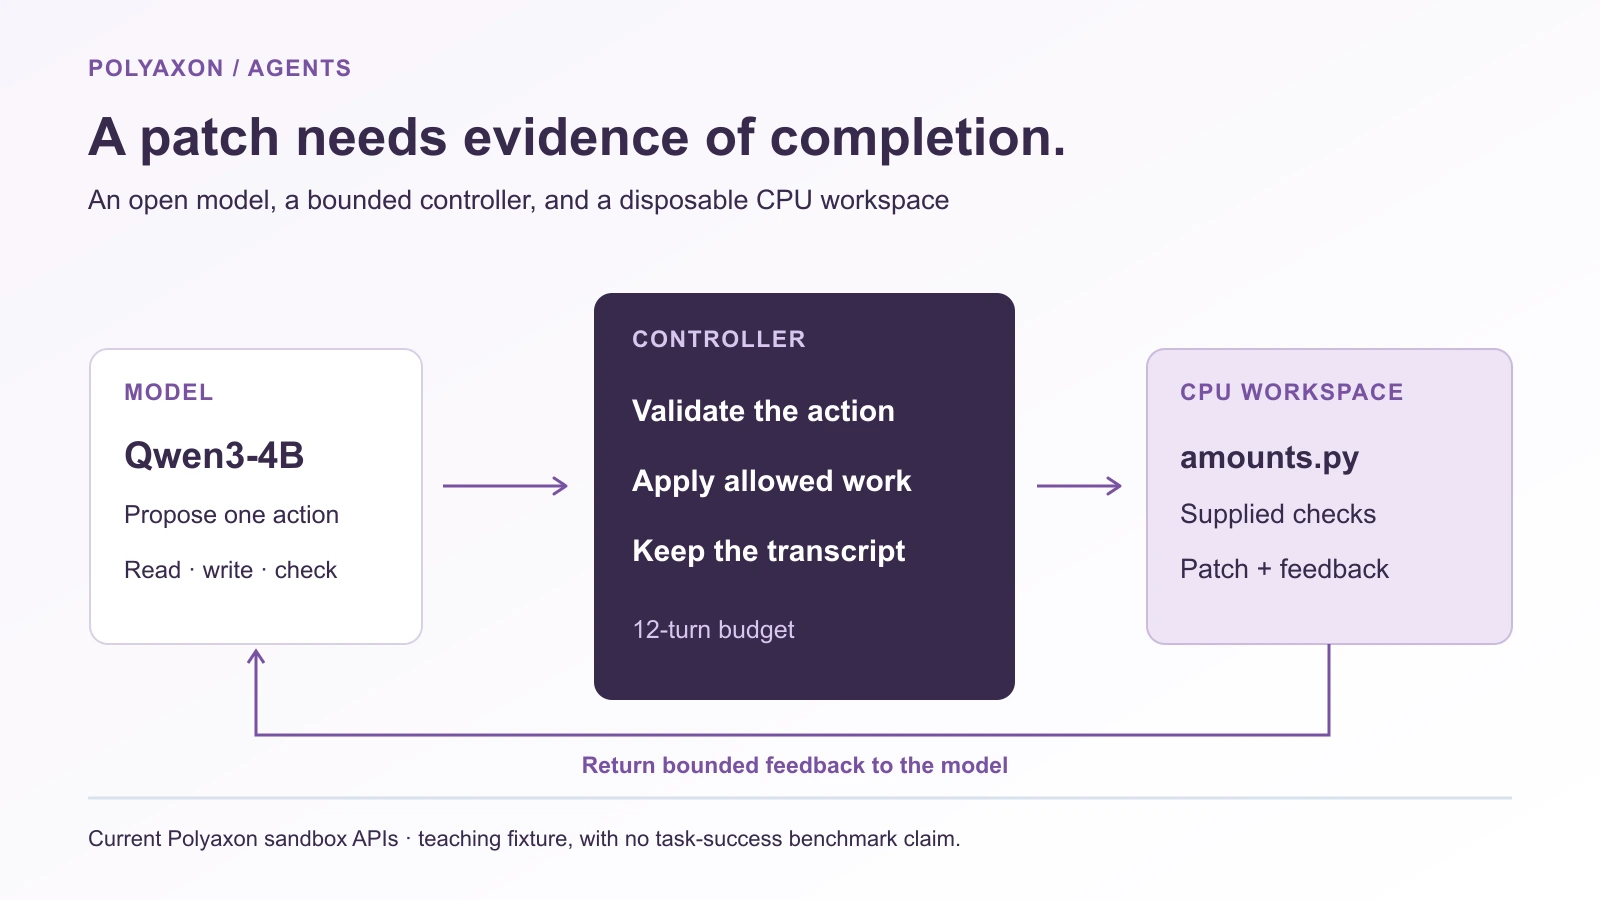
Give an open model a bounded read, edit, and check loop in a Polyaxon workspace, then retain the patch and evidence behind its completion claim.
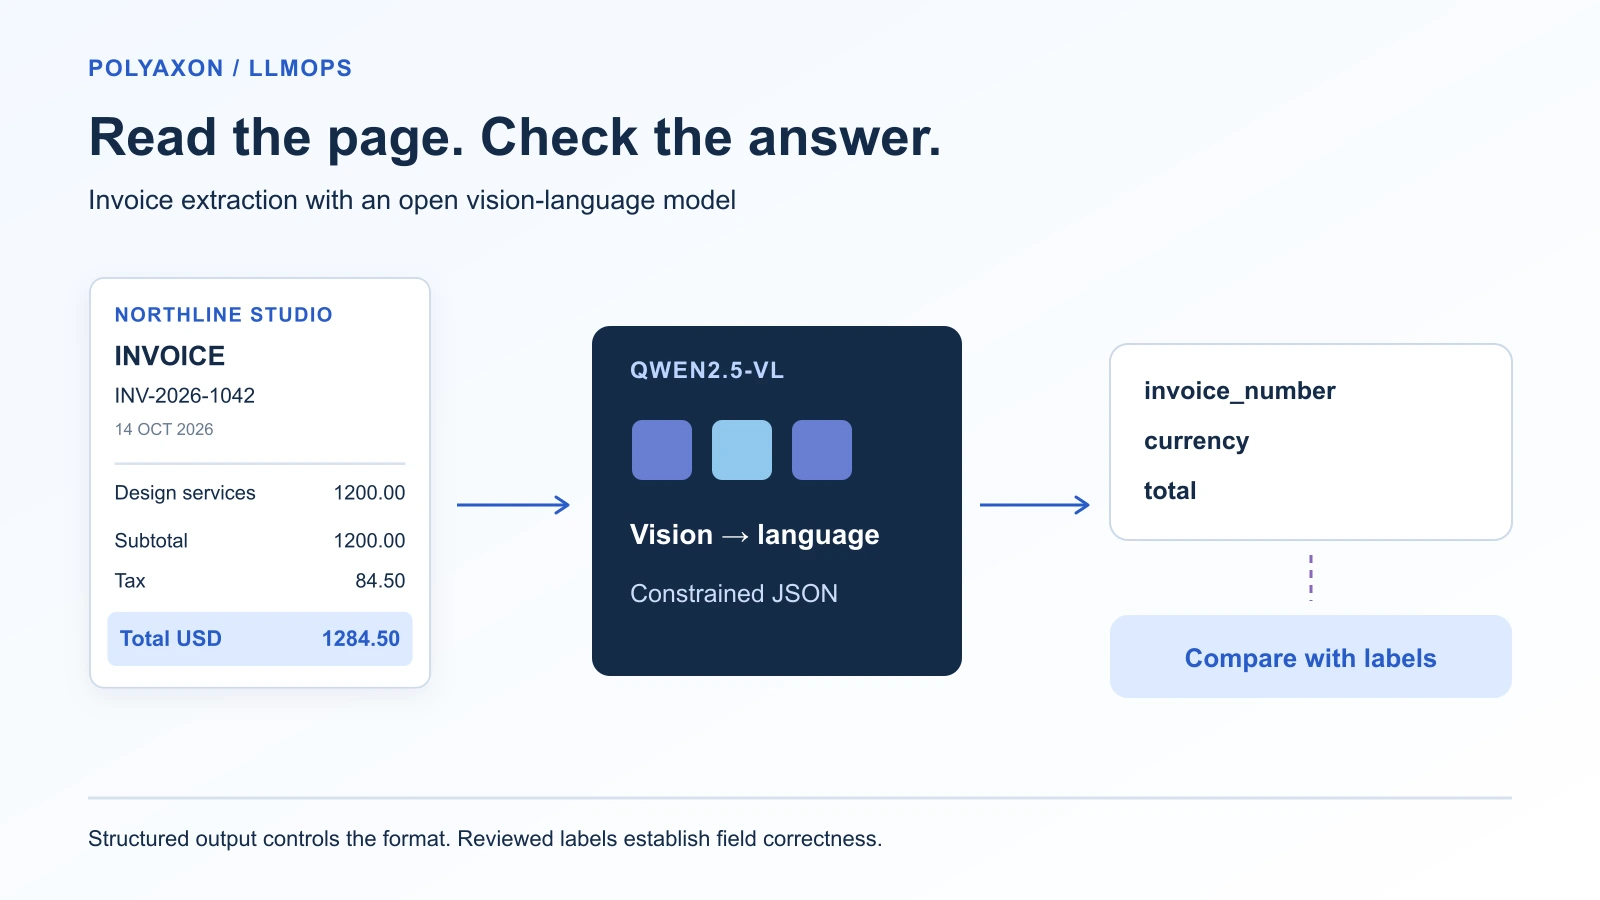
Serve an open vision-language model on your GPU cluster, extract typed invoice fields, and evaluate whether the values actually match the document.
Run synchronized training and inference workers on Polyaxon, compare MIG with time-slicing, and measure the shared interval rather than misleading solo utilization.
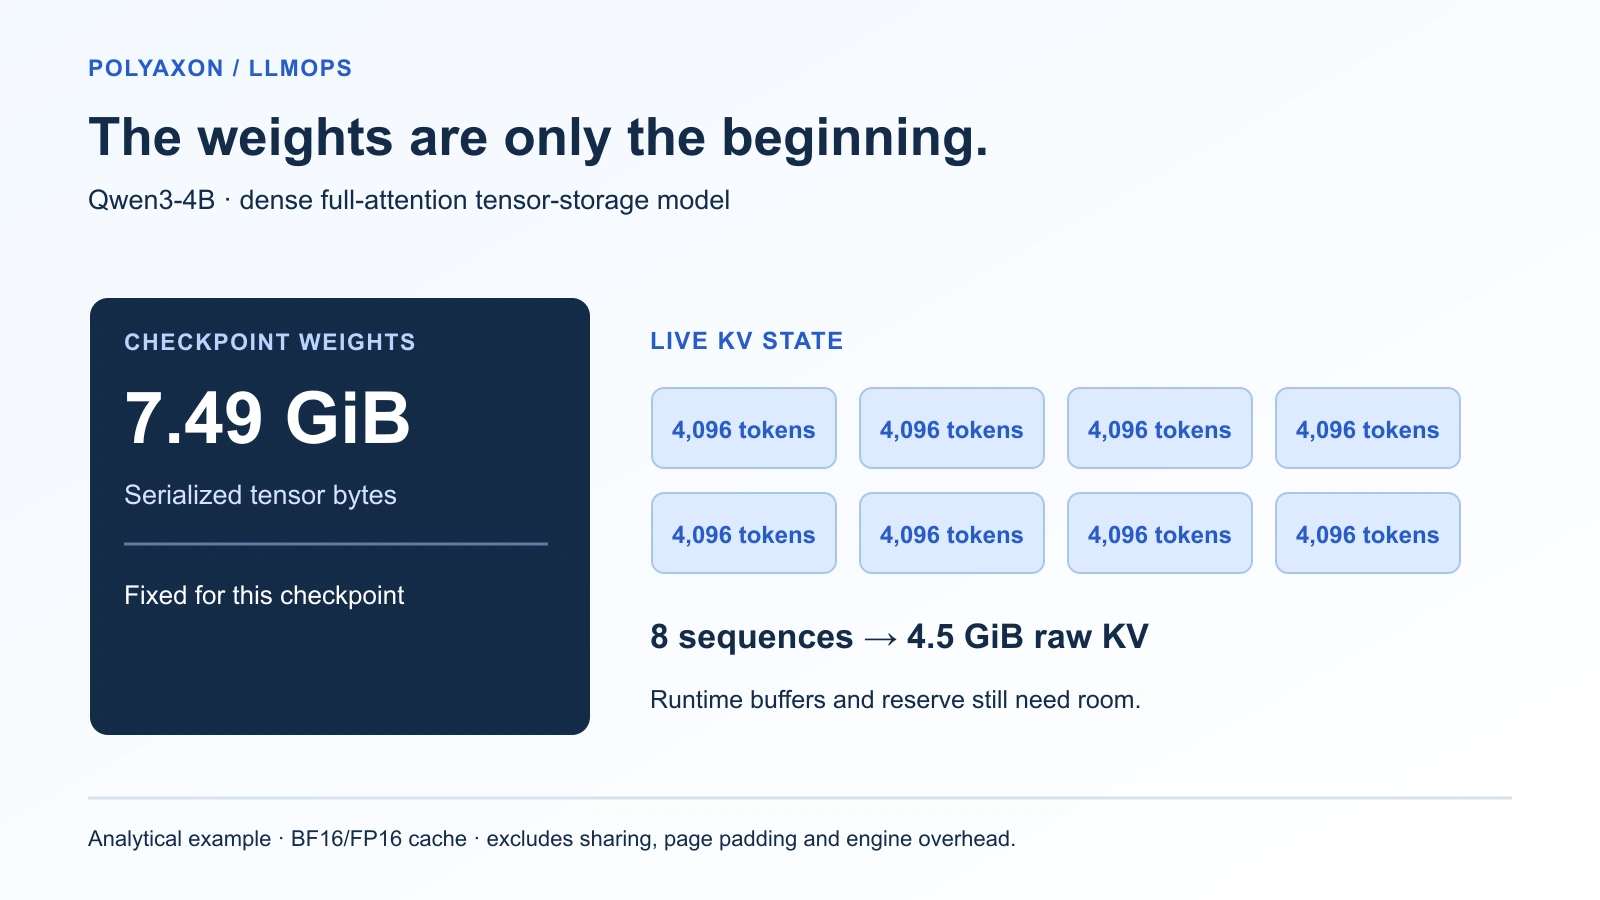
Calculate Qwen3-4B weight and KV-cache storage, understand what the estimate excludes, and use a Polyaxon service to check the actual capacity.
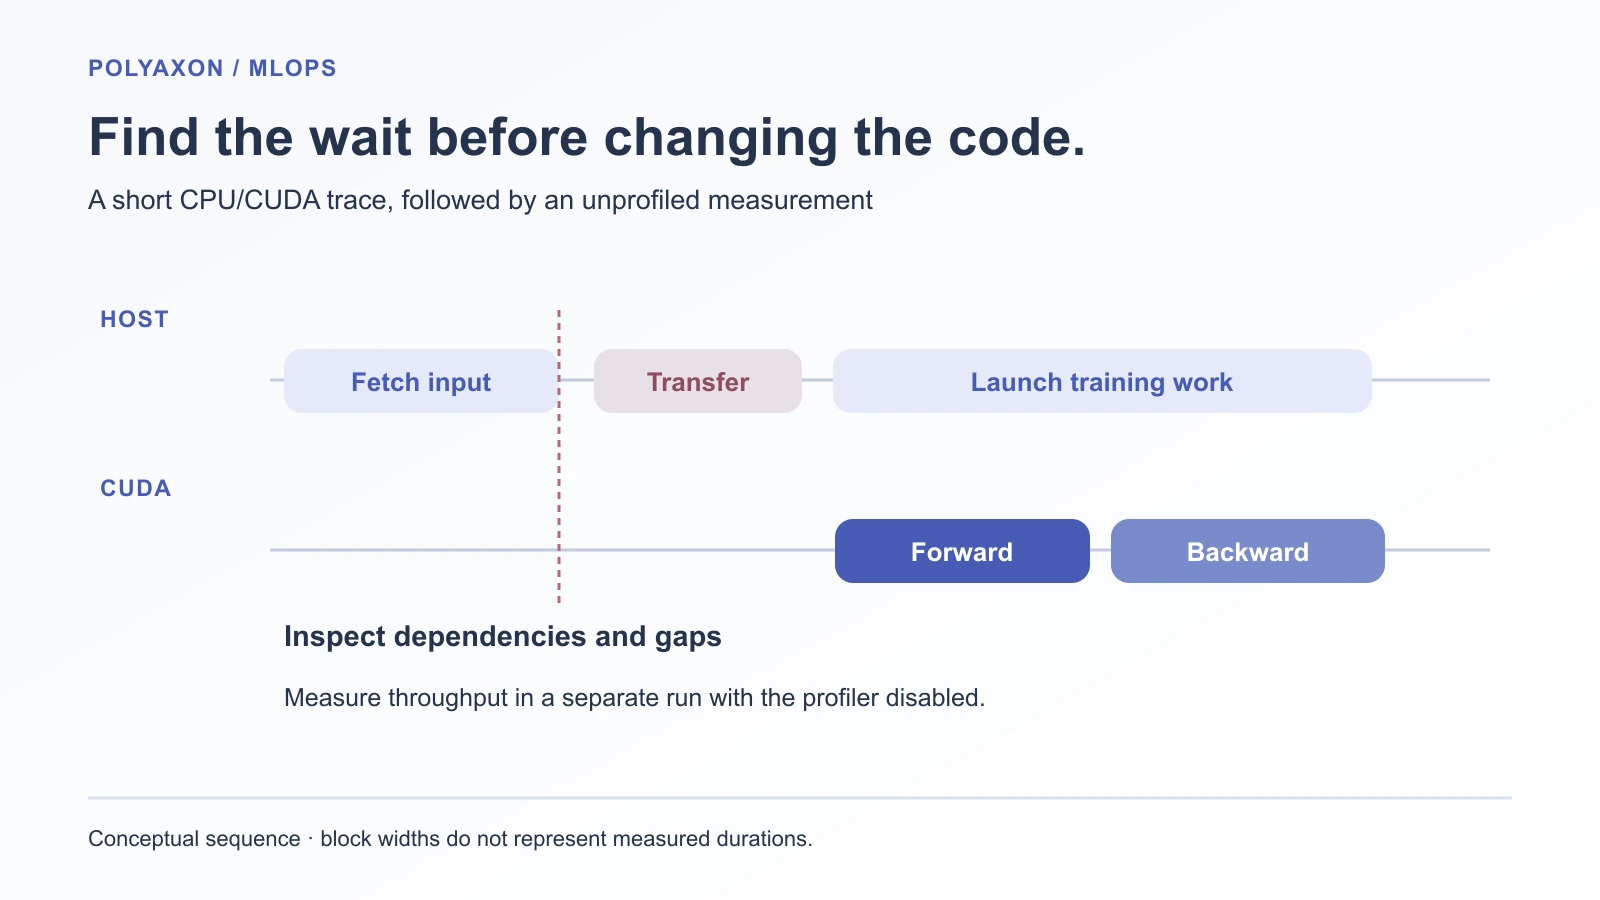
Capture a short CPU/CUDA trace, identify whether input loading or GPU work is delaying training, and measure a targeted change without profiler overhead.
Give urgent GPU evaluations or notebooks higher Kubernetes scheduling priority without evicting running training Pods, and select the policy in Polyaxon.
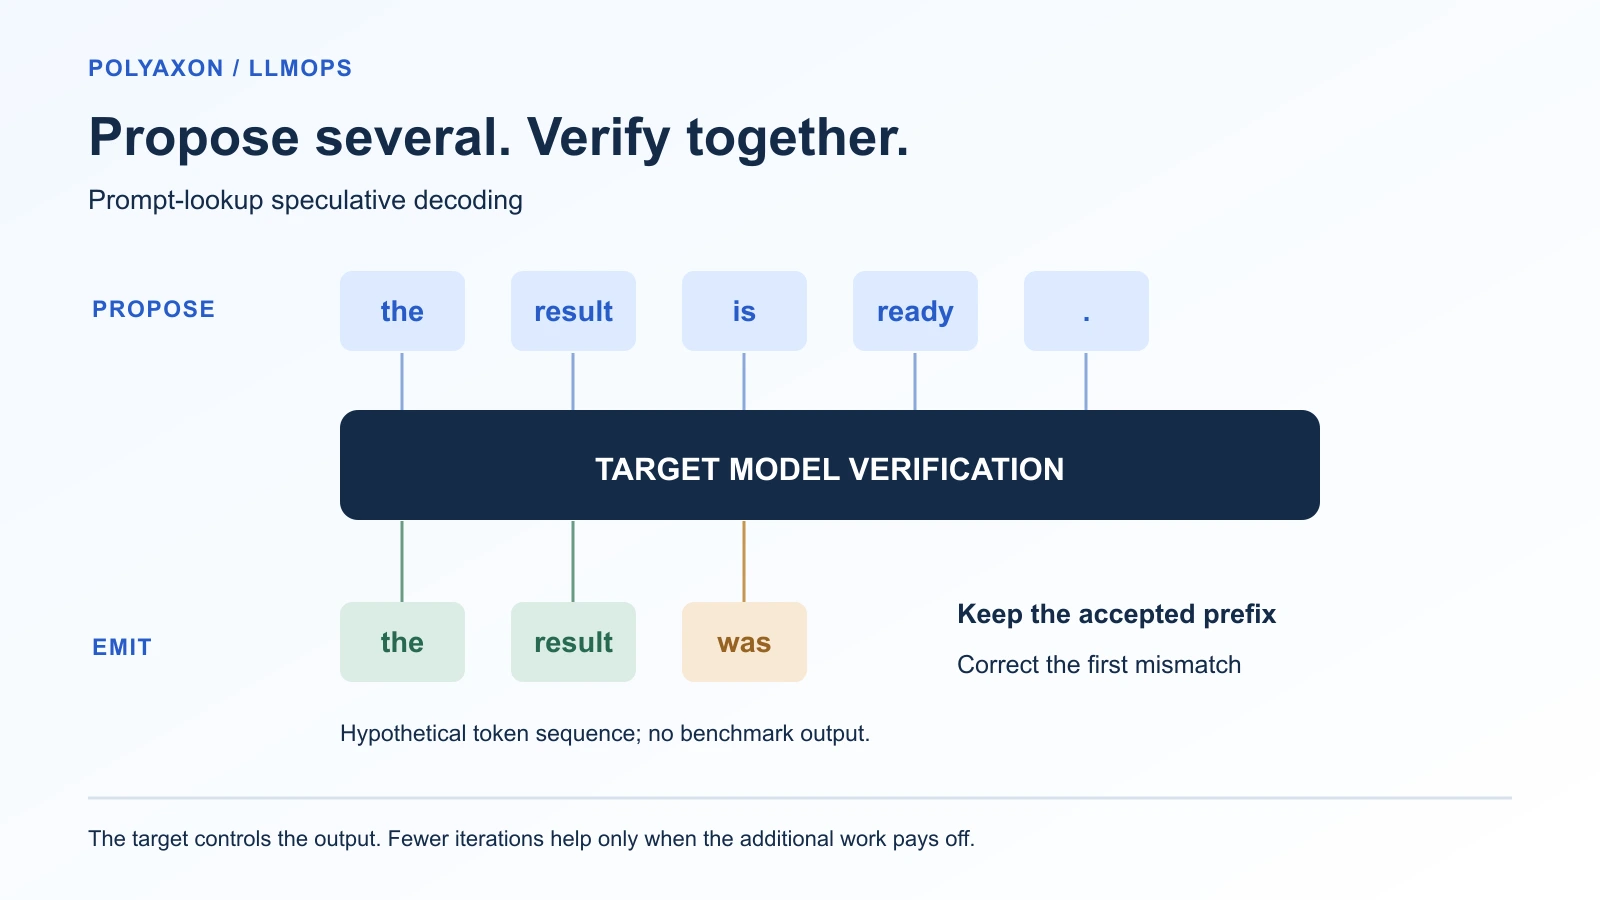
Compare ordinary decoding with prompt-lookup proposals under the same model, workload, and GPU allocation, including latency, failures, and output checks.
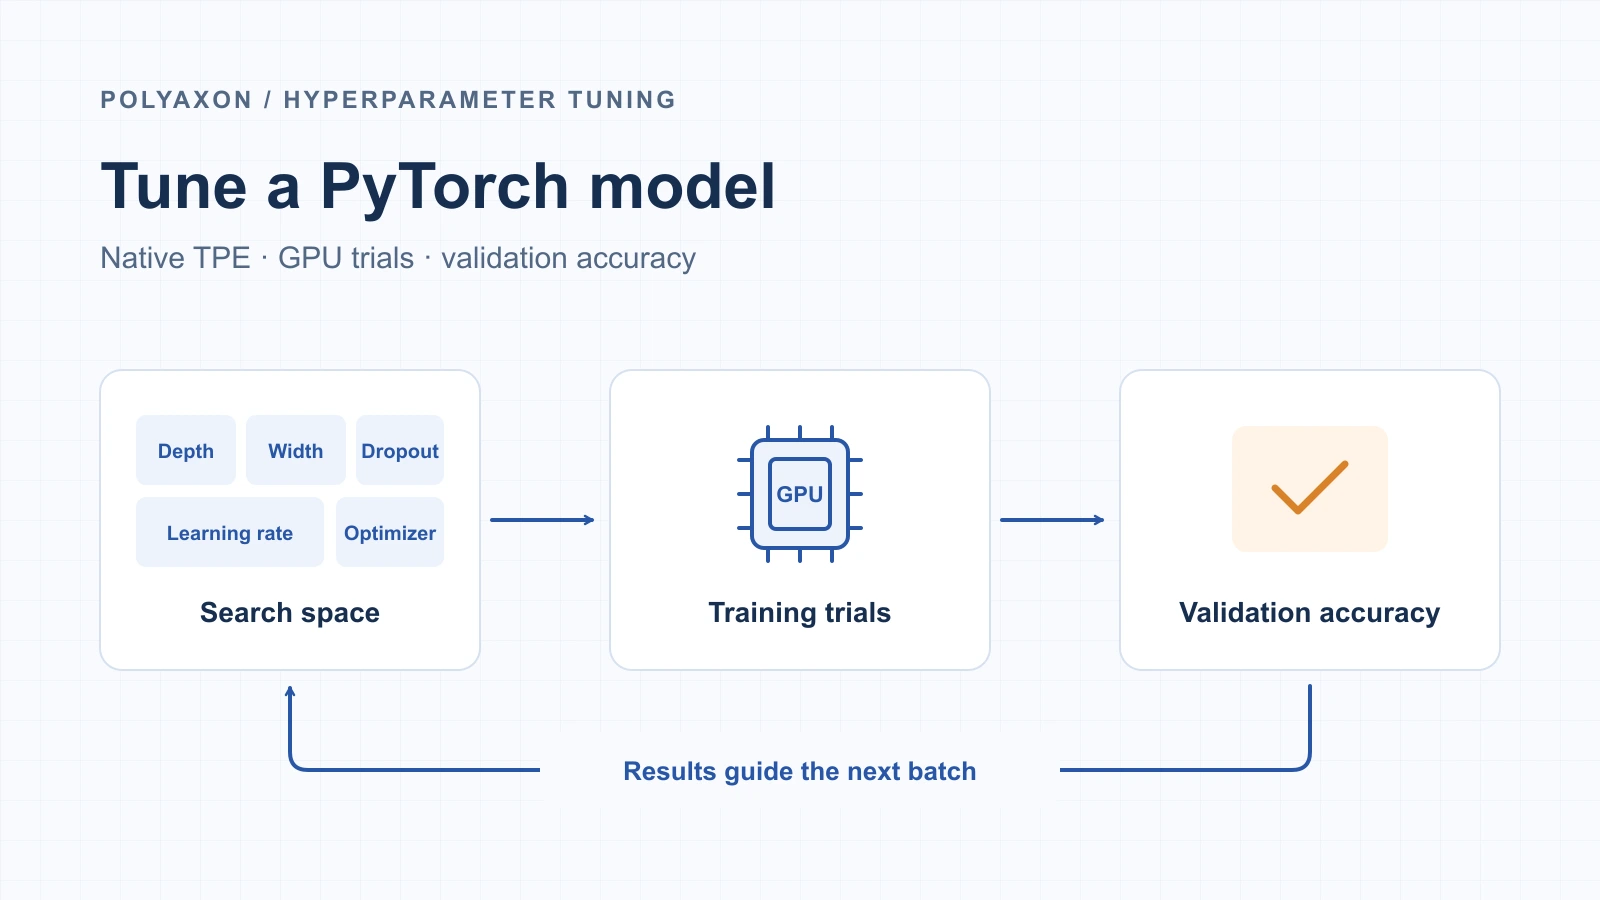
Tune a PyTorch model's depth, width, dropout, optimizer, and learning rate with native TPE, GPU trials, and validation accuracy in Polyaxon.