Blog
Practical guides to MLOps, Kubernetes, LLM applications, and AI agents. Follow a learning path or see the changelog for product release notes.
Keep inference available during Kubernetes node drains
Set a PodDisruptionBudget around usable inference capacity, inspect blocked evictions, and account for replacement GPUs and model warmup.
Sep 29, 2026
Polyaxon
KubernetesInference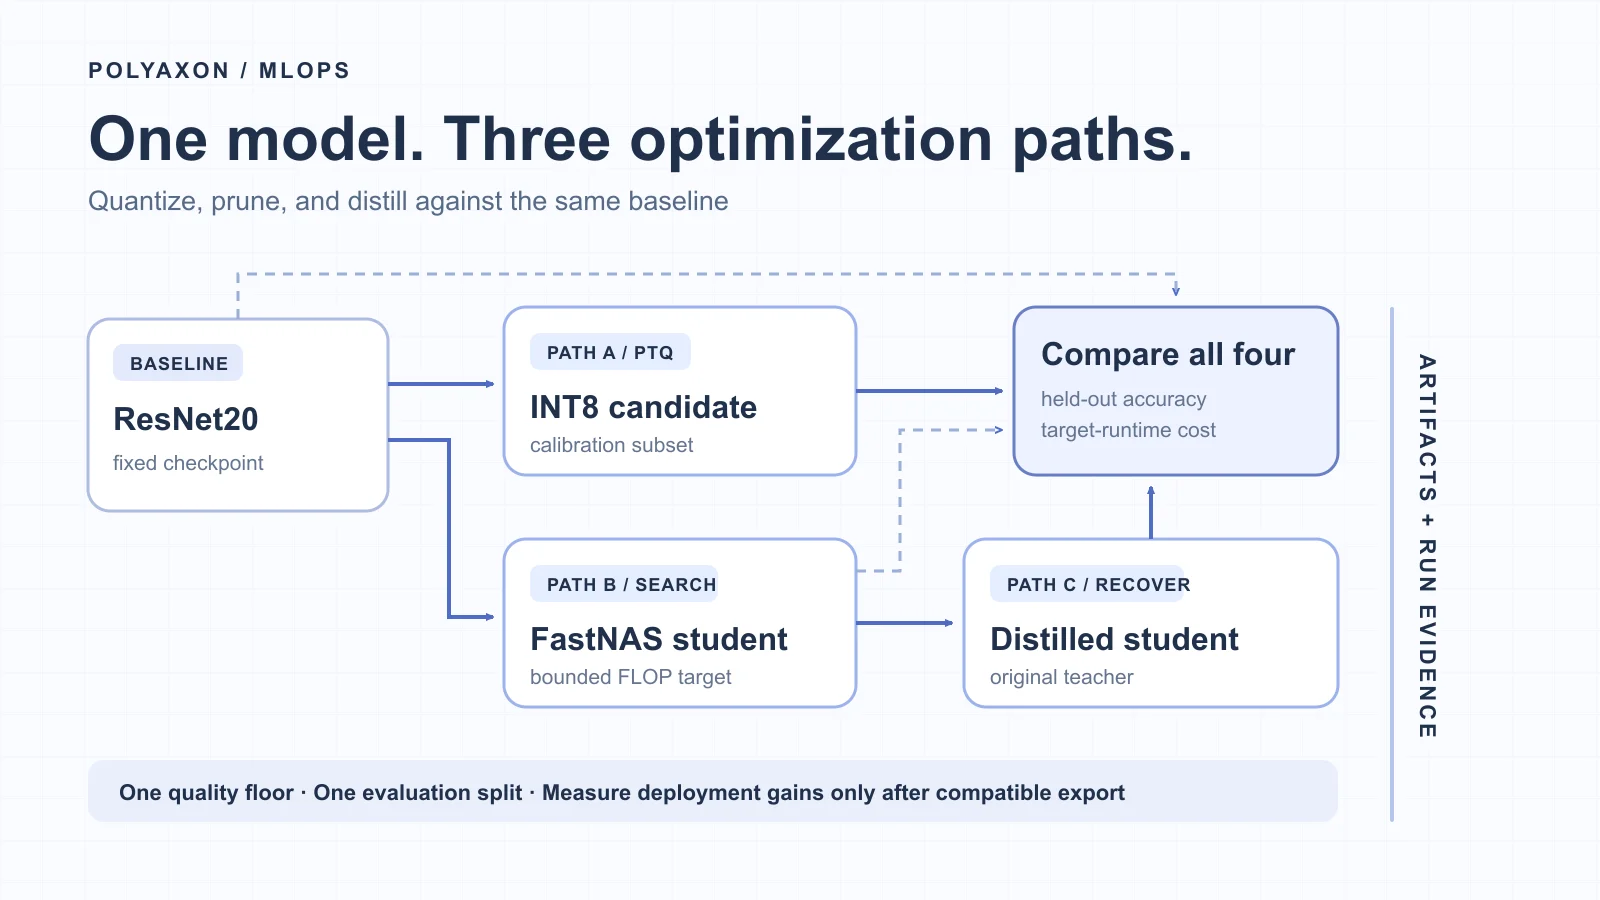
Optimize one model three ways with NVIDIA Model Optimizer on Polyaxon
Compare INT8 quantization, FastNAS pruning, and distillation against one tracked baseline, then measure the candidate that meets your accuracy floor.
Sep 28, 2026
Polyaxon
MLOpsModel optimization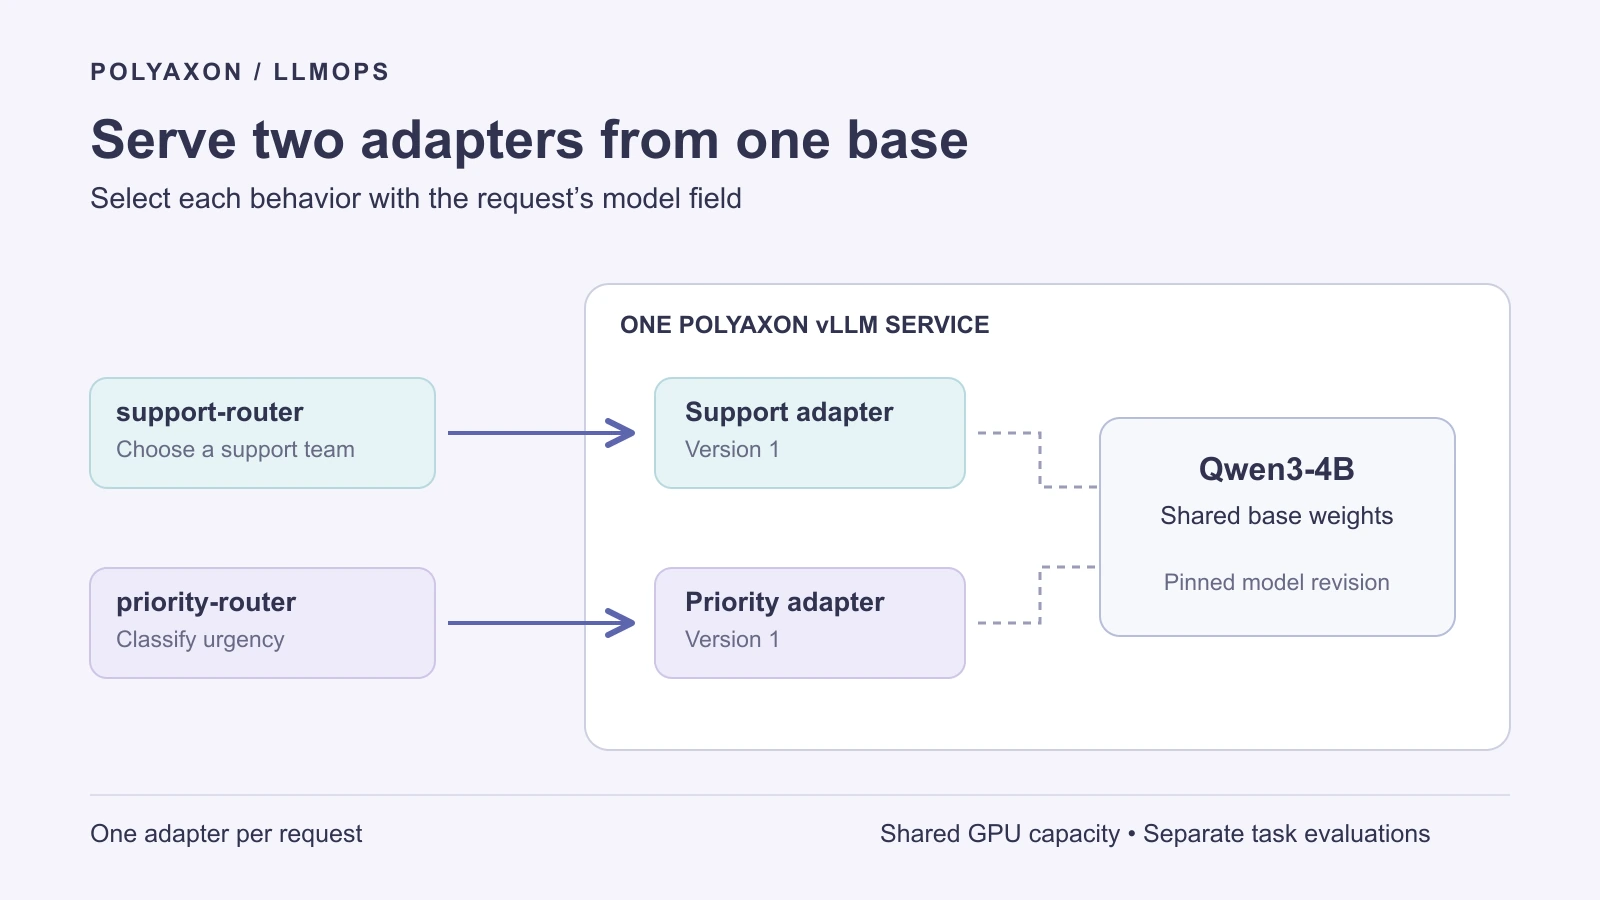
Serve multiple LoRA adapters with vLLM on Polyaxon
Deploy two task-specific LoRA adapters over one Qwen base model, select them by name, and measure quality and shared GPU capacity with Polyaxon.
Sep 27, 2026
Polyaxon
LLMOpsVllm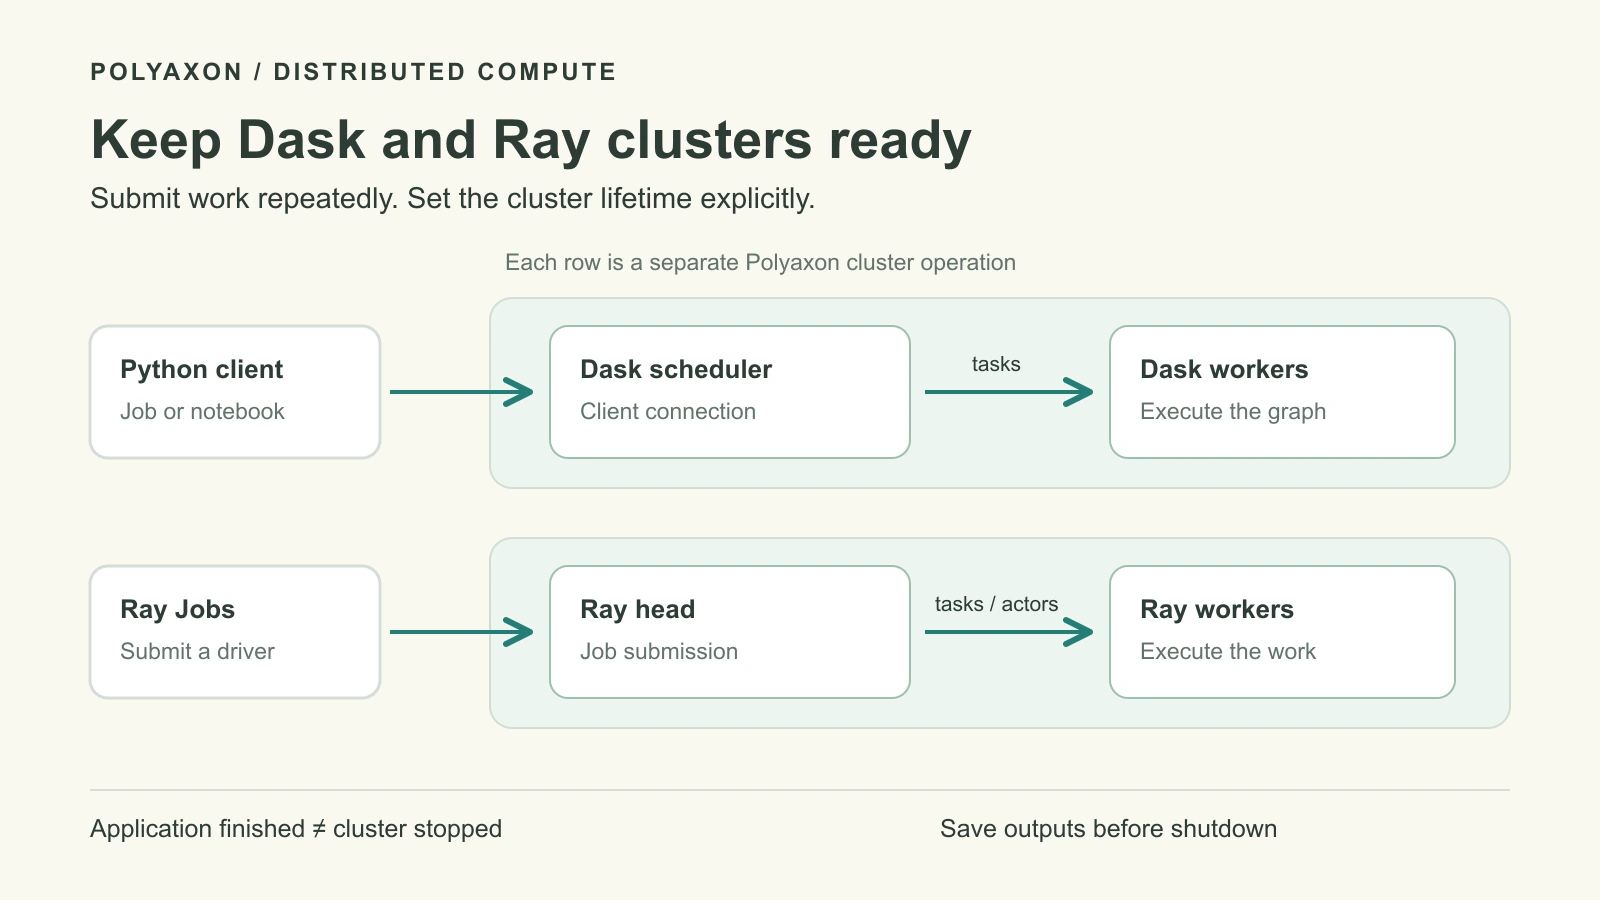
Run persistent Dask and Ray clusters on Polyaxon
Launch Dask or Ray clusters with Polyaxonfiles, submit repeated work, and control worker capacity, durable outputs, and cluster lifetimes.
Sep 26, 2026
Polyaxon
ProductDask
Finish Indexed Jobs after enough attempts succeed
Use Kubernetes Job success policies for chosen indexes or success counts, preserve durable results, and distinguish them from Polyaxon metric early stopping.
Sep 25, 2026
Polyaxon
KubernetesPipelines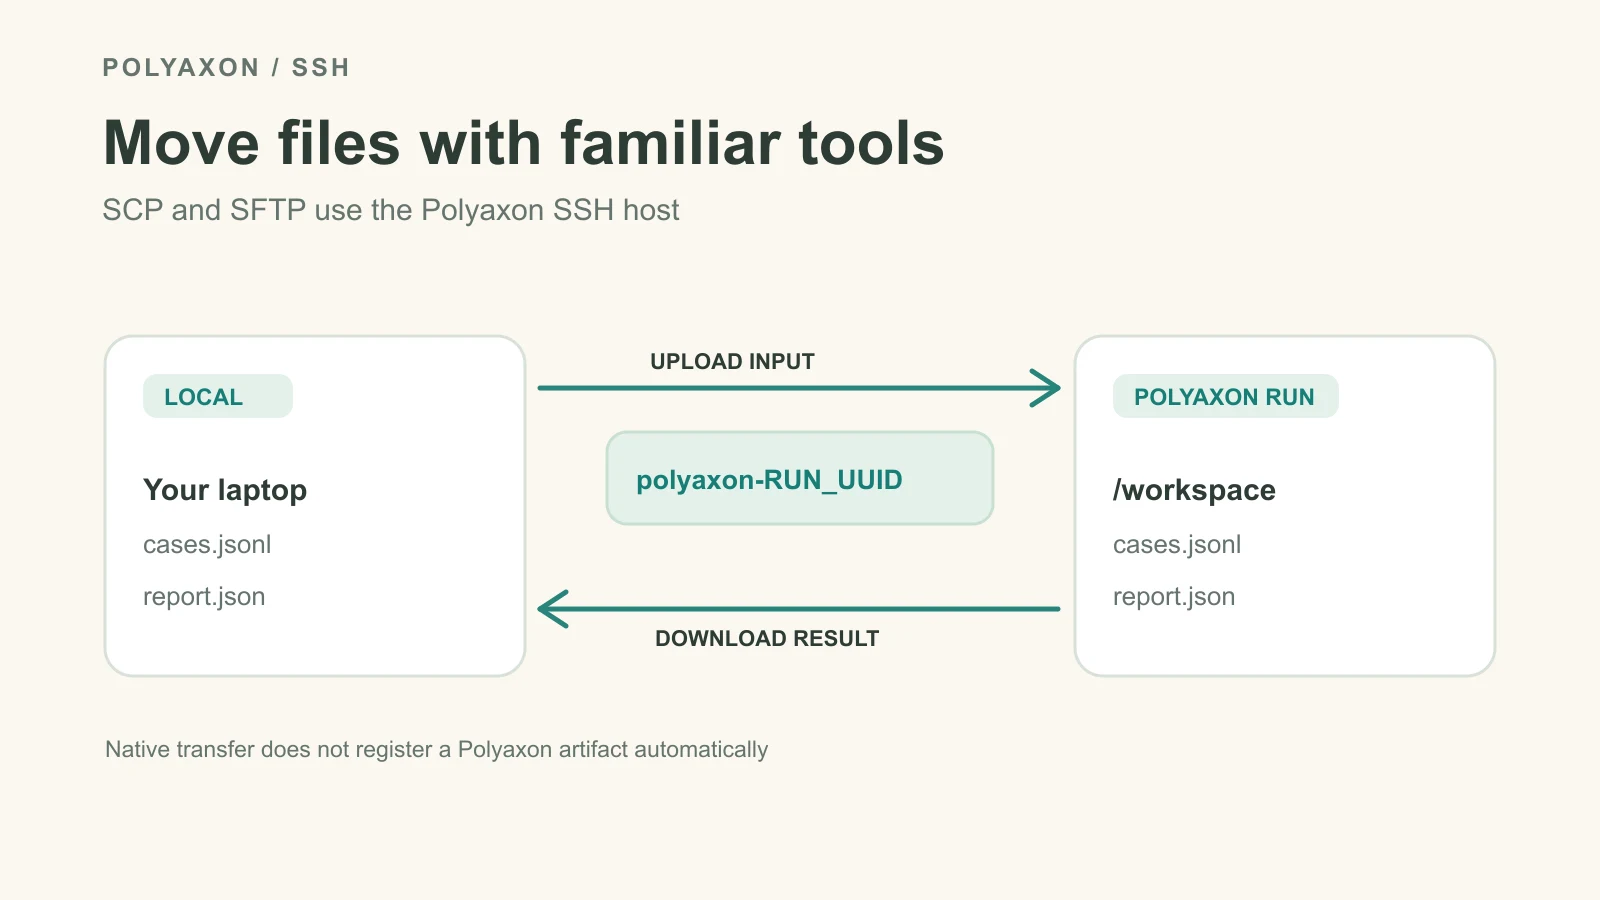
Transfer files to Polyaxon workspaces over SSH
Use Polyaxon's generated SSH host with native SCP and SFTP to move files into and out of a running service workspace.
Sep 25, 2026
Polyaxon
ProductCli
Spread inference replicas across Kubernetes zones
Use topology spread constraints for inference availability, understand minDomains and GPU capacity, and preserve placement intent in Polyaxon.
Sep 24, 2026
Polyaxon
KubernetesScheduling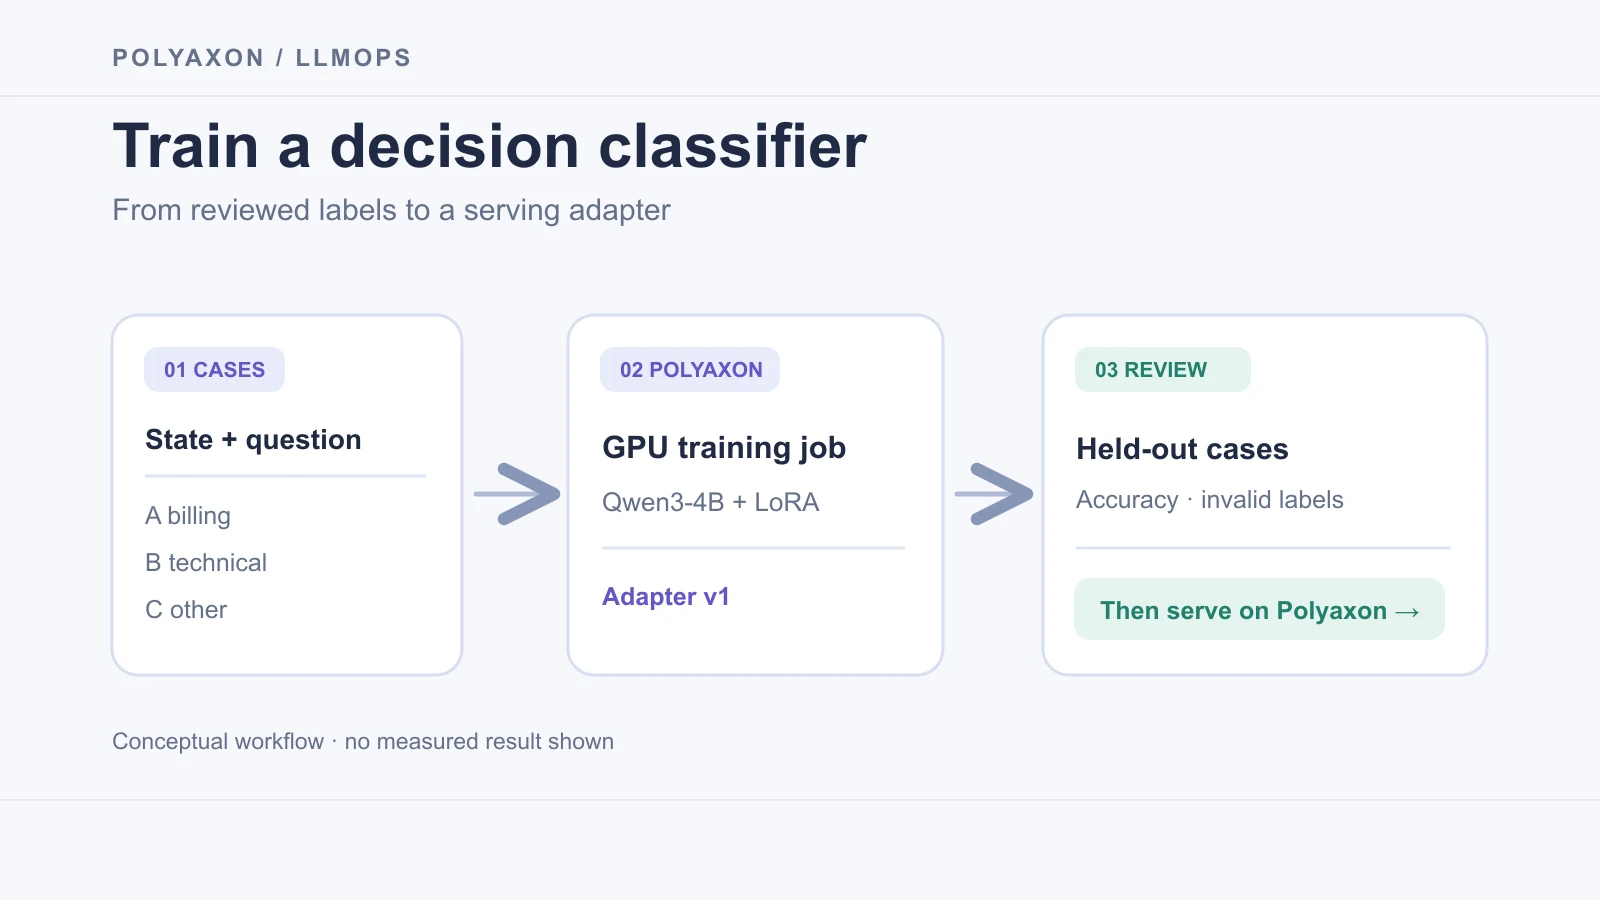
Train a decision classifier on Polyaxon
Fine-tune an open Qwen model for bounded support-routing decisions with Polyaxon jobs, track the adapter, and serve the reviewed version through vLLM.
Sep 24, 2026
Polyaxon
LLMOpsFine Tuning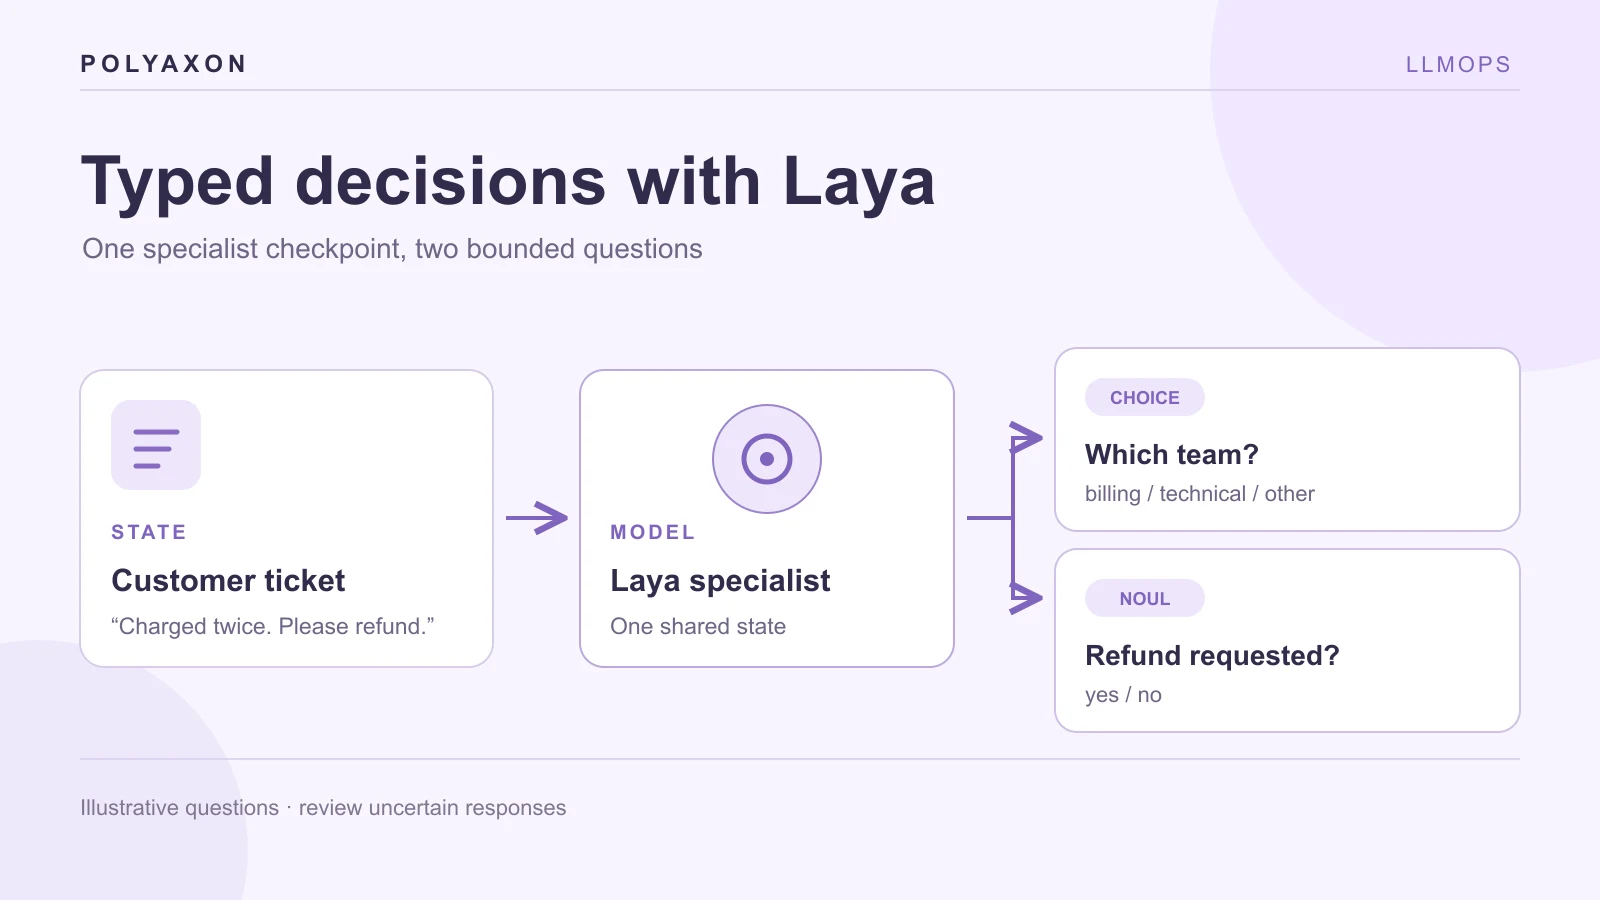
Deploy Laya typed decisions on Polyaxon
Serve the open Laya typed-decisions checkpoint through Polyaxon, with a CPU classifier endpoint, explicit model scope, and a review path for uncertain classifications.
Sep 23, 2026
Polyaxon
LLMOpsInference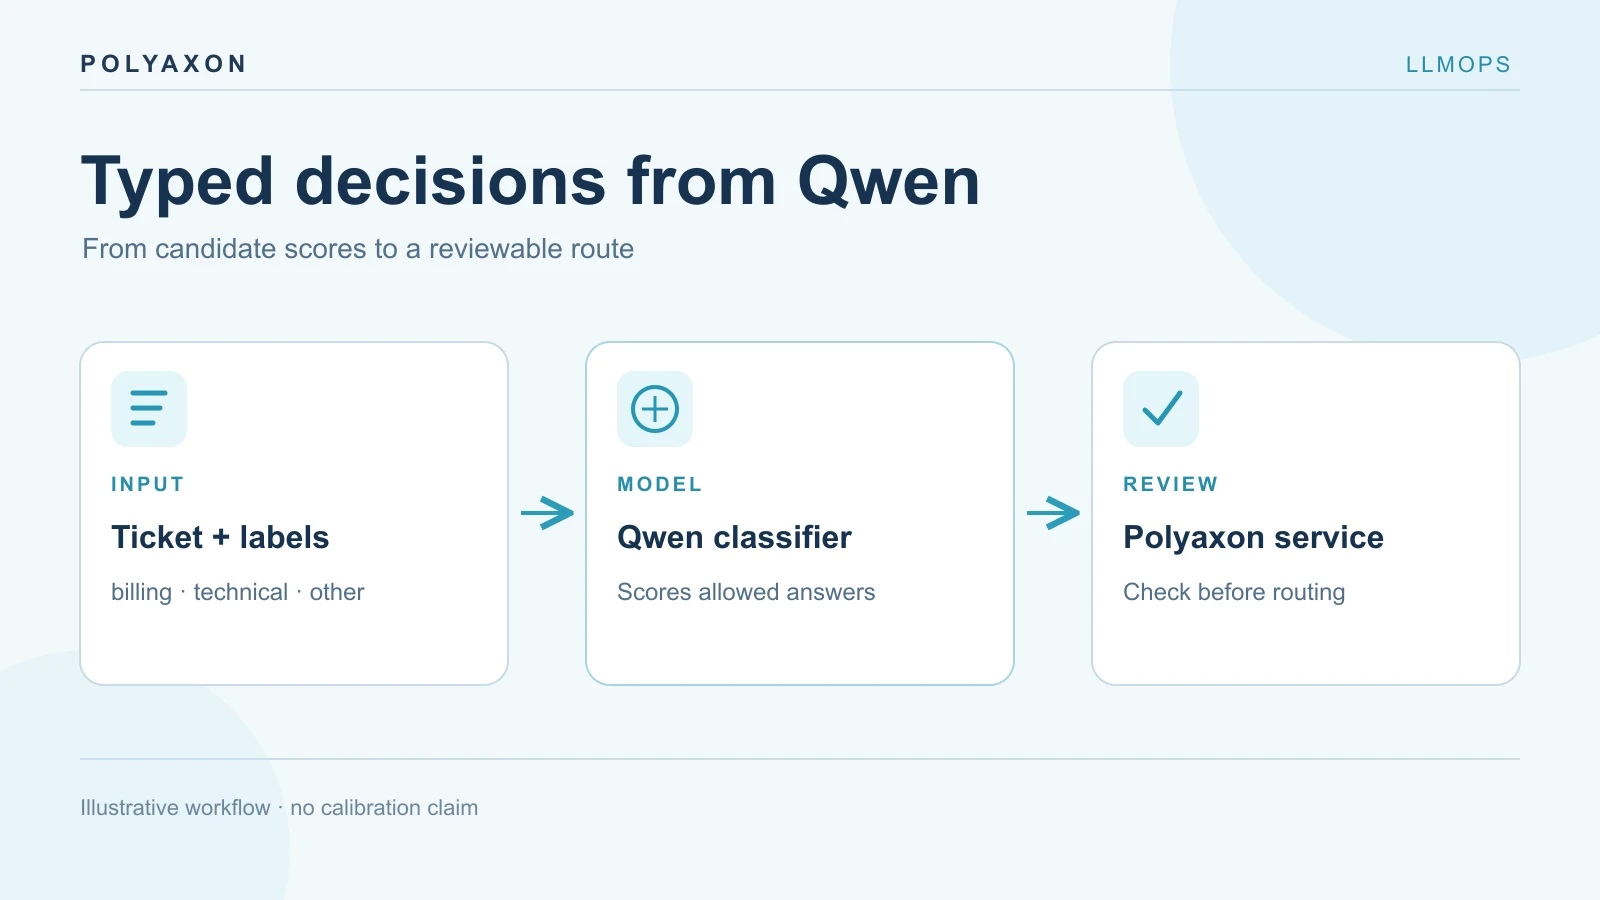
Serve a Jev-style Qwen classifier on Polyaxon
Deploy an open Qwen model behind a typed classification API on Polyaxon, then check the decision schema and calibration before routing real work.
Sep 23, 2026
Polyaxon
LLMOpsInference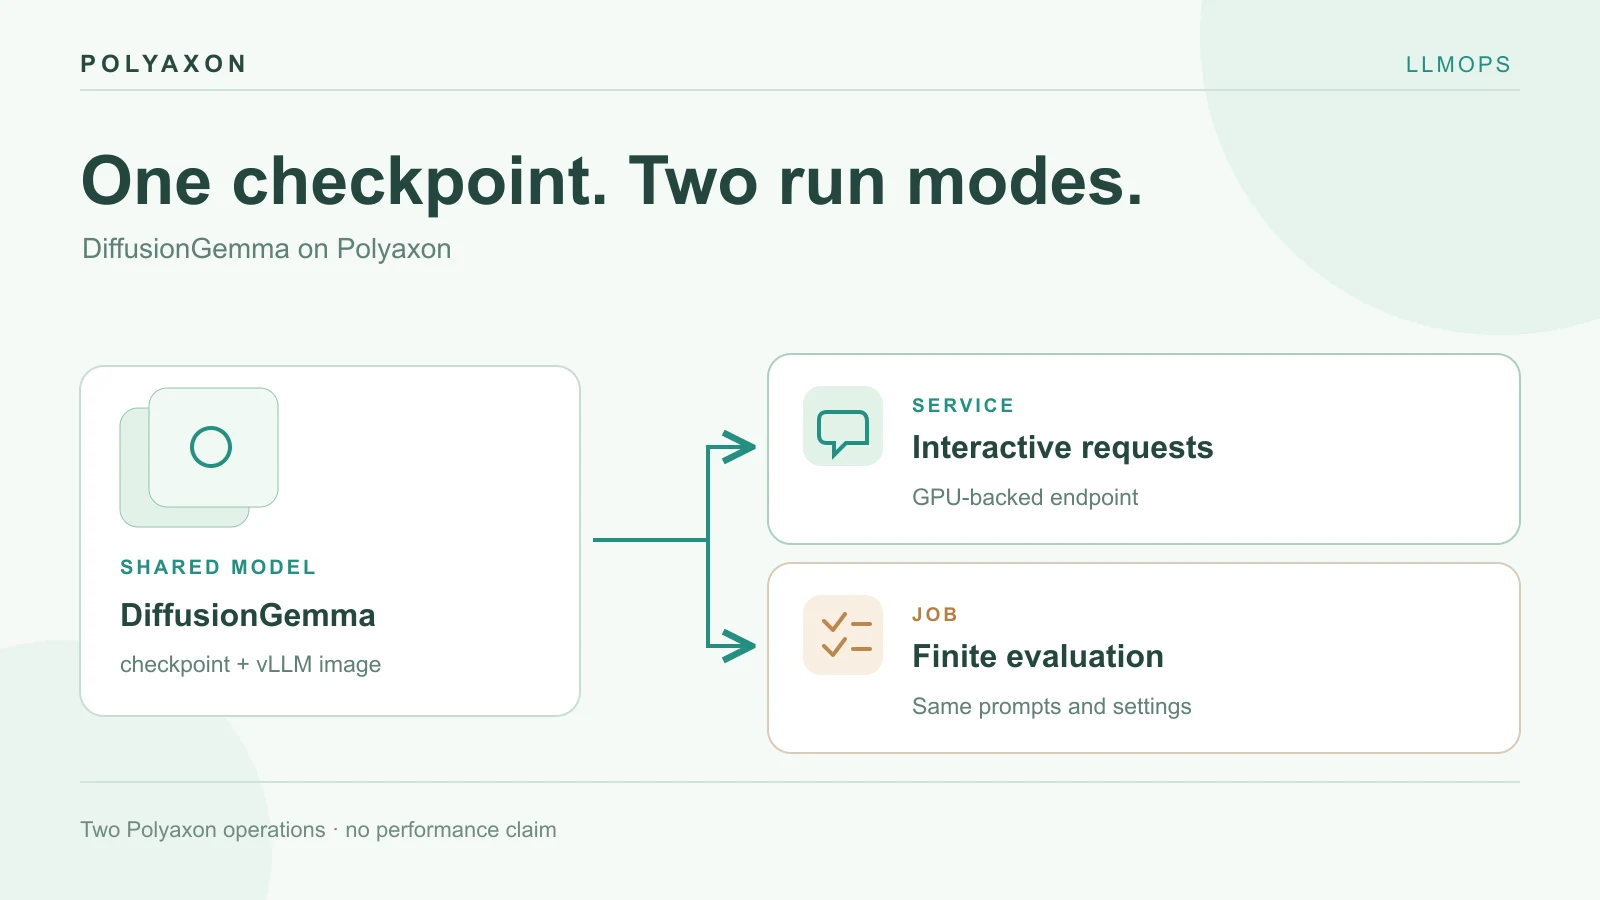
Serve DiffusionGemma on Polyaxon
Adapt Google's Gemma-on-Kubernetes deployment choices to Polyaxon with a DiffusionGemma vLLM service, a batch evaluation job, and an explicit compatibility checklist.
Sep 23, 2026
Polyaxon
LLMOpsInference
Align CPU and GPU resources with Kubernetes NUMA policies
Combine CPU Manager eligibility, full-core allocation, and Topology Manager policy, then compare CPU/GPU workloads with Polyaxon.
Sep 22, 2026
Polyaxon
KubernetesGpu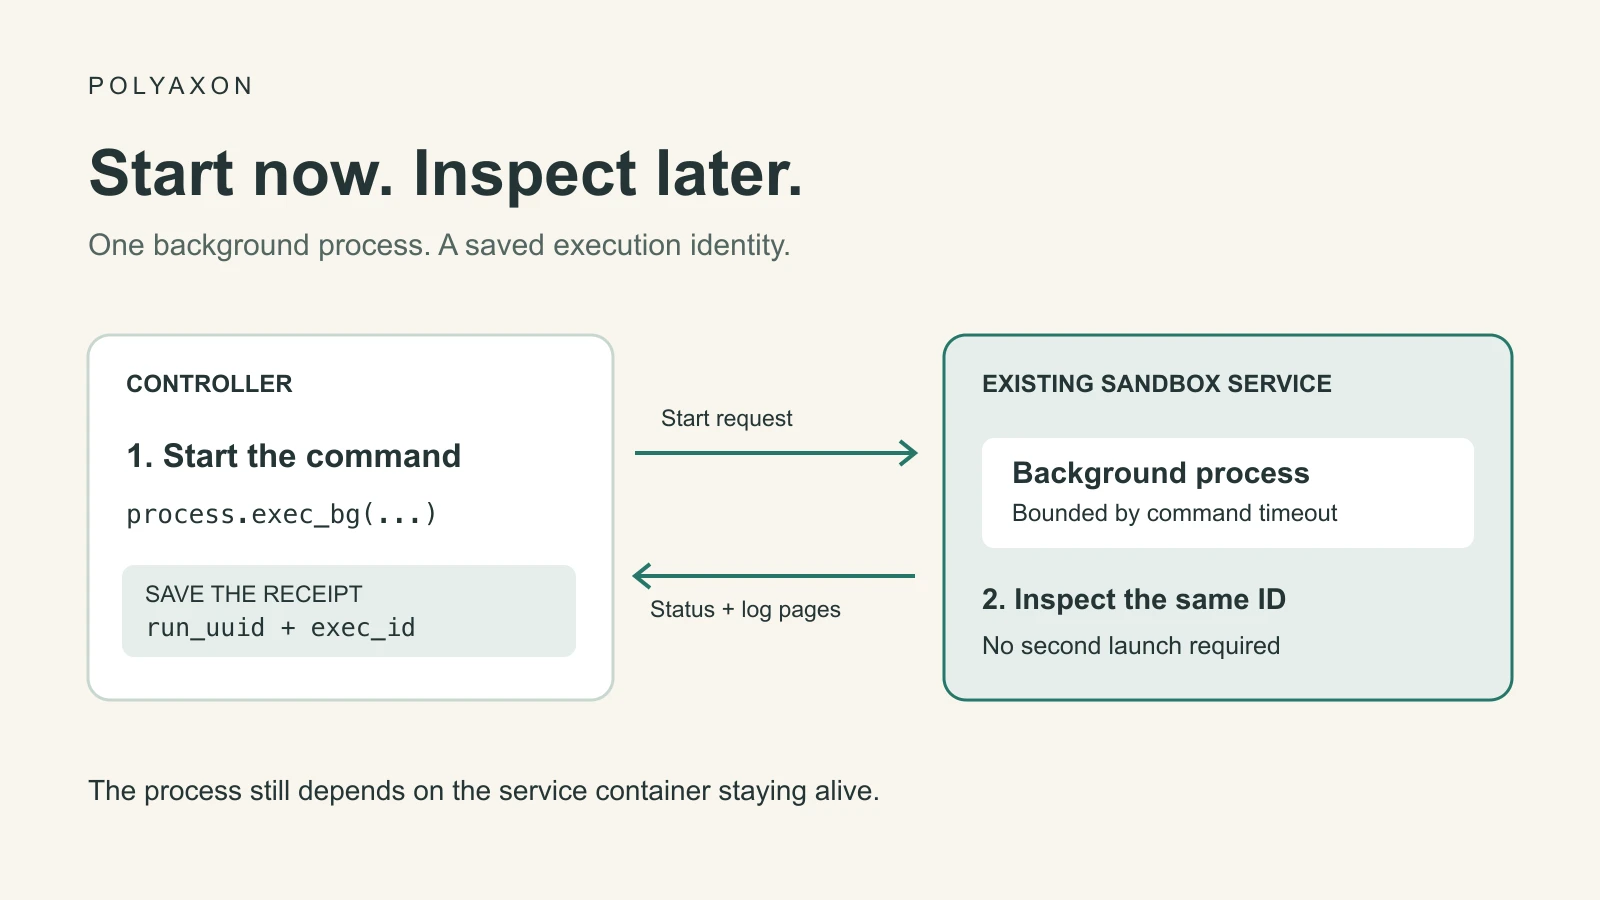
Run background commands in Polyaxon sandboxes
Start a background process, save its execution ID, reconnect to status and logs, and distinguish command limits from the lifetime of a Polyaxon sandbox.
Sep 22, 2026
Polyaxon
PolyaxonSandboxes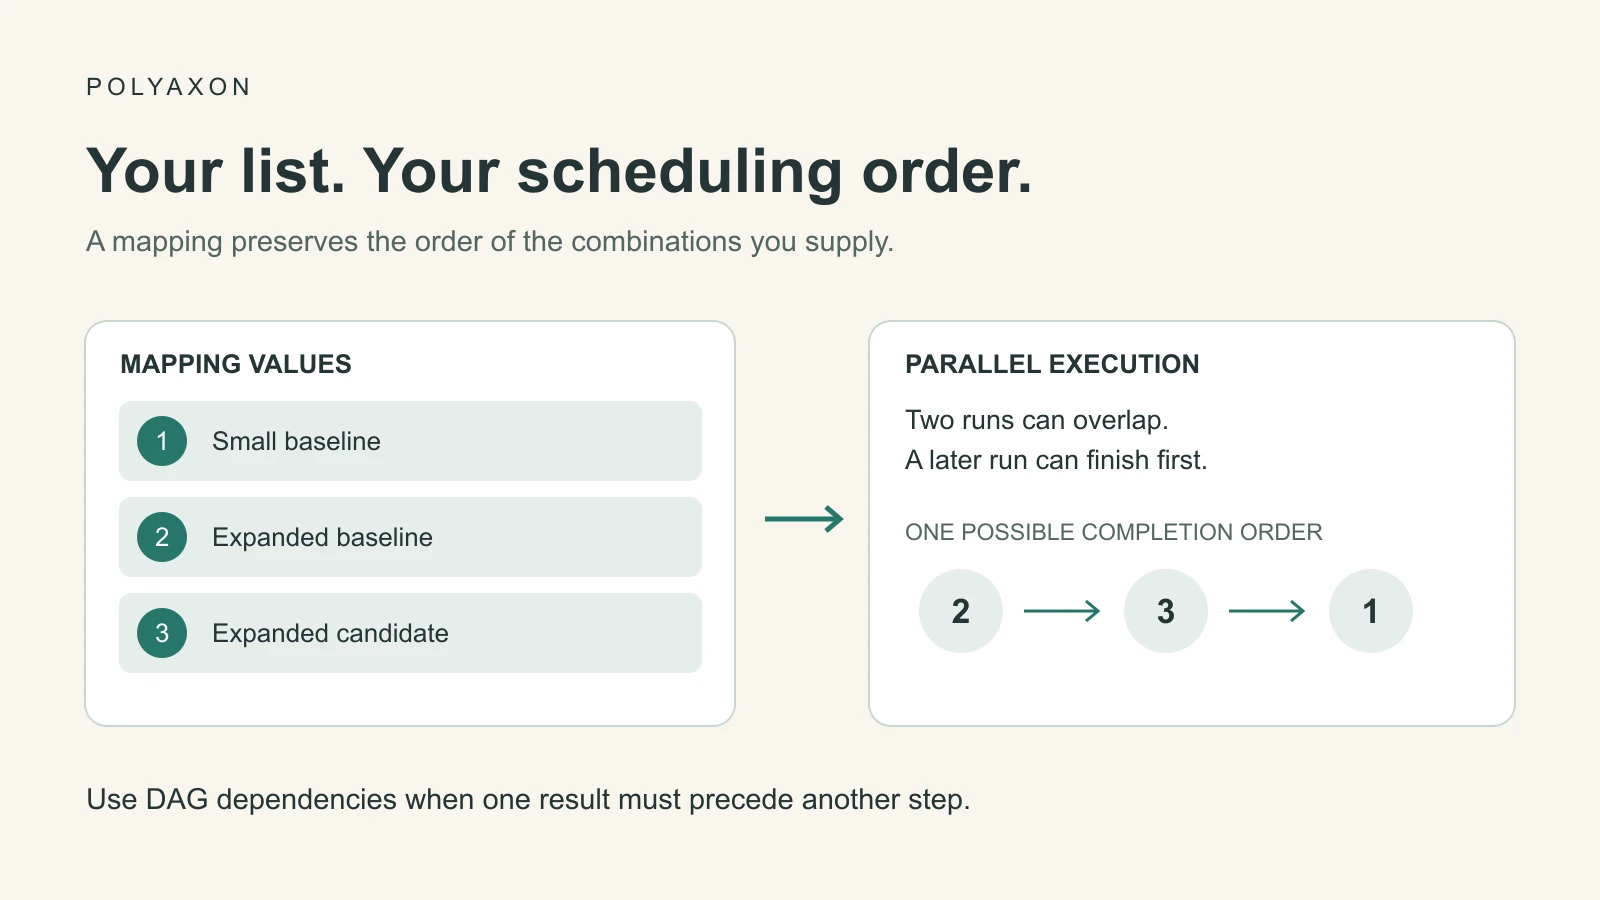
Schedule mapped runs in the order you specify
Use an ordered Polyaxon mapping for a curated list of experiments, control concurrency, and distinguish scheduling order from dependencies and completion order.
Sep 22, 2026
Polyaxon
PolyaxonOrchestration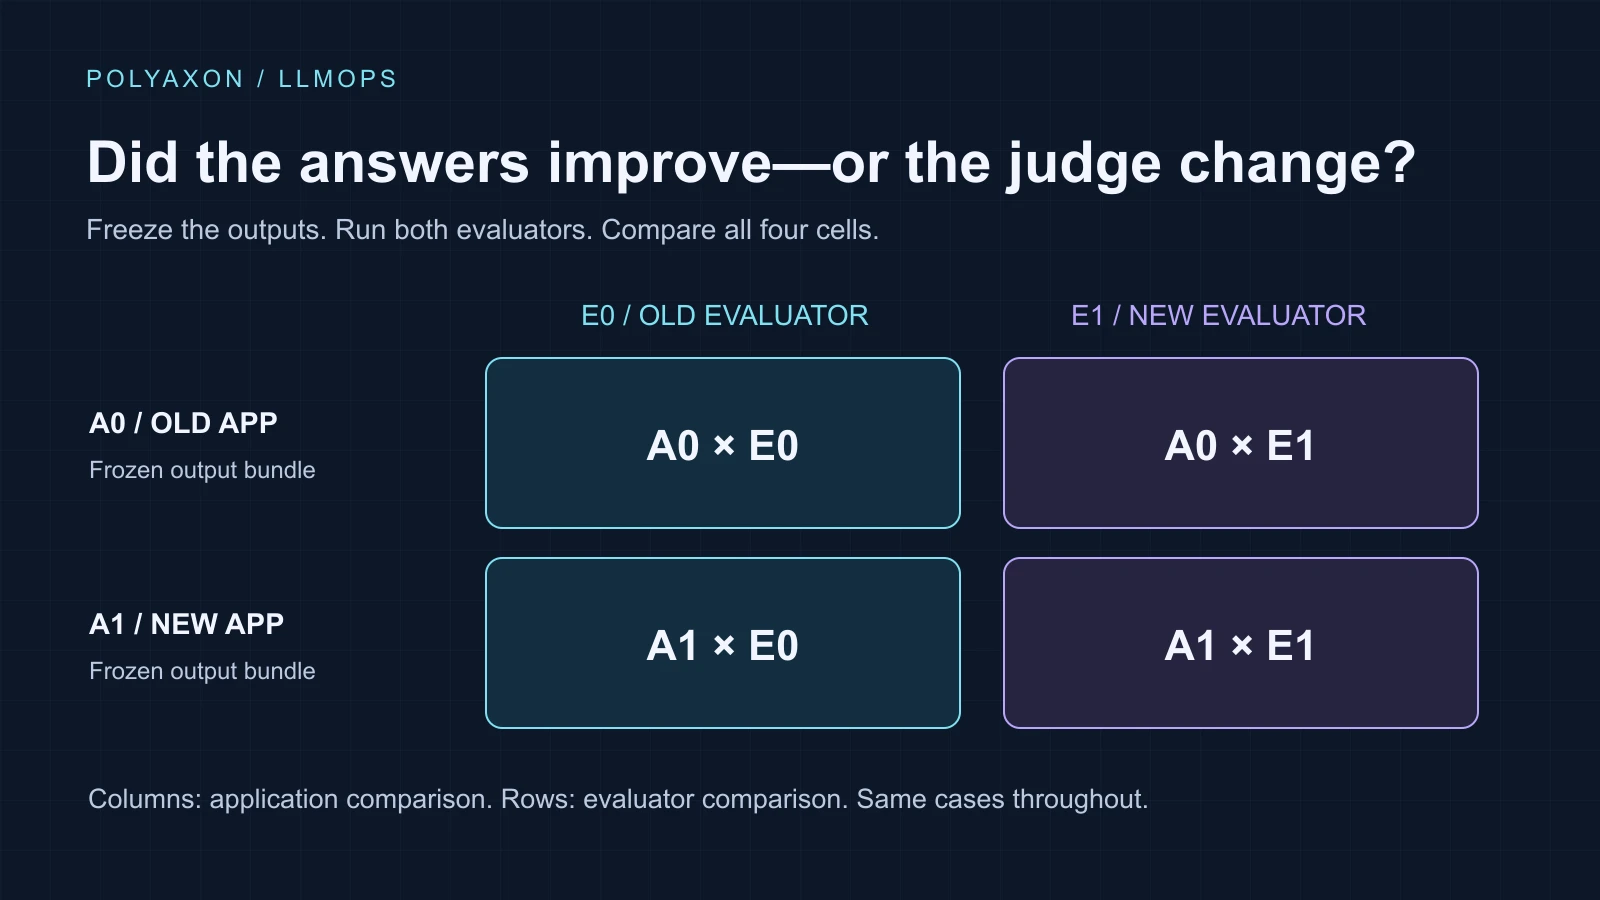
Separate evaluator changes from application improvements
Compare old and new application outputs under both evaluator versions, inspect changed decisions, and retain the four comparisons in Polyaxon.
Sep 22, 2026
Polyaxon
LLMOpsEvaluation
Make vLLM prefix caching work for repeated prompts
Understand exact prefix reuse in vLLM, structure repeated context, account for replica routing, and compare cold and warm workloads with Polyaxon.
Sep 21, 2026
Polyaxon
LLMOpsInferenceResize CPU and memory without replacing Kubernetes Pods
Use Kubernetes in-place resource resizing for running workloads, inspect whether changes took effect, and understand the limits for Polyaxon services.
Sep 21, 2026
Polyaxon
KubernetesScheduling
Native gang scheduling reaches beta in Kubernetes 1.37
Explore native gang scheduling in Kubernetes 1.37, its potential for Polyaxon training and sandboxes, and how it compares with KAI, Kueue, and Volcano.
Sep 20, 2026
Polyaxon
KubernetesScheduling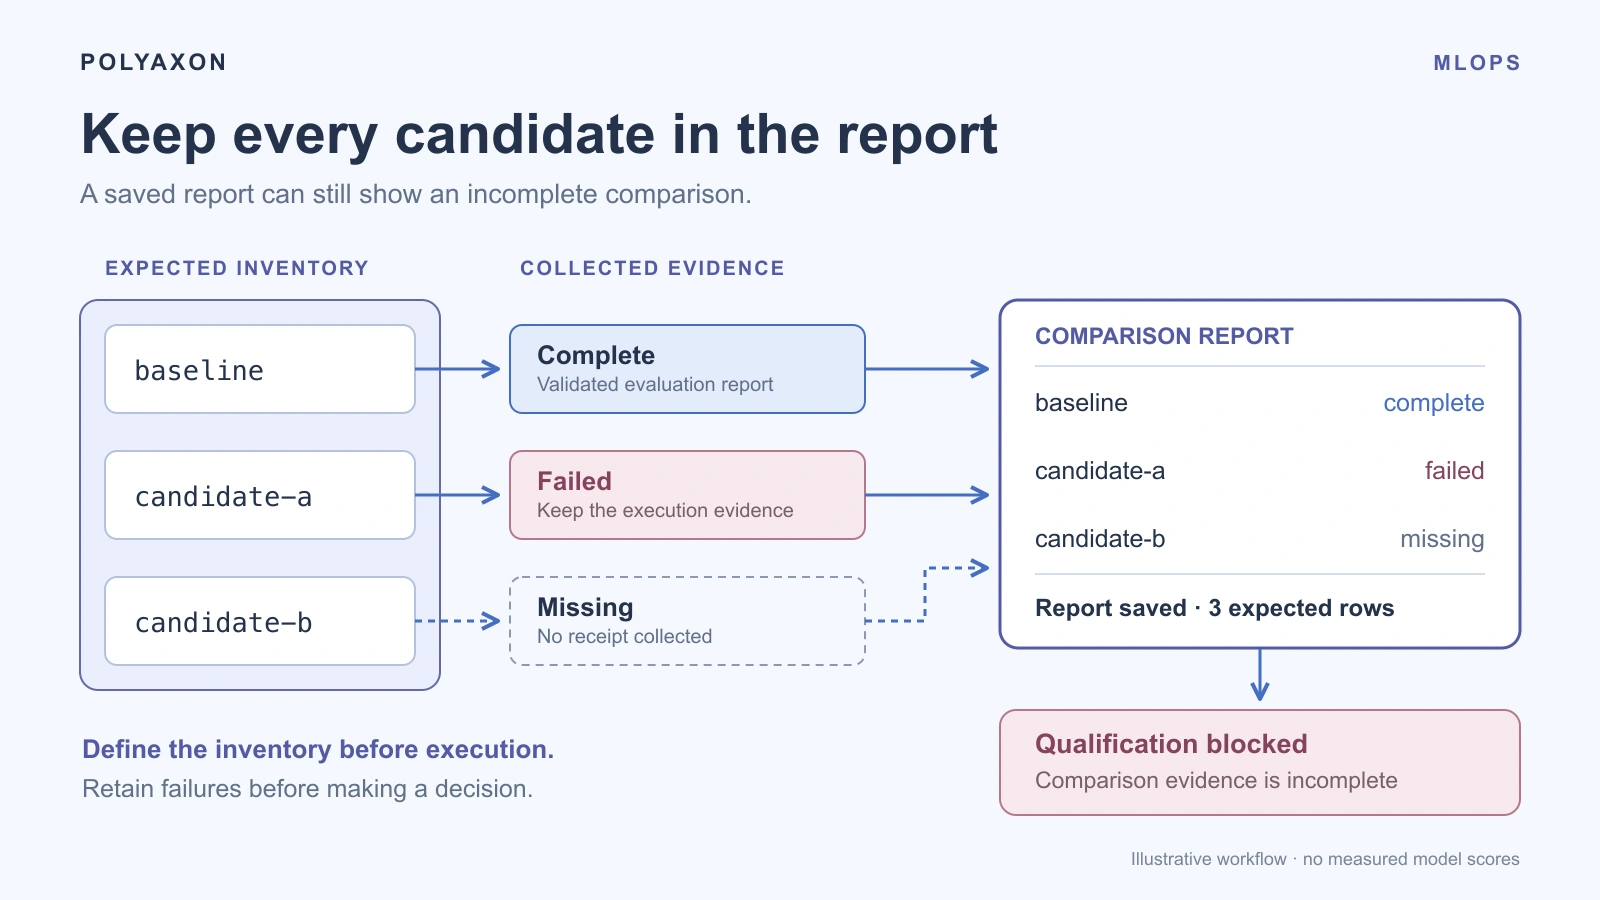
Keep failed candidates visible in pipeline reports
Reconcile evaluation results against an expected candidate manifest, preserve failed and missing outcomes, and separate pipeline reporting from release approval.
Sep 19, 2026
Polyaxon
MLOpsOrchestration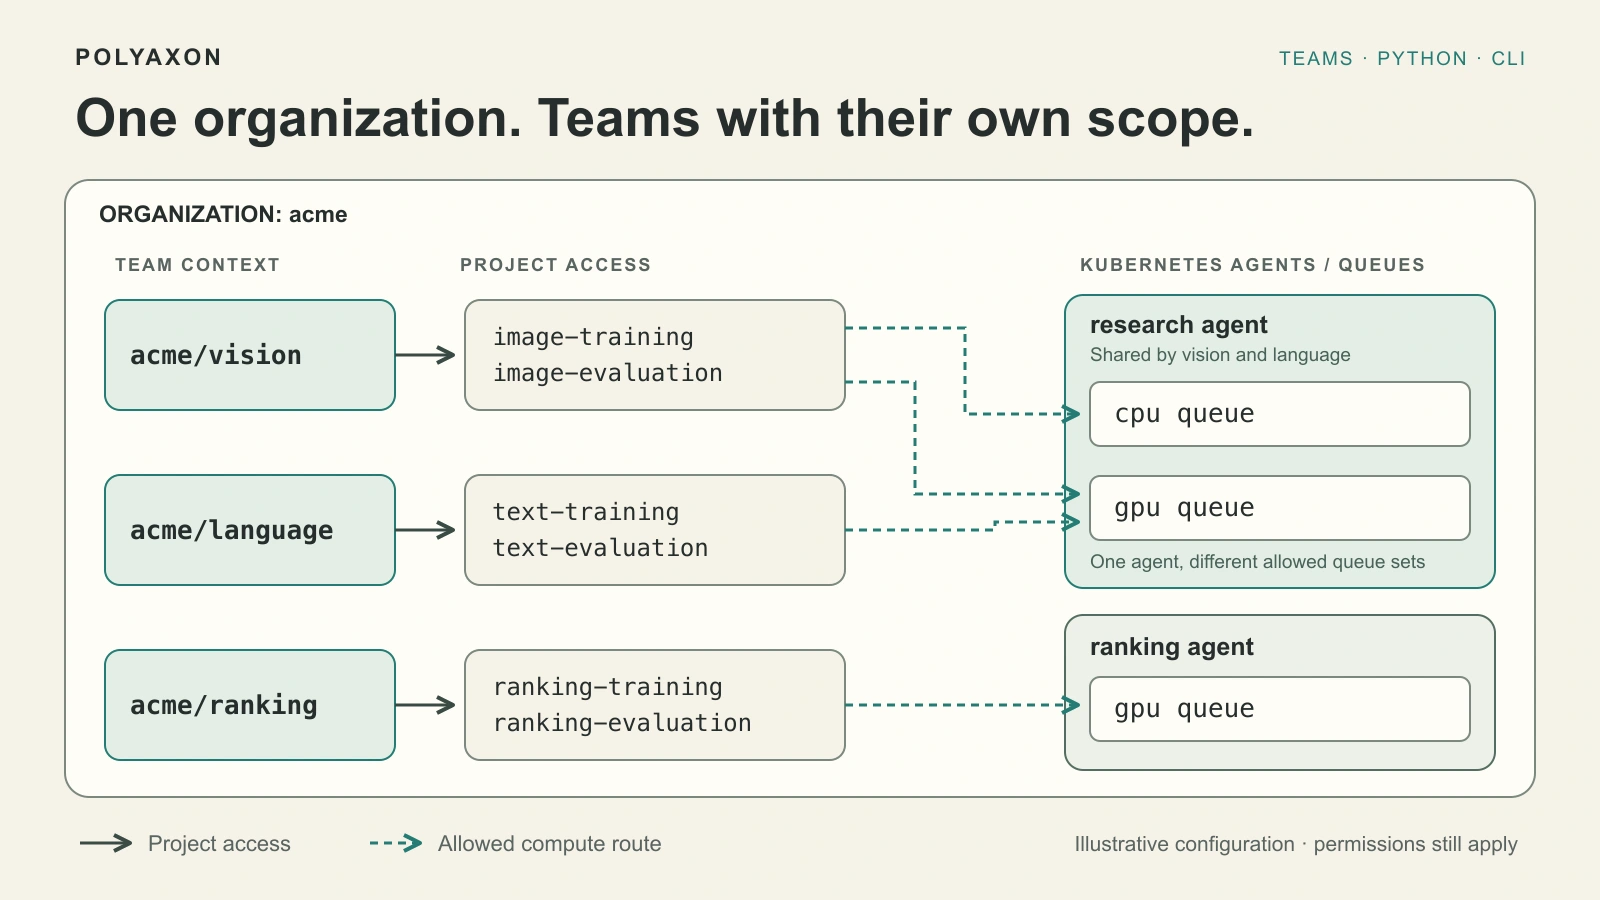
Work inside a team from Python and the CLI
Scope Polyaxon Python clients and CLI commands to a team, review runs across its projects, and keep explicit project targets and saved defaults clear.
Sep 19, 2026
Polyaxon
PolyaxonTeams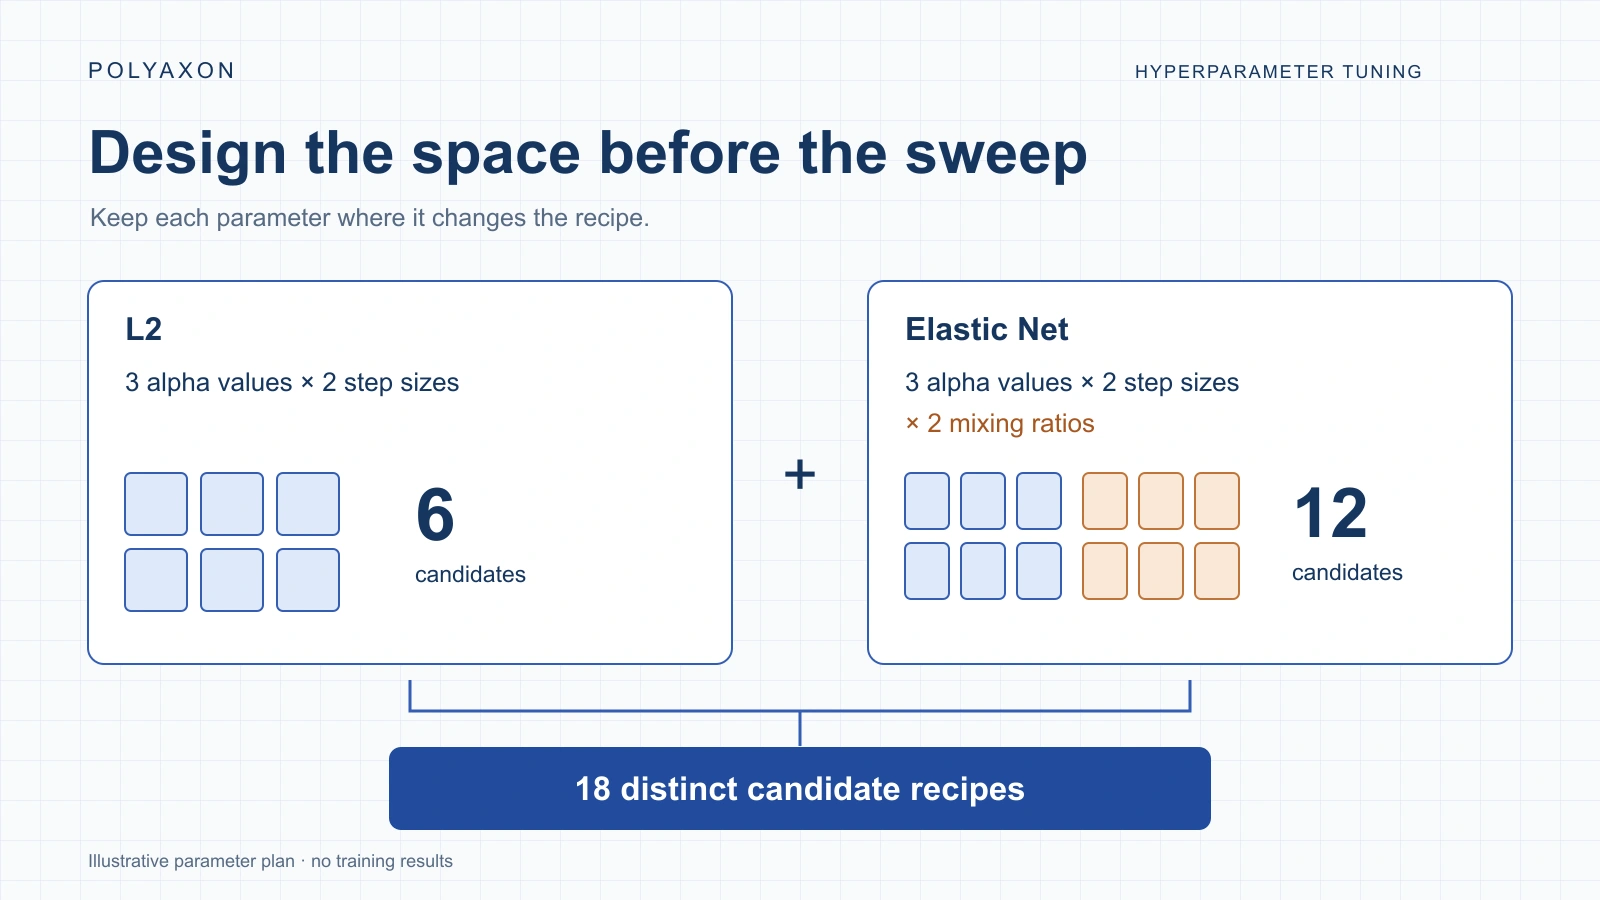
Design a search space before launching the sweep
Use Polyaxon matrices to choose parameter scales, separate meaningful combinations, and control the size of a hyperparameter sweep.
Sep 18, 2026
Polyaxon
Hyperparameter TuningMLOps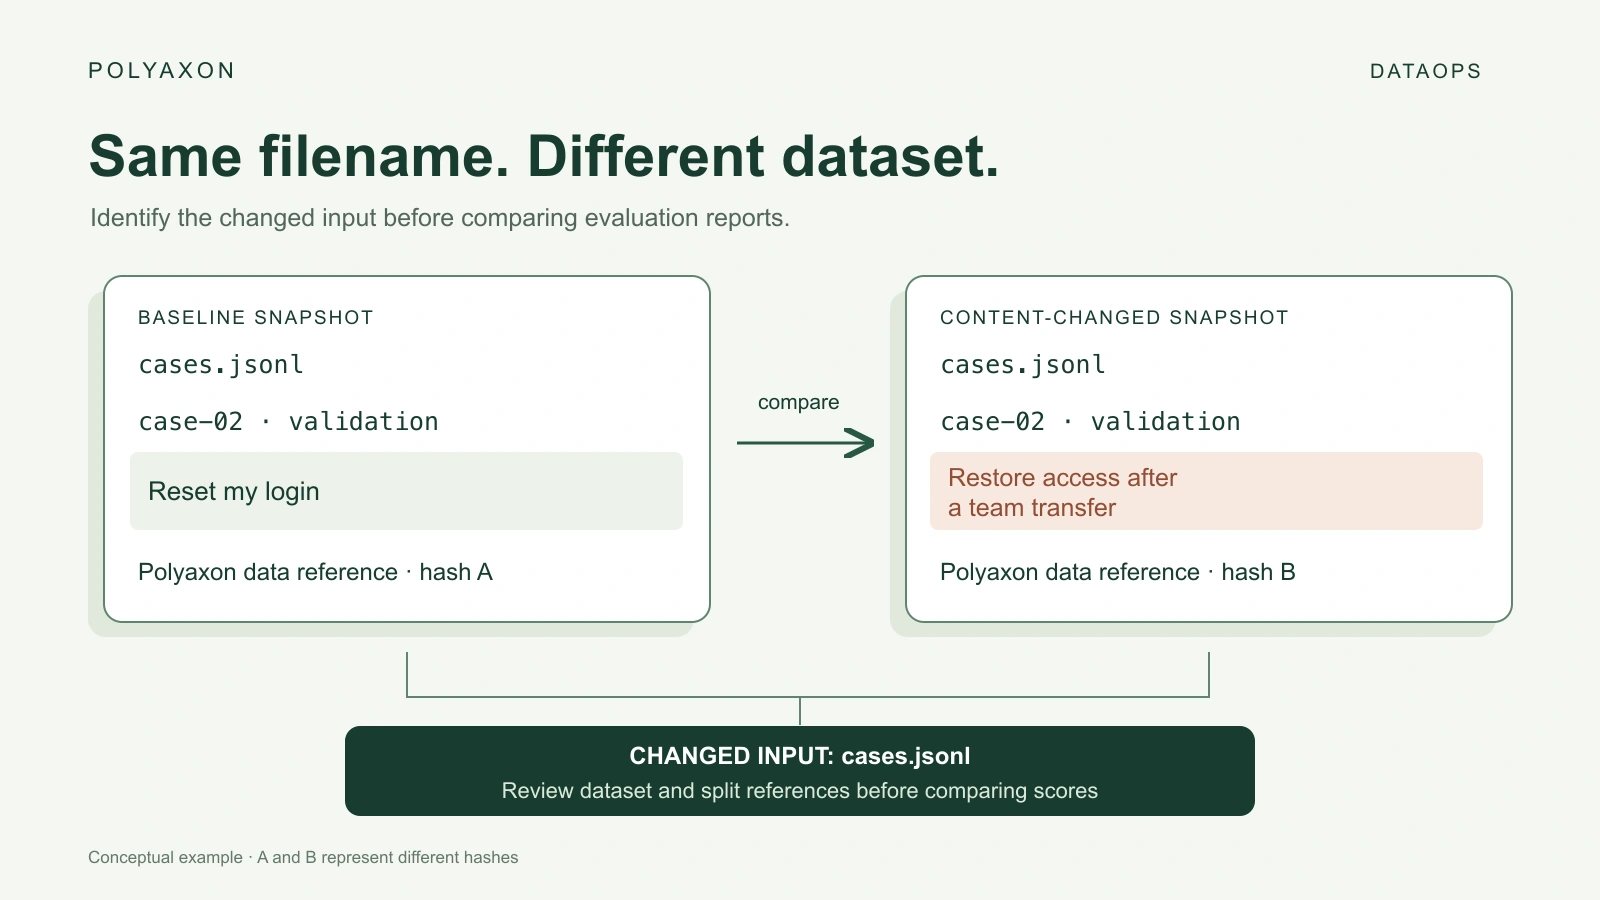
Version the dataset behind every evaluation
Use Polyaxon data references, artifact logging, and registered versions to retain the dataset and split behind each evaluation.
Sep 18, 2026
Polyaxon
DataOpsMLOps
Keep distributed training workers close together
Understand native topology-aware workload scheduling, combine rack locality with gang placement, and assess the tradeoff between waiting and communication.
Sep 17, 2026
Polyaxon
KubernetesScheduling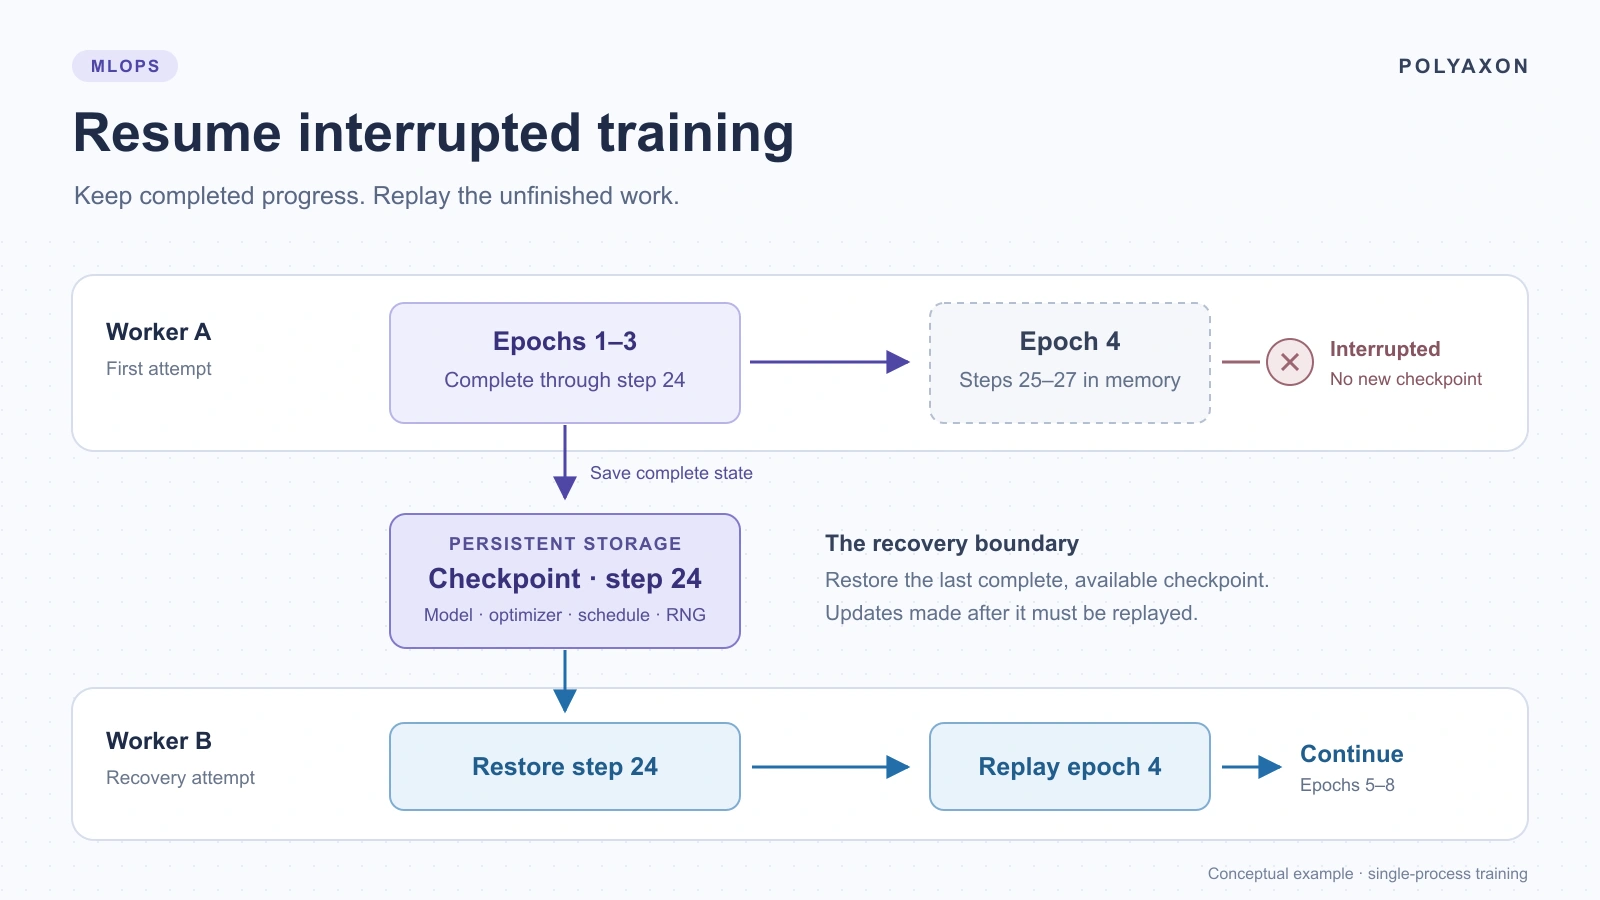
Resume interrupted training without losing progress
Build recoverable PyTorch training jobs with complete checkpoints, durable storage, and explicit restoration. Practice recovery locally and with Polyaxon.
Sep 17, 2026
Polyaxon
MLOpsKubernetes