Keep inference available during Kubernetes node drains
Set a PodDisruptionBudget around usable inference capacity, inspect blocked evictions, and account for replacement GPUs and model warmup.
KubernetesInferenceReliability
The latest guides, tutorials, and product updates.
Set a PodDisruptionBudget around usable inference capacity, inspect blocked evictions, and account for replacement GPUs and model warmup.
Use projected ServiceAccount tokens and refresh-aware clients so long-running training, notebooks, and services can keep authenticating without static credentials.
Use exit-code-based container restart rules, observe what stays within the Pod, and distinguish local recovery from retrying a complete ML operation.
Build an operational foundation for autonomous agents using Polyaxon workload profiles, durable state, bounded authority, evaluation, and recovery ownership.
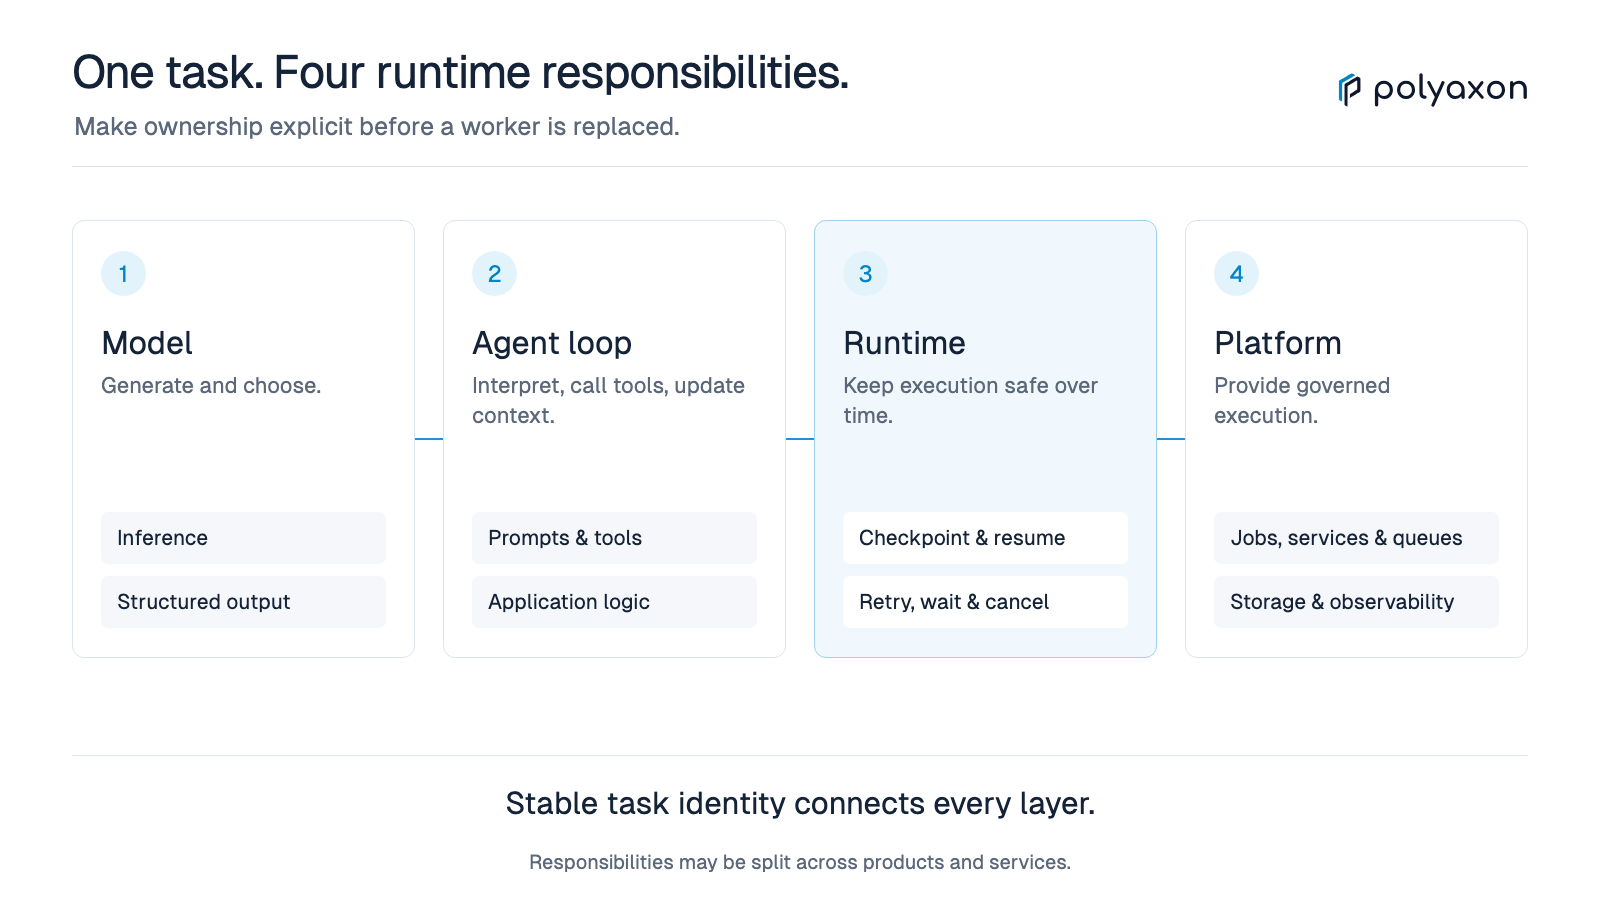
Scale AI agents with admission control, dependency-aware concurrency, durable state, bounded authority, backpressure, and outcome-based capacity planning.
Evaluate AI agent infrastructure reliability through task-level outcomes, recovery behavior, Polyaxon execution evidence, and explicit operational ownership.
Use Pod certificate projections and trust bundles for workload TLS, with signer prerequisites and rotation handling for long-running ML services.