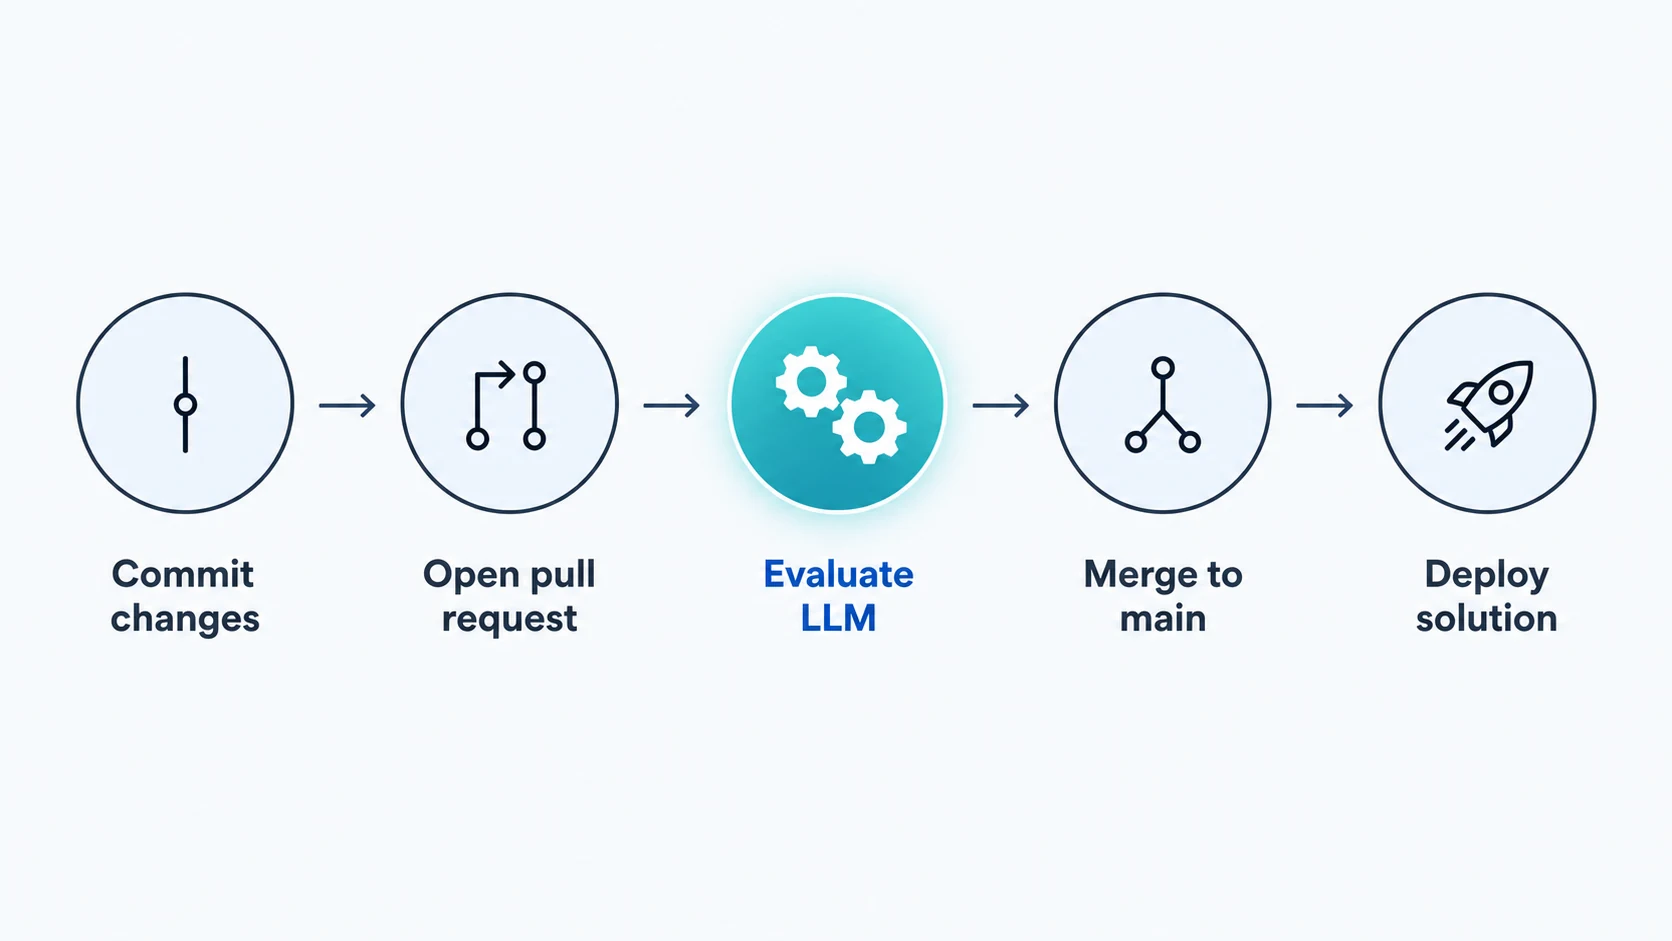
Continuous AI red teaming in CI/CD
Turn AI security findings into repeatable CI checks with versioned cases, complete result manifests, explicit release gates, and retained evidence.
Red TeamingPipelinesEvaluation
The latest guides, tutorials, and product updates.
Turn AI security findings into repeatable CI checks with versioned cases, complete result manifests, explicit release gates, and retained evidence.
Build MCP security tests for tool discovery, authorization, injected tool results, session identity, and approval boundaries in AI agents.
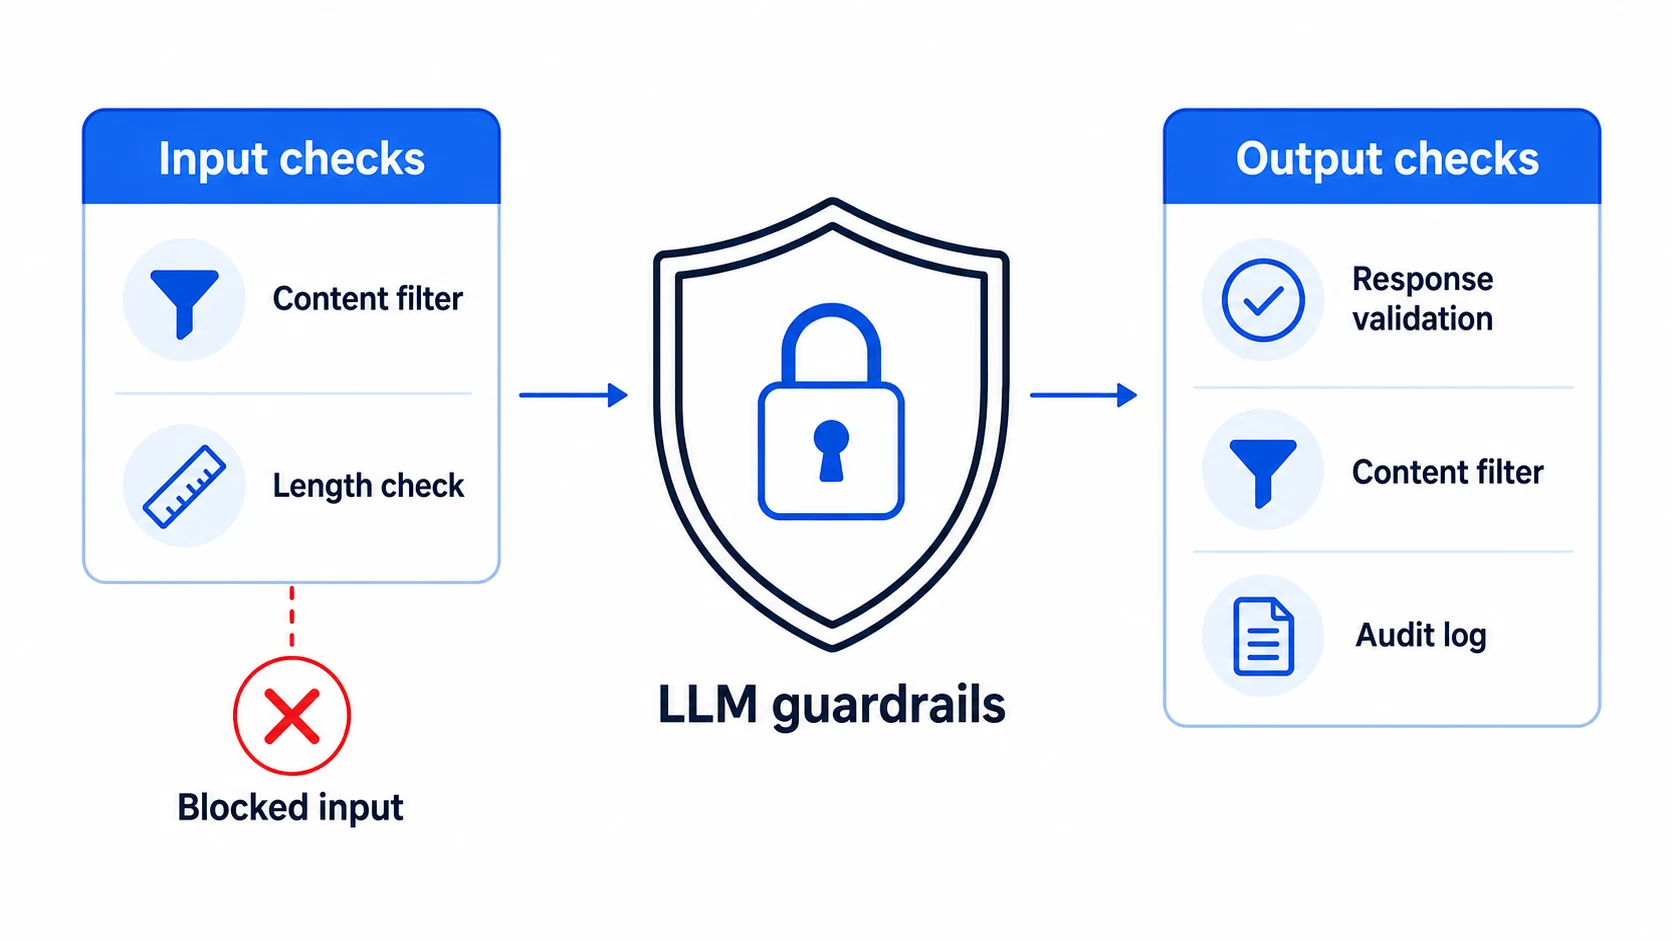
Compare LLM guardrails using attack blocking, legitimate task success, false refusals, latency, cost, and explicit handling of errors.
Measure AI red teaming with explicit attack success rates, attempt budgets, coverage, false refusals, severity, and evaluator uncertainty.
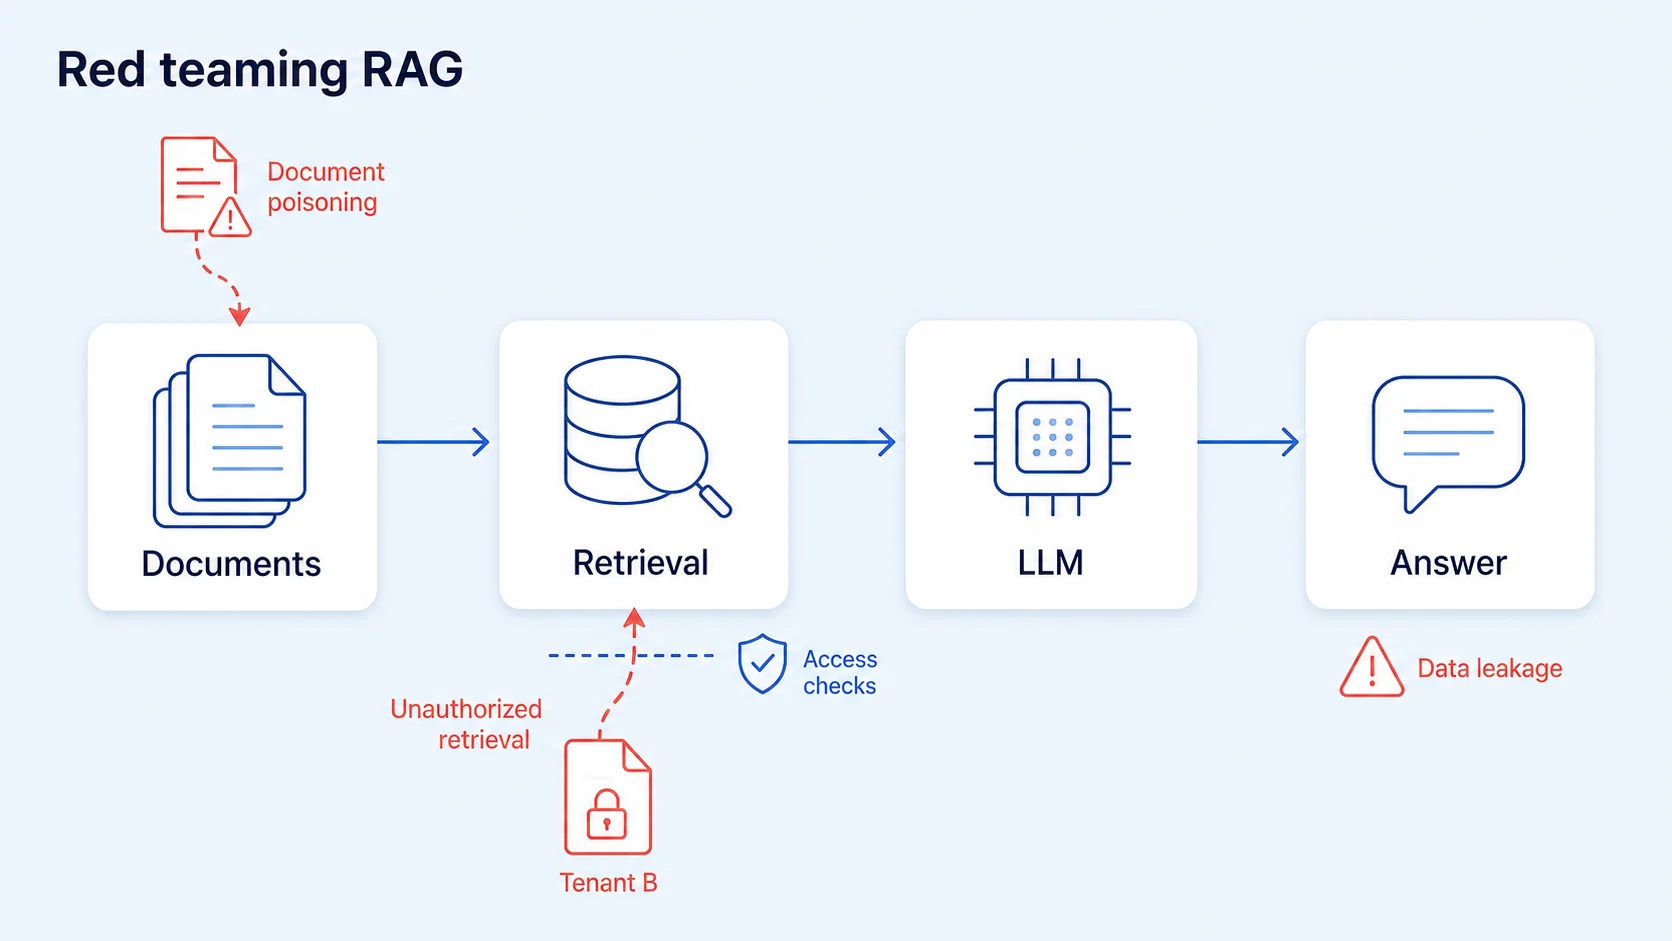
Test RAG systems for poisoned documents, cross-tenant retrieval, stale permissions, citation leaks, and unauthorized tool actions.
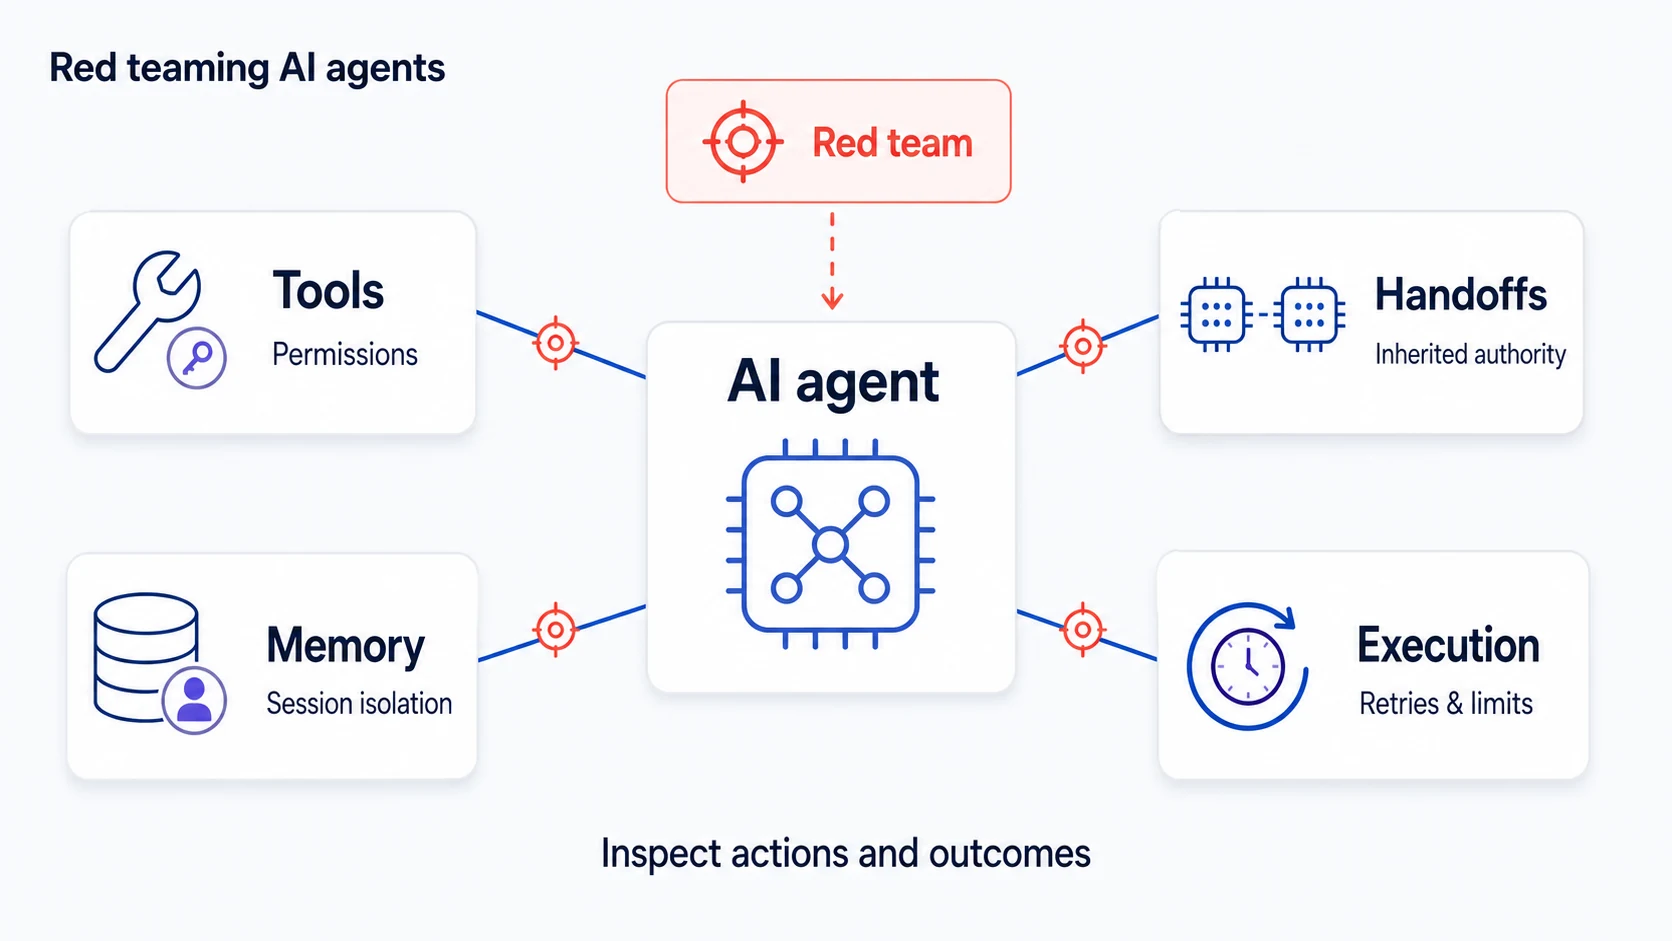
Test AI agent permissions, memory, handoffs, retries, and tool actions with a practical security matrix and reproducible evaluation workflow.
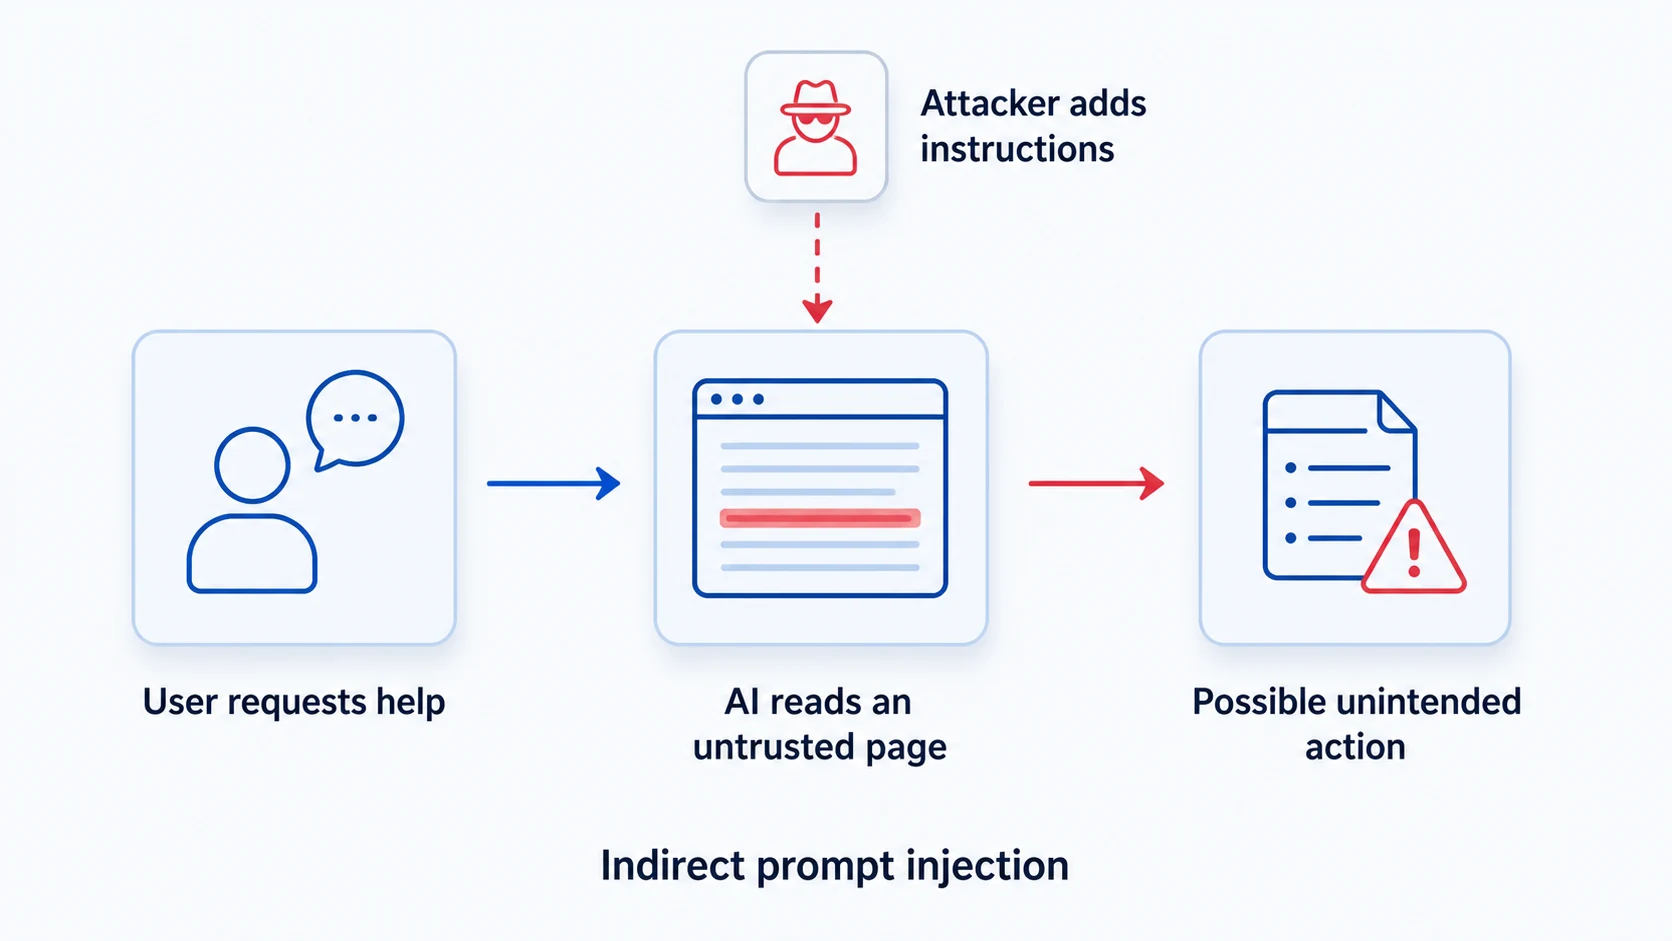
Build prompt injection tests for user input, retrieved documents, and tool responses, with checks for data access and actual side effects.
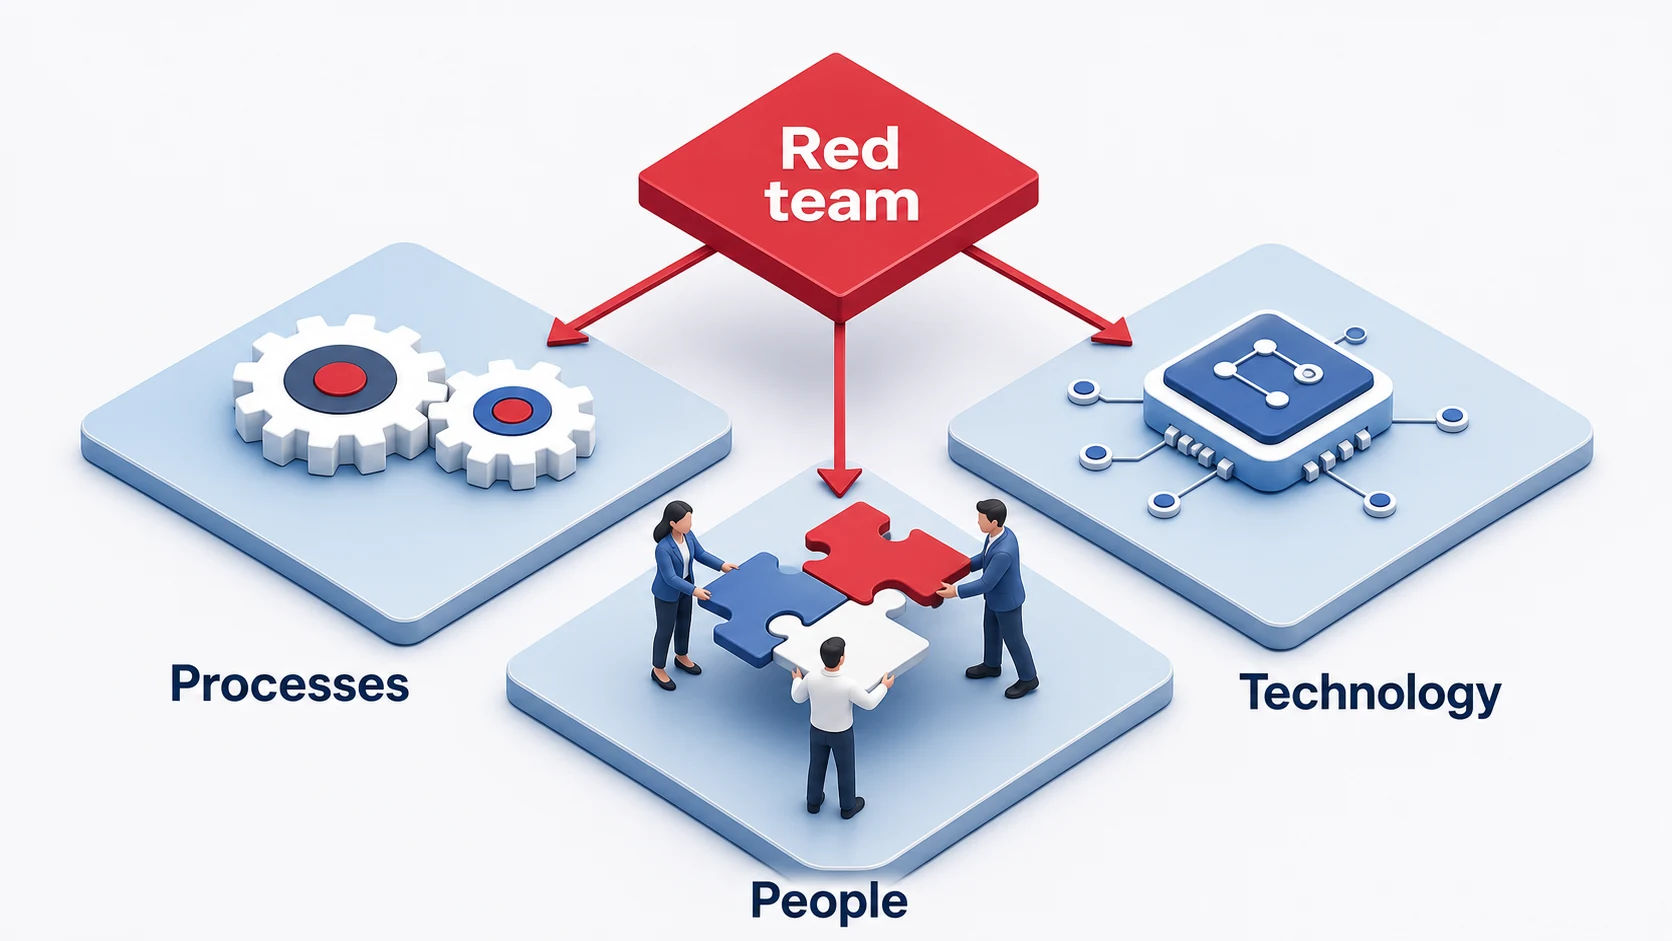
Design scoped adversarial tests for AI applications, examine tool and retrieval boundaries, and turn findings into regression coverage.