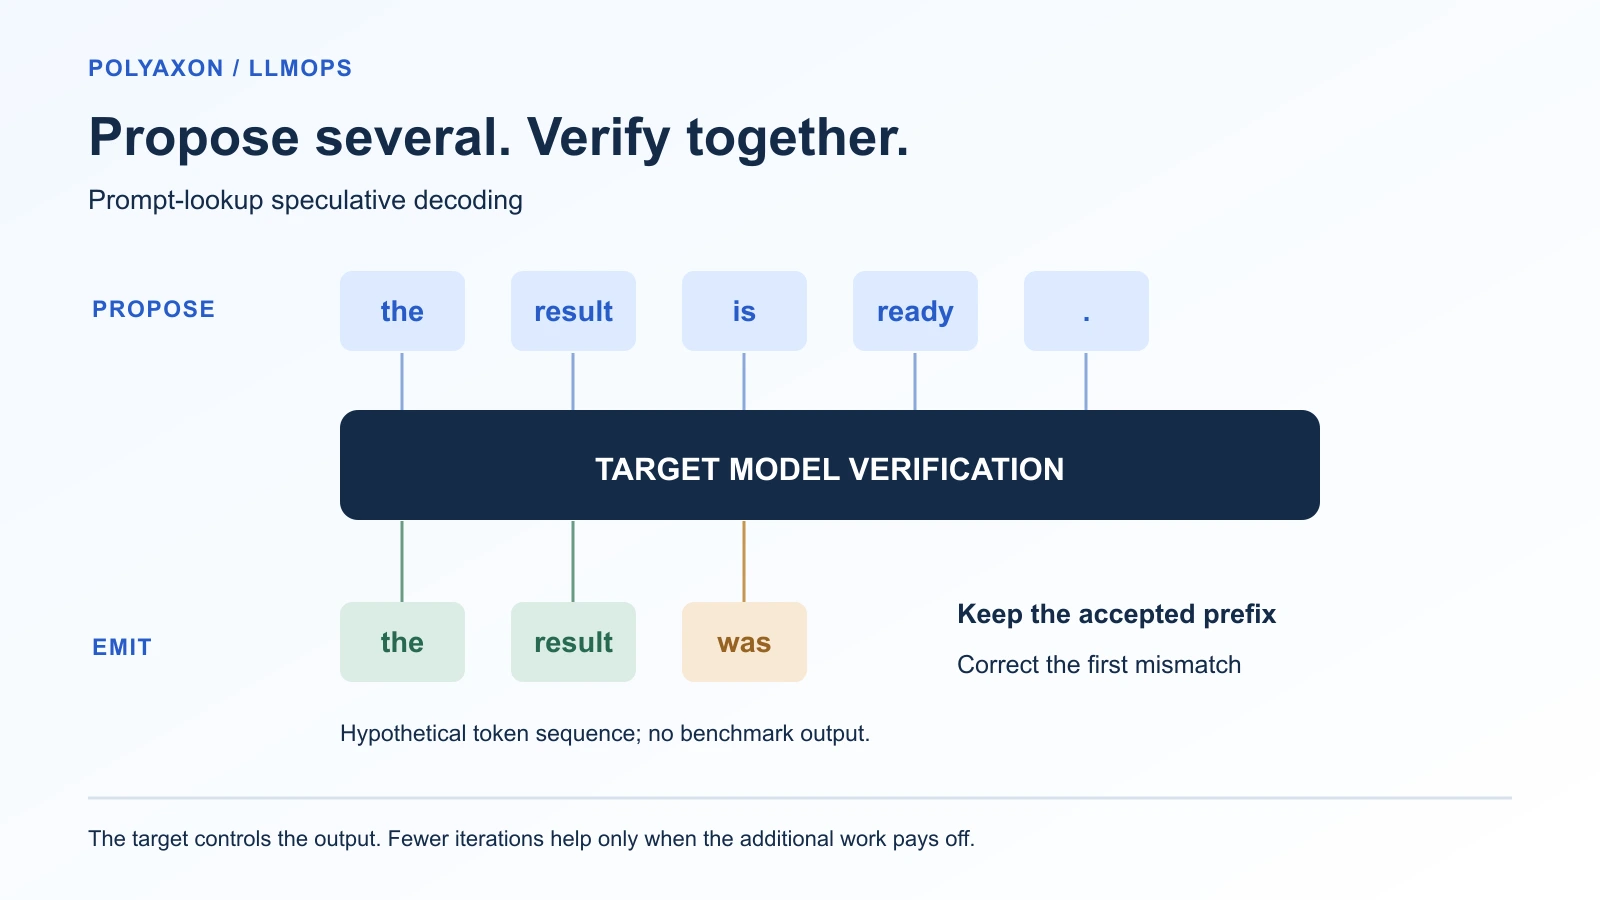
Benchmark vLLM speculative decoding on Polyaxon
Compare ordinary decoding with prompt-lookup proposals under the same model, workload, and GPU allocation, including latency, failures, and output checks.
LLMOpsvLLMInference
The latest guides, tutorials, and product updates.
Compare ordinary decoding with prompt-lookup proposals under the same model, workload, and GPU allocation, including latency, failures, and output checks.
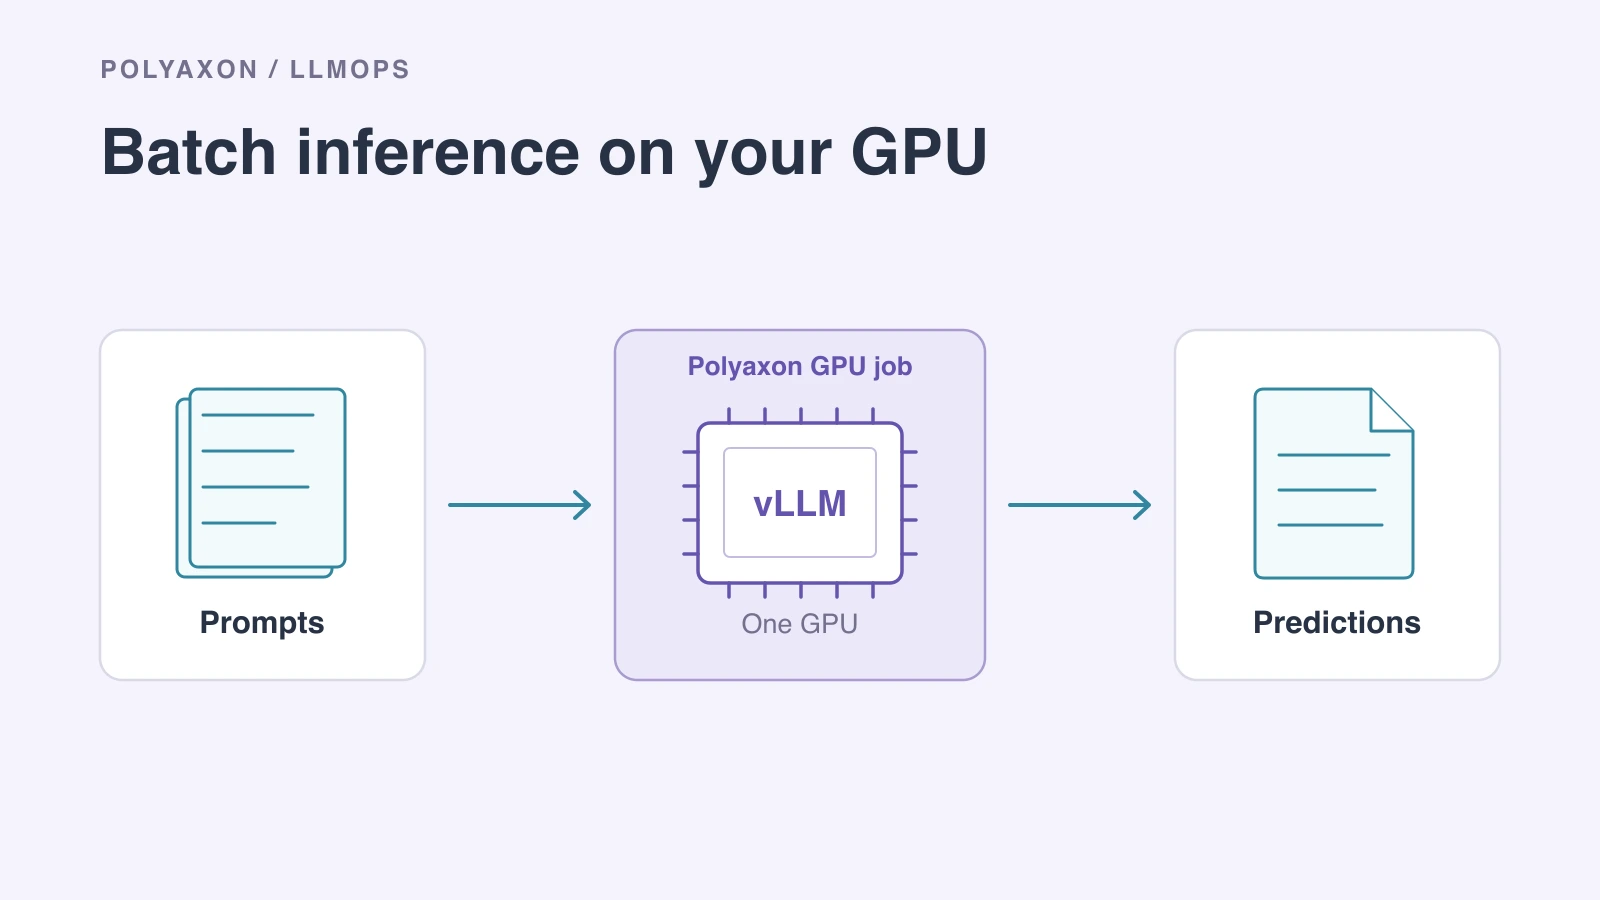
Generate predictions from a JSONL prompt file with vLLM, schedule the work on a Polyaxon GPU agent, and save the results as run artifacts.
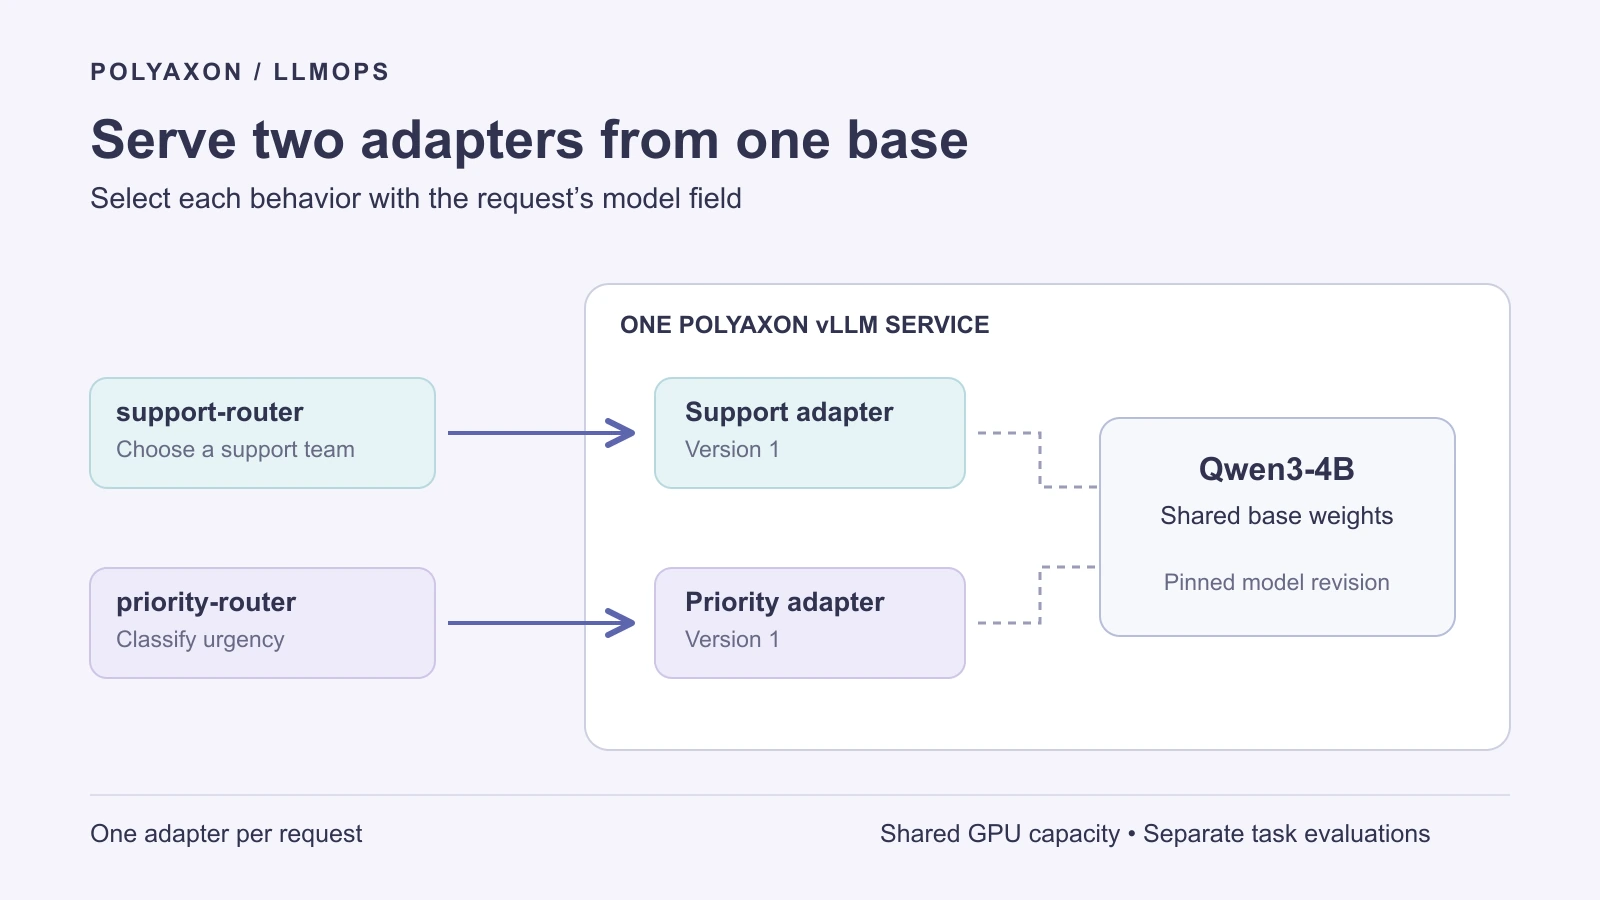
Deploy two task-specific LoRA adapters over one Qwen base model, select them by name, and measure quality and shared GPU capacity with Polyaxon.
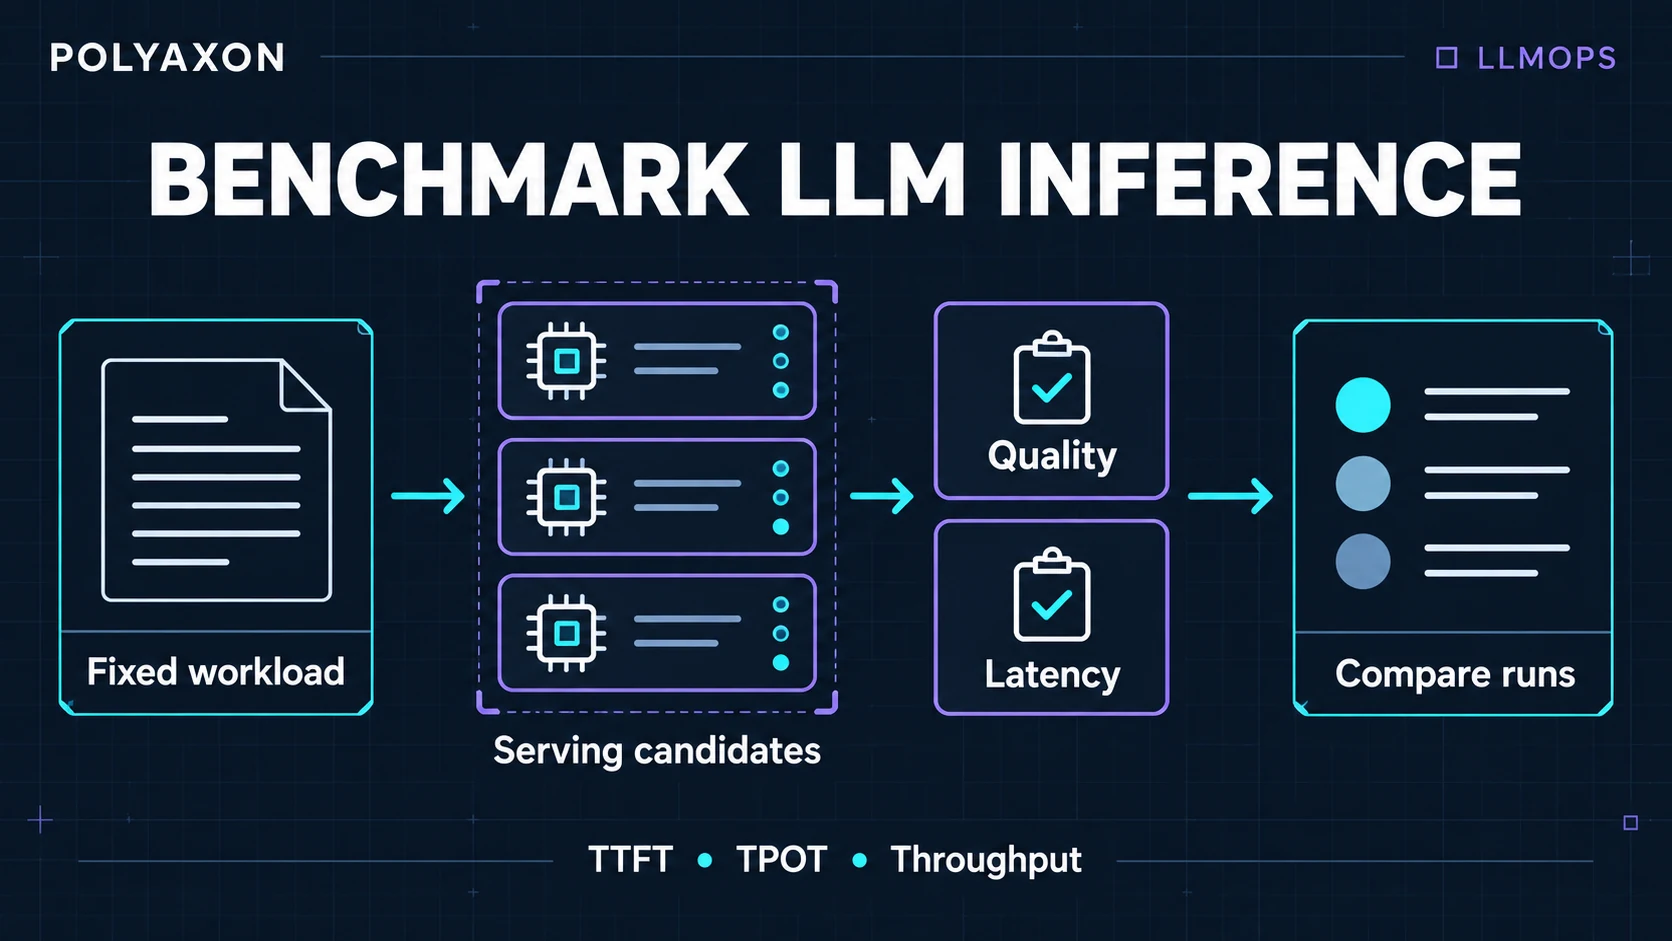
Understand exact prefix reuse in vLLM, structure repeated context, account for replica routing, and compare cold and warm workloads with Polyaxon.