Start large ML containers with lazy image pulling
Use eStargz and containerd for lazy image pulls, then measure a Polyaxon GPU job through its first completed CUDA operation.
KubernetesContainersPerformance
The latest guides, tutorials, and product updates.
Use eStargz and containerd for lazy image pulls, then measure a Polyaxon GPU job through its first completed CUDA operation.
Run synchronized training and inference workers on Polyaxon, compare MIG with time-slicing, and measure the shared interval rather than misleading solo utilization.
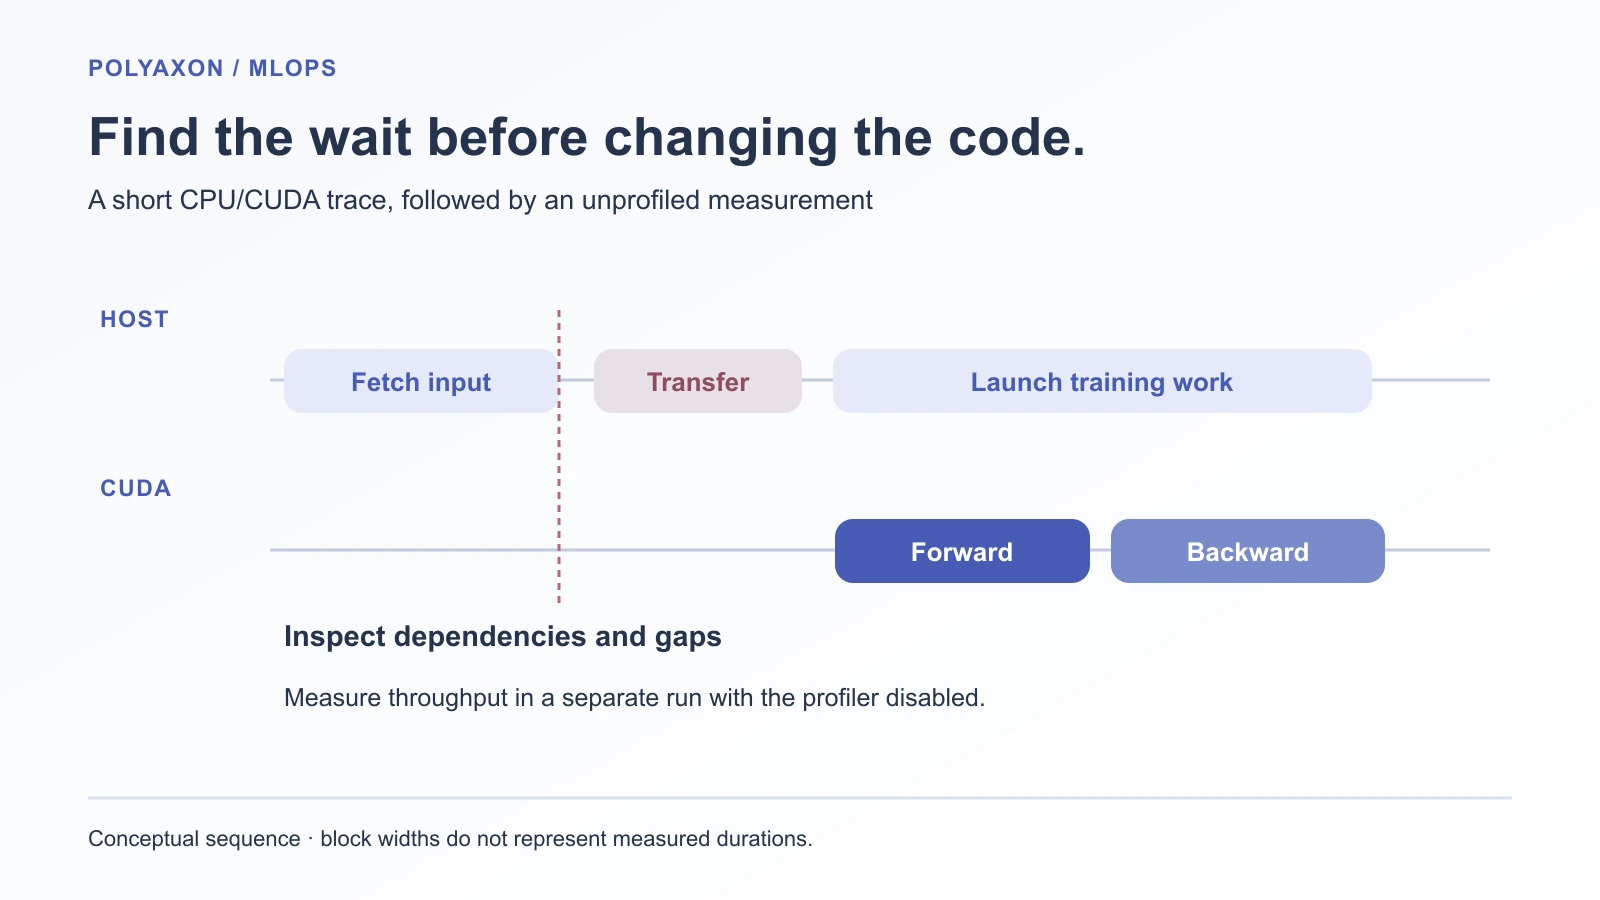
Capture a short CPU/CUDA trace, identify whether input loading or GPU work is delaying training, and measure a targeted change without profiler overhead.
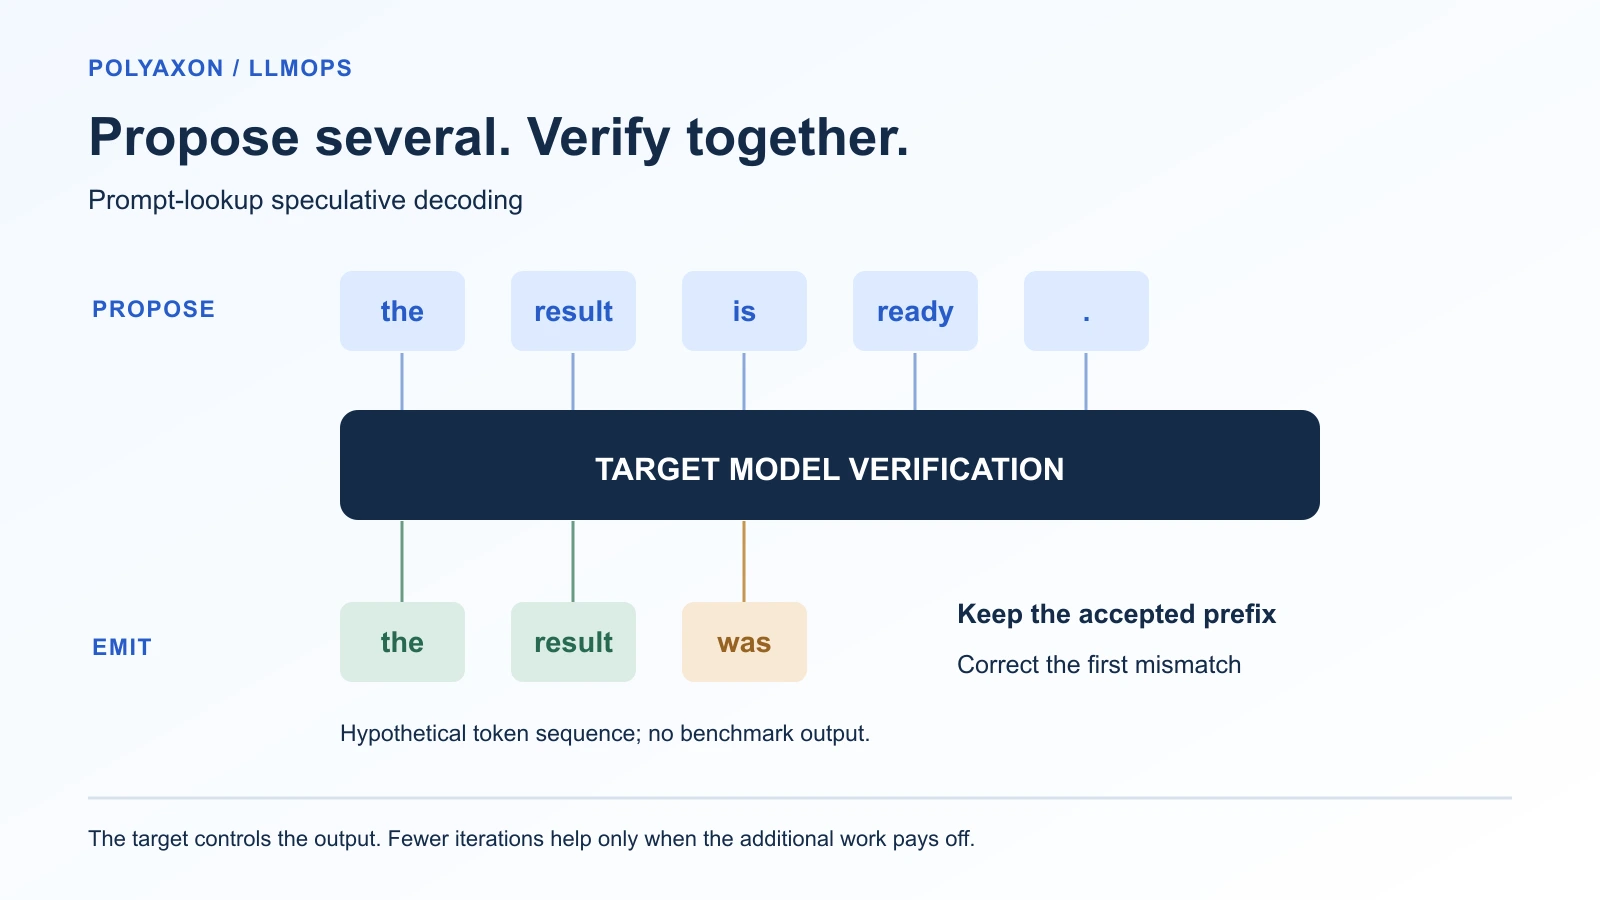
Compare ordinary decoding with prompt-lookup proposals under the same model, workload, and GPU allocation, including latency, failures, and output checks.
Combine CPU Manager eligibility, full-core allocation, and Topology Manager policy, then compare CPU/GPU workloads with Polyaxon.
Measure Polyaxon agent workflow bottlenecks across planning, queueing, execution, transfers, and evaluation using critical-path timing and quality-aware comparisons.
Keep Polyaxon sandbox services ready for active sessions while controlling idle cost, absolute lifetime, state persistence, and cleanup.
Reduce Polyaxon agent startup latency by measuring queueing, image preparation, initialization, and readiness before tuning capacity or workspace reuse.
Change persistent-volume performance profiles, inspect the completed change, and compare checkpoint behavior in Polyaxon GPU jobs.
Evaluate CPU inference using model fit, precision, latency, throughput, memory, Kubernetes placement, and end-to-end cost instead of assuming every model needs a GPU.