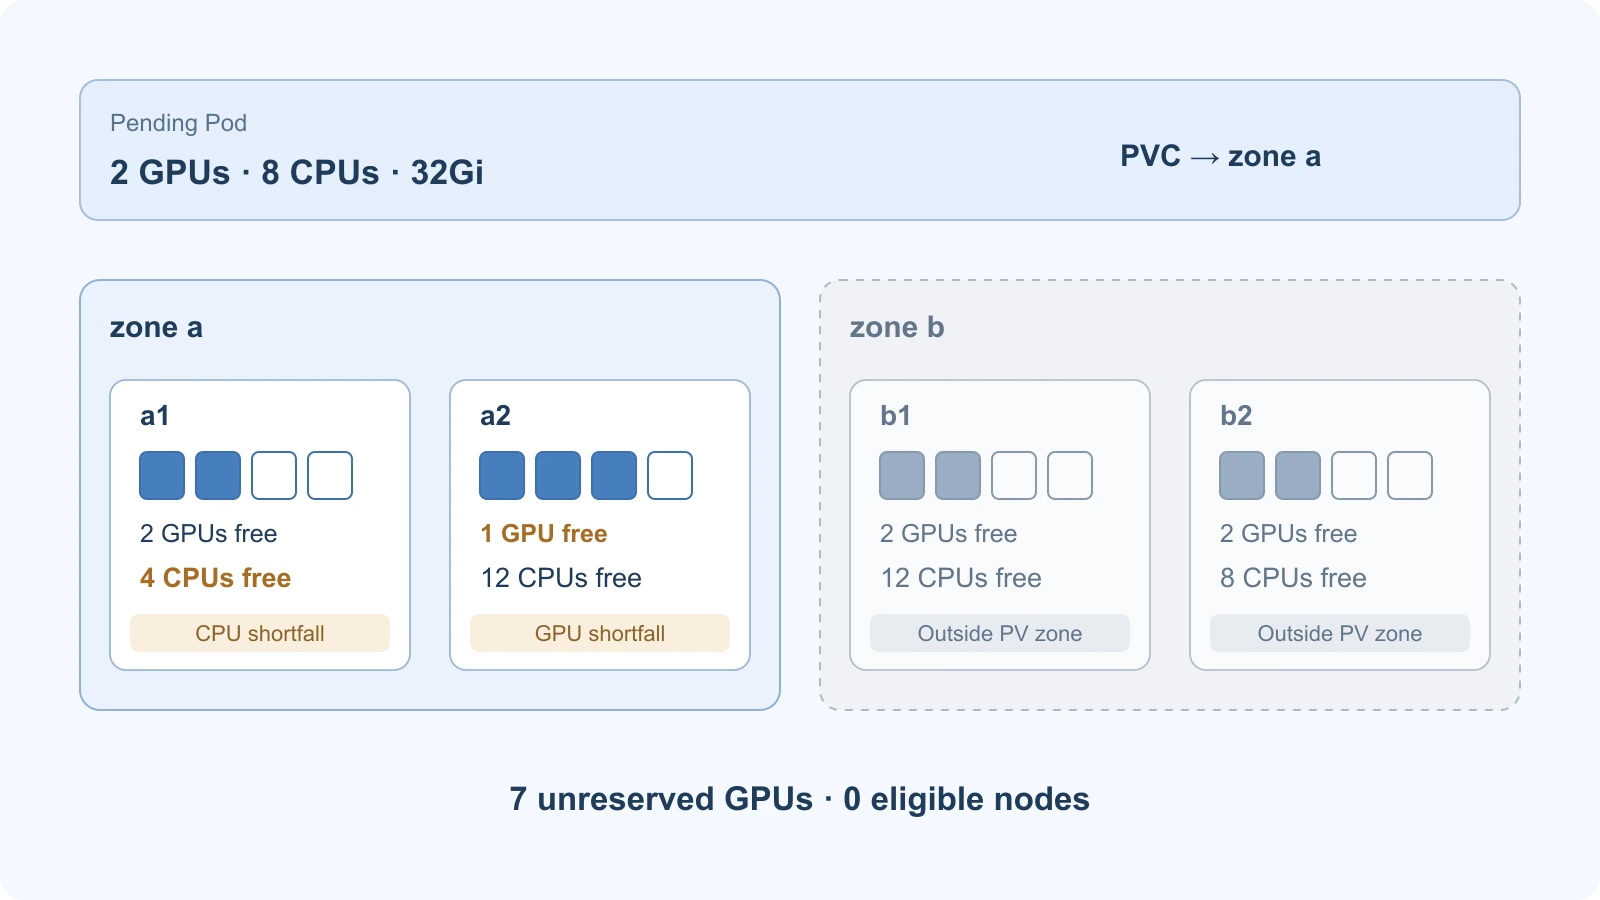
Diagnose a Pending GPU Pod across compute and storage
Work through a GPU placement case where available devices, CPU reservations, and volume topology leave no eligible node.
KubernetesGPUScheduling
The latest guides, tutorials, and product updates.
Work through a GPU placement case where available devices, CPU reservations, and volume topology leave no eligible node.
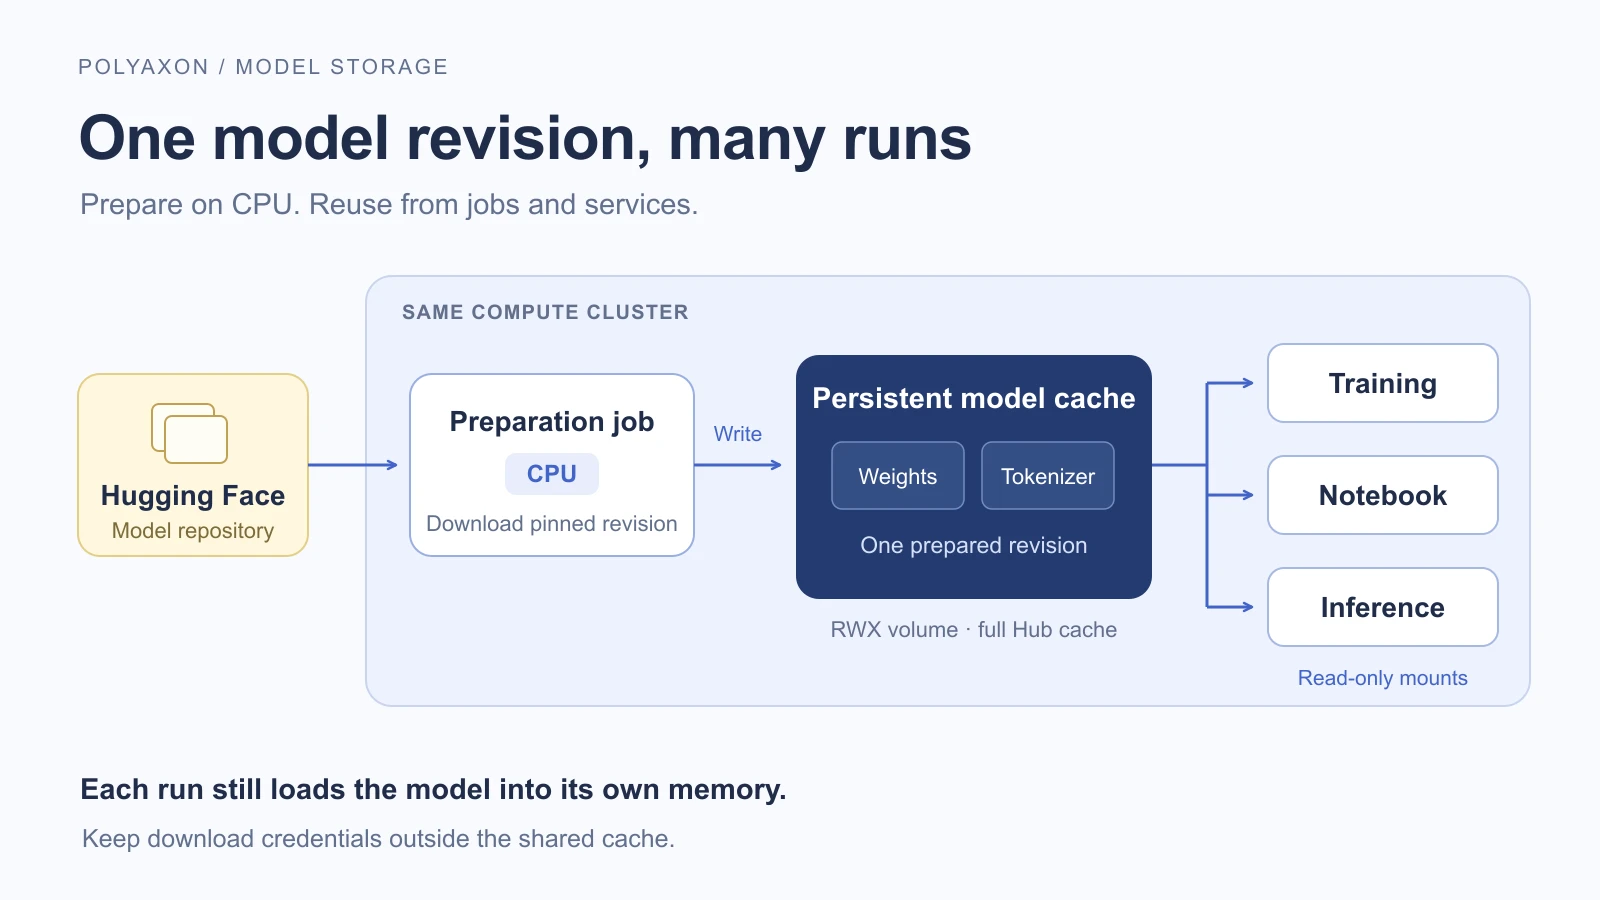
Prepare a pinned model revision in a CPU job, then reuse its files from read-only storage in Polyaxon training, notebook and inference workloads.
Use Kubernetes Job TTLs to bound finished workload retention, preserve logs and artifacts separately, and configure the same policy through Polyaxon.
Restrict a Kubernetes notebook workspace PVC to one Pod, mount it in a Polyaxon service, and hand access to a replacement notebook.
Separate immutable model files from the serving image with Kubernetes image volumes, and choose when an OCI artifact fits better than a download or PVC.
Create a CSI snapshot of a notebook workspace, restore it into a separate PVC, and verify files and application state before switching workspaces.

Persist agent memory outside Polyaxon sandbox lifetimes using application stores, scoped connections, versioned snapshots, and reproducible evaluation.
Choose appropriate lifetimes for agent process memory, sandbox files, persistent volumes, artifacts, and application state in Polyaxon.
Change persistent-volume performance profiles, inspect the completed change, and compare checkpoint behavior in Polyaxon GPU jobs.
Diagnose Kubernetes volume failures across claims, provisioning, topology, attachment, node mounts, permissions, and workload ownership.
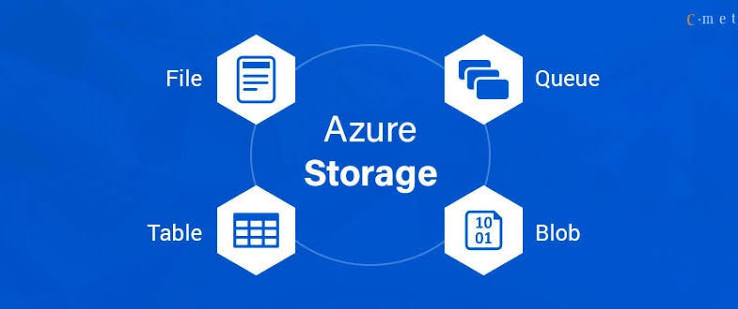
Design Azure Storage accounts for ML datasets and artifacts with clear boundaries, workload identities, network controls, lifecycle rules, and recovery tests.
Choose, size, monitor, and retire Google Cloud Persistent Disk volumes for training, notebooks, caches, and stateful ML services.