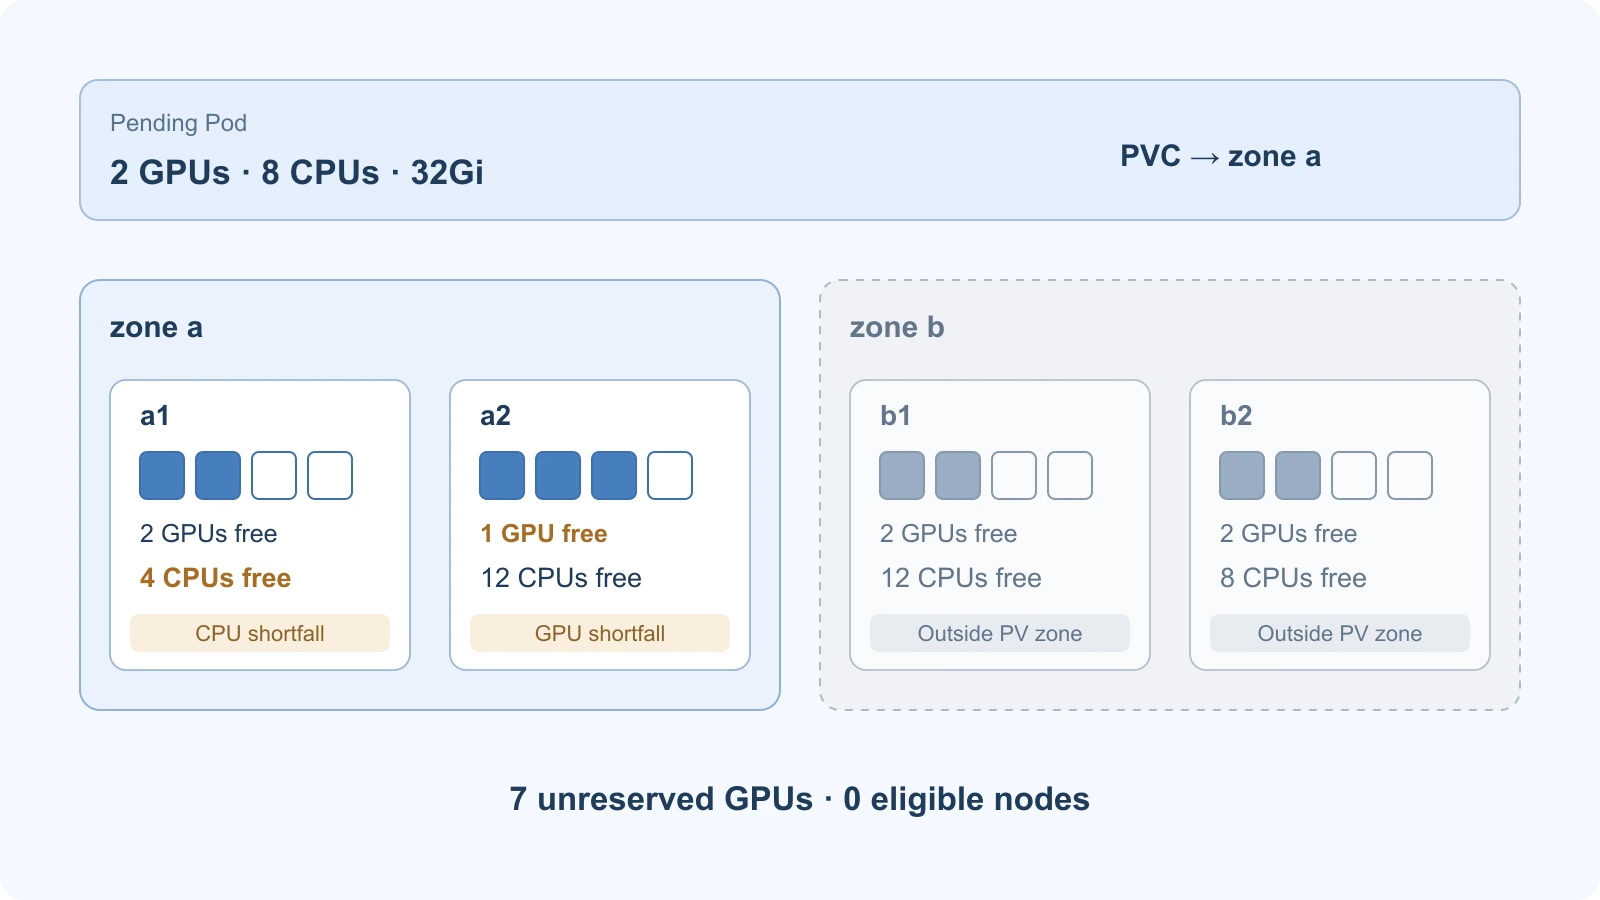
Diagnose a Pending GPU Pod across compute and storage
Work through a GPU placement case where available devices, CPU reservations, and volume topology leave no eligible node.
KubernetesGPUScheduling
The latest guides, tutorials, and product updates.
Work through a GPU placement case where available devices, CPU reservations, and volume topology leave no eligible node.
Inspect /dev/shm, size DataLoader prefetching, and configure shared memory for PyTorch jobs on Kubernetes and Polyaxon.
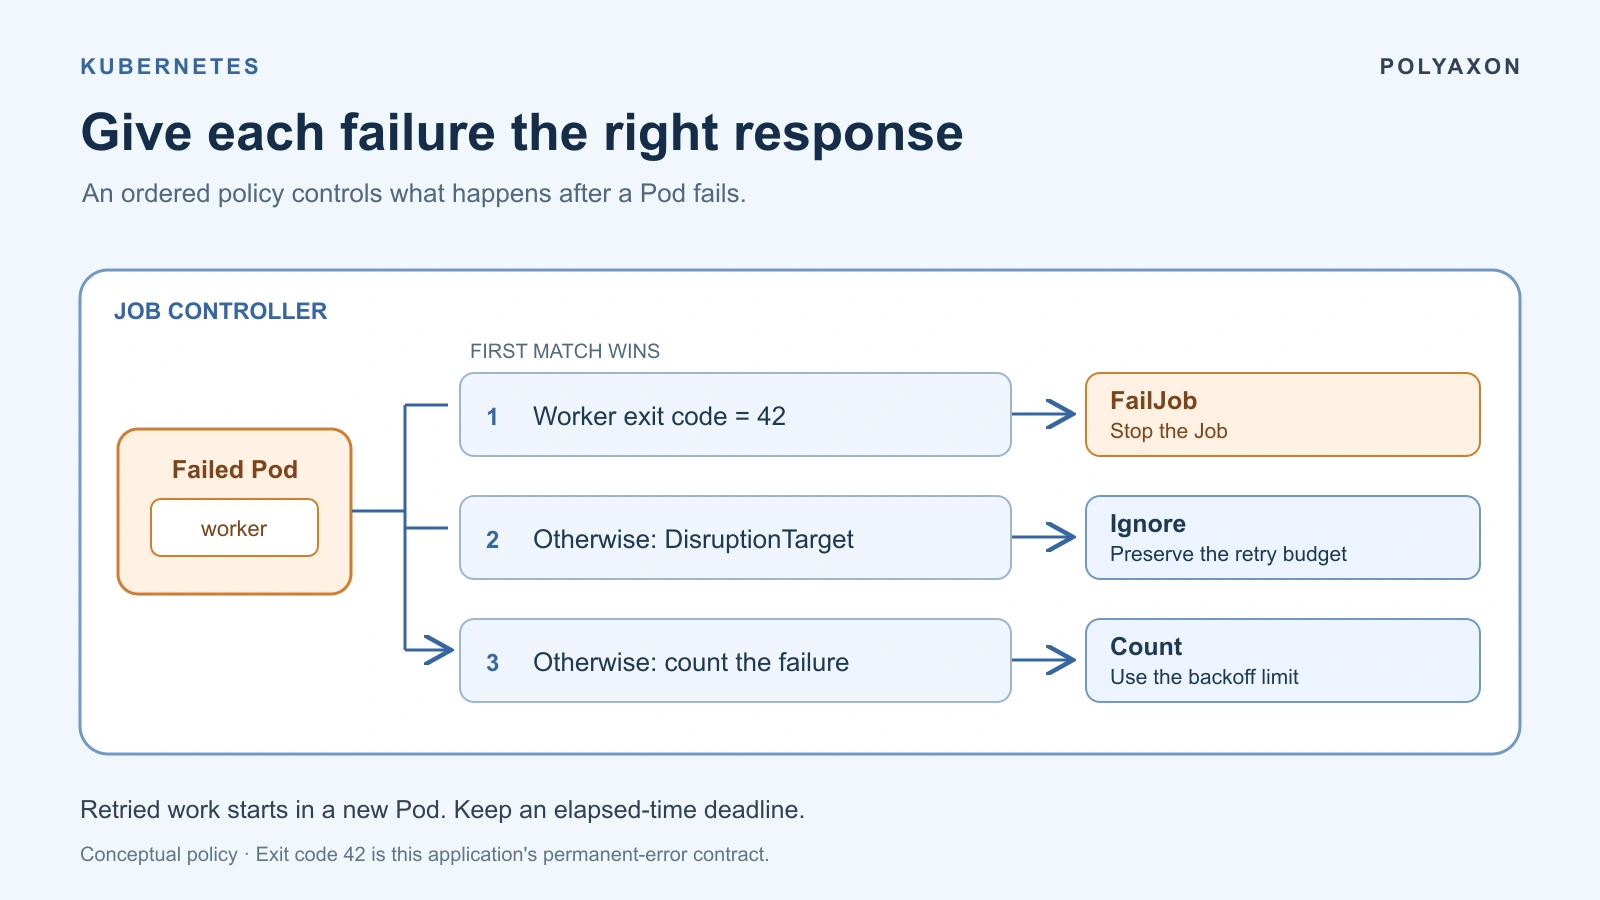
Stop retrying permanent errors, preserve the retry budget for marked disruptions, and inspect Kubernetes Job failure decisions with a concrete example.
Connect Kubernetes DRA allocations, device health, and application failures without confusing missing telemetry with healthy hardware.
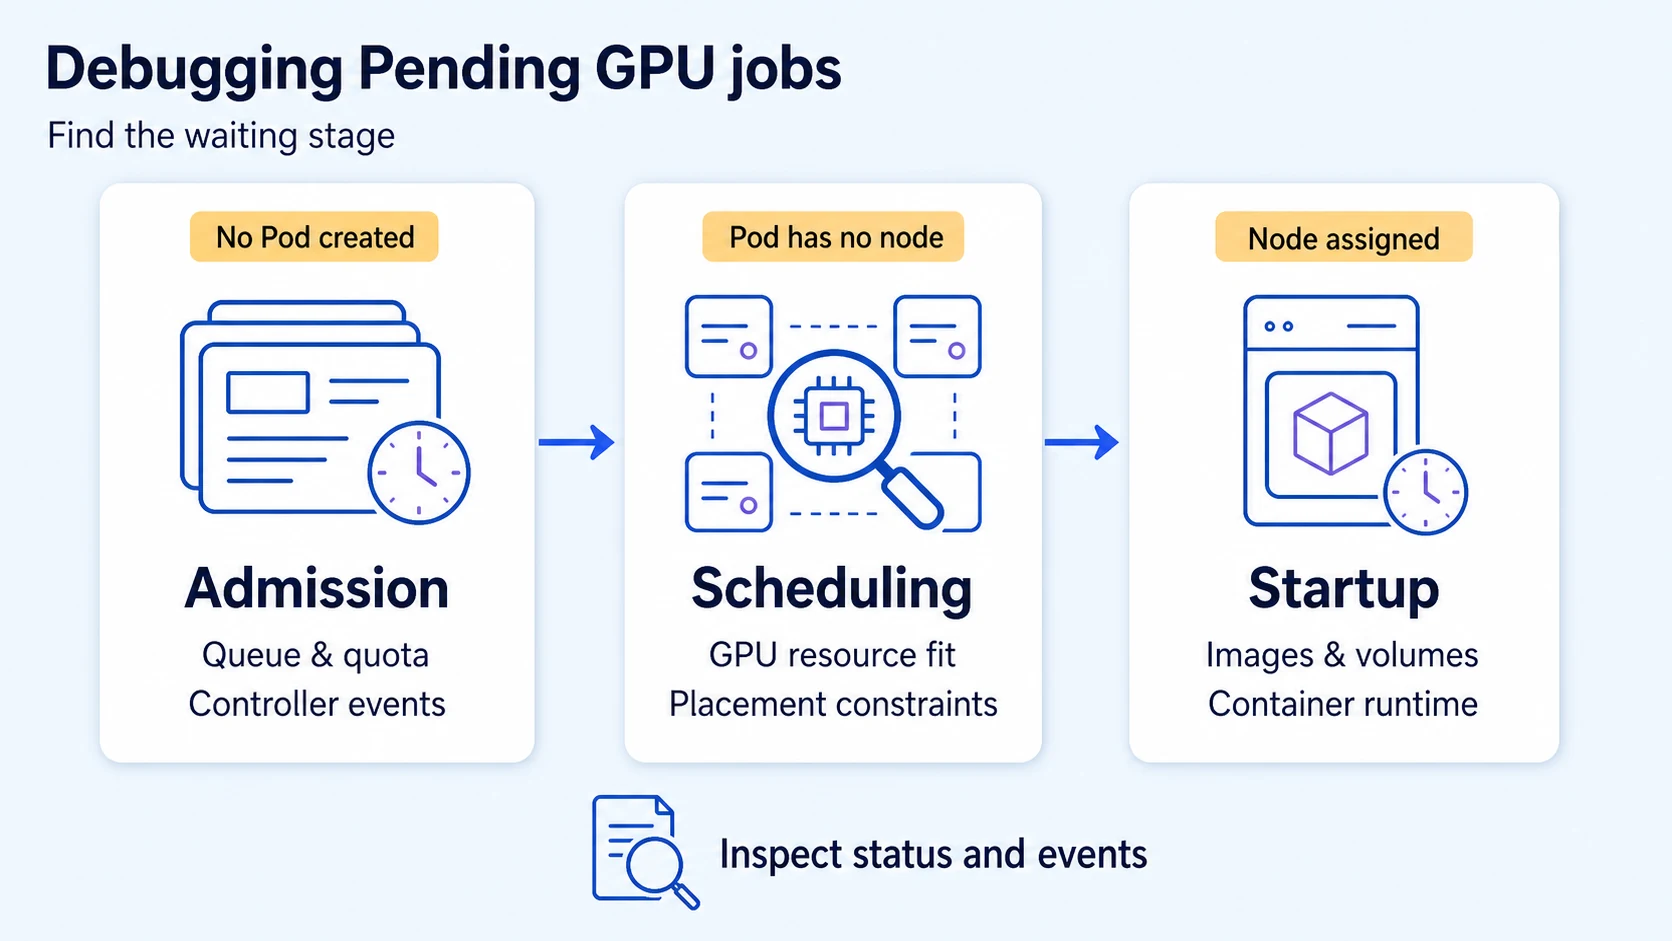
Diagnose Pending GPU jobs by checking queue admission, scheduler events, advertised GPU resources, placement constraints, storage, and node capacity.
Use container state, previous logs, events, probes, configuration, and resource evidence to find the cause behind CrashLoopBackOff.
Diagnose container memory limits, node pressure, application allocation, and ML data-loading behavior before changing Kubernetes resources.
Choose the correct restart path for Deployments, StatefulSets, Jobs, and standalone Pods while preserving evidence and workload ownership.