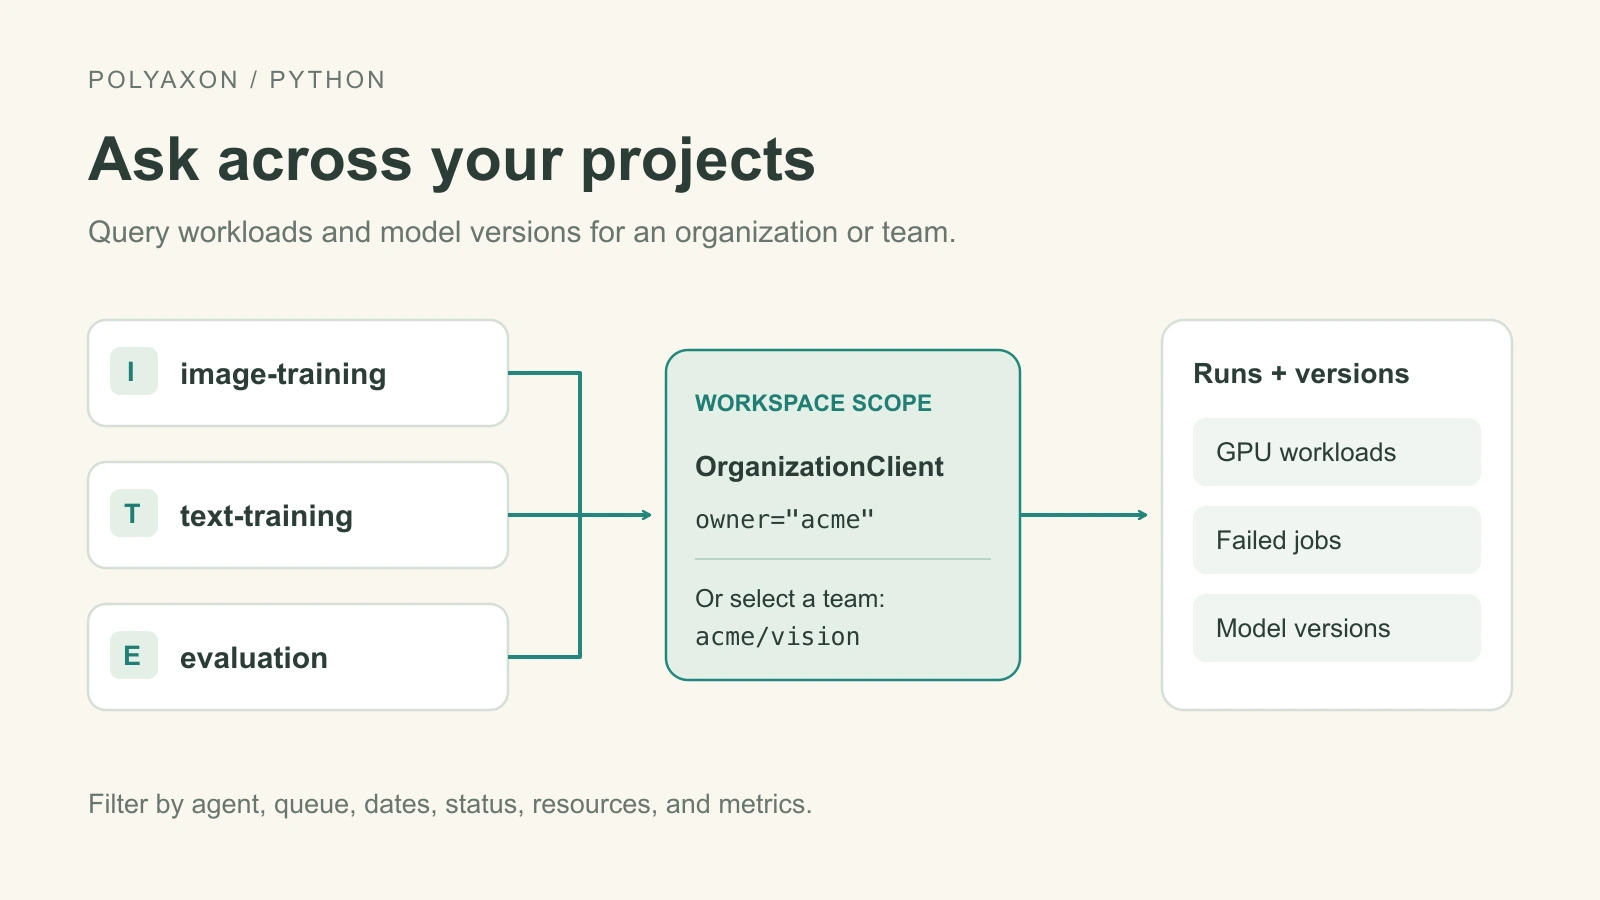
Query runs and model versions across projects
Use Polyaxon's organization and team APIs to inspect GPU workloads by agent, count model versions, and calculate job failure rates across projects.
PolyaxonPythonMonitoring
Page 2 of 2
Use Polyaxon's organization and team APIs to inspect GPU workloads by agent, count model versions, and calculate job failure rates across projects.
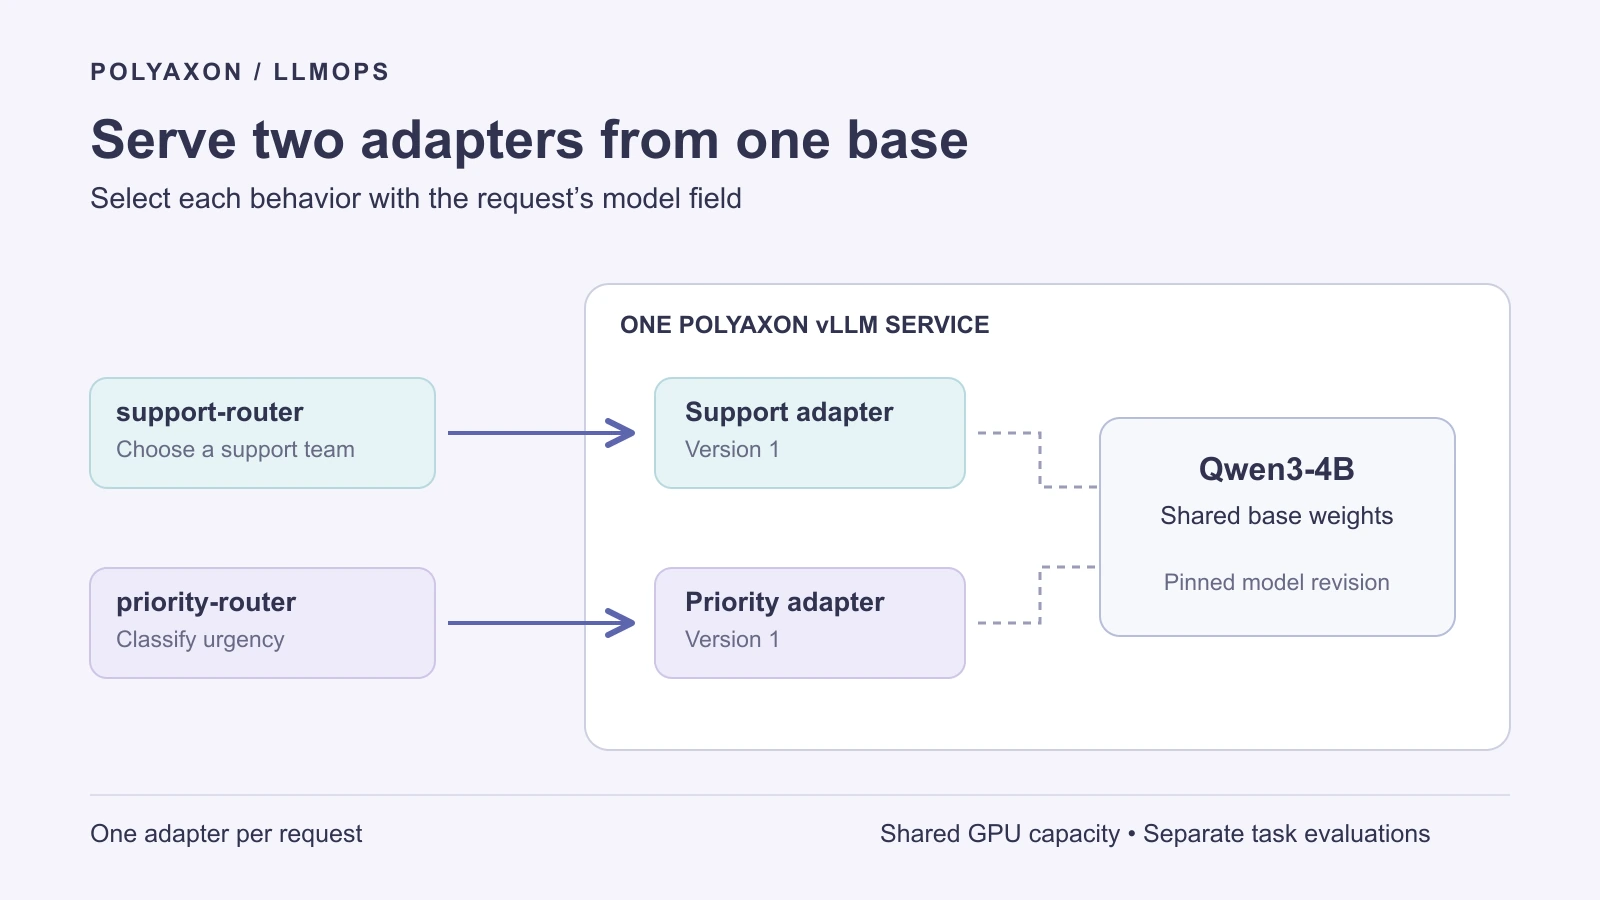
Deploy two task-specific LoRA adapters over one Qwen base model, select them by name, and measure quality and shared GPU capacity with Polyaxon.
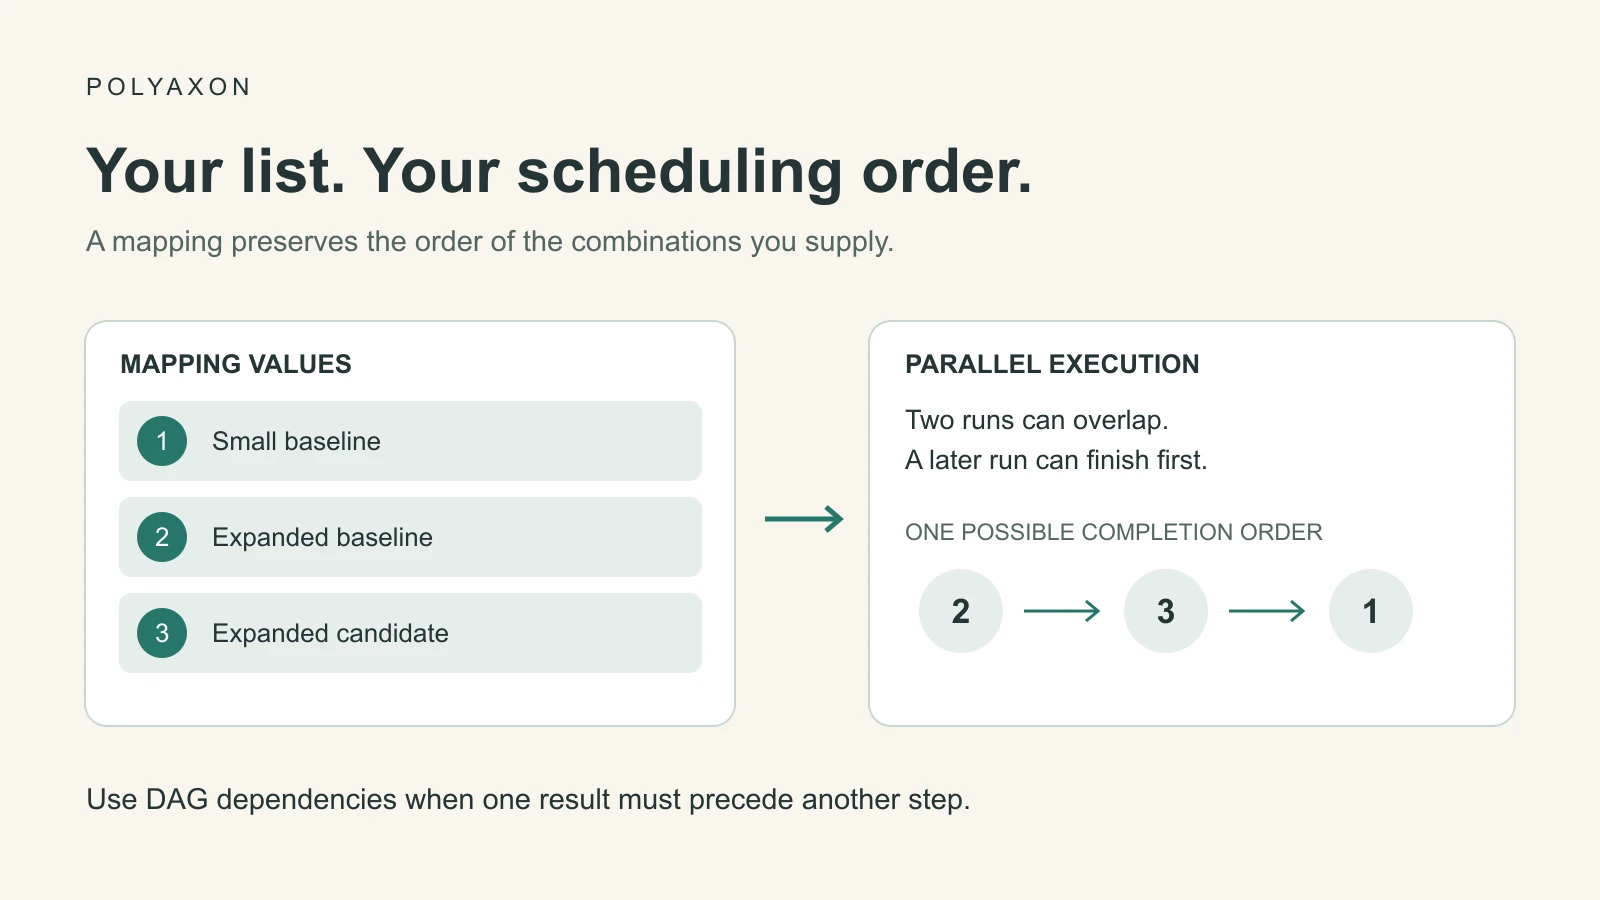
Use an ordered Polyaxon mapping for a curated list of experiments, control concurrency, and distinguish scheduling order from dependencies and completion order.
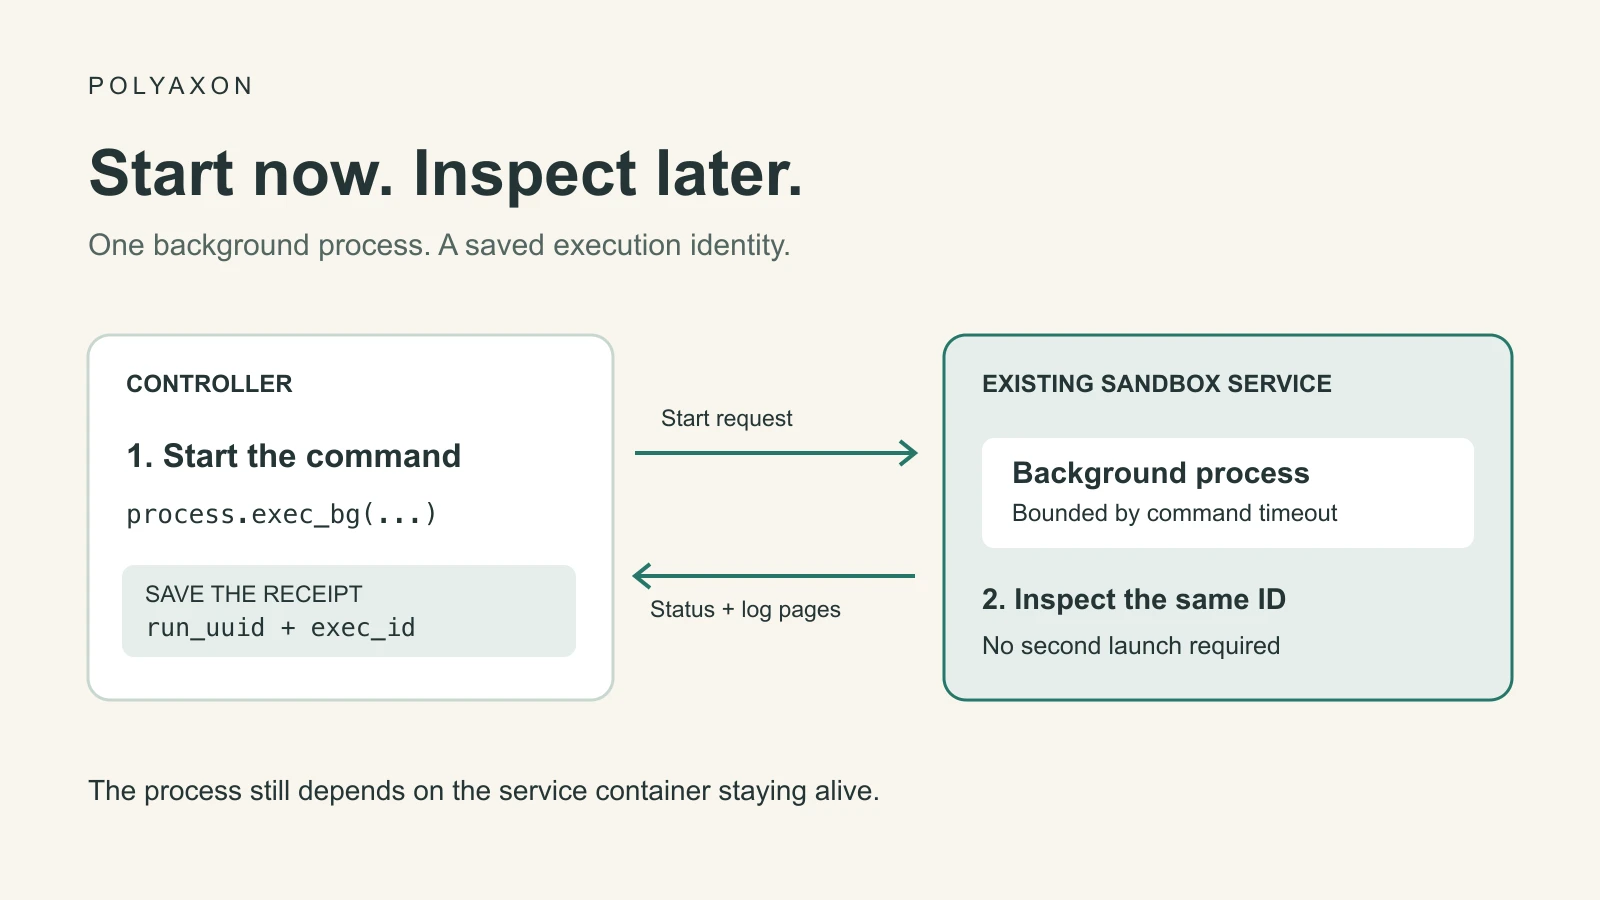
Start a background process, save its execution ID, reconnect to status and logs, and distinguish command limits from the lifetime of a Polyaxon sandbox.
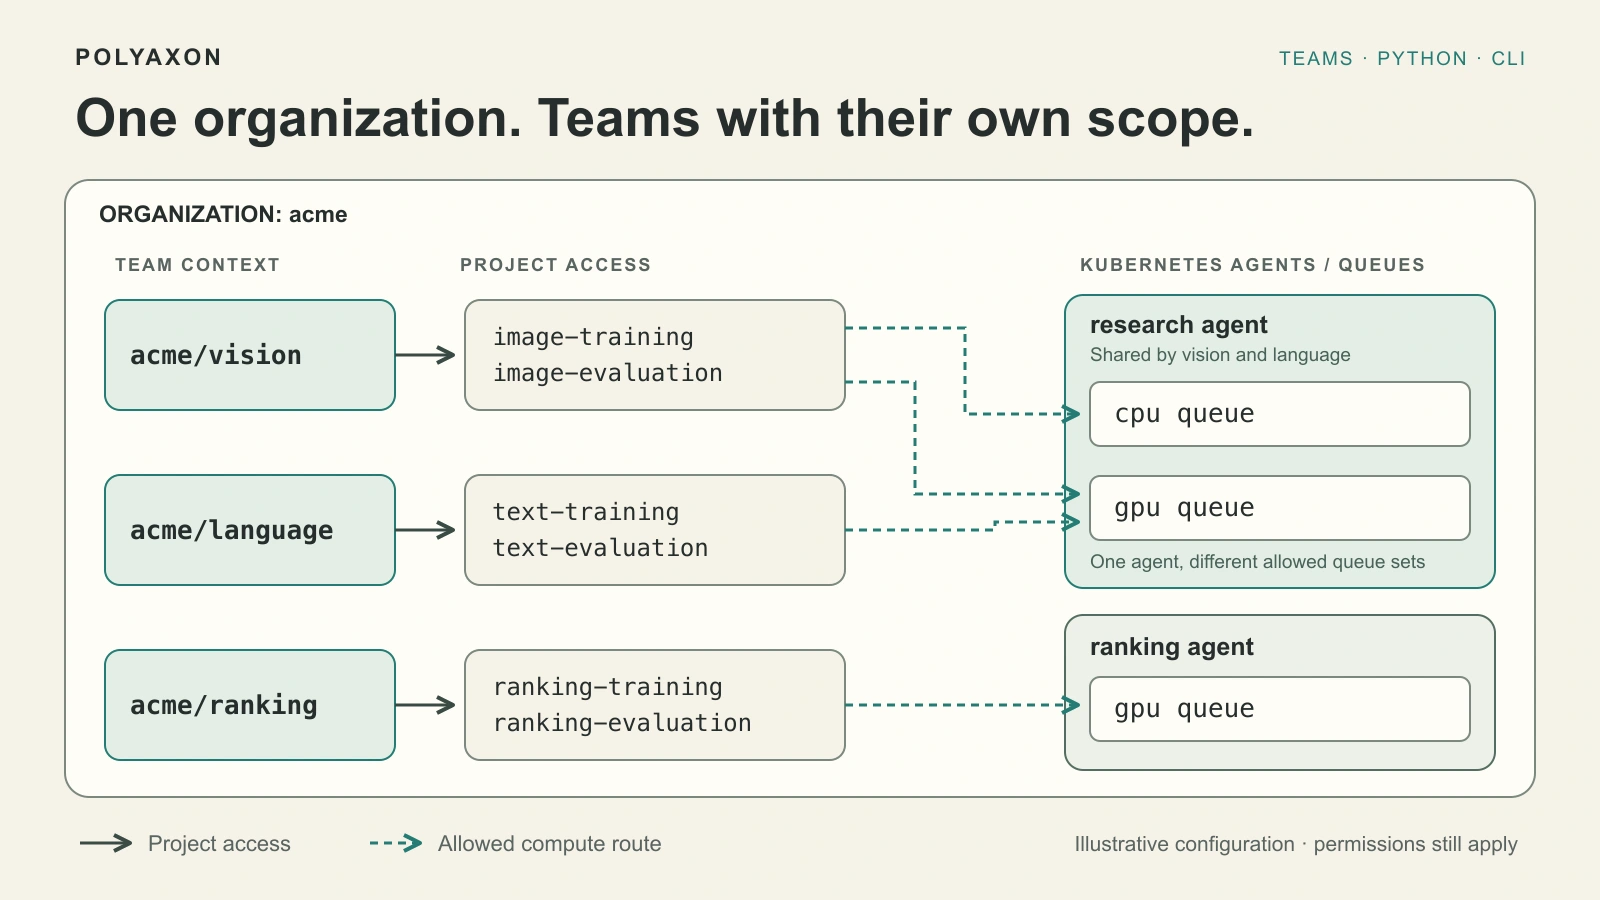
Scope Polyaxon Python clients and CLI commands to a team, review runs across its projects, and keep explicit project targets and saved defaults clear.
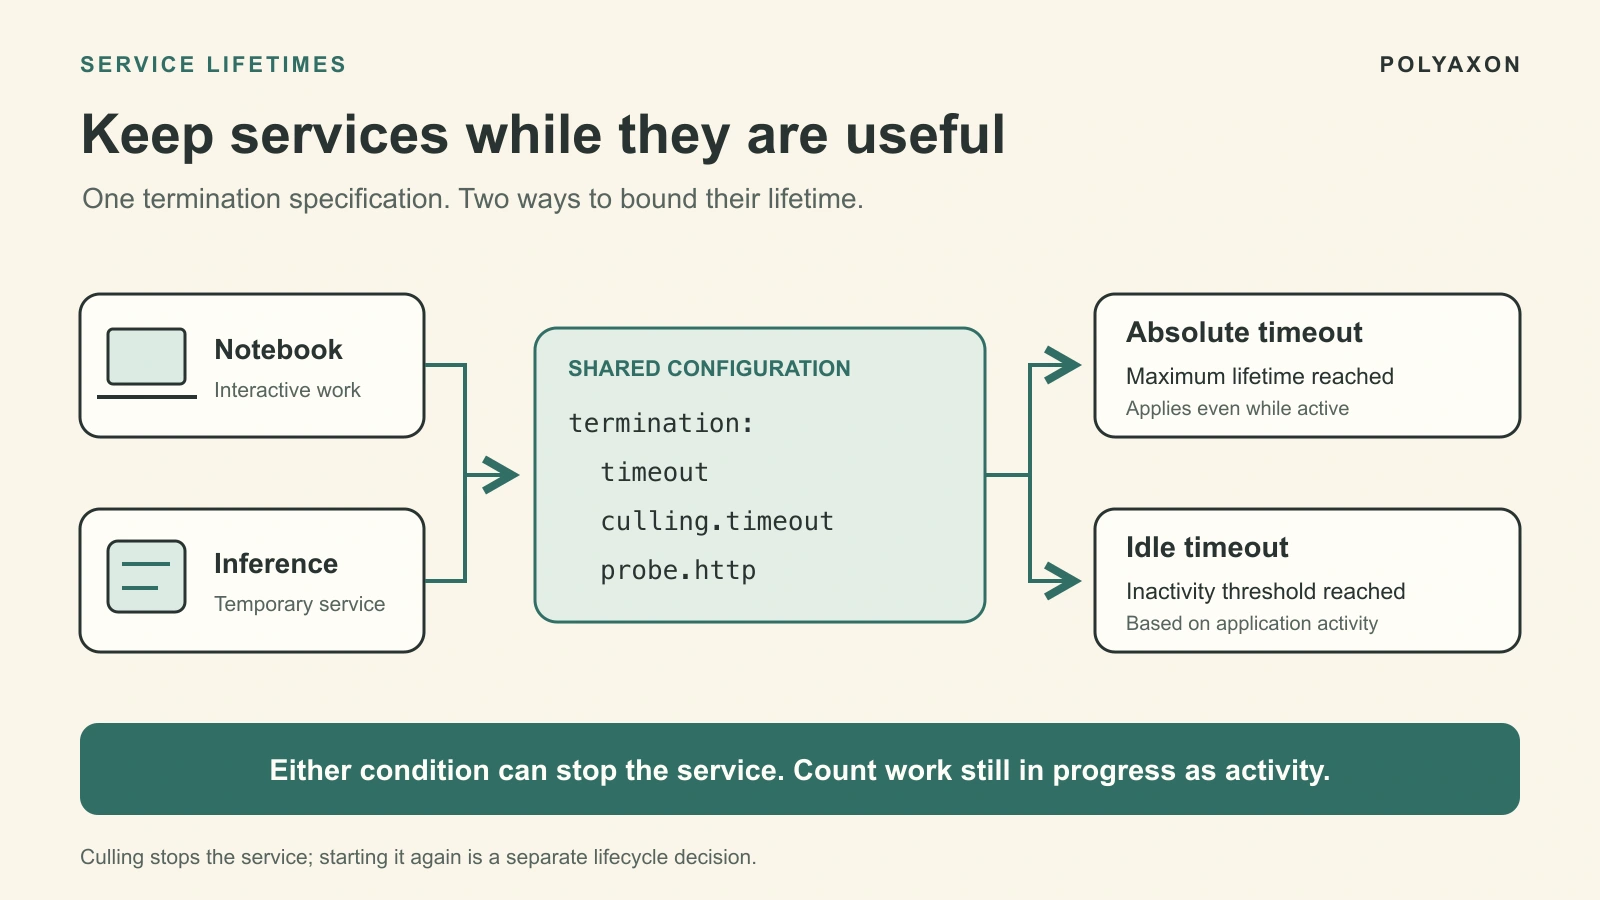
Reuse Polyaxon's termination specification to bound notebook and inference service lifetimes, stop idle services, and distinguish inactivity from ongoing work.
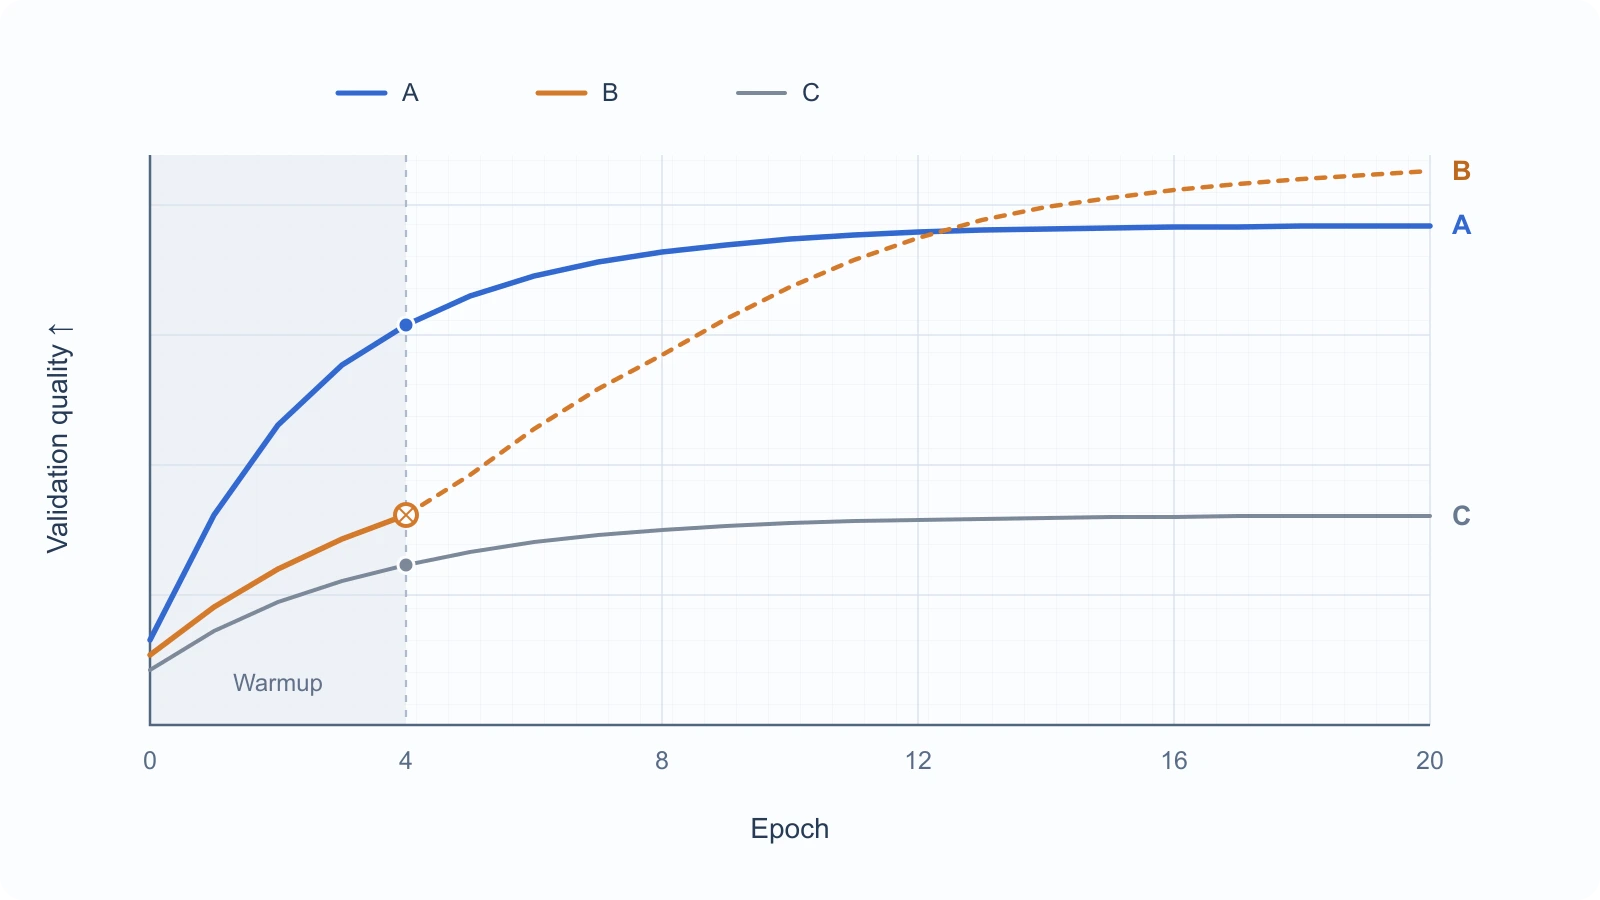
Calibrate early stopping against full training runs, compare equivalent training progress, and track pruning decisions with Polyaxon before enforcing them.
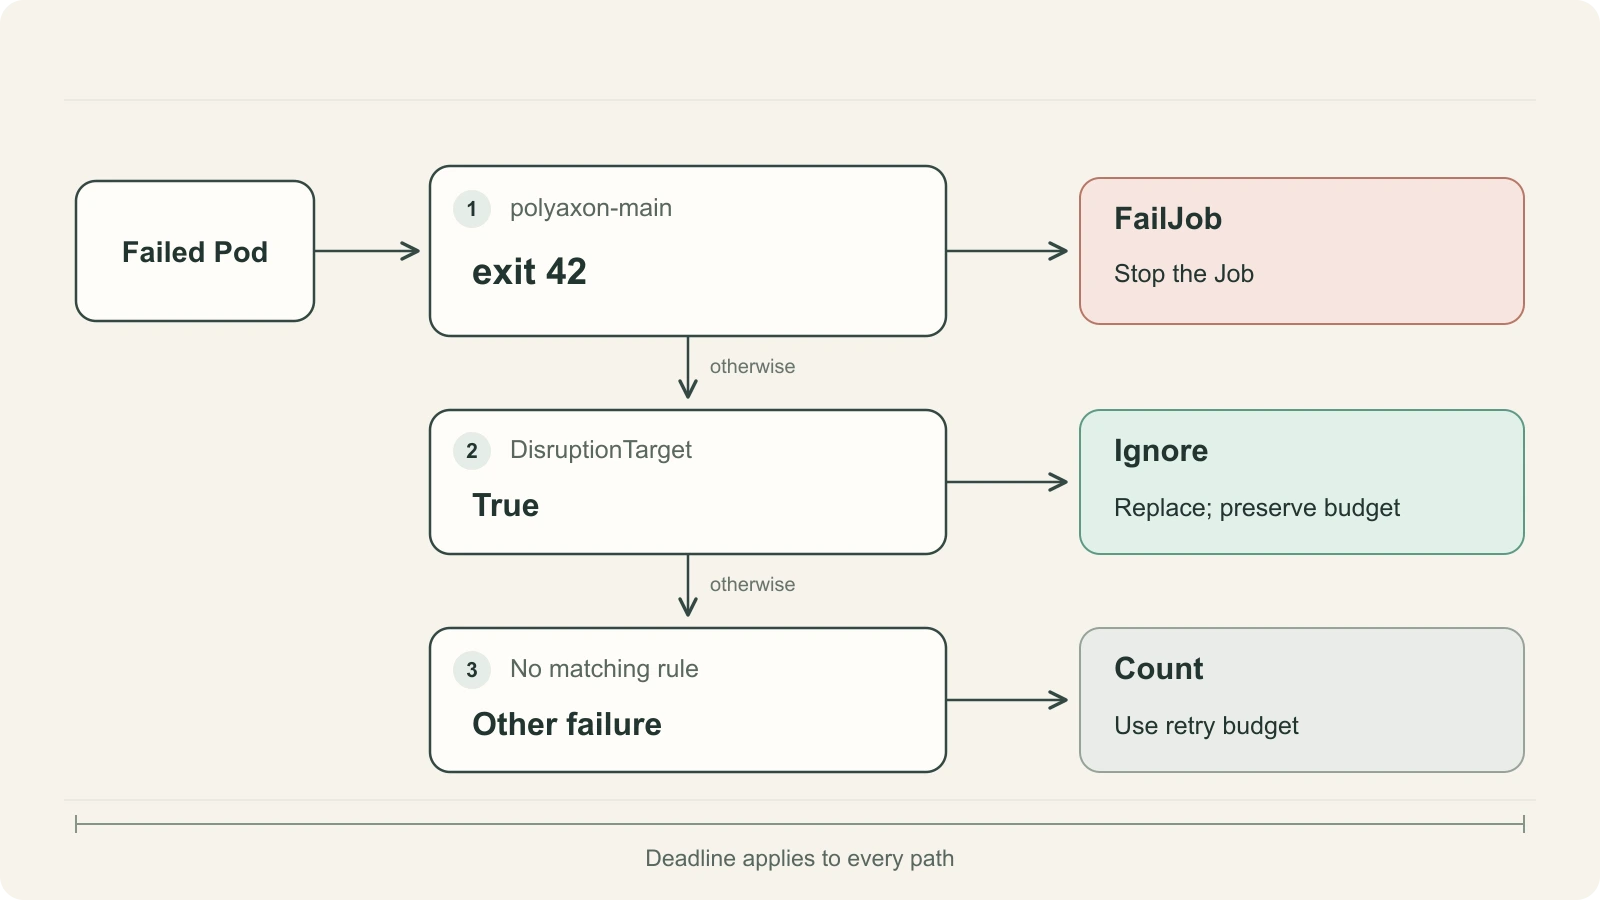
Use ordered Pod failure rules to stop permanent application errors, preserve the retry budget for marked disruptions, and bound replacement attempts.