When Kubernetes is the right platform for ML
Evaluate whether Kubernetes provides enough scheduling, isolation, portability, and operational leverage to justify its complexity for ML workloads.
KubernetesMLOpsGuides
Learn Kubernetes fundamentals, troubleshoot GPU workloads, and monitor ML infrastructure with practical guides for data scientists and platform engineers.
Page 4 of 8
Evaluate whether Kubernetes provides enough scheduling, isolation, portability, and operational leverage to justify its complexity for ML workloads.
Check kubectl, control-plane, node, and API compatibility before upgrades or while diagnosing inconsistent Kubernetes behavior.
Understand how Pods, Services, DNS, ingress, egress, and network policy shape the data paths used by training jobs and model services.
Configure Django logs for container collection, useful request context, exception diagnosis, privacy, and correlation with Kubernetes workload state.
Monitor Node.js services with request outcomes, event-loop delay, memory, dependencies, Kubernetes state, and low-cardinality telemetry.
Choose strategic merge, JSON merge, or JSON Patch deliberately, preview changes, and reconcile emergency Kubernetes patches with declarative configuration.
Keep ordinary Pods away from specialized nodes and combine tolerations with positive placement rules for GPU and interruptible ML capacity.
Understand how CRI runtimes, OCI images, low-level runtimes, RuntimeClass, and GPU integrations affect Kubernetes ML workloads.
Use PostStart and PreStop hooks without confusing them with initialization, readiness, durable events, or application-level shutdown handling.
Diagnose Kubernetes Pod sandbox failures by narrowing the problem to CNI networking, IP allocation, the container runtime, or node health.
Follow an ML workload through the API server, scheduler, controllers, kubelet, runtime, networking, storage, and platform add-ons.
Connect Polyaxon projects, access controls, compute queues, workload identities, and connection catalogs into a practical tenant isolation design.
Design identity, isolation, quotas, queues, networking, storage, and observability for multiple ML teams sharing Kubernetes infrastructure.
Use Polyaxon scheduling presets, workload identities, isolated compute, and run lineage to reduce and investigate container escape risk in AI execution.
Debug Kubernetes containers that terminate with exit code 1 by checking logs, commands, arguments, resources, and pod recreation behavior.
Design Polyaxon agent execution around bounded runs, scoped connections, workload identities, controlled compute environments, and recorded runtime evidence.
Use Polyaxon services, sandbox access, queues, presets, connections, and artifact workflows to configure repeatable AI development and execution environments.
Use native sidecar containers for tightly coupled helpers while keeping startup, shutdown, resources, security, and data ownership explicit.
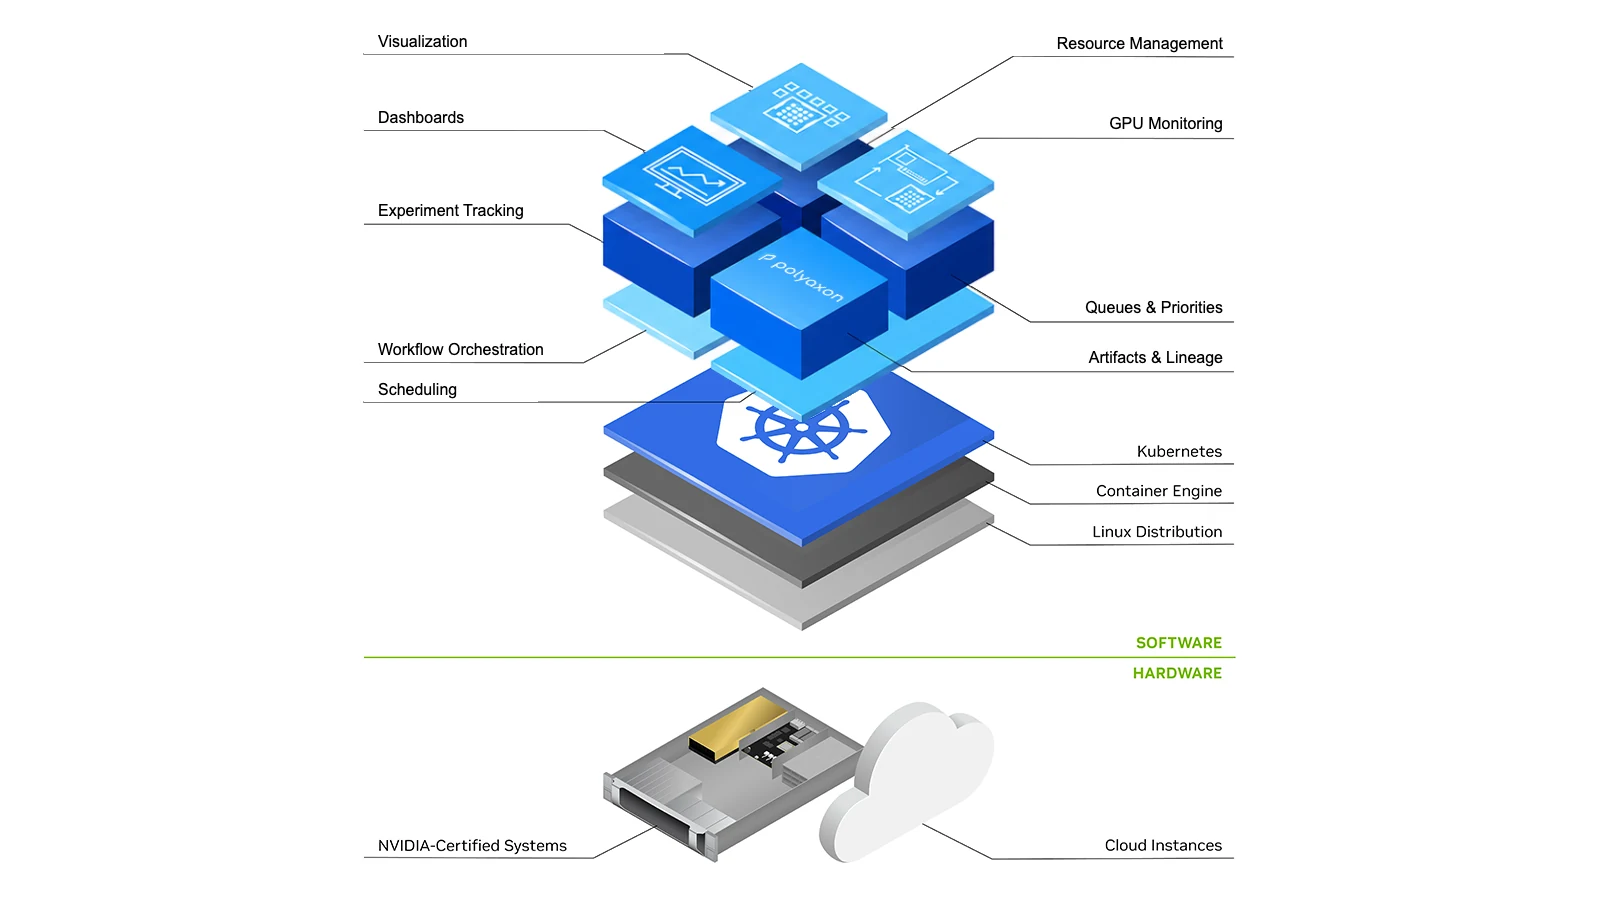
Make AI platforms ready for new accelerator generations through portable workload contracts, device-aware scheduling, topology, storage, compatibility, and migration evidence.
Monitor Kubernetes object state for ML workloads while separating desired state, resource usage, application outcomes, and high-cardinality metadata.
Design Kubernetes audit policy, collection, retention, and investigation workflows for shared ML clusters without recording sensitive payloads by default.
Connect Django request outcomes, database and cache health, worker behavior, Kubernetes state, and release context in one monitoring strategy.
Design container logs for local Docker debugging and Kubernetes collection without losing run context, exhausting nodes, or exposing sensitive data.
Schedule repeatable Kubernetes jobs with explicit time zones, concurrency, deadlines, history limits, idempotency, and observable outcomes.