Helm charts for ML platforms
Design, review, release, and operate Helm charts for ML platforms with predictable values, secure templates, upgrades, and ownership.
KubernetesGuides
Learn Kubernetes fundamentals, troubleshoot GPU workloads, and monitor ML infrastructure with practical guides for data scientists and platform engineers.
Page 6 of 8
Design, review, release, and operate Helm charts for ML platforms with predictable values, secure templates, upgrades, and ownership.
Build container image scanning into ML delivery with digest pinning, SBOMs, provenance, policy, remediation ownership, and runtime controls.
Decide whether a service mesh fits your ML platform, then design traffic policy, identity, observability, rollout, and failure behavior deliberately.
Diagnose ImagePullBackOff through Pod events, immutable image references, registry credentials, node networking, rate limits, and platform configuration.
Use kubectl exec and ephemeral containers for targeted Kubernetes debugging without losing evidence, mutating workloads, or bypassing platform controls.
Diagnose Kubernetes NotReady nodes through conditions, heartbeats, kubelet, runtime, networking, pressure, cloud health, and workload impact.
Choose between one Kubernetes cluster and multiple clusters using isolation, failure domains, data locality, accelerator access, operations, and cost.
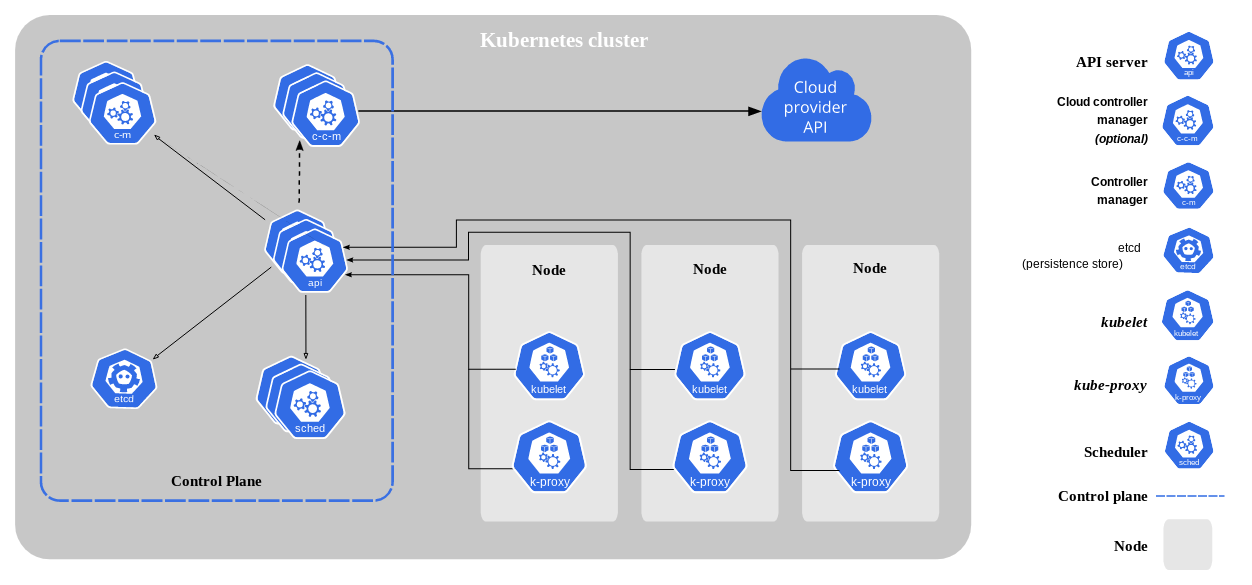
Understand how nodes, Pods, and containers divide responsibility for resources, lifecycle, networking, storage, and failures in Kubernetes ML systems.
Design Redis on Kubernetes around workload semantics, persistence, topology, memory, security, recovery, and observable operation for ML systems.
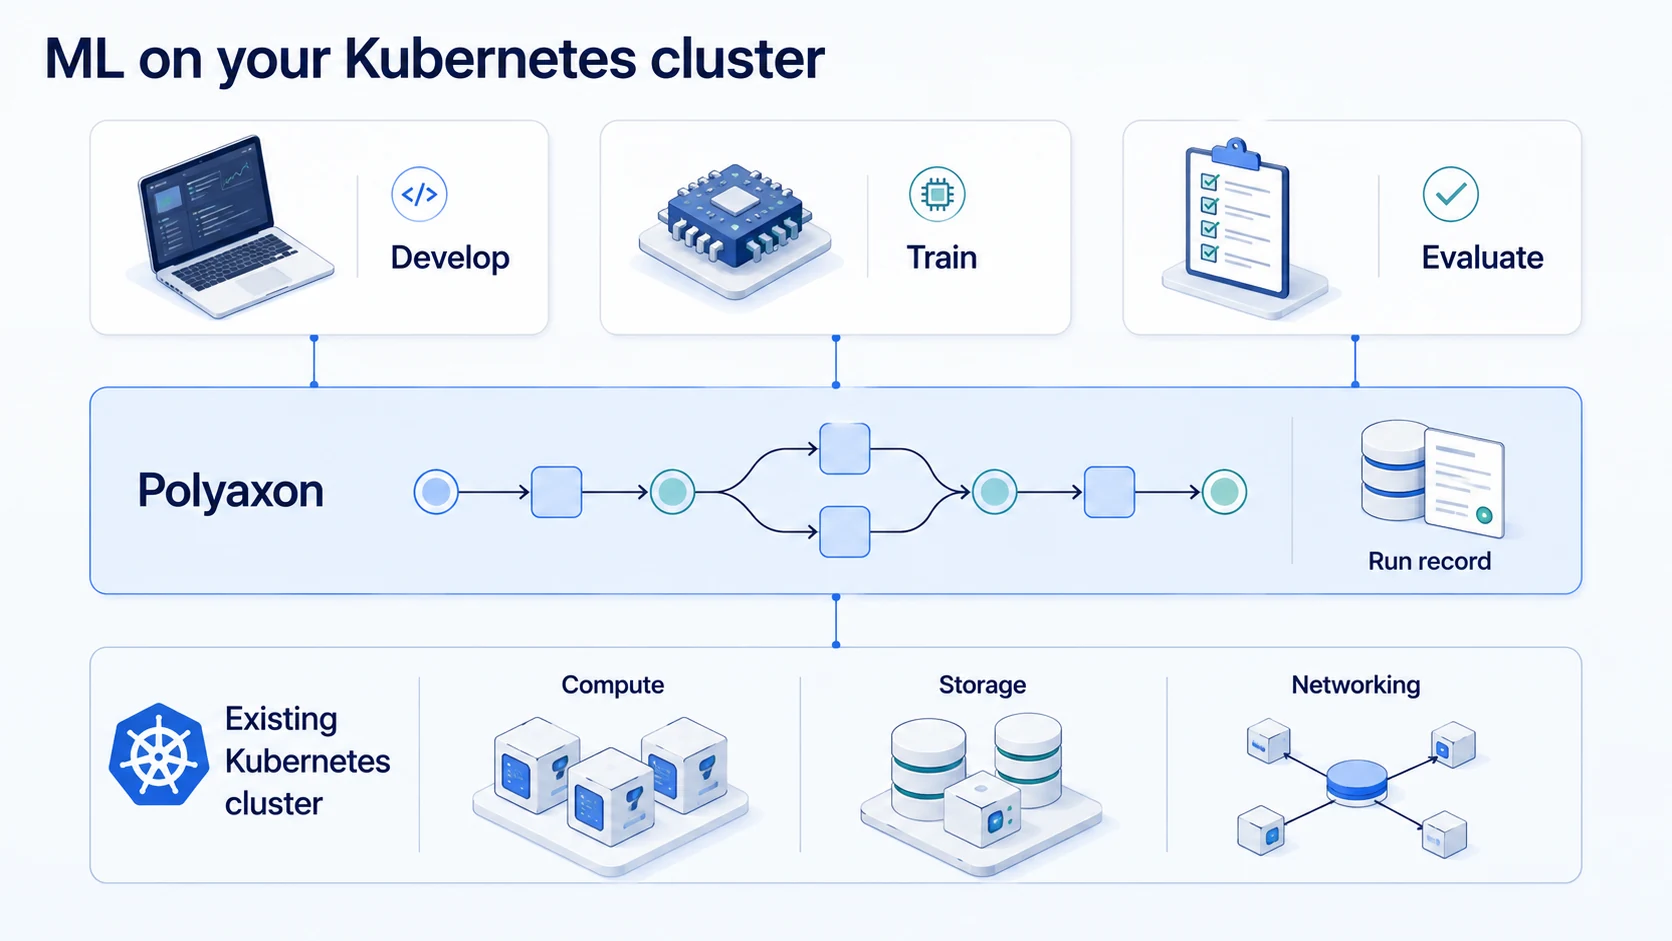
Decide whether Kubernetes fits your ML platform, then migrate workload contracts, storage, scheduling, security, and operations in controlled stages.
Use practical kubectl commands to inspect, diagnose, and manage Kubernetes ML workloads with explicit contexts, namespaces, and safer change habits.
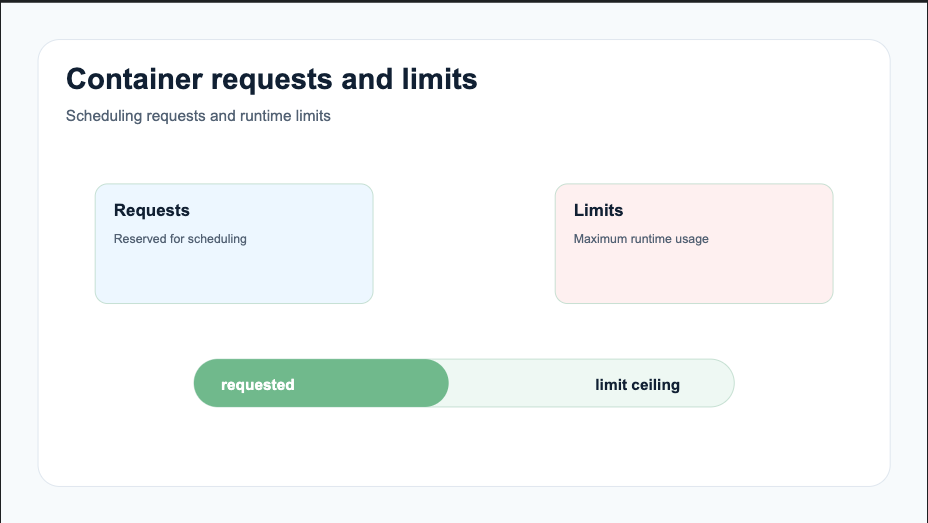
Set CPU, memory, ephemeral-storage, and GPU resources from measured ML workload behavior while preserving scheduling efficiency and reliability.
Use container state, previous logs, events, probes, configuration, and resource evidence to find the cause behind CrashLoopBackOff.
Evaluate observability tools by signals, Kubernetes context, ML workload coverage, operating model, cost, security, and incident workflow.
Turn short-lived Kubernetes events into durable incident evidence and low-noise alerts without treating them as a complete observability system.
Understand when kubectl create, client-side apply, and server-side apply fit—and how field ownership affects safe Kubernetes automation.
Diagnose container memory limits, node pressure, application allocation, and ML data-loading behavior before changing Kubernetes resources.
Distinguish node-pressure, API-initiated, preemption, and node-failure disruptions, then design ML workloads to recover safely.
Container orchestration automates scheduling, scaling, networking, and recovery for containerized applications running across clusters.
Protect ML credentials with encryption, least-privilege access, workload identity, controlled delivery, rotation, and Polyaxon connections.
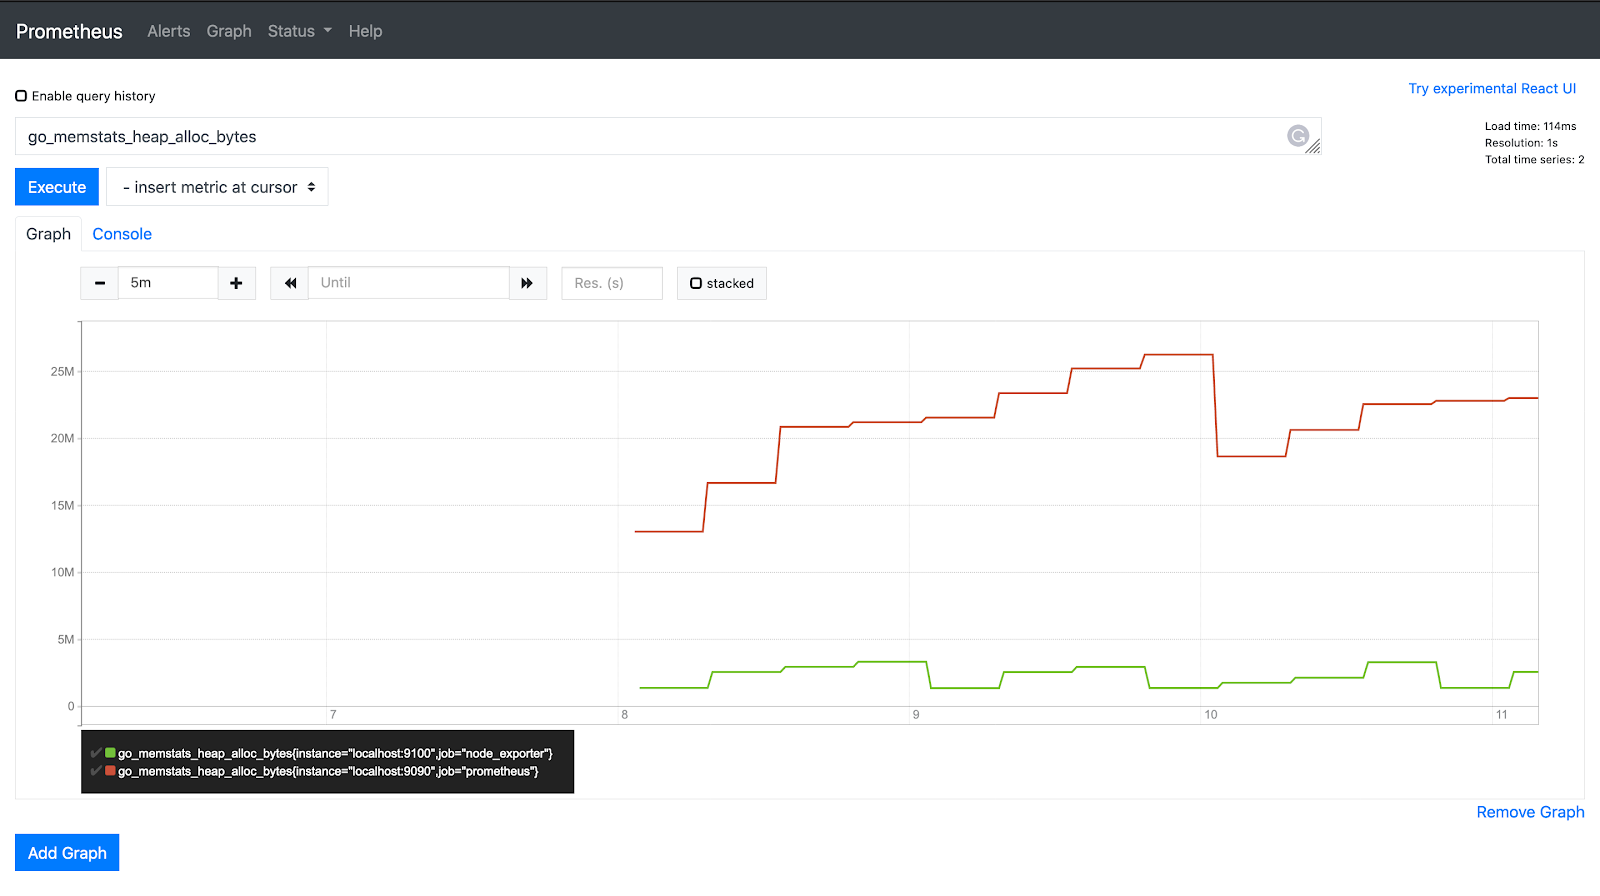
Use practical PromQL patterns for Kubernetes capacity, workload reliability, latency, and ML operations while controlling cardinality.
Evaluate database placement for ML platforms across operational ownership, storage, availability, recovery, upgrades, security, and performance.
Design labels, selectors, and annotations that connect Kubernetes resources to ML ownership and operations without breaking controllers or metrics.
Choose the correct restart path for Deployments, StatefulSets, Jobs, and standalone Pods while preserving evidence and workload ownership.