Kubernetes alerting practices for ML platforms
Design actionable Kubernetes alerts for ML services, batch operations, shared capacity, and the monitoring pipeline itself.
KubernetesMonitoringMLOps
Learn Kubernetes fundamentals, troubleshoot GPU workloads, and monitor ML infrastructure with practical guides for data scientists and platform engineers.
Page 7 of 8
Design actionable Kubernetes alerts for ML services, batch operations, shared capacity, and the monitoring pipeline itself.
Turn Kubernetes into a developer platform with product discovery, workload contracts, self-service templates, secure defaults, actionable diagnostics, and measurable adoption.
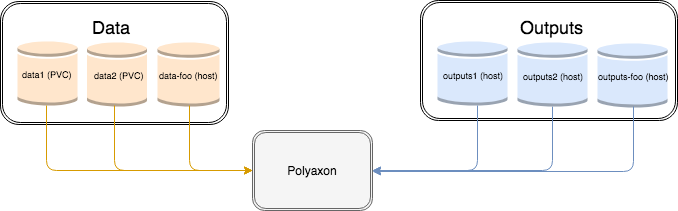
Diagnose Kubernetes volume failures across claims, provisioning, topology, attachment, node mounts, permissions, and workload ownership.
Learn the Kubernetes control model, core workload and infrastructure objects, and the capabilities an ML platform must add above the cluster.
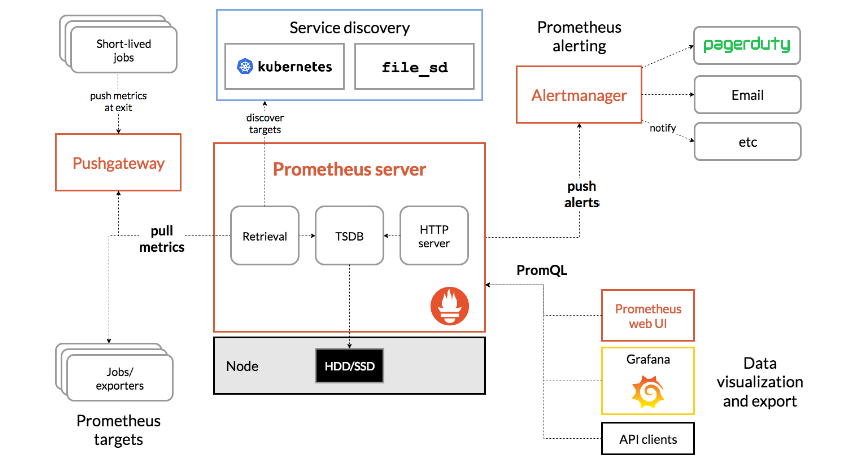
Build a useful Prometheus monitoring model across Kubernetes objects, nodes, containers, applications, and ML operations without uncontrolled cardinality.
Understand where eBPF adds kernel-level visibility in Kubernetes, which questions it can answer, and how to operate it safely for ML workloads.
Production Kubernetes needs monitoring, RBAC, resource controls, versioned manifests, and operational discipline. This guide covers the checks that matter.
Learn how Kubernetes operators extend the API to manage application lifecycle, stateful systems, upgrades, backups, and automation.
A practical guide to Kubernetes monitoring layers, useful metrics, workload visibility, and the limits of raw cluster telemetry.
Connect NGINX metrics to Prometheus with the NGINX Prometheus exporter and configure scraping for basic service monitoring.
Use kubectl delete safely for Kubernetes resources, files, labels, namespaces, force deletion, and cleanup workflows.
Learn how Prometheus exporters expose third-party metrics, how to build a simple exporter, and what practices keep metrics useful.
Understand Prometheus metric types, collection architecture, storage behavior, custom metrics, and Kubernetes monitoring use cases.
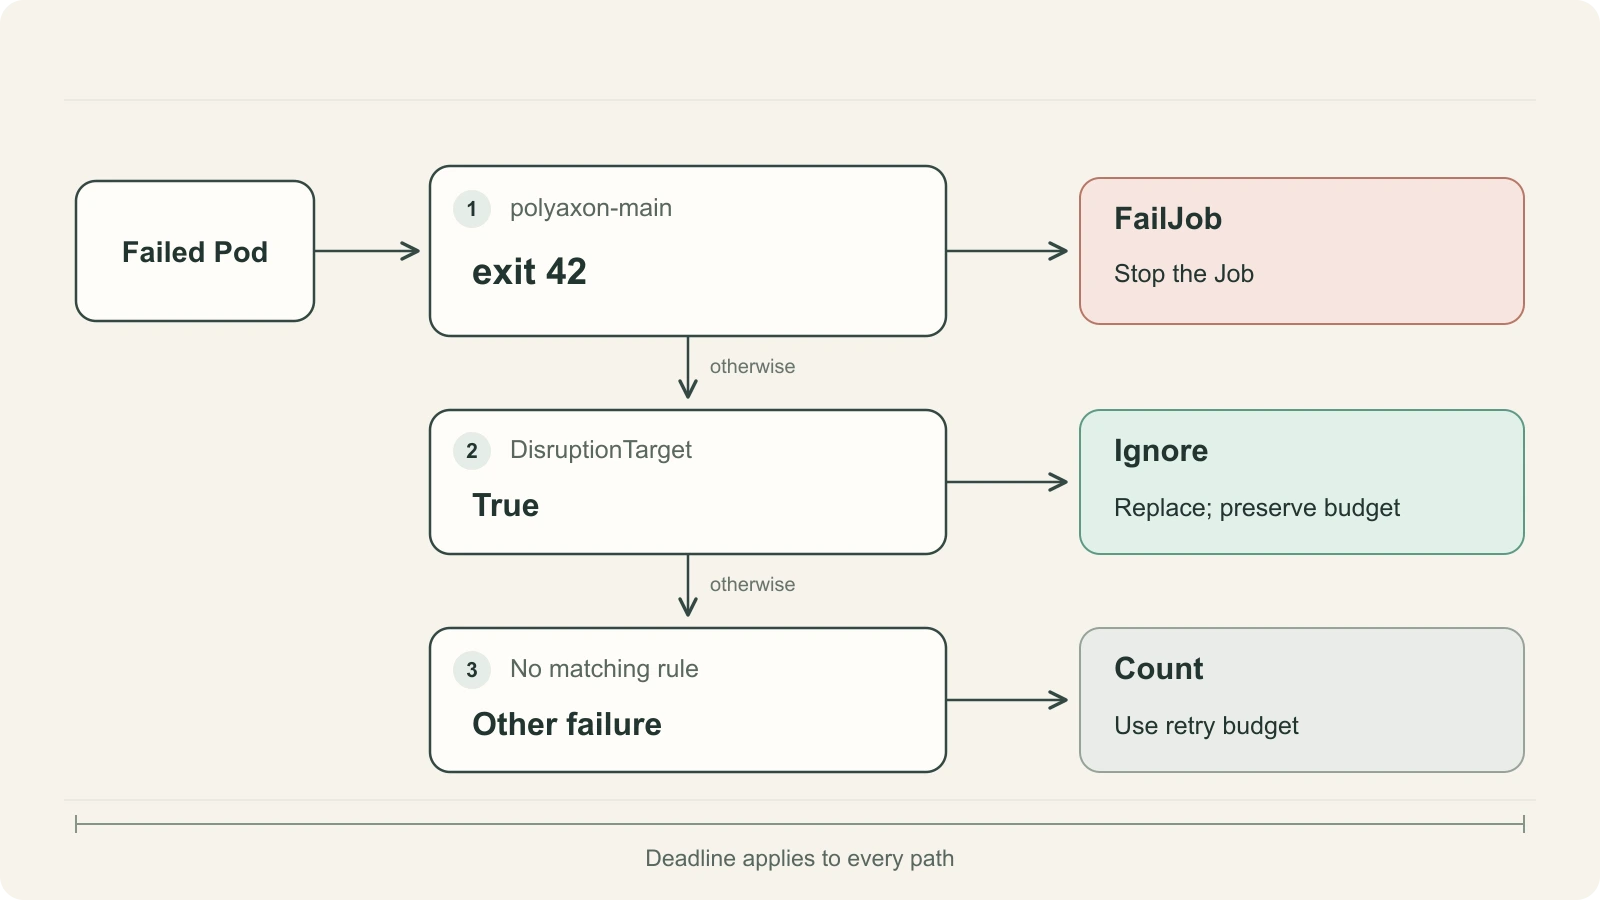
Use ordered Pod failure rules to stop permanent application errors, preserve the retry budget for marked disruptions, and bound replacement attempts.
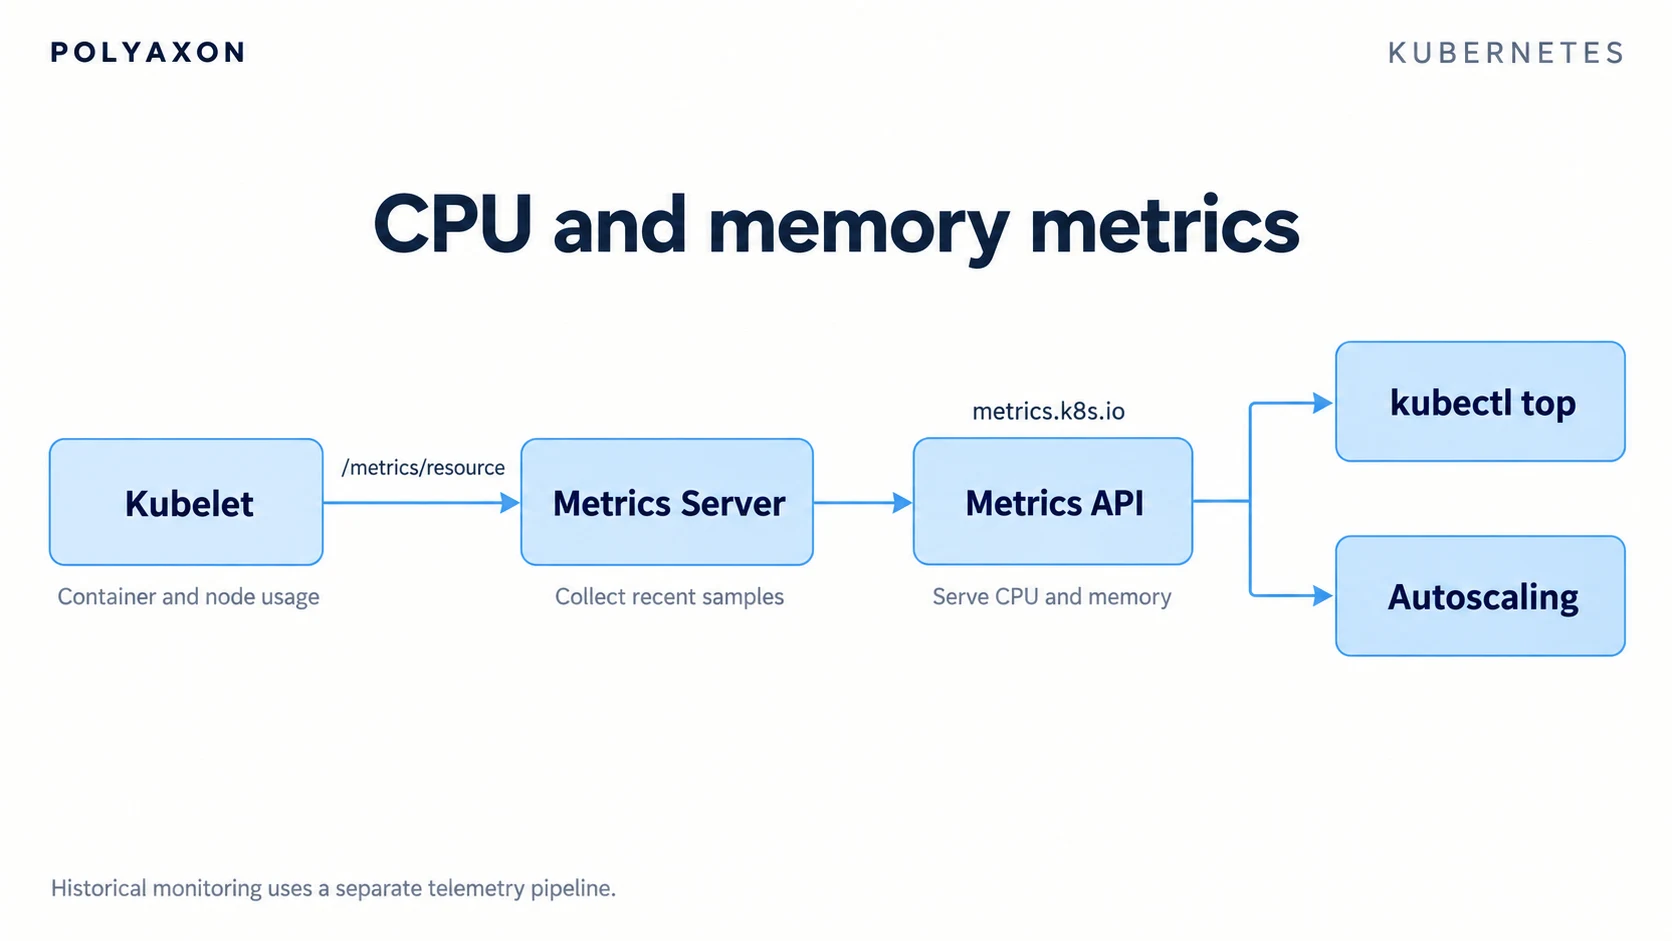
Find Kubernetes CPU, memory, object-state, and control plane metrics, and read them correctly with kubectl and your monitoring tools.
Use Pod certificate projections and trust bundles for workload TLS, with signer prerequisites and rotation handling for long-running ML services.
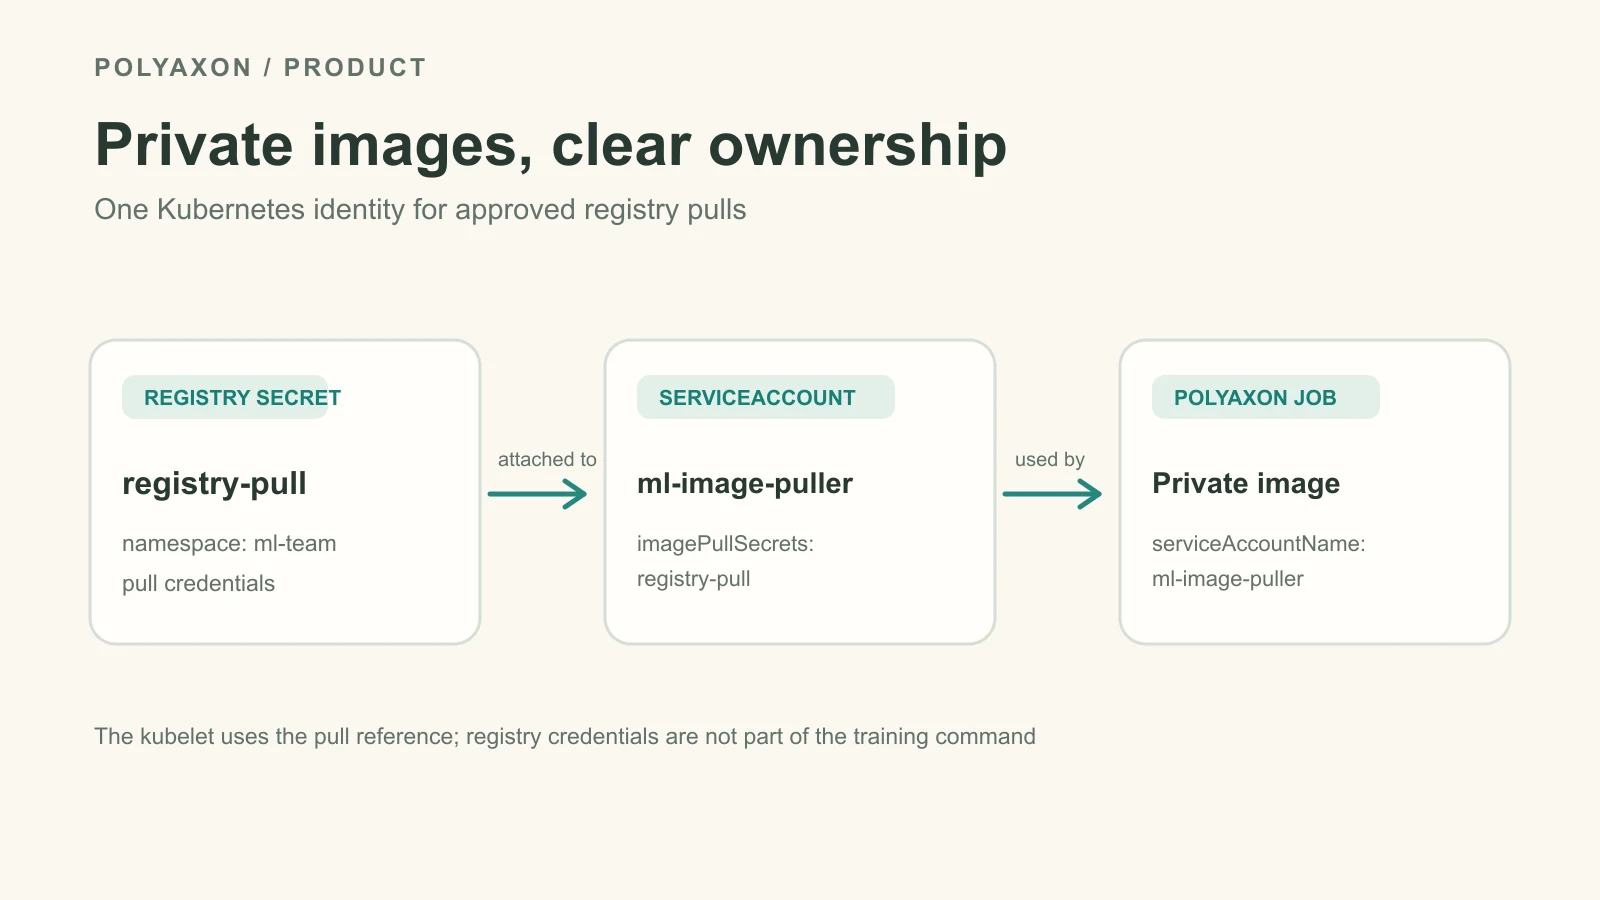
Attach a private-registry pull secret to a Kubernetes ServiceAccount, select it for a Polyaxon operation, and verify the new Pod can use the intended image.
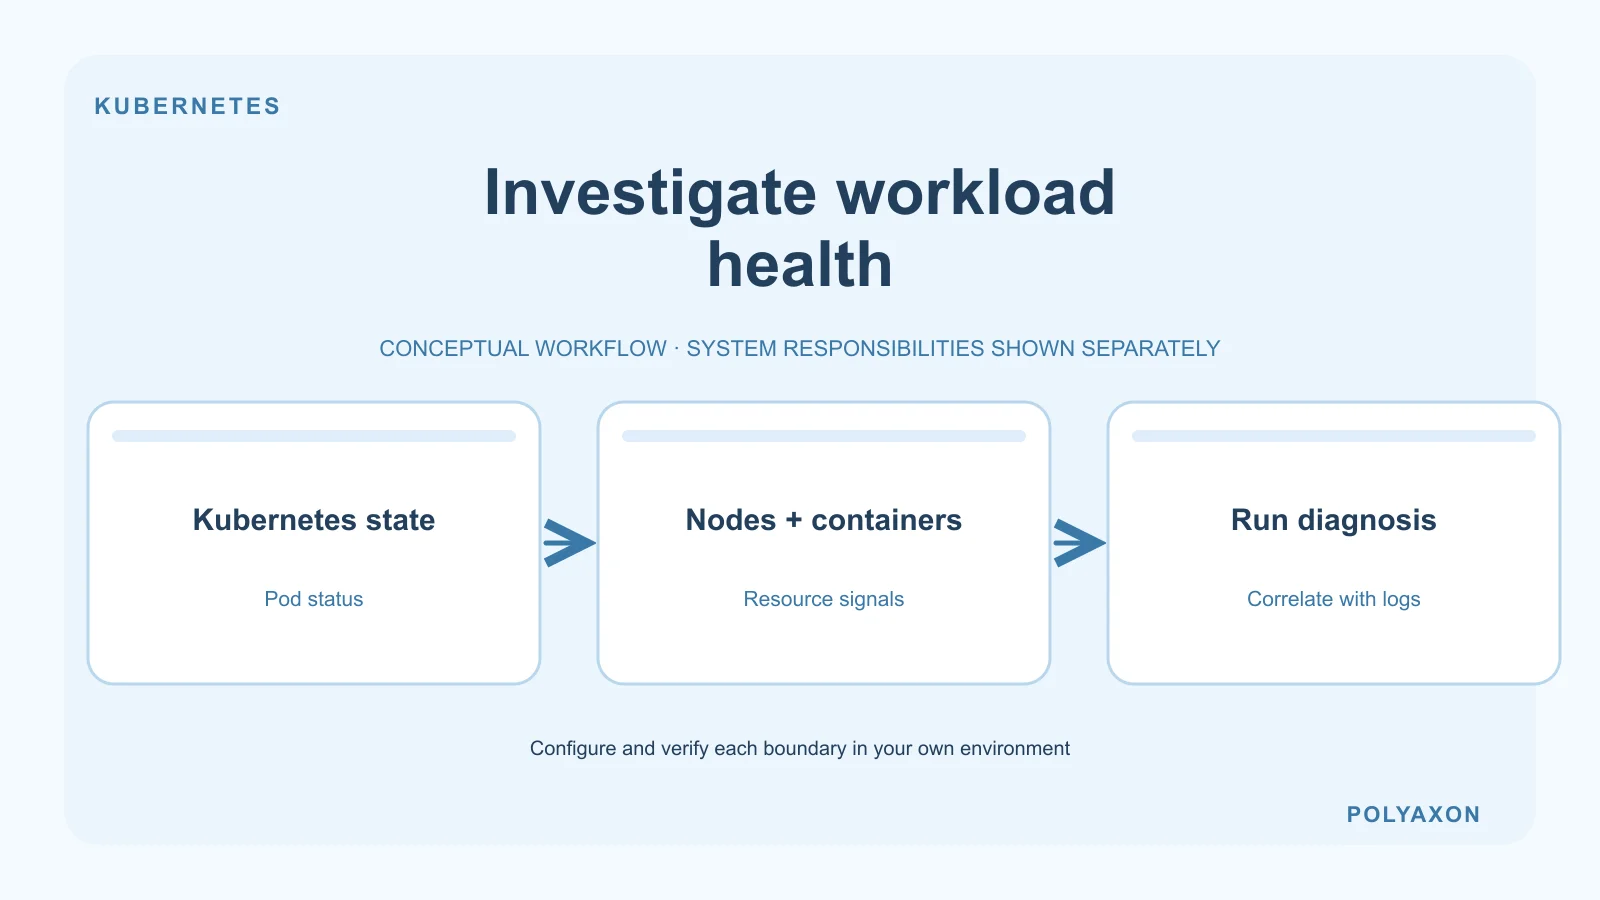
Correlate Kubernetes object state, container usage, and node health when investigating a Polyaxon workload.
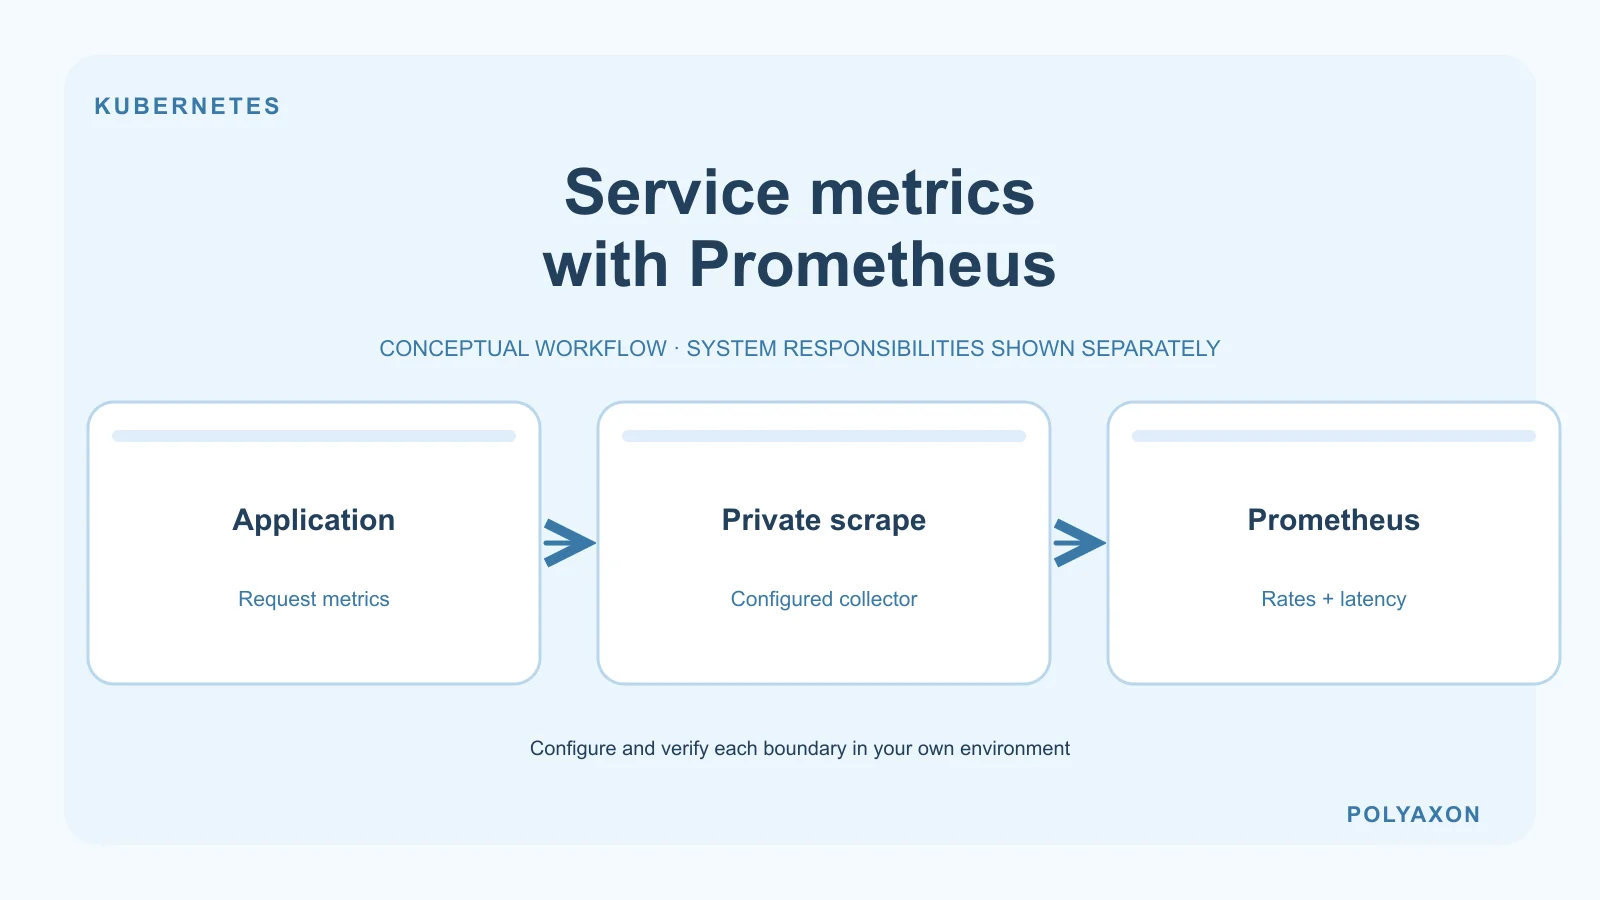
Instrument application request metrics in a Polyaxon service and configure a separate Prometheus collector to scrape them.
Monitor Kubernetes control planes, nodes, containers, schedulers, applications, and ML outcomes with useful correlations and controlled cardinality.
How to use Minikube for local Kubernetes development, basic cluster operations, and testing ML workloads before moving to shared infrastructure.
Understand Kubernetes StorageClasses, dynamic provisioning, reclaim policies, volume binding, and persistent volume claims.
Deploy a single PostgreSQL instance with a Secret, persistent storage, and private access, then verify that its data survives a Pod replacement.
Diagnose kubectl command not found errors caused by missing installs, PATH issues, permissions, Docker state, or Minikube command syntax.