
Turn LLM experiments into a reusable engineering knowledge base
Use Polyaxon run queries, comparison dashboards, artifact reports, and lineage to preserve the evidence behind LLM engineering decisions.
LLMOpsGuides
Page 4 of 7
Use Polyaxon run queries, comparison dashboards, artifact reports, and lineage to preserve the evidence behind LLM engineering decisions.
Understand Kubernetes objects, desired state, metadata, ownership, and reconciliation through the lifecycle of an ML workload.
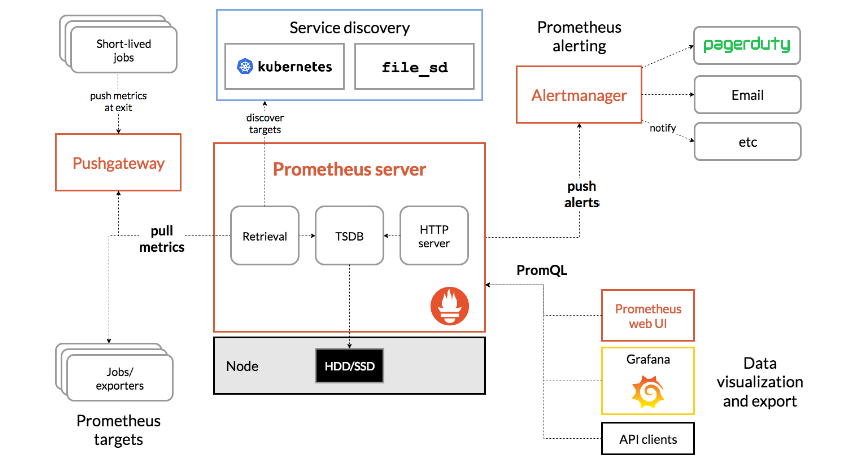
Decide between managed and self-operated Prometheus using scale, availability, PromQL compatibility, data governance, cost, and operational ownership.
Understand how BPF Type Format supports eBPF introspection, CO-RE portability, safer deployment, and kernel-level observability for ML infrastructure.
Debug ML workloads by following Kubernetes admission, scheduling, Pod startup, containers, nodes, networking, storage, and application outcomes in order.
A guide to Kubernetes ephemeral storage options, emptyDir, CSI ephemeral volumes, generic ephemeral volumes, and monitoring storage pressure.
Learn how Kubernetes Deployments manage pods and ReplicaSets, support rollout strategies, and keep applications available.
Use OpenTelemetry automatic instrumentation as a safe baseline, then add domain spans, stable attributes, sampling, and rollout controls for ML services.
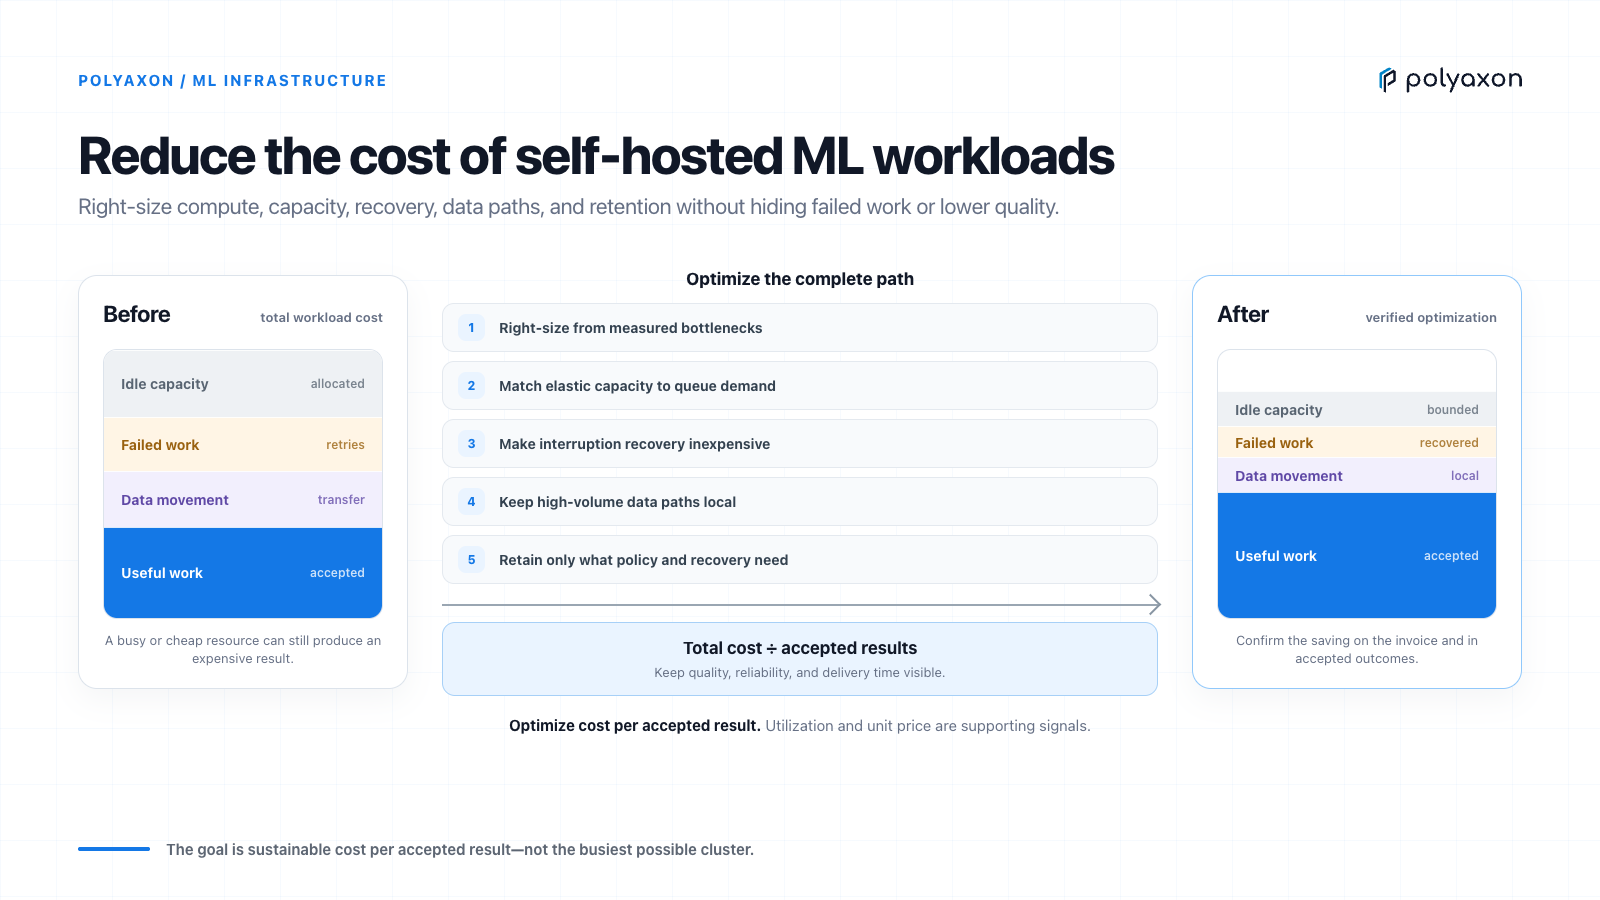
Allocate Kubernetes and GPU costs to ML teams and runs while keeping idle capacity, shared services, failed work, data movement, and useful outcomes visible.
Track usage and pricing assumptions in Polyaxon, compare cost against quality in run dashboards, and control resources and concurrency during LLM experiments.
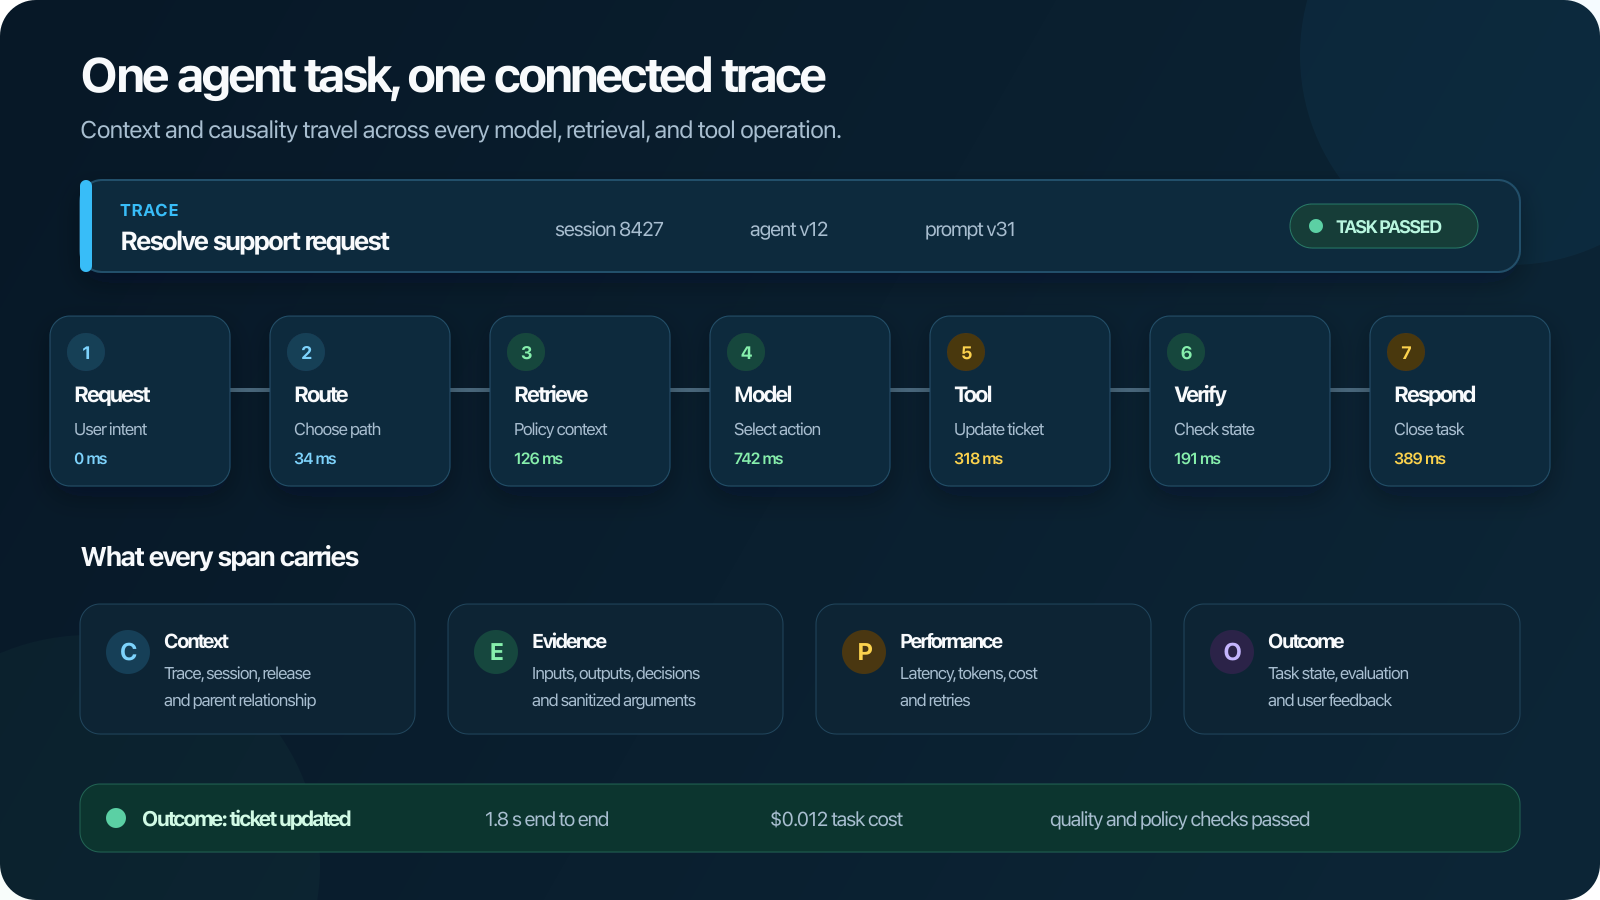
Trace ML requests and operations across APIs, queues, schedulers, storage, model services, and external tools without losing context or causality.
Use built-in admission, policies, and webhooks to enforce safe ML workload defaults without adding unnecessary latency or a cluster-wide failure point.
Learn Kubernetes through practical ML projects covering Pods, Jobs, storage, networking, scheduling, observability, security, and failure recovery.
Compare Istio, Linkerd, and Consul service mesh architectures by workload scope, traffic policy, identity, observability, operations, and ML fit.
Design, review, release, and operate Helm charts for ML platforms with predictable values, secure templates, upgrades, and ownership.
Build container image scanning into ML delivery with digest pinning, SBOMs, provenance, policy, remediation ownership, and runtime controls.
Instrument Java and Spring ML services with the OpenTelemetry agent, SDK, OTLP, domain spans, stable resource identity, and safe rollout controls.
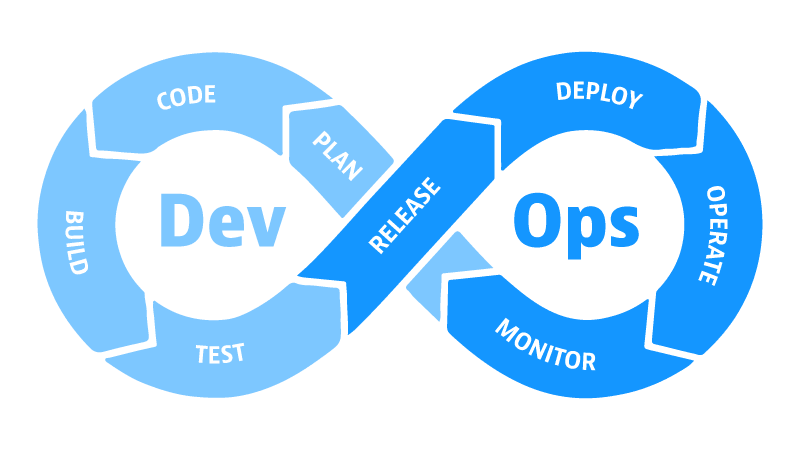
Clarify how DevOps and site reliability engineering complement each other through delivery, service objectives, error budgets, automation, and ML operations.
Understand OpenTelemetry signals, APIs, SDKs, semantic conventions, OTLP, the Collector, and how they fit into an ML observability architecture.
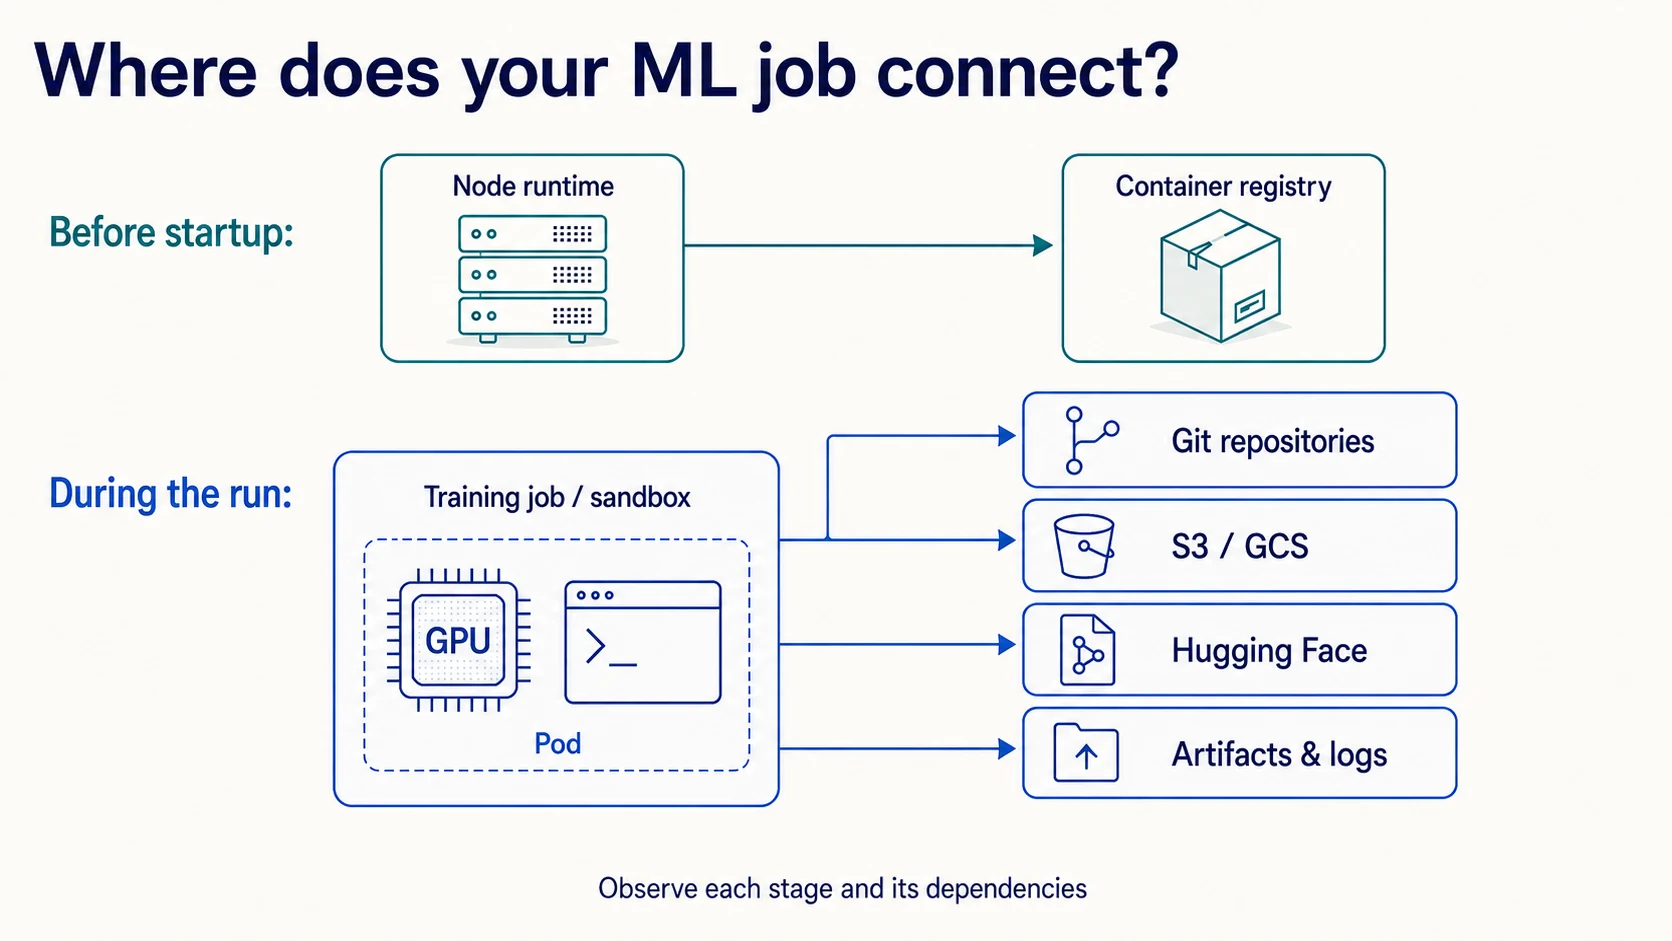
Decide whether a service mesh fits your ML platform, then design traffic policy, identity, observability, rollout, and failure behavior deliberately.
Diagnose ImagePullBackOff through Pod events, immutable image references, registry credentials, node networking, rate limits, and platform configuration.
Use kubectl exec and ephemeral containers for targeted Kubernetes debugging without losing evidence, mutating workloads, or bypassing platform controls.
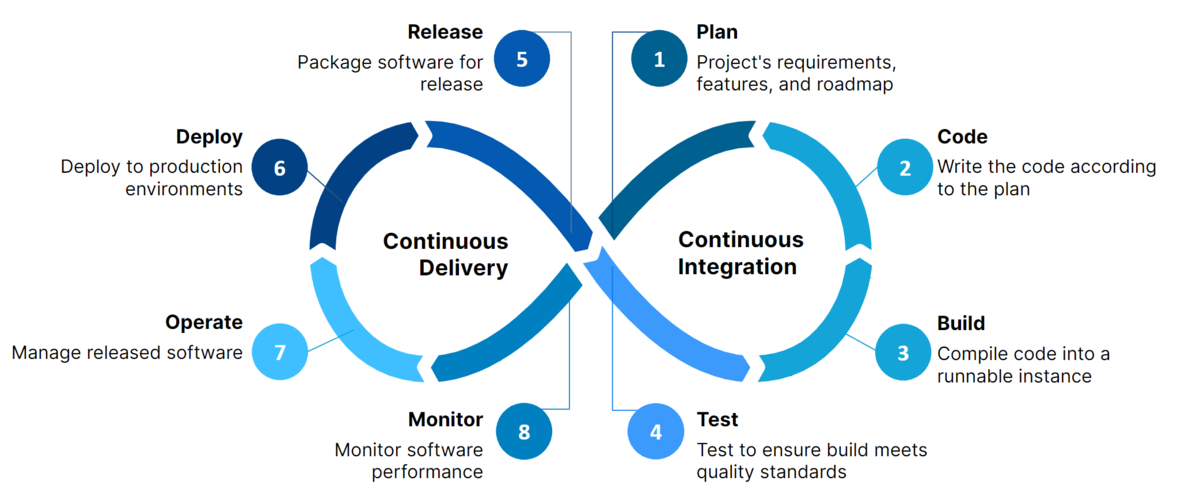
Use GitHub Actions to validate and submit traceable AI, ML, and agent workloads to Polyaxon without turning CI runners into training infrastructure.
Diagnose Kubernetes NotReady nodes through conditions, heartbeats, kubelet, runtime, networking, pressure, cloud health, and workload impact.